HyperLogLogで作る
“だいたい合ってる” COUNT (distinct …)
HeteroDB,Inc
Chief Architect 兼 CEO
海外 浩平 <kkaigai@heterodb.com>
自己紹介/HeteroDB社について
PostgreSQL Unconference online 2021.09.28
2
会社概要
 商号 ヘテロDB株式会社
 創業 2017年7月4日
 拠点 品川区北品川5-5-15
大崎ブライトコア4F
 事業内容 高速データベース製品の販売
GPU&DB領域の技術コンサルティング
ヘテロジニアスコンピューティング技術を
データベース領域に適用し、
誰もが使いやすく、安価で高速なデータ解析基盤を提供する。
代表者プロフィール
 海外 浩平(KaiGai Kohei)
 OSS開発者コミュニティにおいて、PostgreSQLやLinux kernelの
開発に15年以上従事。主にセキュリティ・FDW等の分野でアッ
プストリームへの貢献。
 IPA未踏ソフト事業において“天才プログラマー”認定 (2006)
 GPU Technology Conference Japan 2017でInception Awardを受賞
COUNT(distinct KEY) ってキツくないですか?
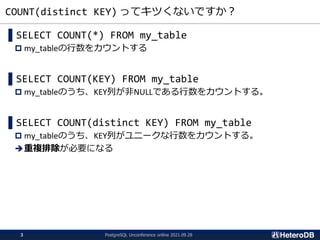
▌SELECT COUNT(*) FROM my_table
 my_tableの行数をカウントする
▌SELECT COUNT(KEY) FROM my_table
 my_tableのうち、KEY列が非NULLである行数をカウントする。
▌SELECT COUNT(distinct KEY) FROM my_table
 my_tableのうち、KEY列がユニークな行数をカウントする。
➔重複排除が必要になる
PostgreSQL Unconference online 2021.09.28
3
メモリ消費量が
予測不可能
COUNT(distinct KEY) ってキツくないですか?
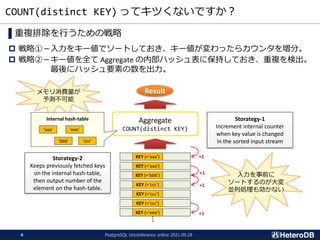
▌重複排除を行うための戦略
 戦略①-入力をキー値でソートしておき、キー値が変わったらカウンタを増分。
 戦略②-キー値を全て Aggregate の内部ハッシュ表に保持しておき、重複を検出。
最後にハッシュ要素の数を出力。
KEY (=‘aaa’)
KEY (=‘aaa’)
KEY (=‘bbb’)
KEY (=‘ccc’)
KEY (=‘ccc’)
KEY (=‘ccc’)
Aggregate
COUNT(distinct KEY)
KEY (=‘eee’)
Storategy-1
Increment internal counter
when key value is changed
in the sorted input stream
+1
+1
+1
+1
Storategy-2
Keeps previously fetched keys
on the internal hash-table,
then output number of the
element on the hash-table.
Result
Internal hash-table
‘aaa’
‘bbb’ ‘ccc’
‘eee’
入力を事前に
ソートするのが大変
並列処理も効かない
PostgreSQL Unconference online 2021.09.28
4
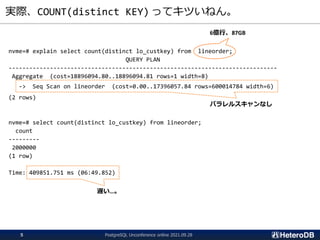
実際、COUNT(distinct KEY) ってキツいねん。
nvme=# explain select count(distinct lo_custkey) from lineorder;
QUERY PLAN
------------------------------------------------------------------------------
Aggregate (cost=18896094.80..18896094.81 rows=1 width=8)
-> Seq Scan on lineorder (cost=0.00..17396057.84 rows=600014784 width=6)
(2 rows)
nvme=# select count(distinct lo_custkey) from lineorder;
count
---------
2000000
(1 row)
Time: 409851.751 ms (06:49.852)
6億行、87GB
パラレルスキャンなし
遅い…。
PostgreSQL Unconference online 2021.09.28
5
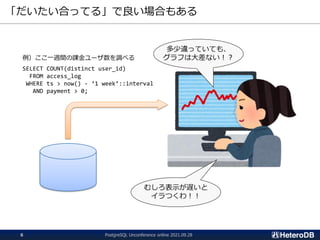
「だいたい合ってる」で良い場合もある
例)ここ一週間の課金ユーザ数を調べる
SELECT COUNT(distinct user_id)
FROM access_log
WHERE ts > now() - ‘1 week’::interval
AND payment > 0;
多少違っていても、
グラフは大差ない!?
むしろ表示が遅いと
イラつくわ!!
PostgreSQL Unconference online 2021.09.28
6
HyperLogLog - カーディナリティの推定アルゴリズム
▌様々な Big-Data 処理系でも採用
 Amazon RedShift
 Google BigQuery
 Microsoft CitusDB
 Pivotal Greenplum
PostgreSQL Unconference online 2021.09.28
7
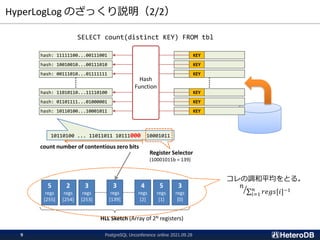
HyperLogLog のざっくり説明(1/2)
SELECT count(distinct KEY) FROM tbl
KEY
KEY
KEY
KEY
KEY
KEY
hash: 11111100...00111001
hash: 10010010...00111010
hash: 00111010...01111111
hash: 11010110...11110100
hash: 01101111...01000001
hash: 10110100...10001011
Hash
Function
10110100 ... 11011011 10111000 10001011
Register Selector
(10001011b = 139)
count number of contentious zero bits
regs
[255]
regs
[254]
regs
[253]
3
regs
[139]
regs
[2]
regs
[1]
regs
[0]
HLL Sketch (Array of 2N registers)
PostgreSQL Unconference online 2021.09.28
8
HyperLogLog のざっくり説明(2/2)
SELECT count(distinct KEY) FROM tbl
KEY
KEY
KEY
KEY
KEY
KEY
hash: 11111100...00111001
hash: 10010010...00111010
hash: 00111010...01111111
hash: 11010110...11110100
hash: 01101111...01000001
hash: 10110100...10001011
Hash
Function
10110100 ... 11011011 10111000 10001011
Register Selector
(10001011b = 139)
count number of contentious zero bits
5
regs
[255]
2
regs
[254]
3
regs
[253]
3
regs
[139]
4
regs
[2]
5
regs
[1]
3
regs
[0]
HLL Sketch (Array of 2N registers)
コレの調和平均をとる。
ൗ
𝑛
σ𝑖=1
𝑛
𝑟𝑒𝑔𝑠[𝑖]−1
PostgreSQL Unconference online 2021.09.28
9
PG-StromにおけるHyperLogLog(1/3)
=# select hll_count(lo_custkey) from lineorder ;
hll_count
-----------
2005437
(1 row)
Time: 9660.810 ms (00:09.661)
=# explain verbose select hll_count(lo_custkey) from lineorder ;
QUERY PLAN
----------------------------------------------------------------------------------
Aggregate (cost=4992387.95..4992387.96 rows=1 width=8)
Output: hll_merge((pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey))))
-> Gather (cost=4992387.72..4992387.93 rows=2 width=32)
Output: (pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey)))
Workers Planned: 2
-> Parallel Custom Scan (GpuPreAgg) on public.lineorder ¥
(cost=4991387.72..4991387.73 rows=1 width=32)
Output: (pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey)))
GPU Output: (pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey)))
GPU Setup: pgstrom.hll_hash(lo_custkey)
Reduction: NoGroup
Outer Scan: public.lineorder (cost=2833.33..4913260.79 rows=250006160 width=6)
GPU Preference: GPU0 (Tesla V100-PCIE-16GB)
GPUDirect SQL: enabled
Kernel Source: /var/lib/pgdata/pgsql_tmp/pgsql_tmp_strom_374786.6.gpu
Kernel Binary: /var/lib/pgdata/pgsql_tmp/pgsql_tmp_strom_374786.7.ptx
(15 rows)
✓ 真の値(2,000,000)と比べて、誤差 0.3% 程度
✓ 実行速度は 40 倍以上早かった(6億行、87GB)
PostgreSQL Unconference online 2021.09.28
10
PG-StromにおけるHyperLogLog(2/3)
=# explain verbose select hll_count(lo_custkey) from lineorder ;
QUERY PLAN
----------------------------------------------------------------------------------
Aggregate (cost=4992387.95..4992387.96 rows=1 width=8)
Output: hll_merge((pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey))))
-> Gather (cost=4992387.72..4992387.93 rows=2 width=32)
Output: (pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey)))
Workers Planned: 2
-> Parallel Custom Scan (GpuPreAgg) on public.lineorder ¥
(cost=4991387.72..4991387.73 rows=1 width=32)
Output: (pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey)))
GPU Output: (pgstrom.hll_sketch_new(pgstrom.hll_hash(lo_custkey)))
GPU Setup: pgstrom.hll_hash(lo_custkey)
Reduction: NoGroup
Outer Scan: public.lineorder (cost=2833.33..4913260.79 rows=250006160 width=6)
GPU Preference: GPU0 (Tesla V100-PCIE-16GB)
GPUDirect SQL: enabled
Kernel Source: /var/lib/pgdata/pgsql_tmp/pgsql_tmp_strom_374786.6.gpu
Kernel Binary: /var/lib/pgdata/pgsql_tmp/pgsql_tmp_strom_374786.7.ptx
(15 rows)
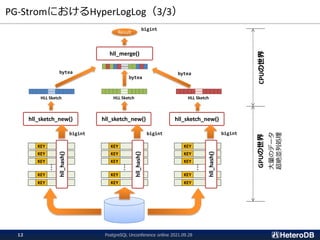
Reduction処理の前に、
HLL用のハッシュ値を計算する(2億行)
2億件のハッシュ値を元に生成した
HLL Sketchを1件だけ返す。(512バイト)
各ワーカーから上がってきた HLL Sketch を結合し、
調和平均に基づいてカーディナリティを推計する
PostgreSQL Unconference online 2021.09.28
11
PG-StromにおけるHyperLogLog(3/3)
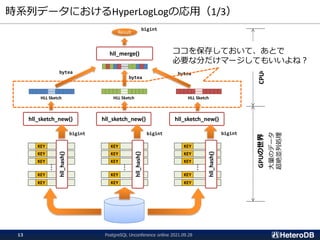
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
hll_sketch_new() hll_sketch_new() hll_sketch_new()
HLL Sketch HLL Sketch HLL Sketch
hll_merge()
Result
KEY KEY KEY
hll_hash()
hll_hash()
hll_hash()
bigint bigint bigint
bytea
bytea
bytea
CPUの世界
GPUの世界
大量のデータ
超絶並列処理
bigint
PostgreSQL Unconference online 2021.09.28
12
時系列データにおけるHyperLogLogの応用(1/3)
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
KEY
hll_sketch_new() hll_sketch_new() hll_sketch_new()
HLL Sketch HLL Sketch HLL Sketch
hll_merge()
Result
KEY KEY KEY
hll_hash()
hll_hash()
hll_hash()
bigint bigint bigint
bytea
bytea
bytea
CPUの世界
GPUの世界
大量のデータ
超絶並列処理
bigint
ココを保存しておいて、あとで
必要な分だけマージしてもいいよね?
PostgreSQL Unconference online 2021.09.28
13
時系列データにおけるHyperLogLogの応用(2/3)
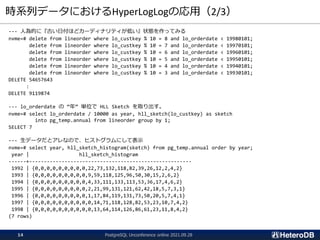
--- 人為的に『古い日付ほどカーディナリティが低い』状態を作ってみる
nvme=# delete from lineorder where lo_custkey % 10 = 8 and lo_orderdate < 19980101;
delete from lineorder where lo_custkey % 10 = 7 and lo_orderdate < 19970101;
delete from lineorder where lo_custkey % 10 = 6 and lo_orderdate < 19960101;
delete from lineorder where lo_custkey % 10 = 5 and lo_orderdate < 19950101;
delete from lineorder where lo_custkey % 10 = 4 and lo_orderdate < 19940101;
delete from lineorder where lo_custkey % 10 = 3 and lo_orderdate < 19930101;
DELETE 54657643
:
DELETE 9119874
--- lo_orderdate の “年” 単位で HLL Sketch を取り出す。
nvme=# select lo_orderdate / 10000 as year, hll_sketch(lo_custkey) as sketch
into pg_temp.annual from lineorder group by 1;
SELECT 7
--- 生データだとアレなので、ヒストグラムにして表示
nvme=# select year, hll_sketch_histogram(sketch) from pg_temp.annual order by year;
year | hll_sketch_histogram
------+-------------------------------------------------------
1992 | {0,0,0,0,0,0,0,0,0,22,73,132,118,82,39,26,12,2,4,2}
1993 | {0,0,0,0,0,0,0,0,0,9,59,118,125,96,50,30,15,2,6,2}
1994 | {0,0,0,0,0,0,0,0,0,4,33,111,133,113,53,36,17,4,6,2}
1995 | {0,0,0,0,0,0,0,0,0,2,21,99,131,121,62,42,18,5,7,3,1}
1996 | {0,0,0,0,0,0,0,0,0,1,17,84,119,131,73,50,20,5,7,4,1}
1997 | {0,0,0,0,0,0,0,0,0,0,14,71,118,128,82,53,23,10,7,4,2}
1998 | {0,0,0,0,0,0,0,0,0,0,13,64,114,126,86,61,23,11,8,4,2}
(7 rows)
PostgreSQL Unconference online 2021.09.28
14
時系列データにおけるHyperLogLogの応用(3/3)
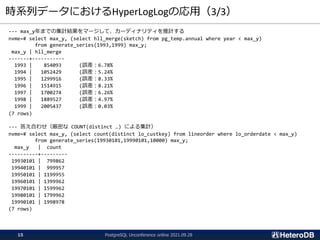
--- max_y年までの集計結果をマージして、カーディナリティを推計する
nvme=# select max_y, (select hll_merge(sketch) from pg_temp.annual where year < max_y)
from generate_series(1993,1999) max_y;
max_y | hll_merge
-------+-----------
1993 | 854093 (誤差:6.78%
1994 | 1052429 (誤差:5.24%
1995 | 1299916 (誤差:8.33%
1996 | 1514915 (誤差:8.21%
1997 | 1700274 (誤差:6.26%
1998 | 1889527 (誤差:4.97%
1999 | 2005437 (誤差:0.03%
(7 rows)
--- 答え合わせ(厳密な COUNT(distinct …) による集計)
nvme=# select max_y, (select count(distinct lo_custkey) from lineorder where lo_orderdate < max_y)
from generate_series(19930101,19990101,10000) max_y;
max_y | count
----------+---------
19930101 | 799862
19940101 | 999957
19950101 | 1199955
19960101 | 1399962
19970101 | 1599962
19980101 | 1799962
19990101 | 1998978
(7 rows)
PostgreSQL Unconference online 2021.09.28
15
結論
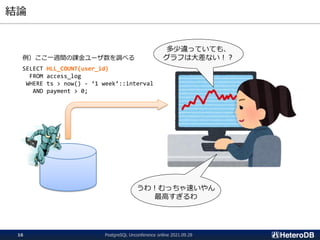
例)ここ一週間の課金ユーザ数を調べる
SELECT HLL_COUNT(user_id)
FROM access_log
WHERE ts > now() - ‘1 week’::interval
AND payment > 0;
多少違っていても、
グラフは大差ない!?
うわ!むっちゃ速いやん
最高すぎるわ
PostgreSQL Unconference online 2021.09.28
16
20210928_pgunconf_hll_count