Copyright (C) PresentSquare Co., Ltd. All Rights Reserved.
7. 結論
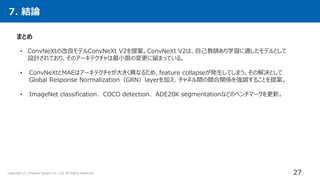
まとめ
27
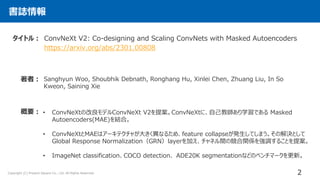
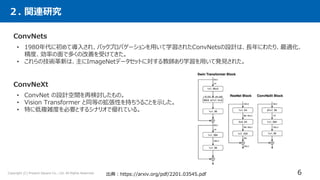
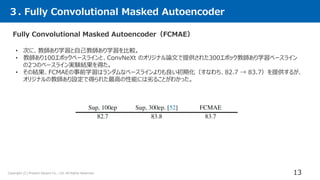
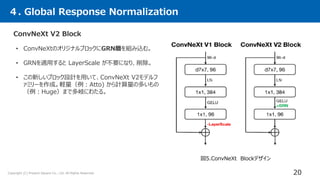
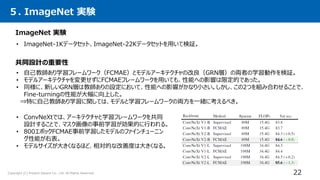
• ConvNeXtの改良モデルConvNeXt V2を提案。ConvNeXt V2は、自己教師あり学習に適したモデルとして
設計されており、そのアーキテクチャは最小限の変更に留まっている。
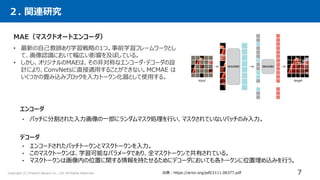
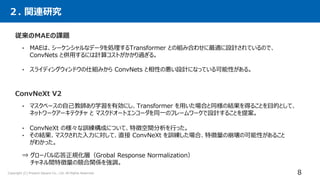
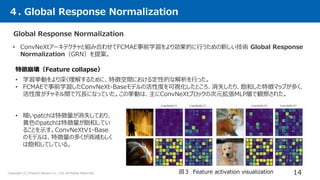
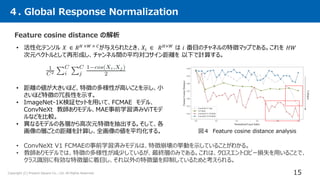
• ConvNeXtとMAEはアーキテクチャが大きく異なるため、feature collapseが発生してしまう。その解決として
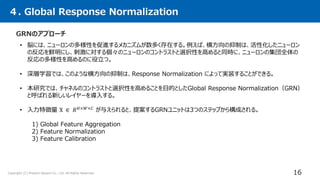
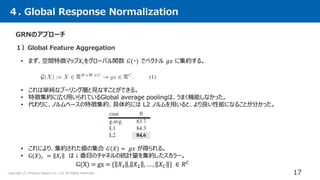
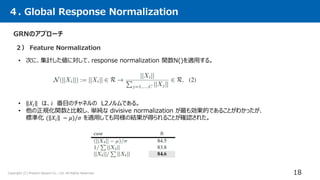
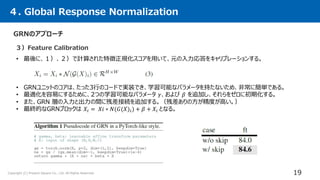
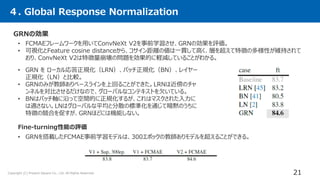
Global Response Normalization(GRN)layerを加え、チャネル間の競合関係を強調することを提案。
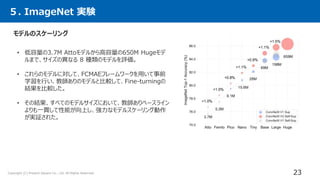
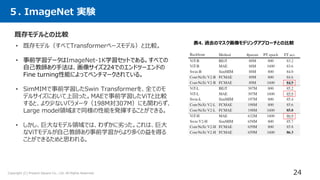
• ImageNet classification、 COCO detection、 ADE20K segmentationなどのベンチマークを更新。
28.
Copyright (C) PresentSquare Co., Ltd. All Rights Reserved.
Appendix
参考文献
• Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer,Trevor Darrell, and Saining Xie. A convnet for the
2020s. In CVPR, 2022.
• Christopher Choy, JunYoung Gwak, and Silvio Savarese. 4d spatio-temporal convnets: Minkowski convolutional neural
networks. In CVPR, 2019.
• Y. Jiang, L. Zhang, Z. Miao, X. Zhu, J. Gao, W. Hu, and Y.-G. Jiang, “Polarformer: Multi-camera 3d object detection with
polar transformer,” ArXiv, p. abs/2206.15398, 2022.
• Ross Girshick, Jeff Donahue, Trevor Darrell, and Jitendra Malik. Rich feature hierarchies for accurate object detection and
semantic segmentation. In CVPR, 2014.
• Kaiming He, Georgia Gkioxari, Piotr Doll´ar, and Ross Girshick. Mask R-CNN. In ICCV, 2017.
• Qilong Wang, Banggu Wu, Pengfei Zhu, Peihua Li, Wangmeng Zuo, and Qinghua Hu. Eca-net: Efficient channel attention
for deep convolutional neural networks. In CVPR, 2020.
• Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa
Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, and Neil Houlsby. An image is worth 16x16
words: Transformers for image recognition at scale. In ICLR, 2021.
28