1
Rigorous and Multi-tenant HBase Performance
Govind Kamat, Yanpei Chen
Performance Engineering
2
Bio
Govind Kamat
• Member of the Performance Engineering Team at Cloudera
• Focuses on Hadoop and HBase performance and scalability
• Experience includes the development of large-scale software systems,
microprocessor architecture, compilers and electronic design
Yanpei Chen
• Member of the Performance Engineering Team at Cloudera
• Works on cross-component performance - Hadoop, HBase, Search and Impala
• Ph.D. from UC Berkeley, focus on performance measurement method and theory
3
Outline
• Apache HBase overview
• Measuring performance + YCSB basics
• Cluster setup best practices
• Techniques for rigorous measurement
• HBase in a multi-tenant environment
4
HBase Overview
• Distributed, "NoSQL" key-value store
• Column-oriented, sorted map
• Keys are lexicographically sorted
• Multiple regions across “regionservers”
• Built on HDFS, MapReduce not required
5
Measuring HBase Performance is Hard!
• Numbers not reproducible
• Large run-to-run variation
• Testbeds not clearly defined/properly setup
• Various workloads have been used
• Configuration parameters not specified
• State of regionservers not taken into account
• Reported numbers not comparable
6
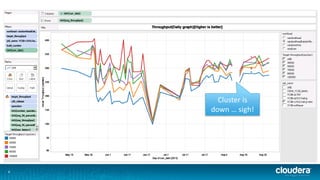
Cluster is
down … sigh!
7
Workloads for Performance Measurement
• Set of transactions to be imposed against it
• read, update, insert, scan and mixes thereof
• Initial data to be loaded into the DB
• Insert
• Transaction load intensity variation over time
• Possible HBase workloads:
• Actual customer/production workloads (best)
• PerformanceEvaluation (not really a workload )
• YCSB (Yahoo! Cloud Serving Benchmark, commonly used)
8
Yahoo! Cloud Serving Benchmark (YCSB) Basics
• Performance evaluation framework for key-value
databases, such as:
• HBase, Cassandra, Sherpa, Accumulo, Voldemort
• Abstracts out the client from the DB
• Flexible and configurable
• Comes with a standard “core” workload
• Reports throughput and latency metrics
9
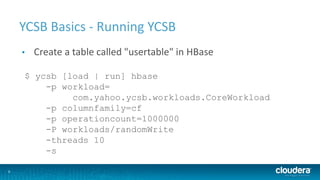
YCSB Basics - Running YCSB
• Create a table called "usertable" in HBase
$ ycsb [load | run] hbase
-p workload=
com.yahoo.ycsb.workloads.CoreWorkload
-p columnfamily=cf
-p operationcount=1000000
-P workloads/randomWrite
-threads 10
-s
10
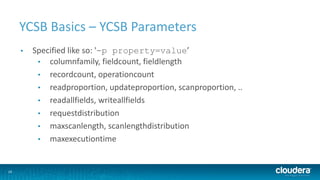
YCSB Basics – YCSB Parameters
• Specified like so: '-p property=value’
• columnfamily, fieldcount, fieldlength
• recordcount, operationcount
• readproportion, updateproportion, scanproportion, ..
• readallfields, writeallfields
• requestdistribution
• maxscanlength, scanlengthdistribution
• maxexecutiontime
11
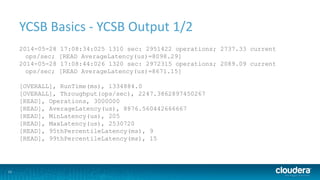
YCSB Basics - YCSB Output 1/2
2014-05-28 17:08:34:025 1310 sec: 2951422 operations; 2737.33 current
ops/sec; [READ AverageLatency(us)=8098.29]
2014-05-28 17:08:44:026 1320 sec: 2972315 operations; 2089.09 current
ops/sec; [READ AverageLatency(us)=8671.15]
[OVERALL], RunTime(ms), 1334884.0
[OVERALL], Throughput(ops/sec), 2247.3862897450267
[READ], Operations, 3000000
[READ], AverageLatency(us), 8876.560442666667
[READ], MinLatency(us), 205
[READ], MaxLatency(us), 2530720
[READ], 95thPercentileLatency(ms), 9
[READ], 99thPercentileLatency(ms), 15
12
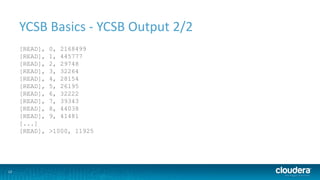
YCSB Basics - YCSB Output 2/2
[READ], 0, 2168499
[READ], 1, 445777
[READ], 2, 29748
[READ], 3, 32264
[READ], 4, 28154
[READ], 5, 26195
[READ], 6, 32222
[READ], 7, 39343
[READ], 8, 44038
[READ], 9, 41481
[...]
[READ], >1000, 11925
13
Cluster Setup Best Practices
• Setting up the cluster
• Configuring HBase
• Creating tables
• Pre-splitting tables
• Loading data
14
HBase Cluster Configuration Best Practices
• Use the appropriate hardware, correctly sized: memory, disk
• Dedicate separate nodes for master services and worker roles
• No Task Trackers and Node Managers on regionserver nodes
• Segregate clients from the regionservers
• Configure HBase properly:
• Block cache (read), memstore (write)
• Bloom filters, compression, compaction, short-circuit reads, etc.
• Use the appropriate data set size, number of regions, etc.
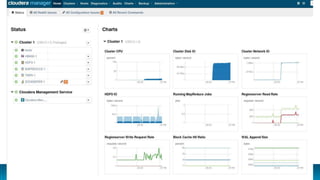
• Monitor the cluster constantly
15
16
Data Loading – Several Options
• Real, actual, production (hot) data 
• Custom loader
• PerformanceEvaluation
• Loading using YCSB
• HFileGenerator followed by bulk-load
17
Data Loading - Pre-split the Table
• Auto-splitting has significant overhead
• RegionSplitter utility
• UniformSplit
• HexStringSplit
• YCSB: user100000 .. user999999
hbase(main):1:0> create 'usertable', 'cf’,
{ SPLITS=> (1..(50-1)).map {|i| "user#{1000 +
i*9000/50}" } } #50 splits
• Set maximum region file size to a large value
18
Techniques for Rigorous Measurement
• Keep the input data set fixed
• Warm up the cache
• Set the target throughput
• Use the correct workload distribution
19
Keep the Input Data Set Fixed!
20
Keep the Input Data Set Fixed!
A beginning is the time for taking the most
delicate care that the balances are correct.
The manual of Muad’Dib
From “Dune” by Frank Herbert
21
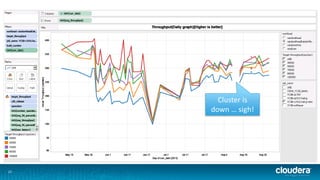
Cluster is
down … sigh!
22
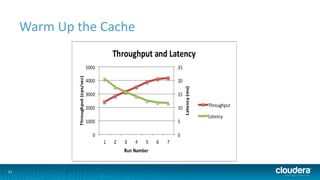
Warm Up the Cache
• Performance depends significantly on memory
• HBase block cache and OS page cache for reads
• Memstore and WAL for writes
• Load all the rows in the table
• Write until data starts getting flushed
• Compaction can affect performance significantly
• Carry out long-running tests
• Repeat till steady-state
• Otherwise, performance can vary a lot
23
Warm Up the Cache
24
Set the Target Throughput
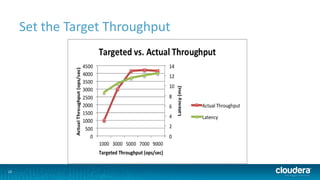
• Two parameters to set desired throughput
• -threads
• -target
• Actual throughput will match target throughput ...
• ... until the DB hits its limit
• Performance may then begin to degrade
• This throughput defines maximum cluster performance
• Can be used to evaluate different HBase releases
• Otherwise, HBase is never stressed beyond saturation
25
Set the Target Throughput
26
Use the Appropriate Workload Distribution
• Various types possible
• Uniform (default, but unrealistic)
• Latest
• Hotspot
• Zipfian
27
Rigorous Measurement Techniques
• Set the cluster up properly
• Keep the input data set fixed
• Pre-split the key space
• Warm up the cache properly
• Set the target throughput
• Use the correct workload distribution
• Monitor cluster statistics continually
28 ©2014 Cloudera, Inc. All rights reserved.
• Multi-tenant as in different compute frameworks
Multi-tenant HBase Performance
29 ©2014 Cloudera, Inc. All rights reserved.
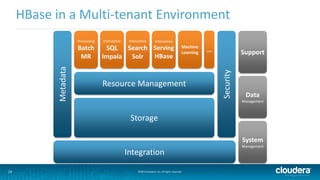
HBase in a Multi-tenant Environment
Integration
Storage
Resource Management
Metadata
Processing
Batch
MR
…
Interactive
SQL
Impala
Interactive
Search
Solr
Interactive
Serving
HBase
Machine
Learning
System
Management
Data
Management
Support
Security
30 ©2014 Cloudera, Inc. All rights reserved.
• Customer wants to do free-text search on data in HBase
• Explore relevant data beyond just key look-up
• This is “multi-tenant” as in multiple frameworks
• HBase + MapReduce + Cloudera Search (Apache Solr)
• Data indexed into Solr via MapReduce (or Lily HBase Indexer)
• Challenge is to not impact HBase and Solr performance
Real Multi-tenant Use Case
31 ©2014 Cloudera, Inc. All rights reserved.
• Inevitable constraints
• More processing, different processing on the same hardware
• Multi-tenant performance of each framework < stand-alone perf.
• Good multi-tenant performance means
• Efficient - good aggregate performance across HBase/MR/Search
• Fair - performance of each reflects assigned share of resources
• Elastic - transient spare resources get quickly and fully used
Multi-tenant Performance is Hard!
32 ©2014 Cloudera, Inc. All rights reserved.
• Configure HBase, Search, and MapReduce
• Large set of performance-relevant parameters for each
• Configure each for achieve a desired resource share
• Many implicit resource controls
• Setup the datasets for high performance
• How many regions for the HBase table
• How many shards for the Solr collection
Practically doing HBase  Solr via MapReduce
33 ©2014 Cloudera, Inc. All rights reserved.
Start with stand-alone performance
• Stand-alone MR indexing rate of HBase  Search
• Should be no lower than that for HDFS  Search
34 ©2014 Cloudera, Inc. All rights reserved.
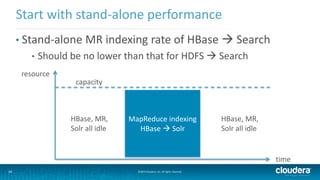
• Stand-alone MR indexing rate of HBase  Search
• Should be no lower than that for HDFS  Search
Start with stand-alone performance
time
MapReduce indexing
HBase  Solr
resource
HBase, MR,
Solr all idle
HBase, MR,
Solr all idle
capacity
35 ©2014 Cloudera, Inc. All rights reserved.
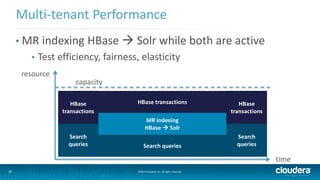
• MR indexing HBase  Solr while both are active
• Test efficiency, fairness, elasticity
Multi-tenant Performance
HBase
transactions
HBase transactions HBase
transactions
MR indexing
HBase  Solr
Search
queries
Search
queriesSearch queries
time
resource
capacity
36 ©2014 Cloudera, Inc. All rights reserved.
• HBase essential to an enterprise data hub
• Need for multiple frameworks to analyze HBase data
• Challenging to define/measure multi-tenant performance
• Not tractable without rigorous techniques
• Look for discipline and rigor in performance numbers!
Recap
37 ©2014 Cloudera, Inc. All rights reserved.
• gkamat@cloudera.com
• yanpei@cloudera.com
Thanks!
38 ©2014 Cloudera, Inc. All rights reserved.
Backup slides
39
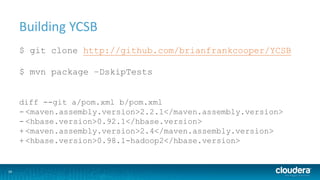
Building YCSB
$ git clone http://github.com/brianfrankcooper/YCSB
$ mvn package –DskipTests
diff --git a/pom.xml b/pom.xml
- <maven.assembly.version>2.2.1</maven.assembly.version>
- <hbase.version>0.92.1</hbase.version>
+ <maven.assembly.version>2.4</maven.assembly.version>
+ <hbase.version>0.98.1-hadoop2</hbase.version>
40
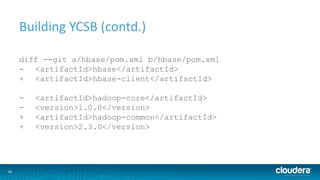
Building YCSB (contd.)
diff --git a/hbase/pom.xml b/hbase/pom.xml
- <artifactId>hbase</artifactId>
+ <artifactId>hbase-client</artifactId>
- <artifactId>hadoop-core</artifactId>
- <version>1.0.0</version>
+ <artifactId>hadoop-common</artifactId>
+ <version>2.3.0</version>