Downloaded 547 times
- 1 / 53
- 2 / 53
- 3 / 53
- 4 / 53
- 5 / 53
- 6 / 53
- 7 / 53
- 8 / 53
- 9 / 53
- 10 / 53
- 11 / 53
- 12 / 53
- 13 / 53
- 14 / 53
- 15 / 53
- 16 / 53
- 17 / 53
- 18 / 53
- 19 / 53
- 20 / 53
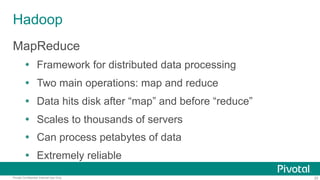
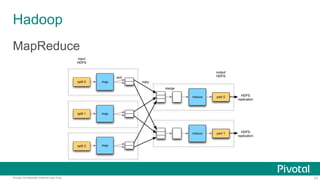
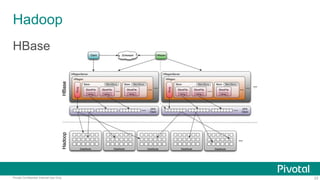
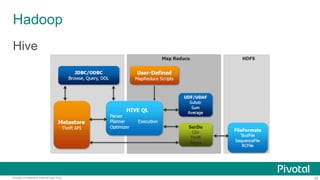
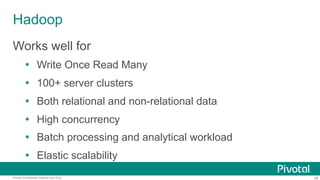
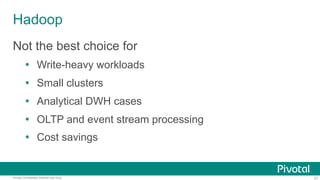
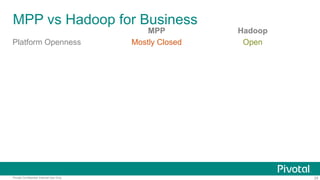
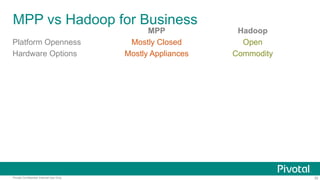
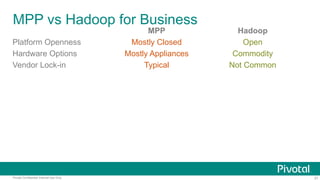
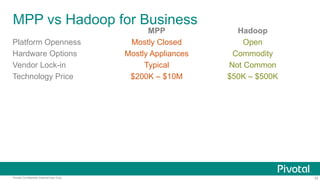
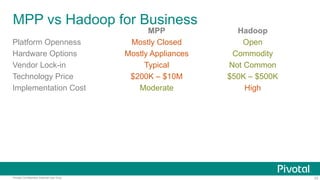
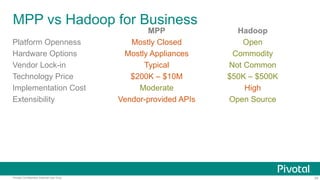
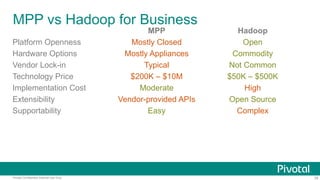
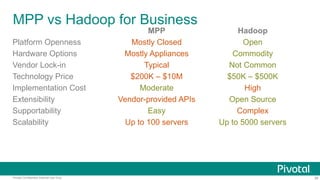
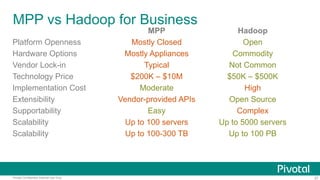
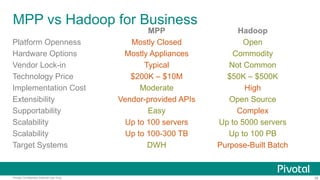
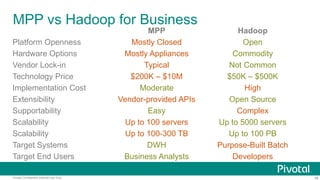
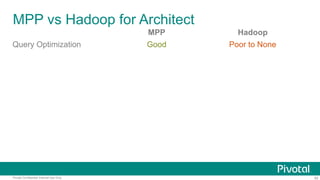
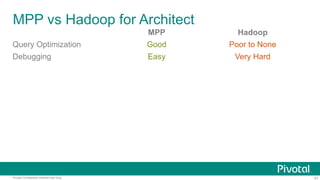
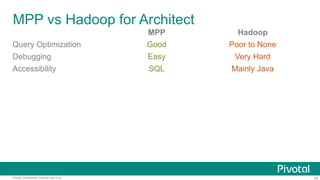
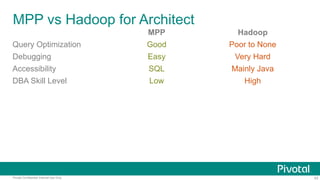
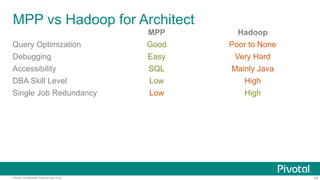
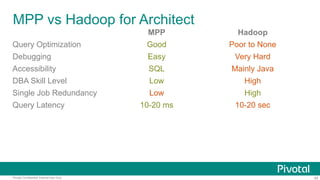
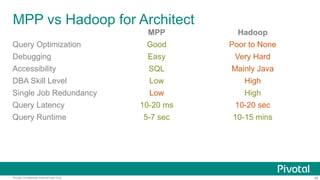
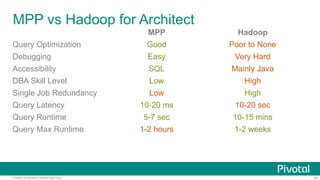
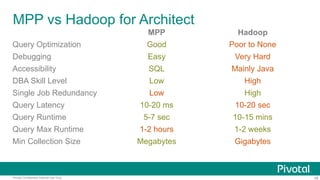
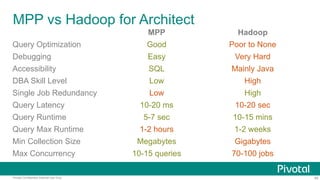
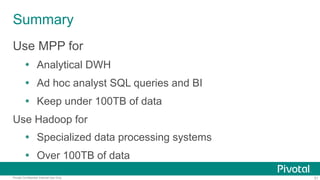

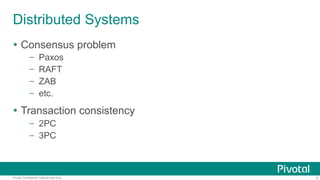
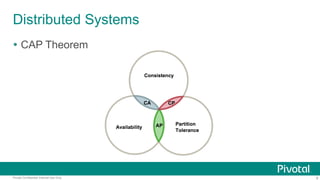
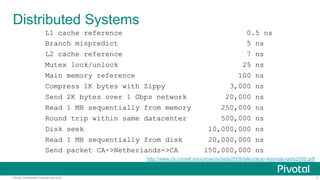
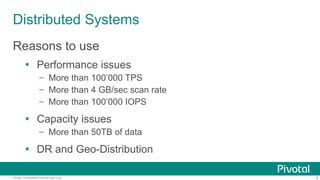
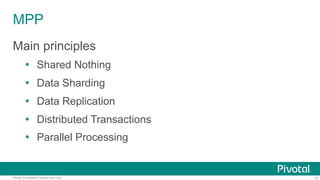
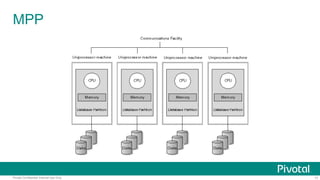
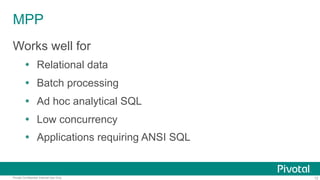
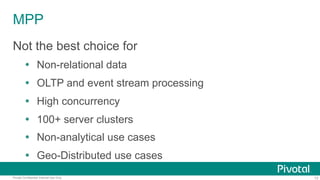
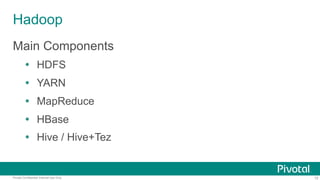
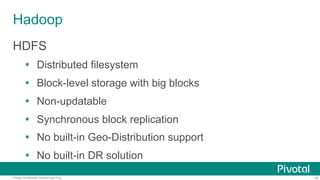
The document presents a comparison between MPP (Massively Parallel Processing) and Hadoop in the context of distributed systems, outlining their respective strengths, weaknesses, and suitable use cases. MPP is ideal for analytical data warehousing and ad hoc SQL queries with data under 100TB, while Hadoop excels in handling specialized data processing systems with data over 100TB. Key differences include cost, scalability, query optimization, and accessibility, with MPP having lower latency and easier debugging compared to Hadoop.


