Molecular Representa/on, 
  Similarity and Search 
          Rajarshi Guha 
   NIH Chemical Genomics Center 

         December 3rd, 2009 
Outline 
•  How can we represent molecules on a 
   computer? 
•  How do we decide when molecules are 
   similar? 
•  What can we do using similarity? 
Molecular Representa/ons 
•  Explicit  
   –  Indicate what the atoms are, what atom is connected 
      to what other atom(s) 
   –  Differing levels of explicitness 
       •  Do we need to show hydrogens? 
       •  Do we need to indicate actual bonds? 
•  Implicit 
   –  Usually very compact (e.g., SMILES) 
   –  Need to know the assump/ons involved 
       •  In SMILES, no specific bond symbol implies single bond 
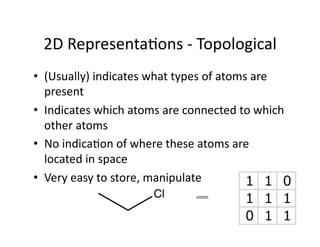
2D Representa/ons ‐ Topological 
•  (Usually) indicates what types of atoms are 
   present 
•  Indicates which atoms are connected to which 
   other atoms 
•  No indica/on of where these atoms are 
   located in space 
•  Very easy to store, manipulate 
                      Cl
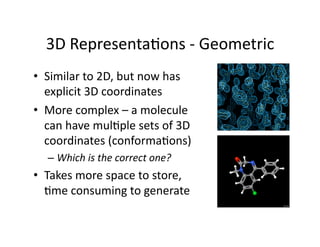
3D Representa/ons ‐ Geometric 
•  Similar to 2D, but now has 
   explicit 3D coordinates 
•  More complex – a molecule 
   can have mul/ple sets of 3D 
   coordinates (conforma/ons) 
  –  Which is the correct one? 
•  Takes more space to store, 
   /me consuming to generate 
Molecular Similarity 
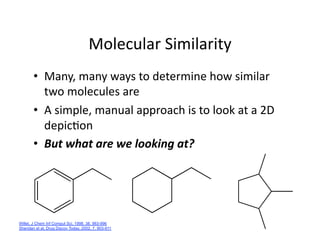
       •  Many, many ways to determine how similar 
          two molecules are 
       •  A simple, manual approach is to look at a 2D 
          depic/on 
       •  But what are we looking at?  


Willet, J Chem Inf Comput Sci, 1998, 38, 983-996
Sheridan et al, Drug Discov Today, 2002, 7, 903-911
Molecular Similarity 
•  But 2D can be misleading 
•  Iden/cal in 2D is not necessarily so in 3D 
How Do We Quan/fy Similarity? 
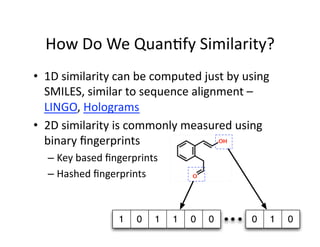
•  1D similarity can be computed just by using 
   SMILES, similar to sequence alignment – 
   LINGO, Holograms 
•  2D similarity is commonly measured using 
   binary fingerprints 
  –  Key based fingerprints 
  –  Hashed fingerprints 
How Do We Quan/fy Similarity? 
•  Given 2 fingerprints we can then calculate a 
   variety of similarity func/ons 
•  Tanimoto is the most commonly used 
  –  Ranges from 0 to 1  
  –  A measure of the number of bits common to both 
     fingerprints 
  –  See Daylight for more details 
•  Can also be extended to 3D similari/es 
How Do We Quan/fy Similarity? 
•  3D similarity  is more complex 
•  Most methods require you to align two 3D 
   structures 
•  Then determine the “volume overlap” 
  –  To what extent do the two structures occupy the 
     same region in space 
•  Most well known tool for this is ROCS 
How Do We Quan/fy Similarity? 
•  Property based similarity will use various 
   physical proper/es or biological ac/vi/es 
  –  If two molecules exhibit similar ac/vity across 
     mul/ple cell lines, they are likely similar 
  –  If two molecules have a set of similar physical 
     proper/es (computed or experimental) they are 
     likely similar 
2D or 3D? 
•  Fast and easy          •  More “accurate” 
•  Not always             •  Computa/onally 
   biological relevant       more expensive 
•  But surprisingly       •  Which 
   useful                    conforma/on is the 
                             correct one? 

  Different representations and similarity
  methods will, in general, lead to different
                results (hits)
What Can We Do With Similarity? 
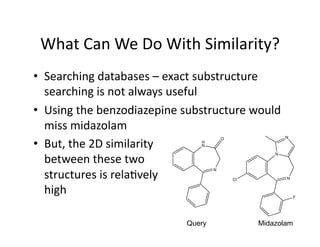
•  Searching databases – exact substructure 
   searching is not always useful 
•  Using the benzodiazepine substructure would              
   miss midazolam 
•  But, the 2D similarity  
                                           O                N
                                   H
                                   N


   between these two 
                                                        N


   structures is rela/vely 
                                       N

                                               Cl           N


   high                                                         F


                               Query                Midazolam
But 2D Only Goes So Far … 
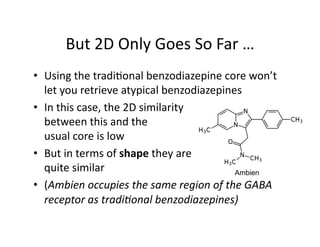
•  Using the tradi/onal benzodiazepine core won’t 
   let you retrieve atypical benzodiazepines 
•  In this case, the 2D similarity 
   between this and the  
   usual core is low 
•  But in terms of shape they are 
   quite similar                           Ambien
•  (Ambien occupies the same region of the GABA 
   receptor as tradi8onal benzodiazepines)  
Virtual Screening 
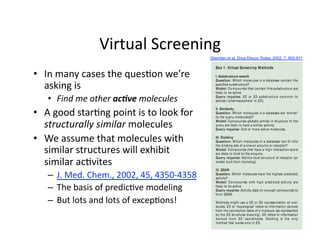
                                            Sheridan et al, Drug Discov Today, 2002, 7, 903-911


•  In many cases the ques/on we’re 
   asking is 
   •  Find me other ac2ve molecules 
•  A good star/ng point is to look for 
   structurally similar molecules 
•  We assume that molecules with 
   similar structures will exhibit 
   similar ac/vites 
   –  J. Med. Chem., 2002, 45, 4350‐4358 
   –  The basis of predic/ve modeling 
   –  But lots and lots of excep/ons! 
Virtual Screening 
•  2D similarity is a cheap, easy and fast way to 
   perform this type of task 
•  Can “screen” databases of many millions of 
   molecules extremely rapidly 
•  Usually only consider “very similar” (Tc >= 0.85) 
   hits 
•  It works … 
Virtual Screening 
•  But can be of limited use if used naively 
  –  Similarity is usually supplanted by machine learning 
  –  S/ll, the only way out if there is no receptor and 
     only a few (or a single) known ac/ves 
•  Main drawback is that the hits are structurally 
   similar 
  –  D’oh! 
  –  Not great if you’re trying to find a molecule that 
     someone else hasn’t already developed 
Scaffold Hopping 
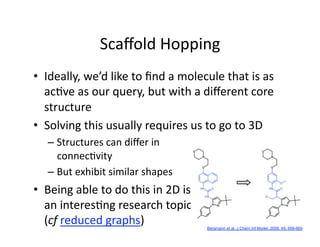
•  Ideally, we’d like to find a molecule that is as 
   ac/ve as our query, but with a different core 
   structure 
•  Solving this usually requires us to go to 3D 
   –  Structures can differ in  
      connec/vity 
   –  But exhibit similar shapes 
•  Being able to do this in 2D is 
   an interes/ng research topic 
   (cf reduced graphs)               Bergmann et al, J Chem Inf Model, 2009, 49, 658-669
Dissimilarity & Library Design 
•  Chemical libraries form the basis of high 
   throughput screening and other discovery 
   methods 
•  Sizes can range from a few hundred molecules 
   to millions (or billions for virtual libraries) 
•  In most cases, we want to cover as much of 
   chemical space as possible 
  –  How do we compare coverage? 
  –  So if we want to add new molecules, how do we 
     choose them? 
Dissimilarity & Library Design 
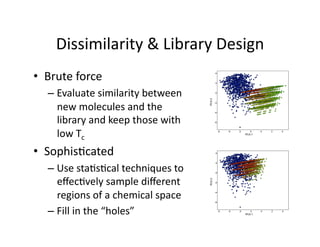
•  Brute force 
   –  Evaluate similarity between 
      new molecules and the 
      library and keep those with 
      low Tc 
•  Sophis/cated 
   –  Use sta/s/cal techniques to 
      effec/vely sample different 
      regions of a chemical space 
   –  Fill in the “holes” 
Summary 
•  Similarity (and dissimilarity) are  
   fundamental concepts 
   –  Simple on the outside, complex on the inside 
•  A wide variety of methods available 
   –  Need to consider pros/cons in terms of 
      computa/onal expense, chemical u/lity, … 
•  Visualizing similarity is useful 
•  Many problems can be recast in terms of 
   similarity or dissimilarity