INDEX
Central tendency is a central value or a typical value
for a probability distribution. It is occasionally called
an average or just the center of the distribution. The
most common measures of central tendency are
the arithmetic mean, the median and the mode. A
central tendency can be calculated for either a finite
set of values or for a theoretical distribution, such as
the normal distribution. Occasionally authors use
central tendency (or centrality), to mean "the
tendency of quantitative data to cluster around some
central value."
• ARITHMETIC MEAN
• HARMONIC MEAN
• GEOMETRIC MEAN
• MEDIAN

• MODE
 IT SHOULD BE RIGIDLY DEFINED.

IT SHOULD BE EASY TO UNDERSTAND AND
CALCULATE
 IT SHOULD BE BASED ON ALL THE
OBSERVATIONS OF DATA .
 IT SHOULD BE SUBJECTED TO FURTHER
MATHEMATICAL CALCULATIONS
 IT SHOULD BE LEAST AFFECTED BY
FLUCTUATION OF SAMPLING
ARITHMETIC
MEAN
HARMONIC
MEAN

GEOMETRIC MEAN
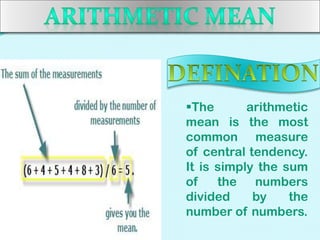
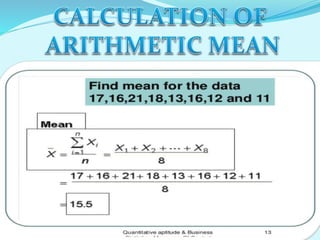
The
arithmetic
mean is the most
common measure
of central tendency.
It is simply the sum
of
the numbers
divided
by
the
number of numbers.
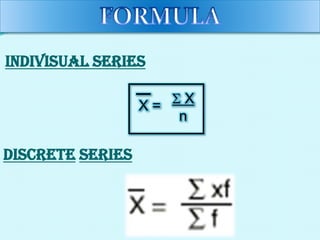
INDIVISUAL SERIES

DISCRETE SERIES
IT ISEASY TO UNDERSTAND AND CALCULATE.
 BASED ON ALL THE ITEMS OF SAMPLE
 RIGIDLY DEFINED BY MATHEMATICAL FORMULA.
 WE CAN COMPUTE COMBINED ARITHMETIC MEAN.
 IT HAS SAMPLING STABILITY .

 AFFECTED BY EXTREME VALUES

 NOT USEFUL FOR STUDYING QUALITATIVE
PHENOMENON
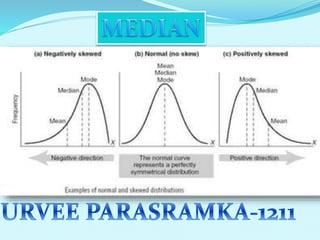
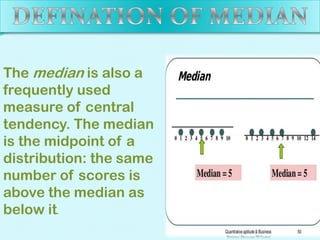
The median is also a
frequently used
measure of central
tendency. The median
is the midpoint of a
distribution: the same
number of scores is
above the median as
below it.
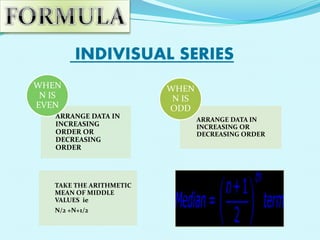
INDIVISUAL SERIES
WHEN
N IS
EVEN
ARRANGE DATA IN
INCREASING
ORDER OR
DECREASING
ORDER

TAKE THE ARITHMETIC
MEAN OF MIDDLE
VALUES ie
N/2 +N+1/2

WHEN
N IS
ODD
ARRANGE DATA IN
INCREASING OR
DECREASING ORDER
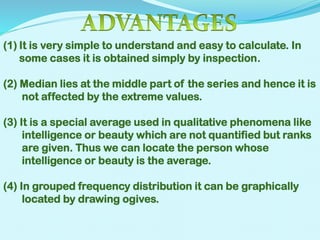
(1) It is very simple to understand and easy to calculate. In
some cases it is obtained simply by inspection.

(2) Median lies at the middle part of the series and hence it is
not affected by the extreme values.
(3) It is a special average used in qualitative phenomena like
intelligence or beauty which are not quantified but ranks
are given. Thus we can locate the person whose
intelligence or beauty is the average.

(4) In grouped frequency distribution it can be graphically
located by drawing ogives.
(1)In simple series, the item values have to be arranged. If the
series contains large number of items, then the process
becomes tedious.

(2) It is a less representative average because it does not depend
on all the items in the series.

(3) It is not capable of further algebraic treatment. For example,
we can not find a combined median of two or more groups if the
median of different groups are given.
(4) It is affected more by sampling fluctuations than the mean
as it is concerned with on1y one item i.e. the middle item
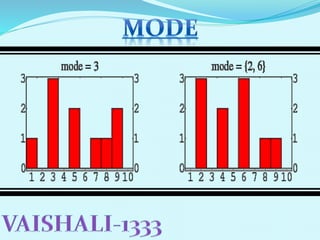
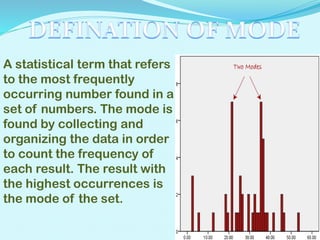
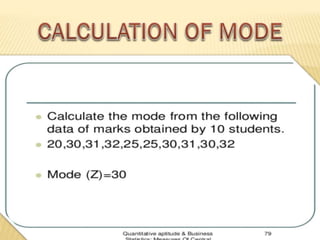
A statistical term that refers
to the most frequently
occurring number found in a
set of numbers. The mode is
found by collecting and
organizing the data in order
to count the frequency of
each result. The result with
the highest occurrences is
the mode of the set.
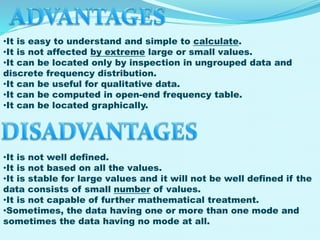
•It is easy to understand and simple to calculate.
•It is not affected by extreme large or small values.
•It can be located only by inspection in ungrouped data and
discrete frequency distribution.
•It can be useful for qualitative data.
•It can be computed in open-end frequency table.
•It can be located graphically.

•It is not well defined.
•It is not based on all the values.
•It is stable for large values and it will not be well defined if the
data consists of small number of values.
•It is not capable of further mathematical treatment.
•Sometimes, the data having one or more than one mode and
sometimes the data having no mode at all.
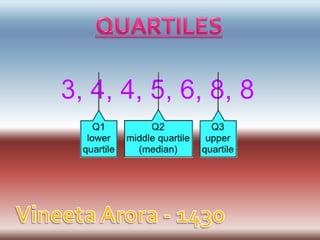
A statistical term describing a division of observations into four
defined intervals based upon the values of the data and how they
compare to the entire set of observations.
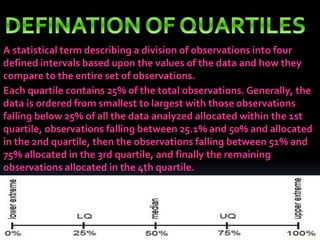
Each quartile contains 25% of the total observations. Generally, the
data is ordered from smallest to largest with those observations
falling below 25% of all the data analyzed allocated within the 1st
quartile, observations falling between 25.1% and 50% and allocated
in the 2nd quartile, then the observations falling between 51% and
75% allocated in the 3rd quartile, and finally the remaining
observations allocated in the 4th quartile.
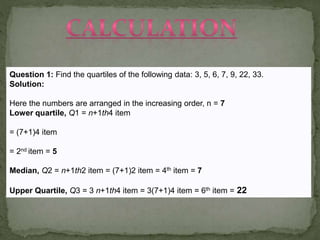
Question 1: Find the quartiles of the following data: 3, 5, 6, 7, 9, 22, 33.
Solution:
Here the numbers are arranged in the increasing order, n = 7
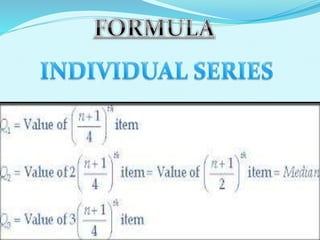
Lower quartile, Q1 = n+1th4 item

= (7+1)4 item
= 2nd item = 5
Median, Q2 = n+1th2 item = (7+1)2 item = 4th item = 7

Upper Quartile, Q3 = 3 n+1th4 item = 3(7+1)4 item = 6th item = 22
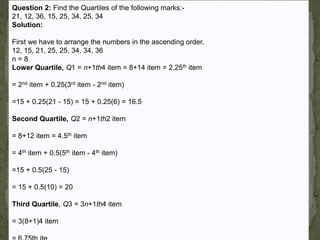
Question 2: Find the Quartiles of the following marks:21, 12, 36, 15, 25, 34, 25, 34
Solution:

First we have to arrange the numbers in the ascending order.
12, 15, 21, 25, 25, 34, 34, 36
n=8
Lower Quartile, Q1 = n+1th4 item = 8+14 item = 2.25th item
= 2nd item + 0.25(3rd item - 2nd item)
=15 + 0.25(21 - 15) = 15 + 0.25(6) = 16.5
Second Quartile, Q2 = n+1th2 item
= 8+12 item = 4.5th item
= 4th item + 0.5(5th item - 4th item)
=15 + 0.5(25 - 15)
= 15 + 0.5(10) = 20

Third Quartile, Q3 = 3n+1th4 item
= 3(8+1)4 item
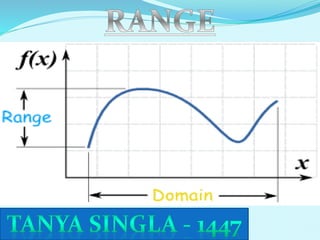
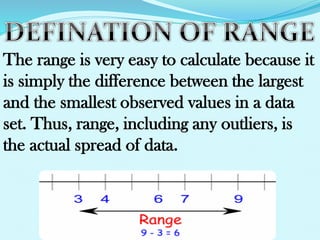
The range is very easy to calculate because it
is simply the difference between the largest
and the smallest observed values in a data
set. Thus, range, including any outliers, is
the actual spread of data.
Range = difference
between highest and
lowest observed values
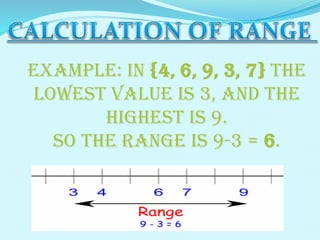
Example: In {4, 6, 9, 3, 7} the
lowest value is 3, and the
highest is 9.
So the range is 9-3 = 6.
The range is an informative tool used as a
supplement to other measures such as the
standard deviation or semi-interquartile range

The range value of a data set is greatly
influenced by the presence of just one unusually
large or small value (outlier).
The disadvantage of using range is that it does not measure
the spread of the majority of values in a data set—it only
measures the spread between highest and lowest values. As a
result, other measures are required in order to give a better
picture of the data spread.
MEASURES OF CENTRAL TENDENCY AND  MEASURES OF DISPERSION