OMG! MY METADATA IS AS
  FRESH AS THE BACKSTREET
 BOYS: HOW GOOGLE REFINE
 CAN UPDATE, CLEAN UP AND
LINK YOUR METADATA TO THE
             WIDER WORLD
                 SARAH BETH WEEKS

   LIBRARY TECHNOLOGY CONFERENCE 2013

                   WEEKSS@STOLAF.EDU
                       @RASCALWHALE
SAMPLE PROJECT: NORDIC AMERICAN
                IMPRINTS

Situation: Wanted to match publishers of our books against a
list of important Nordic American Publishers (compiled by Penny
Huf fman) to find materials for our special collections.
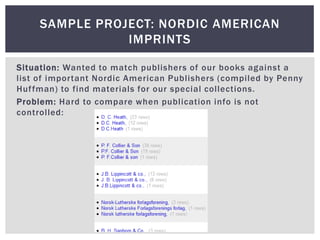
Problem: Hard to compare when publication info is not
controlled:
ANSWER: GOOGLE REFINE!

Google Refine can “match and
 merge” messy data filled with:
 Random, leading or trailing spaces
 stray punctuation
 typos
 odd capitalization
  and more!
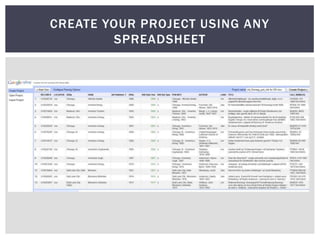
CREATE YOUR PROJECT USING ANY
        SPREADSHEET
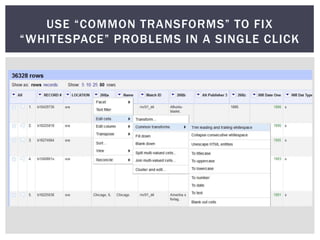
USE “COMMON TRANSFORMS” TO FIX
“WHITESPACE” PROBLEMS IN A SINGLE CLICK
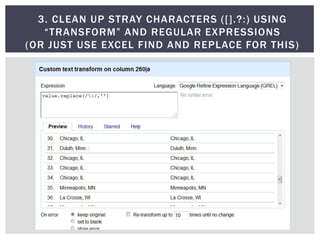
3. CLEAN UP STRAY CHARACTERS ([].?:) USING
   “TRANSFORM” AND REGULAR EXPRESSIONS
(OR JUST USE EXCEL FIND AND REPLACE FOR THIS)
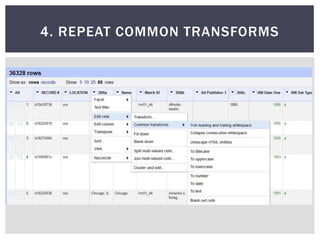
4. REPEAT COMMON TRANSFORMS
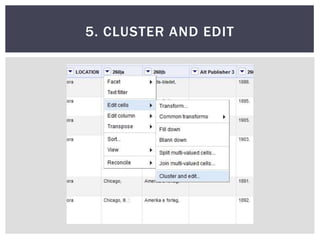
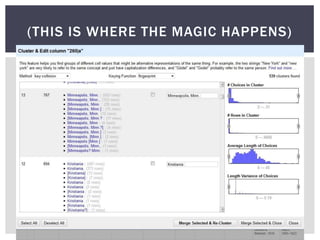
5. CLUSTER AND EDIT
(THIS IS WHERE THE MAGIC HAPPENS)
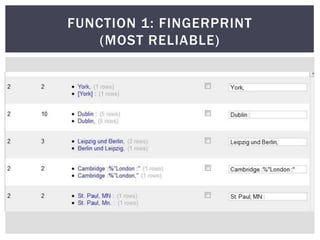
FUNCTION 1: FINGERPRINT
    (MOST RELIABLE)
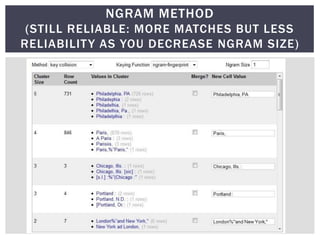
NGRAM METHOD
 (STILL RELIABLE: MORE MATCHES BUT LESS
RELIABILIT Y AS YOU DECREASE NGRAM SIZE)
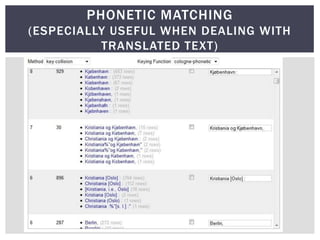
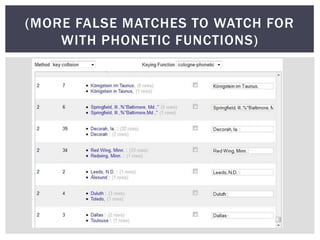
PHONETIC MATCHING
(ESPECIALLY USEFUL WHEN DEALING WITH
          TRANSLATED TEXT)
(MORE FALSE MATCHES TO WATCH FOR
    WITH PHONETIC FUNCTIONS)
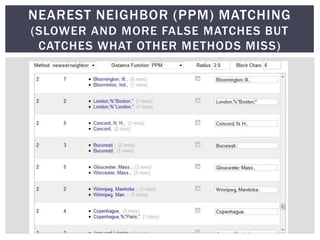
NEAREST NEIGHBOR (PPM) MATCHING
(SLOWER AND MORE FALSE MATCHES BUT
 CATCHES WHAT OTHER METHODS MISS)
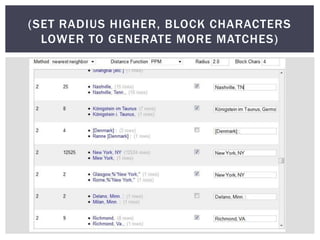
(SET RADIUS HIGHER, BLOCK CHARACTERS
  LOWER TO GENERATE MORE MATCHES)
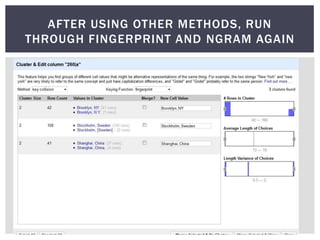
AFTER USING OTHER METHODS, RUN
THROUGH FINGERPRINT AND NGRAM AGAIN
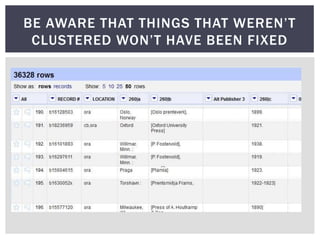
BE AWARE THAT THINGS THAT WEREN’T
 CLUSTERED WON’T HAVE BEEN FIXED
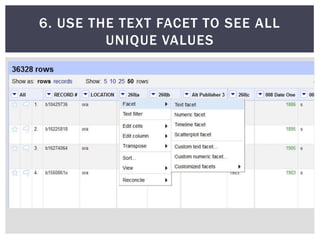
6. USE THE TEXT FACET TO SEE ALL
         UNIQUE VALUES
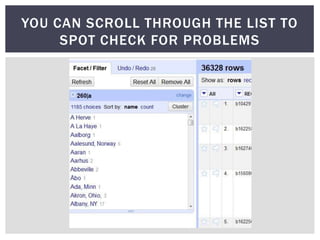
YOU CAN SCROLL THROUGH THE LIST TO
     SPOT CHECK FOR PROBLEMS
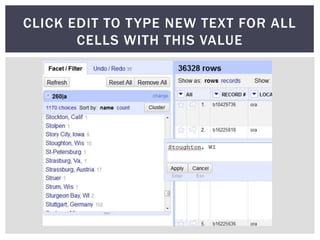
CLICK EDIT TO T YPE NEW TEXT FOR ALL
       CELLS WITH THIS VALUE
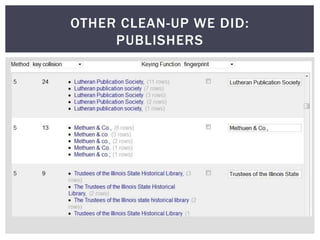
OTHER CLEAN-UP WE DID:
     PUBLISHERS
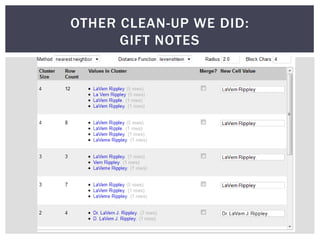
OTHER CLEAN-UP WE DID:
      GIFT NOTES
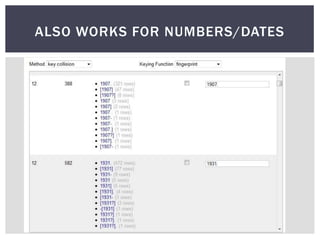
ALSO WORKS FOR NUMBERS/DATES
END RESULT?

 Using Google Refine we were able to reduce the
  3230 unique values for city (260|a) to just 1153. For
  publishers (260|b) we went from 11342 unique
  names for publishers to approximately 6500.
 This project helped to identify over 2,000 potential
  candidates for our Nordic American Imprints
  collection. (These are still being evaluated).
 The controlled publishers, cities of publications and
  dates will be added to a local 9xx field for faceting in
  our future special collections discover tool. Users will
  be able to browse our Nordic American Imprints
  collection by publisher, city or state.
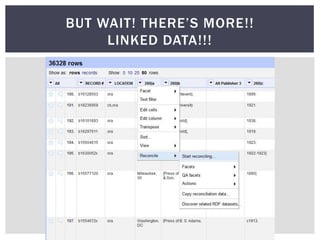
BUT WAIT! THERE’S MORE!!
     LINKED DATA!!!
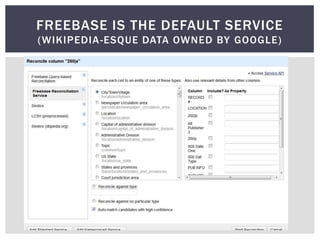
FREEBASE IS THE DEFAULT SERVICE
(WIKIPEDIA -ESQUE DATA OWNED BY GOOGLE)
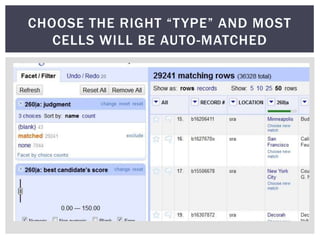
CHOOSE THE RIGHT “T YPE” AND MOST
   CELLS WILL BE AUTO-MATCHED
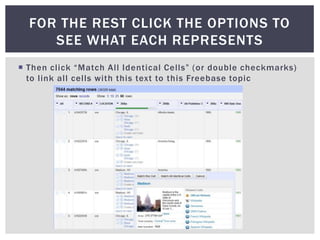
FOR THE REST CLICK THE OPTIONS TO
     SEE WHAT EACH REPRESENTS
 Then click “Match All Identical Cells” (or double checkmarks)
  to link all cells with this text to this Freebase topic
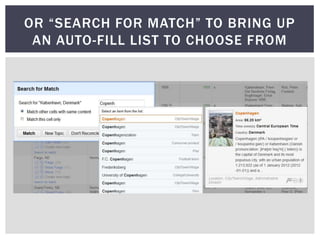
OR “SEARCH FOR MATCH” TO BRING UP
 AN AUTO-FILL LIST TO CHOOSE FROM
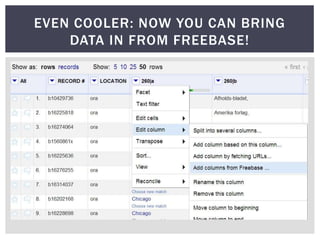
EVEN COOLER: NOW YOU CAN BRING
    DATA IN FROM FREEBASE!
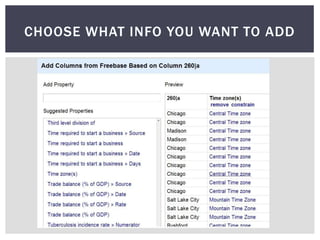
CHOOSE WHAT INFO YOU WANT TO ADD
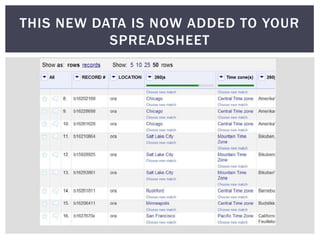
THIS NEW DATA IS NOW ADDED TO YOUR
           SPREADSHEET
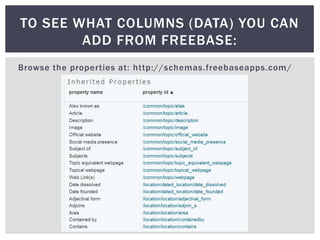
TO SEE WHAT COLUMNS (DATA) YOU CAN
        ADD FROM FREEBASE:
Browse the properties at: http://schemas.freebaseapps.com /
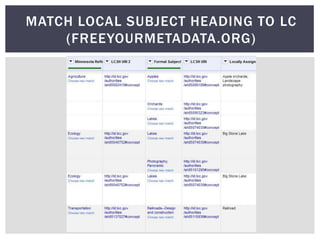
MATCH LOCAL SUBJECT HEADING TO LC
    (FREEYOURMETADATA.ORG)
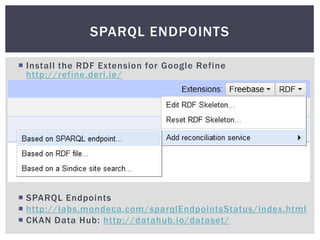
SPARQL ENDPOINTS

 Install the RDF Extension for Google Refine
  http://refine.deri.ie/


 SPARQL Endpoints
 http://labs.mondeca.com/sparqlEndpointsStatus/index.html
 CKAN Data Hub: http://datahub.io/dataset/
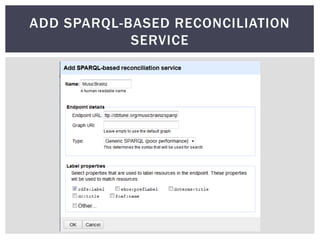
ADD SPARQL-BASED RECONCILIATION
            SERVICE
THANK YOU!

Questions?

Link to a public version of this presentation
 at my (personal) blog:
     gardenandalibrary.blogspot.com
I’m also happy to take questions by e-
 mail
              weekss@stolaf.edu