NOSQL
ROXANA TADAYON
05/04/2017
Outline
 Key-Values stores
 Document-Oriented Databases
 Column Family Stores
 Graph
Physical models, Architecture
What is NOSQL?
Stands for Not Only SQL
built in the early 2000s for the purpose
of large-scale database clustering in
cloud and web applications.
 Class of non-relational data storage
systems
 Usually do not require a fixed table
schema nor do they use the concept of
joins
https://db-engines.com/en/ranking
Why NOSQL
Relational Database Management System doesn’t have the
ability /capacity to handle:
The numbers of concurrent users
The amount of new data type such as unstructured data, stream data,
semi structured data
The continual increase in the amount of data that have been provided by
mobile, social media, geo-location data.
Why NOSQL
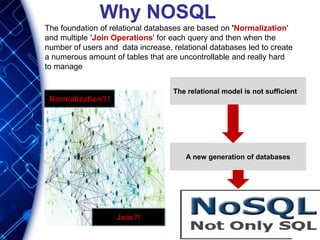
The foundation of relational databases are based on 'Normalization'
and multiple 'Join Operations' for each query and then when the
number of users and data increase, relational databases led to create
a numerous amount of tables that are uncontrollable and really hard
to manage
Normalization?!
Join?!
The relational model is not sufficient
A new generation of databases
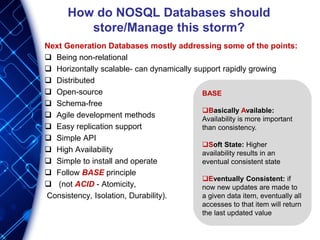
How do NOSQL Databases should
store/Manage this storm?
Next Generation Databases mostly addressing some of the points:
 Being non-relational
 Horizontally scalable- can dynamically support rapidly growing
 Distributed
 Open-source
 Schema-free
 Agile development methods
 Easy replication support
 Simple API
 High Availability
 Simple to install and operate
 Follow BASE principle
 (not ACID - Atomicity,
Consistency, Isolation, Durability).
BASE
Basically Available:
Availability is more important
than consistency.
Soft State: Higher
availability results in an
eventual consistent state
Eventually Consistent: if
now new updates are made to
a given data item, eventually all
accesses to that item will return
the last updated value
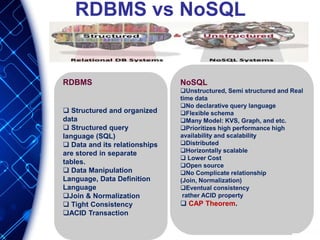
RDBMS vs NoSQL
RDBMS
 Structured and organized
data
 Structured query
language (SQL)
 Data and its relationships
are stored in separate
tables.
 Data Manipulation
Language, Data Definition
Language
Join & Normalization
 Tight Consistency
ACID Transaction
NoSQL
Unstructured, Semi structured and Real
time data
No declarative query language
Flexible schema
Many Model: KVS, Graph, and etc.
Prioritizes high performance high
availability and scalability
Distributed
Horizontally scalable
 Lower Cost
Open source
No Complicate relationship
(Join, Normalization)
Eventual consistency
rather ACID property
 CAP Theorem.
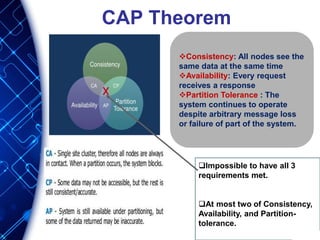
CAP Theorem
Consistency: All nodes see the
same data at the same time
Availability: Every request
receives a response
Partition Tolerance : The
system continues to operate
despite arbitrary message loss
or failure of part of the system.
Impossible to have all 3
requirements met.
At most two of Consistency,
Availability, and Partition-
tolerance.
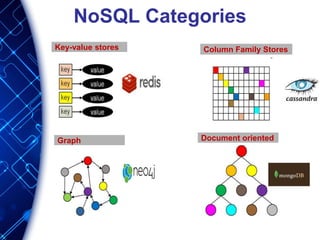
NoSQL Categories
Key-value stores
Document oriented
Column Family Stores
Graph
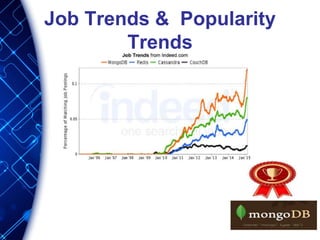
Job Trends & Popularity
Trends
Document-Oriented Databases
 Documents are the main concept.
 A Document-Oriented database stores and retrieves documents in some standard
format(s):
 JSON
 XML
 BSON
 YAML
 Binary forms (like PDF and MS Word).
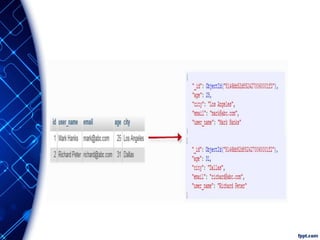
 Document is similar to row or record in relation DB, but more flexible (Documents have
differences in their attributes).
 Document are indexed
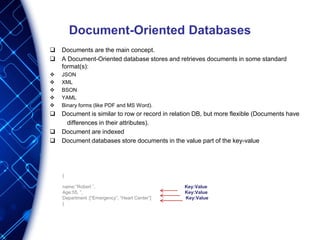
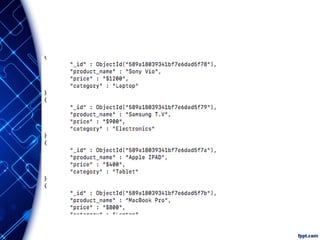
 Document databases store documents in the value part of the key-value
{
name:”Robert ”, Key:Value
Age:55, ”, Key:Value
Department :[“Emergency”, “Heart Center”] Key:Value
}
The best known examples of Document-Oriented
Databases
MONGO DB
MongoDB Overview
 MongoDB is a scalable and high-performance open source database.
 MongoDB can Store complex documents as arrays, hash tables, integers, objects and
every thing else supported by JSON .
 Written in C++
 Has driver to all most every popular language programming
 Full Index Support
 Built-In Replication & Cluster Management
 Data redundancy
 Fault tolerant (automatic failover AND recovery)
 Consistency (wait-for-propagate or write-and-forget)
 Simplified maintenance
 Distributed Storage (Sharding)
 Base on define shard key.
 It’s enabling horizontal scaling across multiple nodes.
 Auto-Balances as shard servers are added or removed
 Failover handled through replica sets.
 Map Reduce queries are run in parallel across shards.
MongoDB in
many ways “feels”
like an RDMS
Who is using MongoDB?
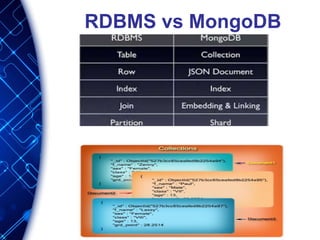
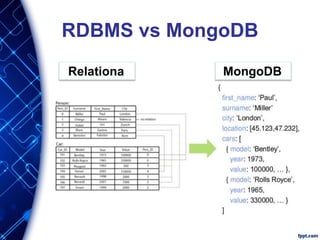
RDBMS vs MongoDB
RDBMS vs MongoDB
Relational MongoDBl
MongoDB Advantages
 To reduce complexity
 Get rid of migrations
 No create table
 No alter column
 No add column
 No change column
 Get rid of relationships
 Many to one/ One to Many/ Many to Many
 Reduce number of database requests
 Joined
 Rich queries
 In-place updates
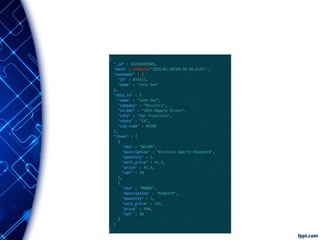
 JSON
 MongoDB knows JSON
 Don’t have to convert data from / to JSON
 Adapt to changes
 Changes in schema
 Changes in data & algorithms $set, $unset, $push, $rename,
 Changes for performance & scaling
Data Types
 String : This is most commonly used datatype to store the data. String in mongodb
must be UTF-8 valid.
 Integer : This type is used to store a numerical value. Integer can be 32 bit or 64 bit
depending upon your server.
 Boolean : This type is used to store a boolean (true/ false) value.
 Double : This type is used to store floating point values.
 Min/ Max keys : This type is used to compare a value against the lowest and highest
BSON elements.
 Arrays : This type is used to store arrays or list or multiple values into one key.
 Timestamp : ctimestamp. This can be handy for recording when a document has been
modified or added.
 Object : This datatype is used for embedded documents.
 Null : This type is used to store a Null value.
 Symbol : This datatype is used identically to a string however, it's generally reserved
for languages that use a specific symbol type.
 Date : This datatype is used to store the current date or time in UNIX time format. You
can specify your own date time by creating object of Date and passing day, month, year
into it.
 Object ID : This datatype is used to store the document’s ID.
 Binary data : This datatype is used to store binay data.
 Code : This datatype is used to store javascript code into document.
 Regular expression : This datatype is used to store regular expression
Data Modeling
MongoDB is the most similar database to relational database
regarding data Modeling, but there exists some significant
differences between the document oriented model and the
relational model:
 Flexible schema
 Lack of join in MongoDB
 Arrays & Embedded-Documents
 De-Normalization
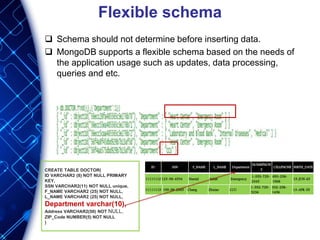
Flexible schema
 Schema should not determine before inserting data.
 MongoDB supports a flexible schema based on the needs of
the application usage such as updates, data processing,
queries and etc.
CREATE TABLE DOCTOR(
ID VARCHAR2 (8) NOT NULL PRIMARY
KEY,
SSN VARCHAR2(11) NOT NULL unique,
F_NAME VARCHAR2 (25) NOT NULL,
L_NAME VARCHAR2 (25) NOT NULL,
Department varchar(10),
Address VARCHAR2(50) NOT NULL,
ZIP_Code NUMBER(5) NOT NULL
)
ID SSN F_NAME L_NAME Department
HOMEPHON
E
CELLPHONE BIRTH_DATE
11111112 123-98-4534 Hamid Sahat Emergency
1-555-729-
2345
693-258-
1968
15-JUN-63
11111113 199-98-2365 Chang Zhxiao CCU
1-552-729-
5236
332-258-
1456
13-APR-55
Lack of join in MongoDB
 Data spilt horizontally on different clients and
therefore, to perform so many joins on different
applications’ server is unrealistic.
 Supports a left outer join to an unsharded collection
in the same database($lookup ).
 It supports partially the relational model(Primary
key & Foreign Key)
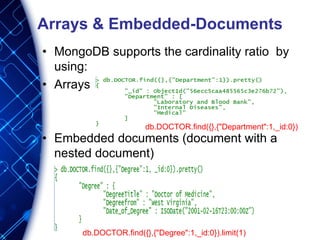
Arrays & Embedded-Documents
• MongoDB supports the cardinality ratio by
using:
• Arrays
• Embedded documents (document with a
nested document)
db.DOCTOR.find({},{"Department":1,_id:0})
db.DOCTOR.find({},{"Degree":1,_id:0}).limit(1)
De-Normalization
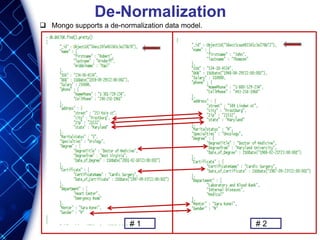
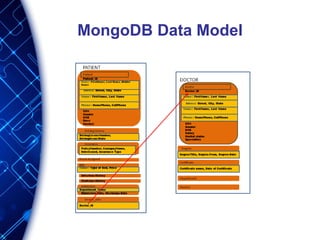
 Mongo supports a de-normalization data model.
# 1#1 # 2#1
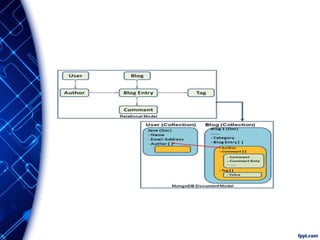
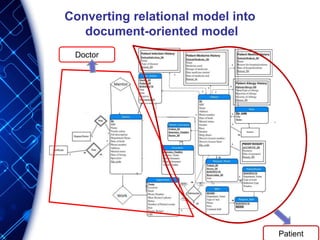
Converting relational model into
document-oriented model
Doctor
Patient
MongoDB Data Model
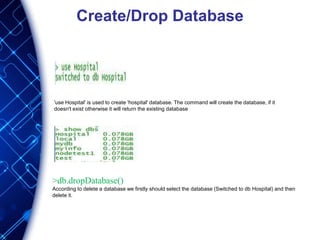
Create/Drop Database
'use Hospital' is used to create 'hospital' database. The command will create the database, if it
doesn't exist otherwise it will return the existing database
>db.dropDatabase()
According to delete a database we firstly should select the database (Switched to db Hospital) and then
delete it.
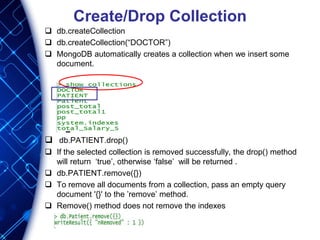
Create/Drop Collection
 db.createCollection
 db.createCollection(“DOCTOR”)
 MongoDB automatically creates a collection when we insert some
document.
 db.PATIENT.drop()
 If the selected collection is removed successfully, the drop() method
will return ‘true’, otherwise ‘false’ will be returned .
 db.PATIENT.remove({})
 To remove all documents from a collection, pass an empty query
document '{}' to the ’remove’ method.
 Remove() method does not remove the indexes
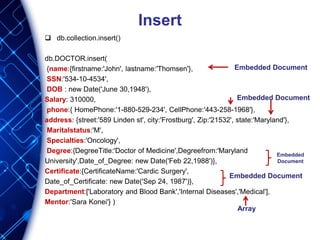
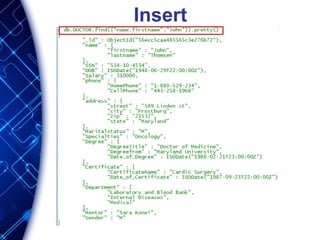
Insert
 db.collection.insert()
db.DOCTOR.insert(
{name:{firstname:'John', lastname:'Thomsen'},
SSN:'534-10-4534',
DOB : new Date('June 30,1948'),
Salary: 310000,
phone:{ HomePhone:'1-880-529-234', CellPhone:'443-258-1968'},
address: {street:'589 Linden st', city:'Frostburg', Zip:'21532', state:'Maryland'},
Maritalstatus:'M',
Specialties:'Oncology',
Degree:{DegreeTitle:'Doctor of Medicine',Degreefrom:'Maryland
University',Date_of_Degree: new Date('Feb 22,1988')},
Certificate:{CertificateName:'Cardic Surgery',
Date_of_Certificate: new Date('Sep 24, 1987')},
Department:['Laboratory and Blood Bank','Internal Diseases','Medical'],
Mentor:'Sara Konei'} )
Embedded Document
Embedded Document
Embedded
Document
Embedded Document
Array
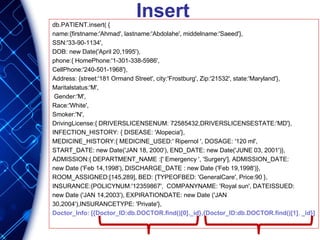
Insert
Insertdb.PATIENT.insert( {
name:{firstname:'Ahmad', lastname:'Abdolahe', middelname:'Saeed'},
SSN:'33-90-1134',
DOB: new Date('April 20,1995'),
phone:{ HomePhone:'1-301-338-5986',
CellPhone:'240-501-1968'},
Address: {street:'181 Ormand Street', city:'Frostburg', Zip:'21532', state:'Maryland'},
Maritalstatus:'M',
Gender:'M',
Race:'White',
Smoker:'N',
DrivingLicense:{ DRIVERSLICENSENUM: 72585432,DRIVERSLICENSESTATE:'MD'},
INFECTION_HISTORY: { DISEASE: 'Alopecia'},
MEDICINE_HISTORY:{ MEDICINE_USED:' Ripernol ', DOSAGE: '120 ml',
START_DATE: new Date('JAN 18, 2000'), END_DATE: new Date('JUNE 03, 2001')},
ADMISSION:{ DEPARTMENT_NAME :[' Emergency ', 'Surgery'], ADMISSION_DATE:
new Date ('Feb 14,1998'), DISCHARGE_DATE : new Date ('Feb 19,1998')},
ROOM_ASSIGNED:[145,289], BED: {TYPEOFBED: 'GeneralCare', Price:90 },
INSURANCE:{POLICYNUM:'12359867', COMPANYNAME: 'Royal sun', DATEISSUED:
new Date ('JAN 14,2003'), EXPIRATIONDATE: new Date ('JAN
30,2004'),INSURANCETYPE: 'Private'},
Doctor_Info: [{Doctor_ID:db.DOCTOR.find()[0]._id},{Doctor_ID:db.DOCTOR.find()[1]. _id}]
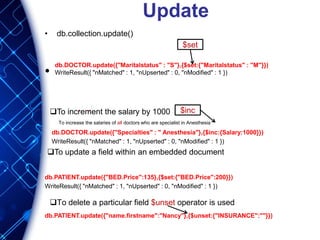
Update
• db.collection.update()
•
db.DOCTOR.update({"Specialties" : " Anesthesia"},{$inc:{Salary:1000}})
WriteResult({ "nMatched" : 1, "nUpserted" : 0, "nModified" : 1 })
db.PATIENT.update({"BED.Price":135},{$set:{"BED.Price":200}})
WriteResult({ "nMatched" : 1, "nUpserted" : 0, "nModified" : 1 })
db.PATIENT.update({"name.firstname":"Nancy"},{$unset:{"INSURANCE":""}})
$set
To increment the salary by 1000 $inc
To update a field within an embedded document
To increase the salaries of all doctors who are specialist in Anesthesia
To delete a particular field $unset operator is used
db.DOCTOR.update({"Maritalstatus" : "S"},{$set:{"Maritalstatus" : "M"}})
WriteResult({ "nMatched" : 1, "nUpserted" : 0, "nModified" : 1 })
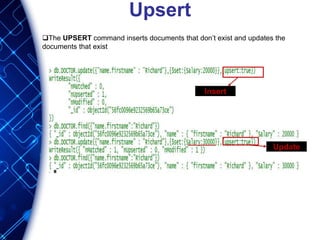
Upsert
The UPSERT command inserts documents that don’t exist and updates the
documents that exist
Insert
Update
Aggregation & Queries
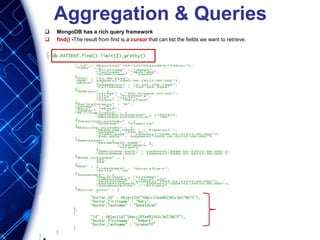
 MongoDB has a rich query framework
 find() -The result from find is a cursor that can list the fields we want to retrieve.
Aggregation & Queries
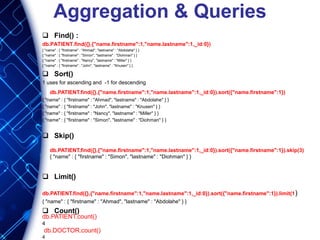
 Find() :
db.PATIENT.find({},{"name.firstname":1,"name.lastname":1,_id:0})
{ "name" : { "firstname" : "Ahmad", "lastname" : "Abdolahe" } }
{ "name" : { "firstname" : "Simon", "lastname" : "Diohman" } }
{ "name" : { "firstname" : "Nancy", "lastname" : "Miller" } }
{ "name" : { "firstname" : "John", "lastname" : "Knusen" } }
 Sort()
1 uses for ascending and -1 for descending
{ "name" : { "firstname" : "Ahmad", "lastname" : "Abdolahe" } }
{ "name" : { "firstname" : "John", "lastname" : "Knusen" } }
{ "name" : { "firstname" : "Nancy", "lastname" : "Miller" } }
{ "name" : { "firstname" : "Simon", "lastname" : "Diohman" } }
 Skip()
 Limit()
db.PATIENT.find({},{"name.firstname":1,"name.lastname":1,_id:0}).sort({"name.firstname":1}).limit(1)
{ "name" : { "firstname" : "Ahmad", "lastname" : "Abdolahe" } }
 Count()
db.PATIENT.find({},{"name.firstname":1,"name.lastname":1,_id:0}).sort({"name.firstname":1})
db.PATIENT.find({},{"name.firstname":1,"name.lastname":1,_id:0}).sort({"name.firstname":1}).skip(3)
{ "name" : { "firstname" : "Simon", "lastname" : "Diohman" } }
db.PATIENT.count()
4
db.DOCTOR.count()
4
Aggregation & Queries
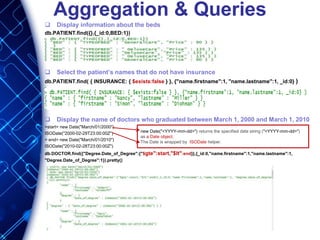
 Display information about the beds
db.PATIENT.find({},{_id:0,BED:1})
 Select the patient’s names that do not have insurance
db.PATIENT.find( { INSURANCE: { $exists:false } }, {"name.firstname":1, "name.lastname":1, _id:0} )
 Display the name of doctors who graduated between March 1, 2000 and March 1, 2010
>start= new Date("March/01/2000")
ISODate("2000-02-29T23:00:00Z")
> end= new Date("March/01/2010")
ISODate("2010-02-28T23:00:00Z")
db.DOCTOR.find({"Degree.Date_of_Degree":{"$gte":start,"$lt":end}},{_id:0,"name.firstname":1,"name.lastname":1,
"Degree.Date_of_Degree":1}).pretty()
new Date("<YYYY-mm-dd>") returns the specified date string ("<YYYY-mm-dd>")
as a Date object.
The Date is wrapped by ISODate helper.
Aggregation Pipeline
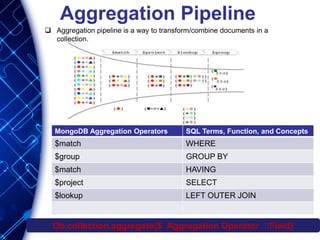
 Aggregation pipeline is a way to transform/combine documents in a
collection.
MongoDB Aggregation Operators SQL Terms, Function, and Concepts
$match WHERE
$group GROUP BY
$match HAVING
$project SELECT
$lookup LEFT OUTER JOIN
Db.collection.aggregate{$ Aggregation Operator :Field}
Aggregation & Queries
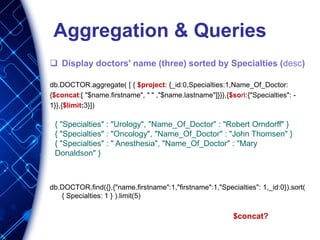
 Display doctors' name (three) sorted by Specialties (desc)
db.DOCTOR.aggregate( [ { $project: {_id:0,Specialties:1,Name_Of_Doctor:
{$concat:[ "$name.firstname", " " ,"$name.lastname"]}}},{$sort:{"Specialties": -
1}},{$limit:3}])
db.DOCTOR.find({},{"name.firstname":1,"firstname":1,"Specialties": 1,_id:0}).sort(
{ Specialties: 1 } ).limit(5)
$concat?
{ "Specialties" : "Urology", "Name_Of_Doctor" : "Robert Orndorff" }
{ "Specialties" : "Oncology", "Name_Of_Doctor" : "John Thomsen" }
{ "Specialties" : " Anesthesia", "Name_Of_Doctor" : "Mary
Donaldson" }
Aggregation & Queries
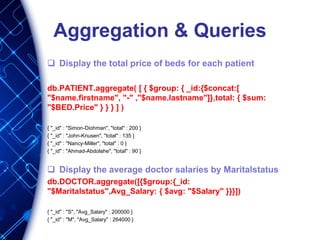
 Display the total price of beds for each patient
db.PATIENT.aggregate( [ { $group: { _id:{$concat:[
"$name.firstname", "-" ,"$name.lastname"]},total: { $sum:
"$BED.Price" } } } ] )
{ "_id" : "Simon-Diohman", "total" : 200 }
{ "_id" : "John-Knusen", "total" : 135 }
{ "_id" : "Nancy-Miller", "total" : 0 }
{ "_id" : "Ahmad-Abdolahe", "total" : 90 }
 Display the average doctor salaries by Maritalstatus
db.DOCTOR.aggregate([{$group:{_id:
"$Maritalstatus",Avg_Salary: { $avg: "$Salary" }}}])
{ "_id" : "S", "Avg_Salary" : 200000 }
{ "_id" : "M", "Avg_Salary" : 264000 }
Aggregation & Queries
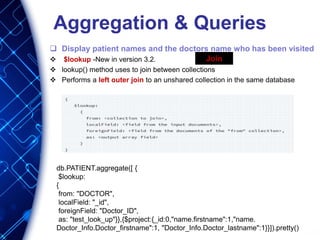
 Display patient names and the doctors name who has been visited
 $lookup -New in version 3.2.
 lookup() method uses to join between collections
 Performs a left outer join to an unshared collection in the same database
db.PATIENT.aggregate([ {
$lookup:
{
from: "DOCTOR",
localField: "_id",
foreignField: "Doctor_ID",
as: "test_look_up"}},{$project:{_id:0,"name.firstname":1,"name.
Doctor_Info.Doctor_firstname":1, "Doctor_Info.Doctor_lastname":1}}]).pretty()
Join
Aggregation & Queries
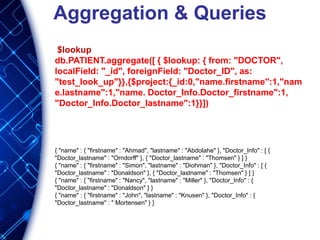
$lookup
db.PATIENT.aggregate([ { $lookup: { from: "DOCTOR",
localField: "_id", foreignField: "Doctor_ID", as:
"test_look_up"}},{$project:{_id:0,"name.firstname":1,"nam
e.lastname":1,"name. Doctor_Info.Doctor_firstname":1,
"Doctor_Info.Doctor_lastname":1}}])
{ "name" : { "firstname" : "Ahmad", "lastname" : "Abdolahe" }, "Doctor_Info" : [ {
"Doctor_lastname" : "Orndorff" }, { "Doctor_lastname" : "Thomsen" } ] }
{ "name" : { "firstname" : "Simon", "lastname" : "Diohman" }, "Doctor_Info" : [ {
"Doctor_lastname" : "Donaldson" }, { "Doctor_lastname" : "Thomsen" } ] }
{ "name" : { "firstname" : "Nancy", "lastname" : "Miller" }, "Doctor_Info" : {
"Doctor_lastname" : "Donaldson" } }
{ "name" : { "firstname" : "John", "lastname" : "Knusen" }, "Doctor_Info" : {
"Doctor_lastname" : " Mortensen" } }
Aggregation & Queries
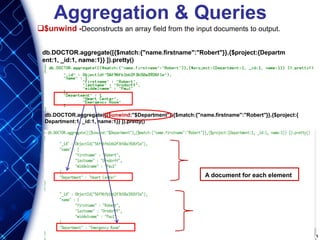
db.DOCTOR.aggregate([{$match:{"name.firstname":"Robert"}},{$project:{Departm
ent:1, _id:1, name:1}} ]).pretty()
db.DOCTOR.aggregate([{$unwind:"$Department"},{$match:{"name.firstname":"Robert"}},{$project:{
Department:1, _id:1, name:1}} ]).pretty()
$unwind -Deconstructs an array field from the input documents to output.
A document for each element.
Aggregation & Queries
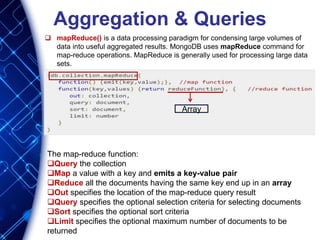
 mapReduce() is a data processing paradigm for condensing large volumes of
data into useful aggregated results. MongoDB uses mapReduce command for
map-reduce operations. MapReduce is generally used for processing large data
sets.
The map-reduce function:
Query the collection
Map a value with a key and emits a key-value pair
Reduce all the documents having the same key end up in an array
Out specifies the location of the map-reduce query result
Query specifies the optional selection criteria for selecting documents
Sort specifies the optional sort criteria
Limit specifies the optional maximum number of documents to be
returned
Array
Aggregation & Queries
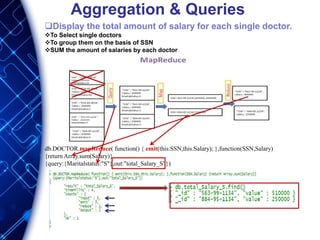
Display the total amount of salary for each single doctor.
To Select single doctors
To group them on the basis of SSN
SUM the amount of salaries by each doctor
db.DOCTOR.mapReduce( function() { emit(this.SSN,this.Salary); },function(SSN,Salary)
{return Array.sum(Salary)},
{query:{Maritalstatus:"S"},out:"total_Salary_S"})
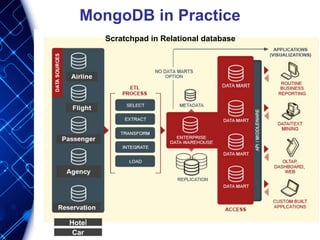
MongoDB in Practice
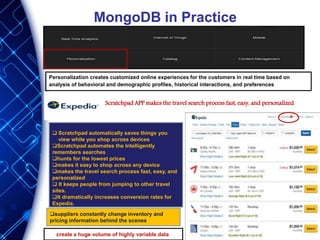
Personalization creates customized online experiences for the customers in real time based on
analysis of behavioral and demographic profiles, historical interactions, and preferences.
 Scratchpad automatically saves things you
view while you shop across devices
Scratchpad automates the Intelligently
remembers searches
hunts for the lowest prices
makes it easy to shop across any device
makes the travel search process fast, easy, and
personalized
 It keeps people from jumping to other travel
sites.
It dramatically increases conversion rates for
Expedia.
suppliers constantly change inventory and
pricing information behind the scenes.
create a huge volume of highly variable data.
Scratchpad APP makes the travel search process fast, easy, and personalized
MongoDB in Practice
Scratchpad in Relational database
Hotel
Car
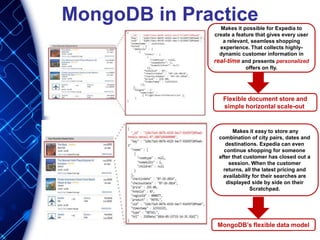
MongoDB in PracticeMakes it possible for Expedia to
create a feature that gives every user
a relevant, seamless shopping
experience. That collects highly-
dynamic customer information in
real-time and presents personalized
offers on fly.
Flexible document store and
simple horizontal scale-out
Makes it easy to store any
combination of city pairs, dates and
destinations. Expedia can even
continue shopping for someone
after that customer has closed out a
session. When the customer
returns, all the latest pricing and
availability for their searches are
displayed side by side on their
Scratchpad.
MongoDB’s flexible data model
Graph Database
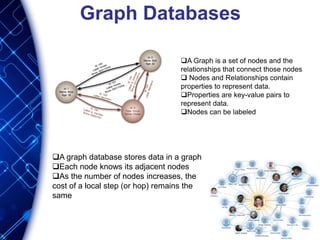
Graph Databases
A Graph is a set of nodes and the
relationships that connect those nodes
 Nodes and Relationships contain
properties to represent data.
Properties are key-value pairs to
represent data.
Nodes can be labeled
A graph database stores data in a graph
Each node knows its adjacent nodes
As the number of nodes increases, the
cost of a local step (or hop) remains the
same
The best known examples of Graph Database
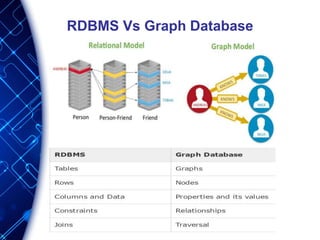
RDBMS Vs Graph Database
Why use a graph database?
 Greater performance – compared to NoSQL stores or relational
databases, graph databases offer much faster access to complex
connected data, mainly as they lack expensive ‘join’ operations. In
one example, a graph database was 1000x faster than a relational
database when working with a query depth of four.
 Lower latency – users of graph databases experience lower levels
of latency. As the nodes and links ‘point’ to one another, millions of
related records can be traversed per second and query response
time remains constant irrespective of the overall database size.
 Flexible and agile – a graph database should closely match the
structure of the data it uses. This allows developers to start work
sooner without the added complexity of mapping data across
tables.
 Good for semi-structured data – graph databases are schema
free, meaning patchy data, or data with exceptional attributes, don’t
pose a structural problem.
Neo4j
Neo4j Overview
 Neo4j is world’s leading graph databases
 Neo Technology is creator of Neo4j
 Follows Property Graph Data Model
 Is written in Java Language.
 CQL(Cypher Query Language) as query
language
 An open source
 Schema-free
 Full ACID
 High Availability
 Supports highly connected data
 It provides REST API to be accessed by any
Programming Language like Java.
Who is using Neo4j?
Advantages of Neo4j
 Easy to model and store relationships
 CQL query language commands are very easy to learn.
 It is very easy to represent connected data.
 It is very easy and faster to retrieve/traversal/navigation data
 It represents semi-structured data very easily.
 Intuitiveness- In humane readable format
 Speed
 It uses simple and powerful data model.
 Performance of relationship traversal remains constant with
growth in data size
 Fast agile development and evolution-It has a naturally
adaptive model
 Scalability-Neo4j scales up and out, supporting tens of
billions of nodes and relationships, and hundreds of
thousands of ACID transactions per second
Property Value Types
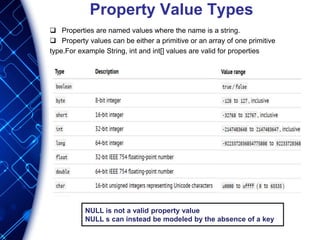
 Properties are named values where the name is a string.
 Property values can be either a primitive or an array of one primitive
type.For example String, int and int[] values are valid for properties
NULL is not a valid property value
NULL s can instead be modeled by the absence of a key
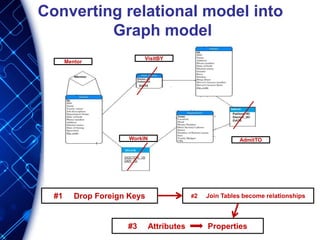
Converting relational model into
Graph model
#1 Drop Foreign Keys #2 Join Tables become relationships
#3 Attributes Properties
AdmitTO
VisitBY
WorkIN
Mentor
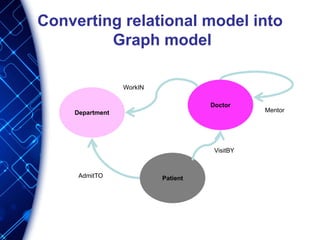
Converting relational model into
Graph model
Department
Doctor
Patient
WorkIN
AdmitTO
VisitBY
Mentor
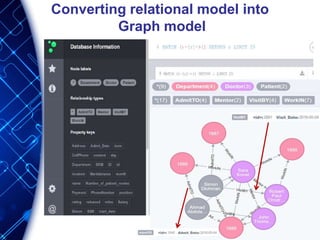
Converting relational model into
Graph model
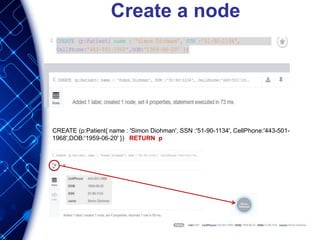
Create a node
MATCH (p: Patient)where p.name= 'Simon Diohman' RETURN p
CREATE (p:Patient{ name : 'Simon Diohman', SSN :'51-90-1134', CellPhone:'443-501-
1968',DOB:'1959-06-20' }) RETURN p
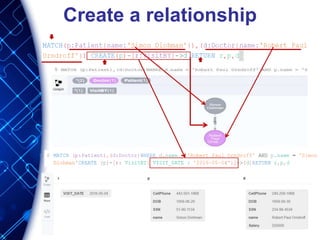
Create a relationship
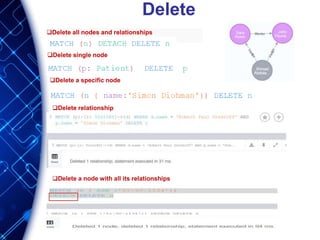
Delete
Delete all nodes and relationships
Delete single node
Delete a specific node
Delete relationship
Delete a node with all its relationships
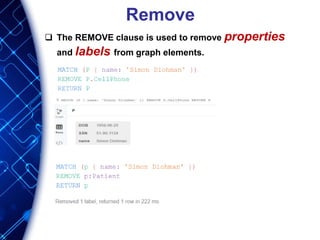
Remove
 The REMOVE clause is used to remove properties
and labels from graph elements.
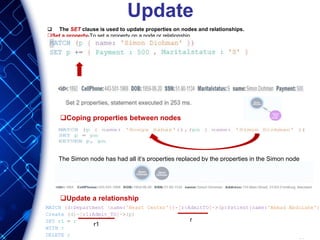
Update
 The SET clause is used to update properties on nodes and relationships.
Set a property-To set a property on a node or relationship
Coping properties between nodes
The Simon node has had all it’s properties replaced by the properties in the Simon node
Update a relationship
r
r1
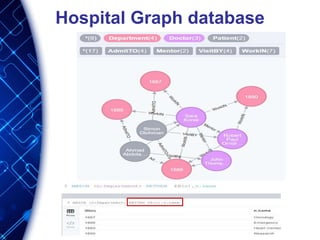
Hospital Graph database
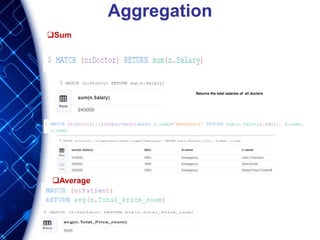
Aggregation
Average
Sum
Returns the total salaries of all doctors
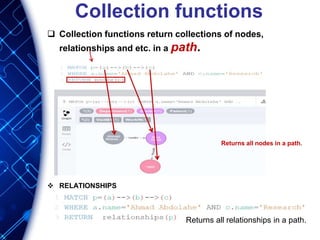
Collection functions
 Collection functions return collections of nodes,
relationships and etc. in a path.
 RELATIONSHIPS
Returns all nodes in a path.
Returns all relationships in a path.
Neo4j in Practice
Insurance Fraud
 Insurance Fraud is the filing of a false
claim to life, health, automobile, property,
workers' compensation or other types of
insurance benefits.
 Insurance fraud is a significant and costly problem for both
policyholders and insurance companies.
 Insurance companies lose millions of dollars each year through
fraudulent claims, largely because they do not have a way to easily
determine which claims are legitimate and which may be fraudulent.
Insurance companies shift the
risk of loss to their customers
Neo4j in Practice
Typical Scenario
 Rings of fraudsters work together to stage fake accidents.
 Such rings normally include a number of roles.
 Providers. Collusions typically involve participation from
professionals in several categories:
a. Doctors, who diagnose false injuries
b. Lawyers, who file fraudulent claims, and
c. Body shops, which misrepresent damage to cars 2.
 Participants. These are the people involved in the
(false) accident, and normally include:
a. Drivers
b. Passengers
c. Pedestrians
d. Witnesses
Neo4j in Practice
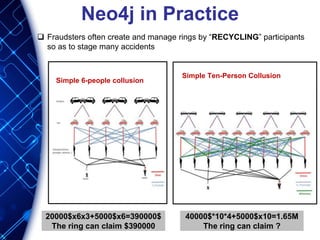
Simple 6-people collusion
Simple Ten-Person Collusion
20000$x6x3+5000$x6=390000$
The ring can claim $390000
40000$*10*4+5000$x10=1.65M
The ring can claim ?
 Fraudsters often create and manage rings by “RECYCLING” participants
so as to stage many accidents
Neo4j in Practice
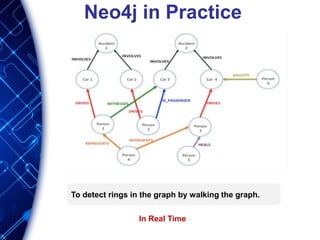
To detect rings in the graph by walking the graph.
In Real Time
References
 https://www.youtube.com/watch?v=A4gRg-9jNF4
 http://www.aerospike.com/what-is-a-key-value-store/
 A. P. D. P. Ameya Nayak, "Type of NOSQL Databases and its Comparison with
Relational Databases
 vol. International Journal of Applied Information Systems (IJAIS), no. ISSN : 2249-
0868, March 2013.
 J. Kaur, "Distributed Hash Tables," 2014.
 https://www.youtube.com/watch?v=i1KAvQ-pw08.
 http://db-engines.com/en/ranking
 https://redislabs.com
 http://redis.io/
 https://www.youtube.com/watch?v=A4gRg-
9jNF4&ebc=ANyPxKoFk4OYpr8O4v1Nf2ugf-
 uEiStTzLxdMdyHf2KFxV5IuvDLA2wpMyAdsWbb9OP9H5KWwmK7wJuYe7d4cb8e3N
YMuEDsRQ
 http://www.tutorialspoint.com/redis/redis_quick_guide.htm
 http://antirez.com/news/75
 M. Paksula, "Persisting Objects in Redis Key-Value Database," University of Helsinki,
Department of
 Computer Science, Helsinki, Finland.
 http://www.lynda.com/NoSQL-tutorials/Understanding-key-value-
stores/368756/387726-4.html
 http://data-magnum.com/9-lessons-for-starting-a-big-data-initiative-and-selecting-the-
right-nosql-tools/
References
 K. Segun, &quot;The little MongoDB Book&quot;.
 https://docs.mongodb.org/manual/core/data-modeling- introduction/.
 https://docs.mongodb.org/manual/core/data-model- design/.
 T. L. MongoDB.
 https://docs.mongodb.org/manual/tutorial/query-documents/
 https://www.mongodb.com/blog/post/joins-and- other-aggregation- enhancements-
coming- in-
 mongodb-3- 2-part- 1-of- 3-introduction
 https://docs.mongodb.org/manual/reference/method/db.collection.save/
 http://www.tutorialspoint.com/mongodb/mongodb_update_document.htm
 https://docs.mongodb.org/manual/tutorial/query-documents/
 http://www.tutorialspoint.com/cassandra/cassandra_cql_datatypes.htm
 http://www.planetcassandra.org/try-cassandra/
 https://dzone.com/refcardz/apache-cassandra
 http://docs.datastax.com/en/cassandra/2.0/cassandra/architecture/architectureDataDist
ributeReplication_c.html
 https://pdfs.semanticscholar.org/22c6/740341ef13d3c5ee52044a4fbaad911f7322.pdf
 http://gettingstartedwithcassandra.blogspot.com/2011/06/cassandra-keyspaces-what-
are-they.html
 http://docs.datastax.com/en/cql/3.1/cql/cql_reference/create_keyspace_r.html
 http://docs.datastax.com/en/cql/3.1/cql/cql_reference/create_table_r.html
References
 http://www.slideshare.net/cjohannsen/apache-cassandra-at-the-geek2geek-berlin
 http://docs.datastax.com/en/cassandra/2.0/cassandra/architecture/architectureIntro_c.ht
ml
 http://www.slideshare.net/planetcassandra/configuring-an-apache-cassandra-node
 http://distributeddatastore.blogspot.com/2015/08/cassandra-replication.html
 http://learn.exponential.io/courses/cassandra-consistency/lectures/98884
 http://docs.datastax.com/en/cassandra/2.0/cassandra/architecture/architectureIntro_c.ht
ml
 http://www.slideshare.net/VaradMeru/cassandra-a-decentralized-structured-storage-
system
 https://grockdoc.com/cassandra/2.1/articles/consistency_bdd0c698-463d-4bdb-b6f7-
8118f601ba09
 https://www.cs.cornell.edu/projects/ladis2009/papers/lakshman-ladis2009.pdf
 http://learn.exponential.io/courses/cassandra-consistency/lectures/98884
 https://www.youtube.com/watch?v=-zyZ35YyT_8
 http://www.planetcassandra.org/blog/case-study-netflix/
 http://www.datastax.com/wp-content/uploads/2011/09/CS-Netflix.pdf
 http://www.3pillarglobal.com/insights/selection-criteria-for-nosql-database
 http://neo4j.com/blog/nosql-scaling-to-size-and-scaling-to-complexity/
 https://www.digitalocean.com/community/tutorials/a-comparison-of-nosql-database-
management-systems-and-models
 http://cambridge-intelligence.com/keylines/graph-databases-data-visualization/
References
 https://redislabs.com/ebook/redis-in-action/part-1-getting-started/chapter-1-getting-to-
know-redis/1-2-what-redis-data-structures-look-like/1-2-4-hashes-in-
redis#sthash.eacmDHF3.dpuf
 http://oldblog.antirez.com/post/take-advantage-of-redis-adding-it-to-your-stack.html
 http://highscalability.com/blog/2011/7/6/11-common-web-use-cases-solved-in-
redis.html
 Http://www.tutorialspoint.com/neo4j/neo4j_overview.htm
 http://www.slideshare.net/neo4j
 http://neo4j.com/docs/stable/graphdb-neo4j.html
 http://www.slideshare.net/maxdemarzi/introduction-to-graph-databases-12735789
 http://www.slideshare.net/andres_taylor/graph-database-super-star-
8079303?qid=2cc5495e-f25a-4d99-be76-ab2ab9f6e72a&v=&b=&from_search=2
 https://www.pythian.com/blog/when-is-mongodb-the-right-choice-for-your-business-we-
explore-detailed-use-cases-2/
 Http://www.slideshare.net/mongodb/expedia-36715535
 http://www.slideshare.net/gschmutz/nosql-databases-for-implementing-data-services-
should-i-care
 http://www.datastax.com/wp-content/uploads/2011/09/CS-Netflix.pdf
 https://www.mongodb.com/document-databases
 http://www2.mta.ac.il/~kirsh/download/MTA%20NoSQL%20Seminar/Lectures/MongoD
B.pdf
 http://info.neo4j.com/rs/neotechnology/images/Fraud%20Detection%20Using%20Grap
hDB%20-%202014.pdf
 https://www.youtube.com/watch?v=hKLKpqY9UrY
 http://data-magnum.com/9-lessons-for-starting-a-big-data-initiative-and-selecting-the-
Nosql