Design Patterns for Efficient Graph Algorithms in MapReduceJimmy Lin and Michael SchatzUniversity of MarylandTuesday, June 29, 2010This work is licensed under a Creative Commons Attribution-Noncommercial-Share Alike 3.0 United StatesSee http://creativecommons.org/licenses/by-nc-sa/3.0/us/ for details
@lintool
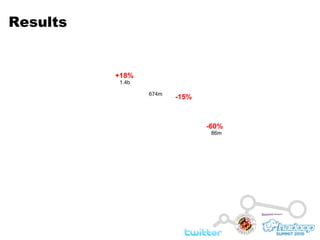
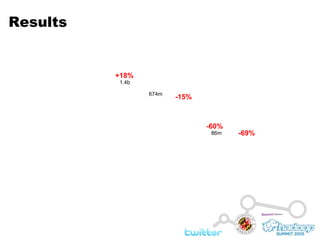
Talk OutlineGraph algorithmsGraph algorithms in MapReduceMaking it efficientExperimental resultsPunch line: per-iteration running time -69% on 1.4b link webgraph!
What’s a graph?G = (V, E), whereV represents the set of vertices (nodes)E represents the set of edges (links)Both vertices and edges may contain additional informationGraphs are everywhere:E.g., hyperlink structure of the web, interstate highway system, social networks, etc.Graph problems are everywhere:E.g., random walks, shortest paths, MST, max flow, bipartite matching, clustering, etc.
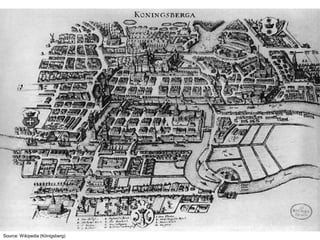
Source: Wikipedia (Königsberg)
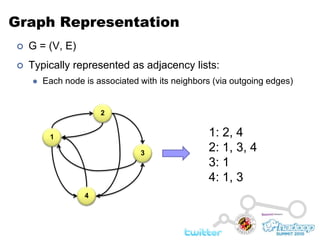
Graph RepresentationG = (V, E)Typically represented as adjacency lists:Each node is associated with its neighbors (via outgoing edges)21: 2, 42: 1, 3, 43: 14: 1, 3134
“Message Passing” Graph AlgorithmsLarge class of iterative algorithms on sparse, directed graphsAt each iteration:Computations at each vertexPartial results (“messages”) passed (usually) along directed edgesComputations at each vertex: messages aggregate to alter stateIterate until convergence
A Few Examples…Parallel breadth-first search (SSSP)Messages are distances from sourceEach node emits current distance + 1Aggregation = MINPageRankMessages are partial PageRank massEach node evenly distributes mass to neighborsAggregation = SUMDNA Sequence assemblyMichael Schatz’s dissertationBoring!Still boring!
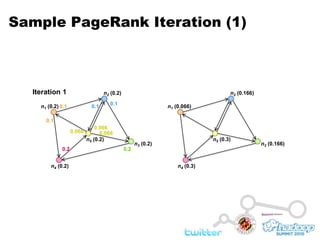
PageRank in a nutshell….Random surfer model:User starts at a random Web pageUser randomly clicks on links, surfing from page to pageWith some probability, user randomly jumps aroundPageRank…Characterizes the amount of time spent on any given pageMathematically, a probability distribution over pages
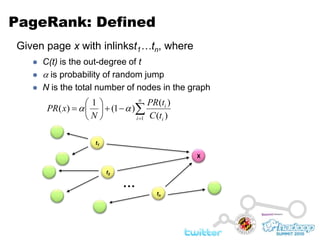
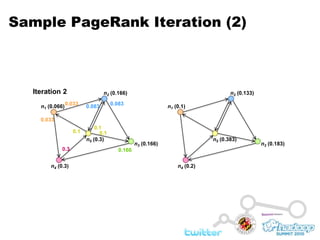
Given page x with inlinkst1…tn, whereC(t) is the out-degree of t is probability of random jumpN is the total number of nodes in the graphPageRank: Definedt1Xt2…tn
Sample PageRank Iteration (1)Iteration 1n2 (0.2)n2 (0.166)0.1n1 (0.2)0.10.1n1 (0.066)0.10.0660.0660.066n5 (0.2)n5 (0.3)n3 (0.2)n3 (0.166)0.20.2n4 (0.2)n4 (0.3)
Sample PageRank Iteration (2)Iteration 2n2 (0.166)n2 (0.133)0.0330.083n1 (0.066)0.083n1 (0.1)0.0330.10.10.1n5 (0.3)n5 (0.383)n3 (0.166)n3 (0.183)0.30.166n4 (0.3)n4 (0.2)
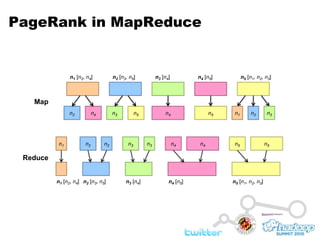
PageRank in MapReduceMapn2n4n3n5n1n2n3n4n5n2n4n3n5n1n2n3n4n5Reduce
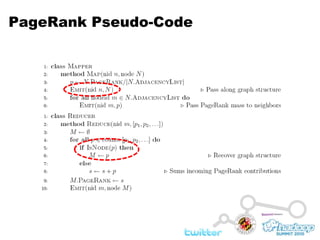
PageRank Pseudo-Code
Why don’t distributed algorithms scale?
Source: http://www.flickr.com/photos/fusedforces/4324320625/
Three Design PatternsIn-mapper combining: efficient local aggregationSmarter partitioning: create more opportunitiesSchimmy: avoid shuffling the graph
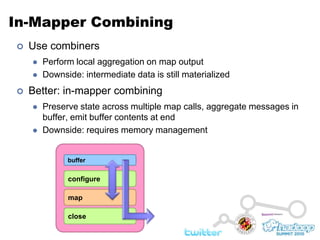
In-Mapper CombiningUse combinersPerform local aggregation on map outputDownside: intermediate data is still materializedBetter: in-mapper combiningPreserve state across multiple map calls, aggregate messages in buffer, emit buffer contents at endDownside: requires memory managementbufferconfiguremapclose
Better PartitioningDefault: hash partitioningRandomly assign nodes to partitionsObservation: many graphs exhibit local structureE.g., communities in social networksBetter partitioning creates more opportunities for local aggregationUnfortunately… partitioning is hard!Sometimes, chick-and-eggBut in some domains (e.g., webgraphs) take advantage of cheap heuristicsFor webgraphs: range partition on domain-sorted URLs
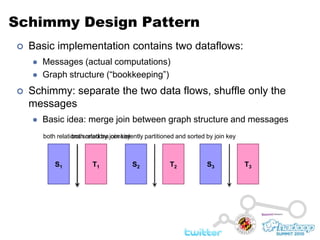
Schimmy Design PatternBasic implementation contains two dataflows:Messages (actual computations)Graph structure (“bookkeeping”)Schimmy: separate the two data flows, shuffle only the messagesBasic idea: merge join between graph structure and messagesboth relations sorted by join keyboth relations consistently partitioned and sorted by join keySTS1T1S2T2S3T3
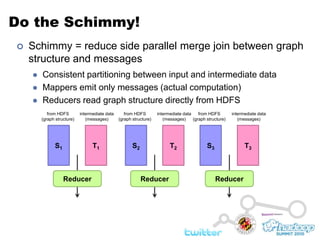
Do the Schimmy!Schimmy = reduce side parallel merge join between graph structure and messagesConsistent partitioning between input and intermediate dataMappers emit only messages (actual computation)Reducers read graph structure directly from HDFSintermediate data(messages)intermediate data(messages)intermediate data(messages)from HDFS(graph structure)from HDFS(graph structure)from HDFS(graph structure)S1T1S2T2S3T3ReducerReducerReducer
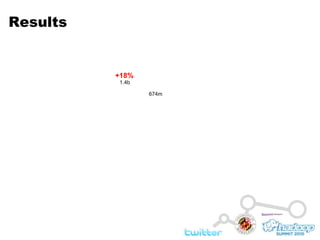
ExperimentsCluster setup:10 workers, each 2 cores (3.2 GHz Xeon), 4GB RAM, 367 GB diskHadoop 0.20.0 on RHELS 5.3Dataset:First English segment of ClueWeb09 collection50.2m web pages (1.53 TB uncompressed, 247 GB compressed)Extracted webgraph: 1.4 billion links, 7.0 GBDataset arranged in crawl orderSetup:Measured per-iteration running time (5 iterations)100 partitions
Results“Best Practices”
Results+18%1.4b674m
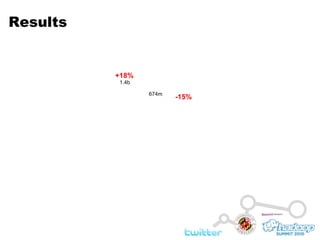
Results+18%1.4b674m-15%
Results+18%1.4b674m-15%-60%86m
Results+18%1.4b674m-15%-60%-69%86m
Take-Away MessagesLots of interesting graph problems!Social network analysisBioinformaticsReducing intermediate data is keyLocal aggregationBetter partitioningLess bookkeeping
Complete details in Jimmy Lin and Michael Schatz. Design Patterns for Efficient Graph Algorithms in MapReduce.Proceedings of the 2010 Workshop on Mining and Learning with Graphs Workshop (MLG-2010), July 2010, Washington, D.C. http://mapreduce.me/Source code available in Cloud9http://cloud9lib.org/@lintool