Vision-Language Models
TEACHING MACHINES TO SEE AND SPEAK – BY M FAHAD BASHIR
What Are Vision-Language Models?
 VLMs are AI models that jointly understand images
and text, allowing them to perform tasks like image
captioning, visual Q&A, and multimodal reasoning.
 Combine computer vision (image understanding)
and natural language processing (NLP)
 Process both visual and text data together
 Examples: CLIP, BLIP, Flamingo, GPT-4V, Gemini,
LLaVA
Why Vision-Language Models?
 Humans understand the world through multiple senses — VLMs mimic
that.
They enable:
 Image Captioning → "A dog playing with a ball"
 Visual Question Answering → “What color is the car?”
 Text-to-Image Generation → “Draw a cat wearing sunglasses”
 Image Search → “Find pictures of a red car in mountains”
🔍
When you see, read, or talk, your brain connects everything.
But traditional AI models were separate — vision models saw, language
models spoke.
Vision-Language Models unite them, creating a more human-like AI.
How Do They Work
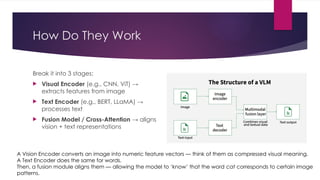
Break it into 3 stages:
 Visual Encoder (e.g., CNN, ViT) →
extracts features from image
 Text Encoder (e.g., BERT, LLaMA) →
processes text
 Fusion Model / Cross-Attention → aligns
vision + text representations
A Vision Encoder converts an image into numeric feature vectors — think of them as compressed visual meaning.
A Text Encoder does the same for words.
Then, a fusion module aligns them — allowing the model to ‘know’ that the word cat corresponds to certain image
patterns.
Famous Vision-Language Models
Model Year Organization Main Idea
CLIP 2021 OpenAI
Learns a shared embedding for image &
text — used for zero-shot classification
BLIP / BLIP-2 2022–23 Salesforce
Generates captions & answers; BLIP-2
connects frozen vision + language models
Flamingo 2022 DeepMind Few-shot multimodal reasoning
LLaVA 2023 Meta & Vicuna
Combines LLaMA with a vision encoder for
visual conversation
GPT-4V /
Gemini
2023–24
OpenAI /
Google
Unified multimodal reasoning (can see,
read, and analyze)
Real World Applications
 AI-powered search engines (e.g., Google
Lens)
 Educational tools (describe diagrams or
charts)
 Medical imaging (describe X-rays, MRIs)
 E-commerce (visual product
recommendation)
 Accessibility (image description for visually
impaired)
Goal :
Show that a Vision-Language Model can look at an image and describe it — that’s the
simplest and most visual way to demonstrate what VLMs do.
Steps :
 Load an image
 Model generates a caption
 You read the output aloud and explain how the model understood the image
Models - Captioning + VQA
Notebook Link : [Click Here]
Live Demo
Future of Vision Language Model
 Moving towards multimodal AI — combining text,
image, audio, video
 Foundation for AGI-like reasoning
 Expected integration in education, healthcare, and
creative industries