Video	Search	by	Deep	Learning
Cees	Snoek
2
Which one is the plane?
3
Which one is the plane?
4
Which one is the bird?
5
Which one is the bird?
6
Which one is the Kentucky Warbler?
7
Which one is the Kentucky Warbler?
8
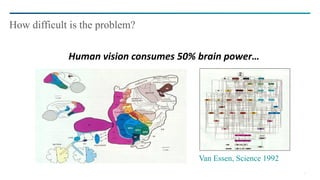
How difficult is the problem?
Human	vision	consumes	50%	brain	power…
Van Essen, Science 1992
9
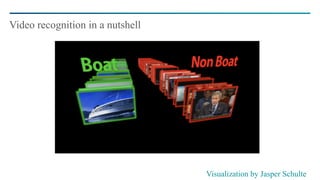
Video recognition in a nutshell
Visualization by Jasper Schulte
10
NIST TRECVID Benchmark
Promote progress in video retrieval research
Big data, standardized tasks, independent evaluation and open innovation
International	video	search	competition
http://trecvid.nist.gov/
11
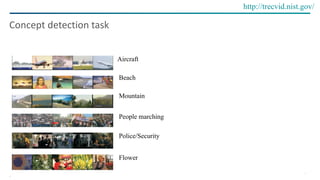
Concept	detection	task
http://trecvid.nist.gov/
Aircraft
Beach
Mountain
People marching
Police/Security
Flower
12
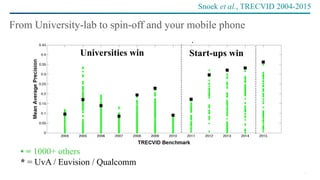
From University-lab to spin-off and your mobile phone
• = 1000+ others
* = UvA / Euvision / Qualcomm
Universities win Start-ups win
Snoek et al., TRECVID 2004-2015
13
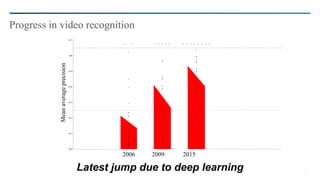
Latest jump due to deep learning
2006 2009 2015
Meanaverageprecision
Progress in video recognition
14
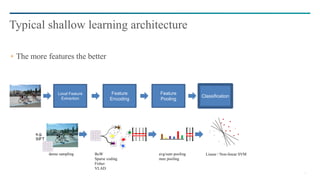
The more features the better
Typical shallow learning architecture
e.g.
SIFT
dense sampling
Local Feature
Extraction
Feature
Pooling
Feature
Encoding
Classification
avg/sum pooling
max pooling
BoW
Sparse coding
Fisher
VLAD
Linear / Non-linear SVM
15
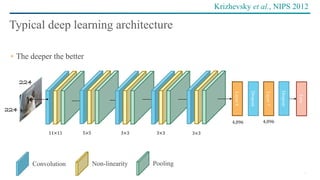
The deeper the better
Typical deep learning architecture
Layer6
Loss
Layer7
Max pool. 2
224
224
3×3
4,096 4,096
Dropout
Dropout
3×33×35×511×11
Convolution Non-linearity Pooling
Krizhevsky et al., NIPS 2012
16
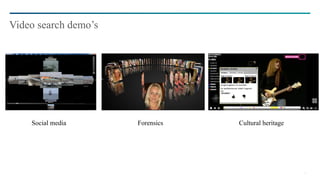
Video search demo’s
Social media Forensics Cultural heritage
17
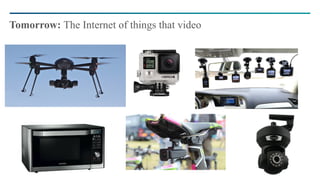
Tomorrow: The Internet of things that video
18
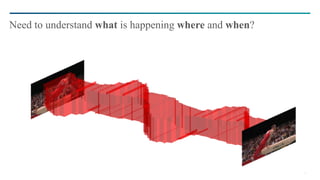
Need to understand what is happening where and when?
19
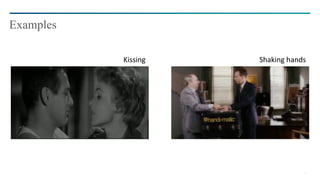
Examples
Shaking	handsKissing
20
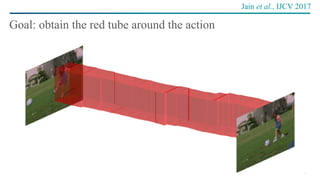
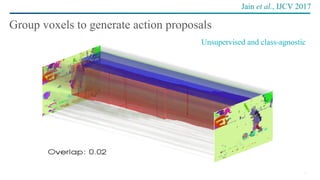
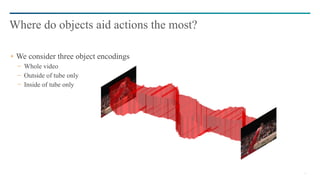
Goal: obtain the red tube around the action
Jain et al., IJCV 2017
21
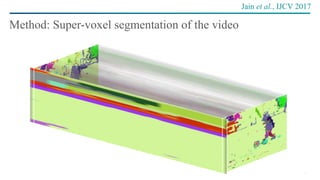
Method: Super-voxel segmentation of the video
Jain et al., IJCV 2017
22
Group voxels to generate action proposals
Jain et al., IJCV 2017
Unsupervised and class-agnostic
23
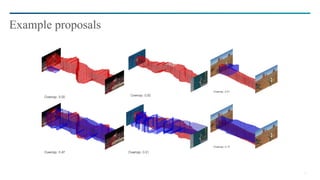
Example proposals
24
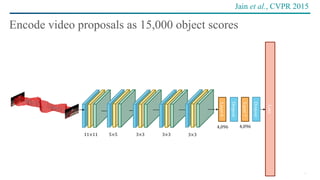
Encode video proposals as 15,000 object scores
Jain et al., CVPR 2015
Layer6
Loss
Layer7
Max
pool. 2
3×3
4,096 4,096
Dropout
Dropout
3×33×35×511×11
25
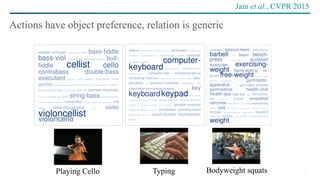
Actions have object preference, relation is generic
TypingPlaying Cello Bodyweight squats
Jain et al., CVPR 2015
26
We consider three object encodings
− Whole video
− Outside of tube only
− Inside of tube only
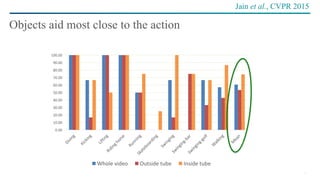
Where do objects aid actions the most?
27
Objects aid most close to the action
0.00
10.00
20.00
30.00
40.00
50.00
60.00
70.00
80.00
90.00
100.00
Whole	video Outside	tube Inside	tube
Jain et al., CVPR 2015
28
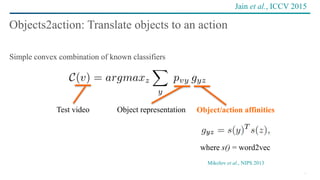
Simple convex combination of known classifiers
Objects2action: Translate objects to an action
Object representationTest video Object/action affinities
where s() = word2vec
Mikolov et al., NIPS 2013
Jain et al., ICCV 2015
29
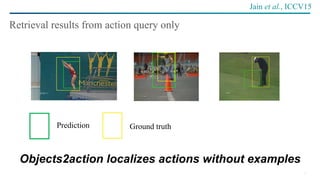
Objects2action localizes actions without examples
Retrieval results from action query only
Jain et al., ICCV15
Prediction Ground truth
30
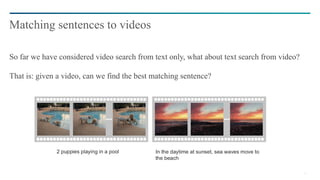
So far we have considered video search from text only, what about text search from video?
That is: given a video, can we find the best matching sentence?
Matching sentences to videos
31
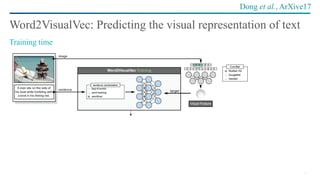
Word2VisualVec: Predicting the visual representation of text
Training time
Dong et al., ArXive17
32
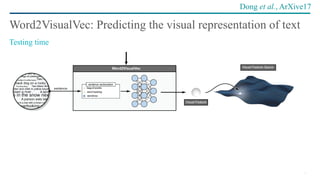
Word2VisualVec: Predicting the visual representation of text
Testing time
Dong et al., ArXive17
33
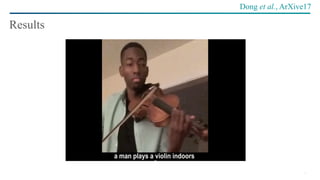
Results
Dong et al., ArXive17
34
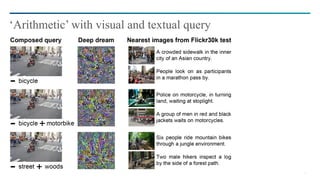
‘Arithmetic’ with visual and textual query
35
Video search by deep learning is powerful, even without examples
Field is progressing rapidly
Precise spatiotemporal video understanding is next
Conclusion
www.ceessnoek.info