The Genesis Mission: Evaluating the U.S. AI-for-Science Initiative's Impact and Challenges
A critical review of the Genesis Mission, a U.S. government AI-for-Science initiative integrating AI, HPC, and scientific research across agencies, highlighting its strengths, weaknesses, and verification challenges.
The Genesis Mission: Evaluating the U.S. AI-for-Science Initiative's Impact and Challenges
1.
The Genesis Mission:A Critical Review of the
U.S. AI-for-Science Initiative
August 2026
Abstract
The Genesis Mission is a national initiative intended to integrate artificial intelligence, high-
performance computing, scientific datasets, experimental facilities, automation, and domain
expertise into a coordinated research platform. Launched by executive order in November 2025
and initially organized around the Department of Energy and its National Laboratories, it has
since become a whole-of-government program spanning roughly twenty federal agencies, a re-
vised portfolio of thirty-three National Science and Technology Challenges, and more than $5
billion in announced federal commitments. This review argues that the initiative is strategically
well conceived and institutionally well matched to the capabilities of the participating agencies.
Its strongest feature is its systems-level conception of AI-assisted science: scientific progress
is treated not as a product of stand-alone language models, but as the result of interactions
among models, simulations, instruments, experiments, data, and human researchers. The cen-
tral weakness of the publicly described program is that verification, independent evaluation,
uncertainty quantification, reproducibility, and scientific accountability are not yet presented
as a platform layer equal in importance to data, models, computation, and experimentation.
Several performance claims already published by the program illustrate the problem directly.
The Genesis Mission could have very high national value, but only if it measures validated sci-
entific and engineering progress rather than the volume of generated hypotheses, simulations,
papers, or automated experiments—and only if the interagency expansion is accompanied by a
correspondingly stronger evaluation and accountability structure.
Contents
1 Introduction 2
2 Scope and Method 3
3 Program Status as of August 2026 3
4 Why the Basic Architecture Is Promising 4
5 The Most Promising Challenge Areas 5
5.1 AI-Driven and Automated Laboratories . . . . . . . . . . . . . . . . . . . . . . . . . 5
5.2 Grid Planning and Operation . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 5
5.3 Materials, Chemistry, and Biotechnology . . . . . . . . . . . . . . . . . . . . . . . . . 6
5.4 Quantum Algorithms . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 6
6 Principal Weaknesses and Risks 6
1
2.
6.1 Verification IsNot Yet a First-Class Platform Layer . . . . . . . . . . . . . . . . . . 6
6.2 The Program’s Own Performance Claims Illustrate the Problem . . . . . . . . . . . 7
6.3 The Challenges Differ Greatly in Maturity . . . . . . . . . . . . . . . . . . . . . . . . 7
6.4 Interagency Scale May Dilute Accountability . . . . . . . . . . . . . . . . . . . . . . 8
6.5 Vendor Dependence and Interoperability . . . . . . . . . . . . . . . . . . . . . . . . . 9
6.6 Federation Solves Access, Not Epistemics . . . . . . . . . . . . . . . . . . . . . . . . 9
6.7 Cybersecurity and Dual-Use Risk . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 10
6.8 Scientific Productivity Is Difficult to Measure . . . . . . . . . . . . . . . . . . . . . . 10
7 A Recommended Verification Architecture 11
7.1 Who Pays for Verification . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 11
7.2 Incident Reporting and Scorecards . . . . . . . . . . . . . . . . . . . . . . . . . . . . 11
8 Suggested Evaluation Framework 12
9 Institutional Pathways 12
10 Overall Assessment 14
11 Conclusion 14
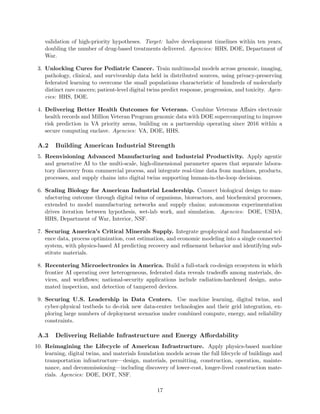
A The Thirty-Three National Science and Technology Challenges 16
A.1 Helping Americans Live Longer, Healthier Lives . . . . . . . . . . . . . . . . . . . . . 16
A.2 Building American Industrial Strength . . . . . . . . . . . . . . . . . . . . . . . . . . 17
A.3 Delivering Reliable Infrastructure and Energy Affordability . . . . . . . . . . . . . . 17
A.4 Extending the Frontiers of American Discovery . . . . . . . . . . . . . . . . . . . . . 18
A.5 Protecting the Nation from Emerging Threats . . . . . . . . . . . . . . . . . . . . . . 19
A.6 Observations on the Portfolio . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 20
1 Introduction
The Genesis Mission is one of the most ambitious U.S. government attempts to organize artificial
intelligence around scientific discovery, energy technology, and national security. It originated in
a November 2025 executive order and was first elaborated by the Department of Energy (DOE),
which described a coordinated effort linking its National Laboratories, universities, industry, phil-
anthropic organizations, advanced computing systems, scientific facilities, and unique datasets. In
February 2026 DOE announced an initial set of twenty-six national science and technology chal-
lenges spanning energy, materials, biotechnology, manufacturing, quantum information science,
autonomous laboratories, microelectronics, water, national security, and foundational science [1, 2].
The mission’s central technological concept is the American Science and Security Platform, de-
scribed as an integrated system combining high-performance computing, experimental facilities,
scientific data resources, artificial-intelligence systems, and production capabilities [4]. This is a
more credible conception of AI-enabled science than the frequently promoted idea that a sufficiently
capable stand-alone language model will independently generate major scientific discoveries. Scien-
tific knowledge normally emerges through a cycle of theorizing, modeling, simulation, measurement,
experimentation, criticism, replication, and revision. An architecture that connects these activities
has a plausible route to accelerating research.
2
3.
The principal concernis that accelerated generation is not equivalent to accelerated knowledge.
AI systems can rapidly produce hypotheses, models, simulations, candidate materials, experimen-
tal plans, and apparently persuasive explanations. They can also rapidly produce subtle errors,
spurious correlations, invalid extrapolations, benchmark artifacts, and confident but unsupported
conclusions. The success of the Genesis Mission will therefore depend less on the number of models
trained or experiments automated than on the quality of its verification architecture.
This review concludes that the Genesis Mission is strategically strong, institutionally promising,
and potentially transformative. At the same time, its public formulation remains underdeveloped
in the areas of independent validation, reproducibility, uncertainty quantification, security, inter-
operability, and accountability—and the July 2026 expansion from a departmental program to an
interagency one has widened that gap rather than closed it.
2 Scope and Method
This assessment is based on public, mission-level communications available through August 4, 2026:
agency announcements, the Genesis Mission challenge pages, the White House expansion release,
the published award list, and independent press coverage of the July 22, 2026 Genesis Mission
Summit. It is a review of what the program has said about itself in public, not an audit of its
internal processes.
That scope should be stated explicitly because it bounds the conclusions. In particular, this re-
view does not examine the merit review criteria of the Genesis Mission Request for Applications
(DE-FOA-0003612, issued March 17, 2026), the statements of work in individual award negotia-
tions, or classified national security components. Evaluation criteria may well be specified in those
instruments. Where this review observes that verification is “not visible” or “not yet presented as
a platform layer,” the claim is about the program’s public architecture and its public accounting
of progress—not an assertion that no project-level evaluation exists.
The distinction matters for the recommendations that follow. Project-level merit review, however
rigorous, does not by itself produce a cross-portfolio evaluation capability, a shared incident record,
or an independent replication function. Those are platform-level goods, and platform-level goods
must be visible in the platform’s public description to be credited.
3 Program Status as of August 2026
The program has moved well beyond announcement. Several developments materially change how
it should be assessed.
From a department to a government. At the July 22, 2026 Genesis Mission Summit, the
initiative was described as a whole-of-government effort, with more than fifteen federal agencies
contributing research awards, funding opportunities, specialized datasets, and research facilities
[10]. Under Secretary for Science Darı́o Gil put the figure at approximately twenty participating
agencies and departments [11]. Participants reported to include the Departments of Defense, Health
and Human Services, Transportation, and the Interior, along with NASA and the National Science
Foundation [13]. This is no longer a DOE program with external partners; it is a federal program
with a DOE-built platform at its center.
3
4.
From twenty-six challengesto thirty-three. The challenge portfolio was revised upward at
the summit, with new or restructured challenges in areas including space, human health, defense,
and veterans health [11, 13]. The current challenge portal reflects the broadened framing, describing
a portfolio that brings together the American Science and Security Platform and federal agencies
across science, energy, national security, health, and space [2]. The consolidated challenge document
describes the mission as a whole-of-nation effort coordinated by the White House Office of Science
and Technology Policy, with the challenges themselves developed by more than fifteen federal
agencies, and organizes them under five thematic pillars [3]. The full portfolio is listed and described
in Appendix A; its composition differs substantially from the original DOE-centered set, with four
challenges in human health and nine in national security and emerging threats.
Funding. More than $5 billion in federal commitments was announced in July 2026 [10]. Re-
ported components include roughly $1.4 billion associated with the Department of Defense, over
$800 million in contributions from consortium partners, a $40 million in-kind commitment from a
founding industry member, and a combined $1 billion U.S.–Japan investment structured as $500
million from each side over five years across eleven priority areas [12]. The first competitive round
of research awards is a much smaller figure—reported at more than $250 million—indicating that
most committed funding sits in infrastructure, agency programs, and partnerships rather than in
the peer-reviewed project portfolio [14].
Awards. In July 2026 the Department of Energy announced 278 projects selected for award nego-
tiations. The composition is 87 projects led by DOE and National Nuclear Security Administration
laboratories, 168 led by universities, 19 led by companies, and 4 led by nonprofit organizations.
The 342 participating institutions comprise 16 DOE and NNSA laboratories, 142 universities, 157
companies, 13 nonprofit organizations, and 14 others. The largest single selection is a three-year,
$60 million nuclear energy effort [8]. Selection for negotiations is explicitly not a commitment to
fund [8], and it is certainly not a scientific result. The full award list is public [9].
Two features of this portfolio bear directly on the analysis below. First, the awards were re-
ported to address twenty-one of the original twenty-six challenges [14]—meaning roughly a fifth of
the challenge portfolio drew no selected proposals in the first competitive round. Second, 157 of
the 342 participating institutions are companies, which makes questions of interoperability, model
portability, and artifact retention operationally immediate rather than hypothetical.
4 Why the Basic Architecture Is Promising
The strongest feature of the Genesis Mission is that it treats AI-assisted science as a systems
problem. The American Science and Security Platform is intended to combine computing, data,
models, instruments, laboratories, and production capabilities rather than treating AI as an isolated
software service [4]. This matters because most important scientific and engineering problems
cannot be solved by text generation alone. A model may propose a catalyst, reactor configuration,
biological intervention, or quantum algorithm, but the proposal must still be tested against physical
constraints, simulation results, experimental measurements, manufacturing limitations, costs, and
safety requirements.
DOE is unusually well positioned to attempt this integration. The National Laboratories oper-
ate major supercomputers, synchrotron light sources, neutron facilities, nuclear-science facilities,
climate and Earth-system models, materials laboratories, engineering testbeds, and specialized
4
5.
national-security infrastructure. CommercialAI firms possess substantial model-development and
computing capabilities, but they generally do not control a comparable combination of scientific
instruments, long-duration datasets, specialized facilities, and domain experts. The interagency ex-
pansion adds further assets—space science, health, and defense data and facilities—that no single
department controls.
The challenge portfolio is also broadly sensible. Many of the selected problems have large com-
binatorial design spaces, expensive experiments, fragmented data, and computational bottlenecks.
These are conditions under which machine learning, surrogate models, scientific foundation models,
optimization algorithms, automated experimentation, and hybrid physics–AI methods may provide
genuine value [2].
The program’s defining technical bet is federation: a single identity and data fabric that follows a
researcher across facilities, so that instruments, computing systems, and datasets appear as nodes
of one network rather than as separate administrative domains. This concept dominated the July
summit, recurring more than any other technical idea [12]. It is the right bet. As discussed in
Section 6.6, it is also a solution to a different problem than the one that limits AI-assisted science.
5 The Most Promising Challenge Areas
5.1 AI-Driven and Automated Laboratories
The autonomous-laboratory challenge may be the most consequential element of the Genesis Mis-
sion. The program envisions AI-driven laboratories in which models, robotics, real-time analysis,
experimental control, and data systems form closed-loop workflows [5]. Such systems could propose
an experiment, configure equipment, collect measurements, analyze results, and select the next ex-
periment. In well-defined domains, this could sharply reduce the delay between hypothesis and
empirical feedback.
The terminology nevertheless requires caution. A laboratory can automate search and optimization
without possessing reliable scientific judgment. An automated system may exploit a faulty sensor,
optimize a misleading proxy, remain trapped in a biased region of parameter space, or mistake an
experimental artifact for a discovery. Early systems should therefore be understood as closed-loop
automated laboratories under scientific supervision, not as autonomous scientists.
Notably, the program’s own description of this challenge is comparatively disciplined: it frames
automation as increasing both data volume for model training and the repeatability of experiments
[2]. Repeatability is a verification-relevant objective, and it is one of the few places where the public
materials name a reliability property rather than a speed or volume property. That framing should
be generalized across the portfolio.
Such laboratories should be evaluated according to validated discoveries, reproducibility, uncer-
tainty calibration, equipment safety, and efficiency relative to strong human-directed baselines.
Experiments per hour, candidates screened, or model-generated hypotheses are useful throughput
measures, but they are not sufficient measures of scientific progress.
5.2 Grid Planning and Operation
AI-assisted grid planning is a comparatively mature and practical challenge. Machine learning and
optimization may help with interconnection studies, load forecasting, contingency analysis, main-
5
6.
tenance, demand response,and planning under changing generation patterns. These applications
have identifiable users, historical data, operational constraints, and measurable outcomes.
They are also the site of the program’s most specific public performance claim, examined in Sec-
tion 6.2. Claims about improved reliability must specify whether reliability means outage frequency,
outage duration, reserve adequacy, resilience to extreme events, voltage stability, restoration time,
or probabilistic loss-of-load measures. Cost reductions must specify whose costs are reduced and
whether savings survive deployment, cybersecurity, integration, and maintenance expenses. Per-
formance should be assessed on realistic operational scenarios and not only on historical test sets.
5.3 Materials, Chemistry, and Biotechnology
Materials science, chemistry, and biotechnology are natural targets for AI-assisted research be-
cause their candidate spaces are enormous and many experimental processes can be standardized.
AI systems may help prioritize catalysts, battery materials, semiconductor compounds, biological
pathways, proteins, and manufacturing processes. The architecture is strongest when computa-
tional prediction is directly connected to experimental testing—and the biotechnology challenge,
which links multi-omics and imaging data to autonomous experimentation, is explicitly structured
that way [2].
These fields also make the verification problem especially clear. A predicted material may be
unstable, toxic, too expensive, difficult to synthesize, or unsuitable for manufacturing. A biological
intervention may perform well in a narrow assay but fail under different conditions. A model may
rediscover known candidates because its training data contain implicit leakage. Progress should
therefore be measured by independently reproduced physical or biological performance, not by
prediction scores alone.
5.4 Quantum Algorithms
The challenge of using AI to discover quantum algorithms is scientifically interesting but compar-
atively speculative. AI may plausibly assist circuit synthesis, compiler optimization, error miti-
gation, tensor-network methods, and searches over algorithmic structures. The program identifies
automated design and translation of quantum algorithms as an objective [6].
Claims of quantum advantage will require unusually careful scrutiny. Comparisons must use the
strongest known classical algorithms, including improved classical methods developed after the
quantum proposal. Small demonstrations, specially constructed oracle problems, and comparisons
against weak classical baselines should not be presented as evidence of broad practical advantage.
The distinction between algorithmic novelty, asymptotic advantage, hardware demonstration, and
useful scientific computation must remain explicit.
6 Principal Weaknesses and Risks
6.1 Verification Is Not Yet a First-Class Platform Layer
The public description of the Genesis Mission emphasizes data, infrastructure, models, experiments,
facilities, and collaboration. These are necessary components, but verification and evaluation should
be given equal architectural status. The platform should include explicit services and governance for
uncertainty quantification, out-of-distribution testing, independent replication, provenance track-
6
7.
ing, formal verificationwhere applicable, benchmark design, adversarial testing, and comparison
with strong non-AI baselines.
This is not an idiosyncratic reading. Independent coverage of the July summit reached the same
conclusion, observing that the event had considerably more to say about money committed than
about how results would be judged, and that separating inputs from outcomes is precisely where
the program remains difficult to grade [12]. When an outside observer with no thesis to defend and
an inside critic converge on the same absence, the absence is probably real.
Without a dedicated verification layer, Genesis could increase the rate at which plausible scientific
claims are generated faster than it increases the rate at which dependable knowledge is estab-
lished. This is not a peripheral concern. It is the central technical and institutional bottleneck for
autonomous or semi-autonomous scientific systems.
6.2 The Program’s Own Performance Claims Illustrate the Problem
The argument above would be abstract were it not for the fact that the program has already
published performance claims of exactly the kind that a verification layer exists to discipline. The
February 2026 challenge announcement states that AI applied to grid planning, interconnection,
operations, and security will enable decisions between twenty and one hundred times faster, and
will improve electricity cost and reliability by up to ten percent. The same announcement states
that AI-designed materials will shrink development timelines from decades to months [1].
A comparison with the consolidated challenge document sharpens the point, because the two texts
do not agree. The challenge document states the grid target as at least a ten percent improvement
in electricity cost and reliability, whereas the announcement states it as up to ten percent [3, 1].
The same figure is therefore published once as a floor and once as a ceiling. The materials claim
diverges similarly: the challenge document describes reducing time to market from many years or
decades down to months or a few years, which the announcement compresses to decades-to-months
[3, 1]. Neither discrepancy is large in isolation, and neither is likely deliberate. Both indicate that
no single office is responsible for the consistency of the program’s quantitative claims across its own
publications—which is precisely the function a verification layer would serve at the communications
boundary, before any scientific result is at stake.
Table 1 lists what would have to be specified for such statements to be testable.
None of these claims is implausible as an aspiration. The difficulty is that as stated they cannot
be falsified, and a program that publishes unfalsifiable targets at launch will find it difficult to
publish disciplined results later. The remedy is inexpensive: for each headline figure, publish the
baseline, the metric definition, the measurement protocol, and the scenario set. A program with the
scientific depth of the National Laboratories should hold its own communications to the standard
it will apply to its awardees.
6.3 The Challenges Differ Greatly in Maturity
The challenge portfolio ranges from comparatively concrete engineering tasks to open-ended foun-
dational aspirations. Improving grid-interconnection analysis, automating a materials laboratory,
predicting water availability, and deepening understanding of the universe do not have comparable
levels of technological maturity or equally clear success criteria. The expansion to thirty-three
challenges spanning space, human health, defense, and veterans health widens this spread further
[11, 13].
7
8.
Table 1: Publishedprogram claims and the specifications required to test them.
Claim as stated What must be specified
Decisions 20–100×
faster
Which decision; measured against which current workflow; whether the
range reflects task heterogeneity, uncertainty, or best-case selection;
whether analyst review and rework time are included in the
denominator.
Cost and reliability
improved by up to
10%
Two distinct quantities reported as one. Whose cost—generation,
transmission, ratepayer, or program? Which reliability metric—SAIDI,
SAIFI, reserve margin, loss-of-load expectation, restoration time? Is “up
to” a mean, a ceiling, or a single favorable scenario?
Materials timelines
from decades to
months
Which stage of the pipeline: candidate proposal, synthesis,
characterization, qualification, or manufacturing scale-up? Timeline
compression at the proposal stage does not compress qualification, which
typically dominates.
The first award round supplies direct evidence for this heterogeneity: the 278 selected projects
were reported to address twenty-one of the twenty-six challenges then defined [14]. Five challenges
attracted no selected proposals. That outcome is informative and should be treated as data rather
than as an embarrassment. It may indicate that the community judges some challenges premature,
that the framing did not map onto fundable work, or that the relevant expertise sits outside the
applicant pool. Each diagnosis implies a different remedy, and the program should say which it
believes.
Projects should be classified into categories such as operational optimization, scientific-workflow
acceleration, predictive-model improvement, experimental discovery, and foundational scientific
discovery. The evidence threshold should rise as projects move from optimization toward foun-
dational claims. A modest operational improvement can be established through controlled com-
parison, whereas a claim of new scientific understanding may require theoretical scrutiny, multiple
experiments, independent replication, and sustained evaluation.
6.4 Interagency Scale May Dilute Accountability
The selection of 278 projects across 342 institutions creates intellectual diversity and distributes
participation widely [8]. Extending the program across roughly twenty agencies multiplies that
diversity again [11, 13]. Both create a risk that Genesis becomes a broad funding label attached
to heterogeneous projects whose relation to the central mission is weak. Existing research pro-
grams may be redescribed as AI-enabled without demonstrating that AI produces a meaningful
improvement.
The interagency structure raises a further and harder problem. Agencies differ in evaluation cul-
ture, publication norms, human-subjects and animal-research oversight, classification regimes, data-
sharing authority, and statutory reporting obligations. A verification standard written for a mate-
rials laboratory does not transfer unmodified to a clinical context or a defense application, and no
single agency has authority to impose one on the others. The likely default—each agency evaluating
its own contributions by its own conventions—would make cross-portfolio comparison impossible
and would leave the mission-level productivity claim unauditable.
8
9.
Two mitigations areworth considering. First, a minimal common evaluation vocabulary, binding
across agencies, specifying only what must be reported rather than how work must be done: base-
line, metric definition, evaluator independence, and outcome. Second, a designated cross-agency
evaluation function with the authority to publish assessments that individual agencies do not con-
trol. Without the second, the first will erode.
Every project should publish, subject to legitimate security restrictions, a concise predeclared eval-
uation statement identifying the baseline, proposed improvement, test protocol, success metric,
independent evaluator, major risks, and conditions under which the project would be judged un-
successful. Negative results should be retained and shared where possible. A scientific mission
becomes more credible, not less credible, when it records failures and abandoned approaches.
6.5 Vendor Dependence and Interoperability
Of the 342 participating institutions, 157 are companies [8], and the consortium has attracted
substantial industry contributions including in-kind provision of commercial model access [12, 7].
Such participation brings valuable resources, but it also creates risks of vendor lock-in, incompatible
proprietary systems, opaque models, and dependence on commercial interfaces that may later
change.
In-kind contributions of model access deserve particular attention. A donated allocation of infer-
ence capacity is a genuine resource, but it also embeds a specific vendor’s models in publicly funded
scientific workflows on terms the government does not control. If the model is later deprecated,
re-tuned, or repriced, results produced with it may become irreproducible—not because the science
was wrong but because the instrument no longer exists. Scientific instruments are normally char-
acterized, calibrated, and version-controlled; frontier models used as instruments should be treated
the same way.
The program should require portable interfaces, standardized data and metadata formats, repro-
ducible execution environments, audit access, documented and retained model versions, and gov-
ernment retention of essential scientific artifacts. Publicly funded workflows should not become
unusable because a vendor changes an application programming interface, licensing arrangement,
price structure, or strategic priority.
6.6 Federation Solves Access, Not Epistemics
Federation—one identity and one data fabric across facilities—is the program’s principal technical
commitment [12]. It is a substantial and worthwhile engineering goal, and it addresses a real
obstacle: researchers currently cannot move fluidly between instruments, computing systems, and
datasets held under different administrative controls.
But federation is an access solution. It makes data reachable; it does not make data trustworthy.
Much federal scientific data is incomplete, classified, proprietary, poorly documented, or stored in
incompatible formats. Historical measurements may lack machine-readable metadata, calibration
records, uncertainty estimates, or consistent terminology. Digitizing documents and federating
access to them does not create a coherent scientific dataset; it creates faster access to an incoherent
one.
There is a specific hazard here. Federation lowers the cost of joining datasets across domains and
agencies, and joining datasets whose provenance, calibration, and uncertainty conventions differ is
a well-established route to spurious correlation. The easier it becomes to combine data, the more
9
10.
important it becomesto record what each measurement means. A federation layer that carries
identity and location but not provenance and uncertainty will accelerate a class of error rather
than a class of discovery.
Genesis should therefore treat data stewardship as scientific infrastructure of equal standing with
the federation fabric. Provenance, measurement uncertainty, calibration history, instrument config-
uration, and changes in experimental procedure are often as important as the raw values. In some
projects, the creation of a trustworthy and well-characterized dataset may be a more important
contribution than training an additional model.
6.7 Cybersecurity and Dual-Use Risk
Connecting AI agents to grid systems, automated laboratories, nuclear information, manufactur-
ing systems, and national-security data creates a consequential attack surface. The interagency
expansion into defense and health domains enlarges it. Risks include data poisoning, malicious in-
structions, compromised software tools, credential theft, model manipulation, unauthorized actions,
and erroneous automated decisions with physical consequences.
Federation compounds this. A single identity fabric spanning many facilities is also a single high-
value credential surface, and lateral movement across a federated scientific network is a more
attractive objective than compromise of any one laboratory. The convenience that makes federation
valuable to researchers makes it valuable to adversaries.
The platform should employ network segmentation, least-privilege permissions, authenticated prove-
nance, sandboxed execution, independent monitoring, immutable logs, red-team testing, and human
authorization for high-consequence actions. National-security and critical-infrastructure applica-
tions should not inherit the default security assumptions of commercial agent platforms.
6.8 Scientific Productivity Is Difficult to Measure
The program’s stated mission-level objective is to “double the productivity and impact of U.S.
research and development within a decade” [1]. This is an understandable aspiration, but scientific
productivity is not a single well-defined quantity. Paper counts, generated hypotheses, experiments
per day, model outputs, and patents can all be increased without a corresponding increase in reliable
knowledge.
The framing has also drifted in public communication, appearing variously as doubling research
and development productivity, doubling scientific productivity, and doubling the pace of discovery.
These are not equivalent propositions, and the difference is not rhetorical: R&D productivity is
an economic measure with established if contested methodologies, whereas the pace of discovery
has no accepted operationalization at all. A decade-scale national target should be stated once,
precisely, with a named baseline and measurement method.
A better evaluation hierarchy would distinguish throughput, efficiency, reliability, scientific value,
and translational value. Throughput concerns the number of simulations or experiments com-
pleted. Efficiency concerns time and cost per validated result. Reliability concerns reproducibility,
calibration, and error rates. Scientific value concerns new explanatory or predictive capability.
Translational value concerns successful deployment, manufacturing, or operational improvement.
These quantities should not be collapsed into a single promotional number.
10
11.
7 A RecommendedVerification Architecture
A robust Genesis workflow should follow the principle:
Generate with AI, independently criticize with AI and conventional tools, experimen-
tally verify, and assign final responsibility to identifiable humans and institutions.
The independent critic should not simply be another prompt to the same model. Wherever feasible,
criticism should use different models, independently developed methods, separate datasets, formal
tools, physical constraints, or human domain experts. Independence reduces correlated failure,
although it does not eliminate it. A useful ordering of reviewer independence, from weakest to
strongest, runs: self-critique by the generating model; critique by a different model from the same
family; critique by an unrelated model; tool-based checking against physical or formal constraints;
and empirical test against measurement. Non-model verifiers should be ranked above model critics
wherever both are available.
At minimum, consequential workflows should contain four separable components:
1. a generator that proposes hypotheses, designs, models, or experiments;
2. an independent critic that searches for errors, hidden assumptions, and alternative explana-
tions;
3. a domain-specific verification mechanism, such as simulation, formal proof, calibrated mea-
surement, replication, or controlled experiment; and
4. a human or institution with explicit authority and responsibility for consequential decisions.
7.1 Who Pays for Verification
The preceding recommendations have a cost, and no participant’s budget currently contains it.
This is the practical reason verification layers do not get built.
It is useful to write the ratio explicitly. Let cg denote the cost of generating a candidate result
and cv the cost of verifying it to a stated standard. AI-assisted workflows drive cg down sharply
while leaving cv largely governed by instrument time, synthesis cost, replication effort, and expert
attention. As ρ = cv/cg rises, verification, not generation, becomes the binding constraint on
validated output, and the marginal value of additional generation capacity falls toward zero. A
program that funds generation capacity without proportionally funding verification capacity will
observe rising throughput and flat validated output.
Three concrete measures follow. First, awards should carry an explicit verification allocation—a
stated fraction of budget and of instrument time reserved for replication, calibration, and adversarial
testing—rather than leaving verification as unfunded residual effort. Second, replication should be
fundable as primary work, not only as a component of new proposals; an institution that successfully
reproduces or refutes another team’s result has produced a scientific good and should be paid for it.
Third, verification capacity should be reported as a platform metric alongside compute capacity,
since it is equally rate-limiting.
7.2 Incident Reporting and Scorecards
The program should establish a shared scientific-AI incident-reporting system. Reportable events
should include invalid discoveries, irreproducible findings, automation failures, benchmark leakage,
11
12.
unsafe experiments, securityincidents, misleading performance claims, and failures caused by model
or data updates. A national program can create a cumulative record of failure modes that individual
laboratories, agencies, and vendors cannot construct independently. The interagency structure
makes this more valuable, not less: failure modes discovered in a materials laboratory are often
relevant to a clinical or defense application, and at present nothing carries that information across
the boundary.
Annual challenge scorecards should report successful results, failed hypotheses, negative replica-
tions, abandoned projects, costs, safety interventions, and performance against predeclared base-
lines. The reporting system should distinguish project selection, preliminary demonstrations, inde-
pendent validation, operational deployment, and sustained scientific impact. Given that the first
award round produced 278 selections and no results, this distinction is currently the single most
important guard against premature claims of success.
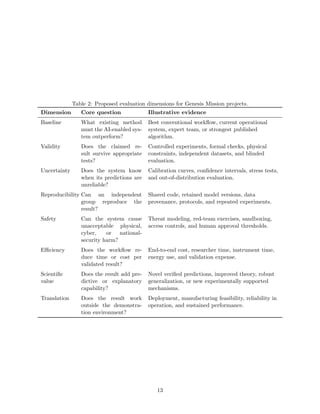
8 Suggested Evaluation Framework
Table 2 sets out eight evaluation dimensions. The framework is intended to be applied at two levels:
by individual projects in their predeclared evaluation statements, and by the program in its annual
scorecards, so that aggregation across a heterogeneous portfolio is possible.
Three design principles govern its use. First, dimensions are not substitutable: strong throughput
does not compensate for absent validity, and a project may not average its way to a passing
assessment. Second, the required evidence rises with the strength of the claim: an operational
optimization needs a controlled comparison, whereas a claim of new scientific understanding needs
independent replication and theoretical scrutiny. Third, evaluator independence is itself reportable:
each dimension should record who performed the assessment and what relationship they had to the
team producing the result.
Efficiency deserves particular emphasis because it is the dimension most often reported incorrectly.
The relevant quantity is cost per validated result, not cost per generated candidate. A workflow that
produces a thousand candidates for the price of ten, of which none survives verification, has reduced
generation cost and increased total cost. Reporting the numerator without the denominator is the
most common way that AI-assisted work appears more productive than it is.
This framework would help prevent easy-to-measure throughput gains from being confused with
validated scientific progress. It would also make comparisons across the heterogeneous challenge
portfolio more meaningful.
9 Institutional Pathways
Recommendations of this kind commonly fail for want of an addressee. Executive initiatives are
subject to changes of administration and priority, and a verification layer that depends on the
continued enthusiasm of current leadership is not infrastructure. There is, however, an available
vehicle: congressional interest in codifying the Genesis Mission in statute, together with atten-
tion to durable oversight frameworks as AI agents assume larger roles in government and critical
infrastructure, was reported at the July summit and appears to be bipartisan [15].
Statutory codification is the natural instrument for the measures recommended here. Four provi-
sions would be worth including: a mandated cross-agency evaluation function with authority to
12
13.
Table 2: Proposedevaluation dimensions for Genesis Mission projects.
Dimension Core question Illustrative evidence
Baseline What existing method
must the AI-enabled sys-
tem outperform?
Best conventional workflow, current operational
system, expert team, or strongest published
algorithm.
Validity Does the claimed re-
sult survive appropriate
tests?
Controlled experiments, formal checks, physical
constraints, independent datasets, and blinded
evaluation.
Uncertainty Does the system know
when its predictions are
unreliable?
Calibration curves, confidence intervals, stress tests,
and out-of-distribution evaluation.
Reproducibility Can an independent
group reproduce the
result?
Shared code, retained model versions, data
provenance, protocols, and repeated experiments.
Safety Can the system cause
unacceptable physical,
cyber, or national-
security harm?
Threat modeling, red-team exercises, sandboxing,
access controls, and human approval thresholds.
Efficiency Does the workflow re-
duce time or cost per
validated result?
End-to-end cost, researcher time, instrument time,
energy use, and validation expense.
Scientific
value
Does the result add pre-
dictive or explanatory
capability?
Novel verified predictions, improved theory, robust
generalization, or new experimentally supported
mechanisms.
Translation Does the result work
outside the demonstra-
tion environment?
Deployment, manufacturing feasibility, reliability in
operation, and sustained performance.
13
14.
publish independently; arequirement that federally funded AI-assisted scientific claims be accom-
panied by predeclared evaluation statements; a scientific-AI incident-reporting obligation analogous
to those in aviation and nuclear operations; and retention requirements for models, data, and exe-
cution environments sufficient to permit later reproduction.
The argument for placing these in statute rather than in program guidance is that verification is
precisely the function that a program has the least incentive to strengthen on its own. Every other
component of the platform makes the program look more productive; this one makes it look less.
Structures of that kind rarely survive without external mandate.
10 Overall Assessment
The Genesis Mission is probably one of the more intelligently framed government AI initiatives
because it recognizes that scientific AI requires a complete operating environment. Its proposed
integration of computation, data, models, instruments, automated laboratories, production ca-
pabilities, and domain expertise is a substantial strength. The National Laboratories and their
new interagency partners possess an institutional and physical infrastructure that is unusually well
suited to such an undertaking.
The challenge portfolio is broad but generally grounded in areas where AI may provide real leverage.
Autonomous laboratories, materials discovery, biotechnology, grid planning, manufacturing, and
scientific computing are plausible candidates for substantial gains. Quantum-algorithm discovery
and foundational scientific discovery are worthwhile research goals, but claims in these areas should
be evaluated more conservatively.
The central weakness is that the public architecture does not yet make verification, independent
replication, uncertainty analysis, and scientific accountability sufficiently prominent, and that the
interagency expansion has outpaced the development of a common evaluation structure. The
mission should not evaluate itself primarily by the number of agencies joined, dollars committed,
projects funded, models trained, hypotheses generated, experiments automated, papers published,
or industrial partners recruited. It should evaluate itself by the number, cost, reliability, and
significance of results that survive independent scrutiny.
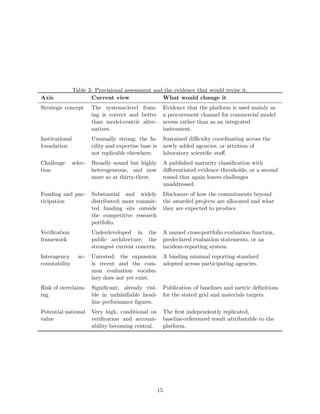
Rather than assign grades, Table 3 states the current assessment on each axis together with the
observation that would change it. This form is preferred because a summary grade is exactly the
kind of collapsed single number that Section 6.8 argues against, and because it makes the assessment
falsifiable by subsequent events.
11 Conclusion
The Genesis Mission should be regarded neither as an assured scientific revolution nor as empty
government promotion. It is a serious attempt to construct national infrastructure for AI-assisted
science, and in the space of nine months it has moved from an executive order to a funded, multi-
agency program with a public portfolio of selected projects. Its systems-level architecture is sub-
stantially more credible than approaches centered on stand-alone generative models. Its eventual
value, however, will depend on whether the participating agencies build a rigorous institutional and
technical process for rejecting attractive but incorrect results.
The decisive principle is simple: generation must be followed by independent criticism, domain-
14
15.
Table 3: Provisionalassessment and the evidence that would revise it.
Axis Current view What would change it
Strategic concept The systems-level fram-
ing is correct and better
than model-centric alter-
natives.
Evidence that the platform is used mainly as
a procurement channel for commercial model
access rather than as an integrated
instrument.
Institutional
foundation
Unusually strong; the fa-
cility and expertise base is
not replicable elsewhere.
Sustained difficulty coordinating across the
newly added agencies, or attrition of
laboratory scientific staff.
Challenge selec-
tion
Broadly sound but highly
heterogeneous, and now
more so at thirty-three.
A published maturity classification with
differentiated evidence thresholds, or a second
round that again leaves challenges
unaddressed.
Funding and par-
ticipation
Substantial and widely
distributed; most commit-
ted funding sits outside
the competitive research
portfolio.
Disclosure of how the commitments beyond
the awarded projects are allocated and what
they are expected to produce.
Verification
framework
Underdeveloped in the
public architecture; the
strongest current concern.
A named cross-portfolio evaluation function,
predeclared evaluation statements, or an
incident-reporting system.
Interagency ac-
countability
Untested; the expansion
is recent and the com-
mon evaluation vocabu-
lary does not yet exist.
A binding minimal reporting standard
adopted across participating agencies.
Risk of overclaim-
ing
Significant; already visi-
ble in unfalsifiable head-
line performance figures.
Publication of baselines and metric definitions
for the stated grid and materials targets.
Potential national
value
Very high, conditional on
verification and account-
ability becoming central.
The first independently replicated,
baseline-referenced result attributable to the
platform.
15
16.
specific verification, andaccountable human judgment. If Genesis institutionalizes that sequence—
and funds it—it could materially improve the speed and reach of American science and engineering.
If it emphasizes output volume and promotional demonstrations without equally strong validation,
it may instead accelerate the production of scientific-looking claims whose reliability remains un-
certain.
The next twelve months should provide a clear signal. The relevant indicator is not how many
additional agencies join, how many further challenges are defined, or how much additional funding
is committed. It is whether the program publishes its first baseline-referenced, independently
validated result—and whether it also publishes the attempts that failed.
A The Thirty-Three National Science and Technology Challenges
This appendix lists and summarizes the revised challenge portfolio as published in the consolidated
Genesis Mission challenge document [3]. Descriptions paraphrase that document. Where a chal-
lenge states a quantitative target, the target is reproduced in brackets; where the document names
contributing agencies, they are listed. The document uses the designation “Department of War” for
the defense department, and that usage is retained below when reporting its agency attributions.
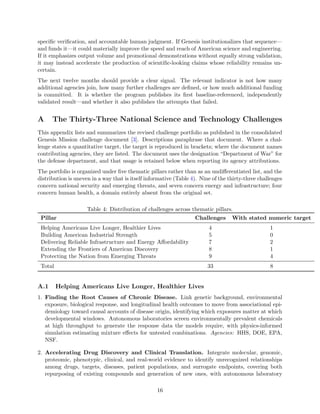
The portfolio is organized under five thematic pillars rather than as an undifferentiated list, and the
distribution is uneven in a way that is itself informative (Table 4). Nine of the thirty-three challenges
concern national security and emerging threats, and seven concern energy and infrastructure; four
concern human health, a domain entirely absent from the original set.
Table 4: Distribution of challenges across thematic pillars.
Pillar Challenges With stated numeric target
Helping Americans Live Longer, Healthier Lives 4 1
Building American Industrial Strength 5 0
Delivering Reliable Infrastructure and Energy Affordability 7 2
Extending the Frontiers of American Discovery 8 1
Protecting the Nation from Emerging Threats 9 4
Total 33 8
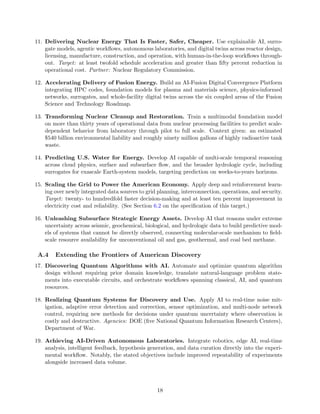
A.1 Helping Americans Live Longer, Healthier Lives
1. Finding the Root Causes of Chronic Disease. Link genetic background, environmental
exposure, biological response, and longitudinal health outcomes to move from associational epi-
demiology toward causal accounts of disease origin, identifying which exposures matter at which
developmental windows. Autonomous laboratories screen environmentally prevalent chemicals
at high throughput to generate the response data the models require, with physics-informed
simulation estimating mixture effects for untested combinations. Agencies: HHS, DOE, EPA,
NSF.
2. Accelerating Drug Discovery and Clinical Translation. Integrate molecular, genomic,
proteomic, phenotypic, clinical, and real-world evidence to identify unrecognized relationships
among drugs, targets, diseases, patient populations, and surrogate endpoints, covering both
repurposing of existing compounds and generation of new ones, with autonomous laboratory
16
17.
validation of high-priorityhypotheses. Target: halve development timelines within ten years,
doubling the number of drug-based treatments delivered. Agencies: HHS, DOE, Department of
War.
3. Unlocking Cures for Pediatric Cancer. Train multimodal models across genomic, imaging,
pathology, clinical, and survivorship data held in distributed sources, using privacy-preserving
federated learning to overcome the small populations characteristic of hundreds of molecularly
distinct rare cancers; patient-level digital twins predict response, progression, and toxicity. Agen-
cies: HHS, DOE.
4. Delivering Better Health Outcomes for Veterans. Combine Veterans Affairs electronic
health records and Million Veteran Program genomic data with DOE supercomputing to improve
risk prediction in VA priority areas, building on a partnership operating since 2016 within a
secure computing enclave. Agencies: VA, DOE, HHS.
A.2 Building American Industrial Strength
5. Reenvisioning Advanced Manufacturing and Industrial Productivity. Apply agentic
and generative AI to the multi-scale, high-dimensional parameter spaces that separate labora-
tory discovery from commercial process, and integrate real-time data from machines, products,
processes, and supply chains into digital twins supporting human-in-the-loop decisions.
6. Scaling Biology for American Industrial Leadership. Connect biological design to man-
ufacturing outcome through digital twins of organisms, bioreactors, and biochemical processes,
extended to model manufacturing networks and supply chains; autonomous experimentation
drives iteration between hypothesis, wet-lab work, and simulation. Agencies: DOE, USDA,
HHS, Department of War, Interior, NSF.
7. Securing America’s Critical Minerals Supply. Integrate geophysical and fundamental sci-
ence data, process optimization, cost estimation, and economic modeling into a single connected
system, with physics-based AI predicting recovery and refinement behavior and identifying sub-
stitute materials.
8. Recentering Microelectronics in America. Build a full-stack co-design ecosystem in which
frontier AI operating over heterogeneous, federated data reveals tradeoffs among materials, de-
vices, and workflows; national-security applications include radiation-hardened design, auto-
mated inspection, and detection of tampered devices.
9. Securing U.S. Leadership in Data Centers. Use machine learning, digital twins, and
cyber-physical testbeds to de-risk new data-center technologies and their grid integration, ex-
ploring large numbers of deployment scenarios under combined compute, energy, and reliability
constraints.
A.3 Delivering Reliable Infrastructure and Energy Affordability
10. Reimagining the Lifecycle of American Infrastructure. Apply physics-based machine
learning, digital twins, and materials foundation models across the full lifecycle of buildings and
transportation infrastructure—design, materials, permitting, construction, operation, mainte-
nance, and decommissioning—including discovery of lower-cost, longer-lived construction mate-
rials. Agencies: DOE, DOT, NSF.
17
18.
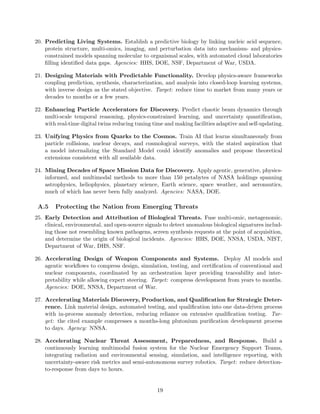
11. Delivering NuclearEnergy That Is Faster, Safer, Cheaper. Use explainable AI, surro-
gate models, agentic workflows, autonomous laboratories, and digital twins across reactor design,
licensing, manufacture, construction, and operation, with human-in-the-loop workflows through-
out. Target: at least twofold schedule acceleration and greater than fifty percent reduction in
operational cost. Partner: Nuclear Regulatory Commission.
12. Accelerating Delivery of Fusion Energy. Build an AI-Fusion Digital Convergence Platform
integrating HPC codes, foundation models for plasma and materials science, physics-informed
networks, surrogates, and whole-facility digital twins across the six coupled areas of the Fusion
Science and Technology Roadmap.
13. Transforming Nuclear Cleanup and Restoration. Train a multimodal foundation model
on more than thirty years of operational data from nuclear processing facilities to predict scale-
dependent behavior from laboratory through pilot to full scale. Context given: an estimated
$540 billion environmental liability and roughly ninety million gallons of highly radioactive tank
waste.
14. Predicting U.S. Water for Energy. Develop AI capable of multi-scale temporal reasoning
across cloud physics, surface and subsurface flow, and the broader hydrologic cycle, including
surrogates for exascale Earth-system models, targeting prediction on weeks-to-years horizons.
15. Scaling the Grid to Power the American Economy. Apply deep and reinforcement learn-
ing over newly integrated data sources to grid planning, interconnection, operations, and security.
Target: twenty- to hundredfold faster decision-making and at least ten percent improvement in
electricity cost and reliability. (See Section 6.2 on the specification of this target.)
16. Unleashing Subsurface Strategic Energy Assets. Develop AI that reasons under extreme
uncertainty across seismic, geochemical, biological, and hydrologic data to build predictive mod-
els of systems that cannot be directly observed, connecting molecular-scale mechanism to field-
scale resource availability for unconventional oil and gas, geothermal, and coal bed methane.
A.4 Extending the Frontiers of American Discovery
17. Discovering Quantum Algorithms with AI. Automate and optimize quantum algorithm
design without requiring prior domain knowledge, translate natural-language problem state-
ments into executable circuits, and orchestrate workflows spanning classical, AI, and quantum
resources.
18. Realizing Quantum Systems for Discovery and Use. Apply AI to real-time noise mit-
igation, adaptive error detection and correction, sensor optimization, and multi-node network
control, requiring new methods for decisions under quantum uncertainty where observation is
costly and destructive. Agencies: DOE (five National Quantum Information Research Centers),
Department of War.
19. Achieving AI-Driven Autonomous Laboratories. Integrate robotics, edge AI, real-time
analysis, intelligent feedback, hypothesis generation, and data curation directly into the experi-
mental workflow. Notably, the stated objectives include improved repeatability of experiments
alongside increased data volume.
18
19.
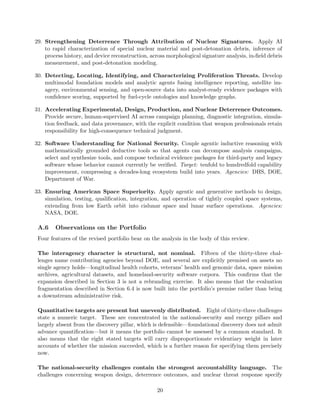
20. Predicting LivingSystems. Establish a predictive biology by linking nucleic acid sequence,
protein structure, multi-omics, imaging, and perturbation data into mechanism- and physics-
constrained models spanning molecular to organismal scales, with automated cloud laboratories
filling identified data gaps. Agencies: HHS, DOE, NSF, Department of War, USDA.
21. Designing Materials with Predictable Functionality. Develop physics-aware frameworks
coupling prediction, synthesis, characterization, and analysis into closed-loop learning systems,
with inverse design as the stated objective. Target: reduce time to market from many years or
decades to months or a few years.
22. Enhancing Particle Accelerators for Discovery. Predict chaotic beam dynamics through
multi-scale temporal reasoning, physics-constrained learning, and uncertainty quantification,
with real-time digital twins reducing tuning time and making facilities adaptive and self-updating.
23. Unifying Physics from Quarks to the Cosmos. Train AI that learns simultaneously from
particle collisions, nuclear decays, and cosmological surveys, with the stated aspiration that
a model internalizing the Standard Model could identify anomalies and propose theoretical
extensions consistent with all available data.
24. Mining Decades of Space Mission Data for Discovery. Apply agentic, generative, physics-
informed, and multimodal methods to more than 150 petabytes of NASA holdings spanning
astrophysics, heliophysics, planetary science, Earth science, space weather, and aeronautics,
much of which has never been fully analyzed. Agencies: NASA, DOE.
A.5 Protecting the Nation from Emerging Threats
25. Early Detection and Attribution of Biological Threats. Fuse multi-omic, metagenomic,
clinical, environmental, and open-source signals to detect anomalous biological signatures includ-
ing those not resembling known pathogens, screen synthesis requests at the point of acquisition,
and determine the origin of biological incidents. Agencies: HHS, DOE, NNSA, USDA, NIST,
Department of War, DHS, NSF.
26. Accelerating Design of Weapon Components and Systems. Deploy AI models and
agentic workflows to compress design, simulation, testing, and certification of conventional and
nuclear components, coordinated by an orchestration layer providing traceability and inter-
pretability while allowing expert steering. Target: compress development from years to months.
Agencies: DOE, NNSA, Department of War.
27. Accelerating Materials Discovery, Production, and Qualification for Strategic Deter-
rence. Link material design, automated testing, and qualification into one data-driven process
with in-process anomaly detection, reducing reliance on extensive qualification testing. Tar-
get: the cited example compresses a months-long plutonium purification development process
to days. Agency: NNSA.
28. Accelerating Nuclear Threat Assessment, Preparedness, and Response. Build a
continuously learning multimodal fusion system for the Nuclear Emergency Support Teams,
integrating radiation and environmental sensing, simulation, and intelligence reporting, with
uncertainty-aware risk metrics and semi-autonomous survey robotics. Target: reduce detection-
to-response from days to hours.
19
20.
29. Strengthening DeterrenceThrough Attribution of Nuclear Signatures. Apply AI
to rapid characterization of special nuclear material and post-detonation debris, inference of
process history, and device reconstruction, across morphological signature analysis, in-field debris
measurement, and post-detonation modeling.
30. Detecting, Locating, Identifying, and Characterizing Proliferation Threats. Develop
multimodal foundation models and analytic agents fusing intelligence reporting, satellite im-
agery, environmental sensing, and open-source data into analyst-ready evidence packages with
confidence scoring, supported by fuel-cycle ontologies and knowledge graphs.
31. Accelerating Experimental, Design, Production, and Nuclear Deterrence Outcomes.
Provide secure, human-supervised AI across campaign planning, diagnostic integration, simula-
tion feedback, and data provenance, with the explicit condition that weapon professionals retain
responsibility for high-consequence technical judgment.
32. Software Understanding for National Security. Couple agentic inductive reasoning with
mathematically grounded deductive tools so that agents can decompose analysis campaigns,
select and synthesize tools, and compose technical evidence packages for third-party and legacy
software whose behavior cannot currently be verified. Target: tenfold to hundredfold capability
improvement, compressing a decades-long ecosystem build into years. Agencies: DHS, DOE,
Department of War.
33. Ensuring American Space Superiority. Apply agentic and generative methods to design,
simulation, testing, qualification, integration, and operation of tightly coupled space systems,
extending from low Earth orbit into cislunar space and lunar surface operations. Agencies:
NASA, DOE.
A.6 Observations on the Portfolio
Four features of the revised portfolio bear on the analysis in the body of this review.
The interagency character is structural, not nominal. Fifteen of the thirty-three chal-
lenges name contributing agencies beyond DOE, and several are explicitly premised on assets no
single agency holds—longitudinal health cohorts, veterans’ health and genomic data, space mission
archives, agricultural datasets, and homeland-security software corpora. This confirms that the
expansion described in Section 3 is not a rebranding exercise. It also means that the evaluation
fragmentation described in Section 6.4 is now built into the portfolio’s premise rather than being
a downstream administrative risk.
Quantitative targets are present but unevenly distributed. Eight of thirty-three challenges
state a numeric target. These are concentrated in the national-security and energy pillars and
largely absent from the discovery pillar, which is defensible—foundational discovery does not admit
advance quantification—but it means the portfolio cannot be assessed by a common standard. It
also means that the eight stated targets will carry disproportionate evidentiary weight in later
accounts of whether the mission succeeded, which is a further reason for specifying them precisely
now.
The national-security challenges contain the strongest accountability language. The
challenges concerning weapon design, deterrence outcomes, and nuclear threat response specify
20
21.
traceability, interpretability, auditability,human supervision, and—in one case explicitly—that hu-
man professionals retain responsibility for high-consequence judgment. The discovery and health
challenges contain no comparable language. This asymmetry is understandable given the conse-
quences of error in the nuclear enterprise, but it is worth noting that the verification vocabulary
the platform needs already exists inside the program. It is a matter of generalizing practice from
the national-security challenges to the rest of the portfolio rather than of inventing it.
Several challenges are themselves verification problems. Software Understanding for Na-
tional Security is, in substance, a program to establish whether the behavior of complex artifacts
can be verified at all; Achieving AI-Driven Autonomous Laboratories names repeatability among
its objectives; and Enhancing Particle Accelerators for Discovery names uncertainty quantification
as a required capability. The argument of this review is therefore not that verification is absent
from the program’s thinking. It is that verification appears as the content of particular challenges
rather than as a service the platform provides to all of them.
References
[1] U.S. Department of Energy, “Energy Department Announces 26 Genesis Mission Science
and Technology Challenges to Accelerate AI-Enabled American Innovation and Leadership,”
February 12, 2026. https://www.energy.gov/undersecretaryforscience/articles/
energy-department-announces-26-genesis-mission-science-and Accessed August 4,
2026.
[2] U.S. Department of Energy, “Genesis Mission National Science and Technology Chal-
lenges,” updated August 3, 2026. https://www.energy.gov/undersecretaryforscience/
genesis-mission/genesis-mission-national-science-and-technology-challenges
Accessed August 4, 2026.
[3] U.S. Department of Energy / White House Office of Science and Technology Policy, “Gene-
sis Mission: National Science & Technology Challenges,” 2026. https://www.energy.gov/
documents/genesis-mission-national-science-technology-challenges Accessed Au-
gust 4, 2026. (Consolidated challenge document; source for the thirty-three challenges described
in Appendix A.)
[4] U.S. Department of Energy, “The American Science and Security Platform,”
2026. https://www.energy.gov/undersecretaryforscience/genesis-mission/
american-science-and-security-platform Accessed August 4, 2026.
[5] U.S. Department of Energy, “Achieving AI-Driven Autonomous Laboratories,”
2026. https://www.energy.gov/undersecretaryforscience/genesis-mission/
achieving-ai-driven-autonomous-laboratories Accessed August 4, 2026.
[6] U.S. Department of Energy, “Discovering Quantum Algorithms with AI,”
2026. https://www.energy.gov/undersecretaryforscience/genesis-mission/
discovering-quantum-algorithms-ai Accessed August 4, 2026.
[7] U.S. Department of Energy, “Genesis Mission Collaboration,” updated August
3, 2026. https://www.energy.gov/undersecretaryforscience/genesis-mission/
genesis-mission-collaboration Accessed August 4, 2026.
21
22.
[8] U.S. Departmentof Energy, “Secretary of Energy Chris Wright An-
nounces First Genesis Mission Projects Selected to Accelerate AI-Driven
Scientific Discovery,” July 22, 2026. https://www.energy.gov/articles/
secretary-energy-chris-wright-announces-first-genesis-mission-projects-selected-accelerate
Accessed August 4, 2026.
[9] U.S. Department of Energy, “Genesis Mission RFA Awards List,” July 22, 2026. https://www.
energy.gov/sites/default/files/2026-07/GM-RFA-Awards-List.pdf Accessed August 4,
2026.
[10] The White House, “Trump Administration Announces More Than $5 Billion for the Genesis
Mission, a National Mission on AI for Science,” July 22, 2026. https://www.whitehouse.
gov/releases/2026/07/45502/ Accessed August 4, 2026.
[11] HPCwire, “Putting AI for Science and Engineering Into Overdrive at Gene-
sis Mission Summit,” July 22, 2026. https://www.hpcwire.com/2026/07/22/
putting-ai-for-science-and-engineering-into-overdrive-at-genesis-mission-summit/
Accessed August 4, 2026.
[12] HPCwire, “Genesis Mission Summit 2026: Big Ambitions and a Famil-
iar Blind Spot,” July 24, 2026. https://www.hpcwire.com/2026/07/24/
genesis-mission-summit-2026-big-ambitions-and-a-familiar-blind-spot/ Accessed
August 4, 2026.
[13] FedScoop, “NASA, DOD and others join Energy Department-led Genesis Mission,” July
2026. https://fedscoop.com/doe-genesis-mission-expansion-nasa-nsf-hhs-dod/ Ac-
cessed August 4, 2026.
[14] The Epoch Times, “With AI Spurring Research—And Paying Dividends—US Gen-
esis Mission Gains Momentum,” July 2026. https://www.theepochtimes.com/us/
with-ai-spurring-research-and-paying-dividends-us-genesis-mission-gains-momentum-6066062
Accessed August 4, 2026. (Secondary account of remarks delivered at the Genesis Mission
Summit; figures attributed to Under Secretary Gil have not been confirmed against a primary
transcript.)
[15] Everglade Consulting, “Inside the Genesis Mission Summit: The AI for Sci-
ence Platform and the Funding Behind It,” July 2026. https://everglade.com/
inside-the-genesis-mission-summit-the-ai-for-science-platform-and-the-funding-behind-it/
Accessed August 4, 2026. (Secondary summit account; used only for reported congressional
interest and summit participation figures.)
22