#pubcon
Presented by: Dawn Anderson
@dawnieando
‘Myths, Facts And Theories On Crawl
Budget And The Importance Of ‘URL
Importance Optimization’’
#pubcon
Dawn Anderson
• Move It Marketing
• University Lecturer – Digital Marketing
• From Manchester, UK (rains a lot)
• International SEO Consultant – 10+ yrs in SEO
• Pomeranian pooch lover - Bert
• Fascinated by crawling (practice & academia)
• Doesn’t fare well in YouTube screen grabs ;P
• Party trick: Remembering UK postcode areas
(US Zip code equivalent)
• Search Awards Judge
• Twitter chatterer @dawnieando
#pubcon
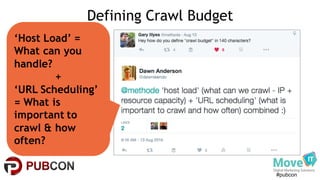
Defining Crawl Budget
‘Host Load’ =
What can you
handle?
+
‘URL Scheduling’
= What is
important to
crawl & how
often?
#pubcon
Myths About Crawl Budget
#pubcon
Myth – It’s All About Just My Site, Right?
• NO – HOST LOAD is apportioned at an IP
level and shared amongst the sites
there (Host load)
#pubcon
Host Load - When Will This Matter?
• It’s more about server capacity than SEO TBH
• Your site is massive (similar in size e.g. to ’Amazon’)
• Your site is massive and you’re on a shared hosting
• You’re using a CDN and your site is massive
• You have lots of large subdomains sharing space
• Crawlable test or staging sites
• You have ‘infinite loops’ and ‘spider traps’
• You keep throwing server errors during
crawling
‘Average’ sites don’t
normally hit the payload
(‘host load’)
#pubcon
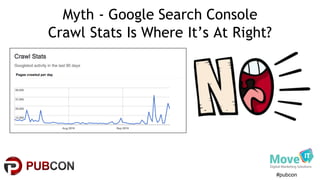
Myth - Google Search Console
Crawl Stats Is Where It’s At Right?
#pubcon
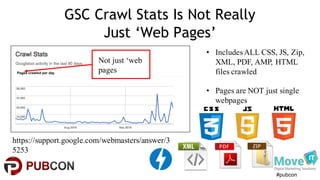
GSC Crawl Stats Is Not Really
Just ‘Web Pages’
• Includes ALL CSS, JS, Zip,
XML, PDF, AMP, HTML
files crawled
• Pages are NOT just single
webpages
https://support.google.com/webmasters/answer/3
5253
Not just ‘web
pages
#pubcon
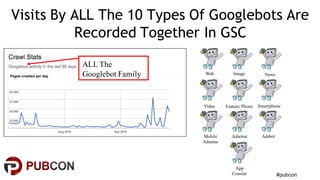
Visits By ALL The 10 Types Of Googlebots Are
Recorded Together In GSC
Web Image News
Video Feature Phone Smartphone
Mobile
Adsense
Adsense Adsbot
App
Crawler
ALL The
Googlebot Family
#pubcon
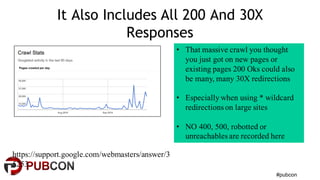
It Also Includes All 200 And 30X
Responses
• That massive crawl you thought
you just got on new pages or
existing pages 200 Oks could also
be many, many 30X redirections
• Especially when using * wildcard
redirections on large sites
• NO 400, 500, robotted or
unreachables are recorded here
https://support.google.com/webmasters/answer/3
5253
#pubcon
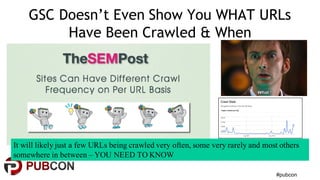
GSC Doesn’t Even Show You WHAT URLs
Have Been Crawled & When
It will likely just a few URLs being crawled very often, some very rarely and most others
somewhere in between – YOU NEED TO KNOW
#pubcon
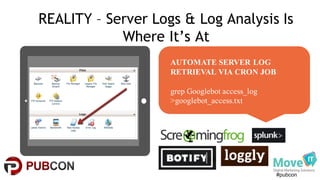
REALITY – Server Logs & Log Analysis Is
Where It’s At
AUTOMATE SERVER LOG
RETRIEVAL VIA CRON JOB
grep Googlebot access_log
>googlebot_access.txt
#pubcon
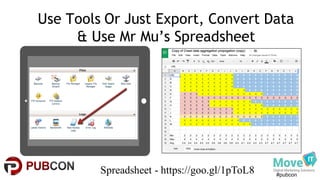
Use Tools Or Just Export, Convert Data
& Use Mr Mu’s Spreadsheet
Spreadsheet - https://goo.gl/1pToL8
#pubcon
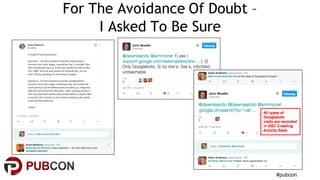
For The Avoidance Of Doubt –
I Asked To Be Sure
#pubcon
Why Does This Matter?
On A Large Site You Need To Be Able To
See Through ‘Spider Eyes’
You need to see what
Googlebot
‘REALLY’ thinks of
your site
#pubcon
Myth – It’s The No Of ‘Pages’ Crawled In
GSC Crawl Stats Divided By Days
For all of the reasons
in the previous 7+
slides
#pubcon
Myth – Googlebot Crawls Through Your
Website From One End To The Other
Then Starts Again
• This is where it gets complicated
• Web crawl efficiency is key
• There is an order to things
• Minimizing visibility of existing stale content is
key too – the rest of the web is changing
• Fresh results are vital to searchers
#pubcon
“What I Think You Are Talking About Is
Scheduling” (Illyes, Google)
Remember that time when Mr Mu
kicked Andrey under the table?
(joking JJ)
#pubcon
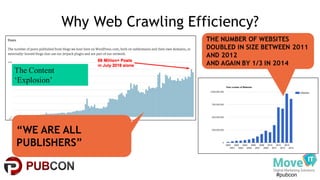
Why Web Crawling Efficiency?
“WE ARE ALL
PUBLISHERS”
THE NUMBER OF WEBSITES
DOUBLED IN SIZE BETWEEN 2011
AND 2012
AND AGAIN BY 1/3 IN 2014
The Content
‘Explosion’
#pubcon
“We don't index every one of
those trillion pages -- many of
them are similar to each
other” (J Alpert, Google)
“There’s a needle in here
somewhere”
“It’s an important needle
too” If only we could
identify it
“So how many unique pages
does the
web really contain? We
don't know;
we don't have time to look
at them all!”
(J Alpert, Google)
#pubcon
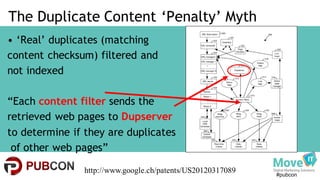
The Duplicate Content ‘Penalty’ Myth
• ‘Real’ duplicates (matching
content checksum) filtered and
not indexed
“Each content filter sends the
retrieved web pages to Dupserver
to determine if they are duplicates
of other web pages”
http://www.google.ch/patents/US20120317089
#pubcon
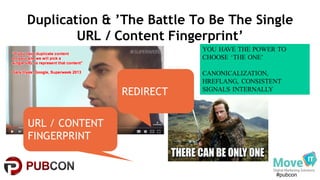
Duplication & ’The Battle To Be The Single
URL / Content Fingerprint’
URL / CONTENT
FINGERPRINT
REDIRECT
YOU HAVE THE POWER TO
CHOOSE ‘THE ONE’
CANONICALIZATION,
HREFLANG, CONSISTENT
SIGNALS INTERNALLY
#pubcon
NON-
PREFERRED
VERSION
‘IMPOSTER
INDEXATION’ &
‘TOO SIMILAR’
CONTENT
The wrong version
of your URL is
selected and
indexed
Users may pick the wrong version of
the duplicate content and link to that
one. Then signals are dissipated
#pubcon
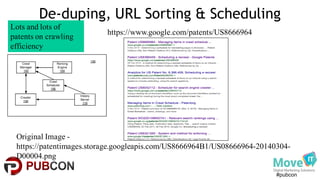
De-duping, URL Sorting & Scheduling
Original Image -
https://patentimages.storage.googleapis.com/US8666964B1/US08666964-20140304-
D00004.png
https://www.google.com/patents/US8666964
Lots and lots of
patents on crawling
efficiency
#pubcon
Important Pages Are Crawled More Frequently
These pages are important and need to be up to
date. They cannot be returned as stale data
#pubcon
Depth Of Crawl Is Greater In Higher
Quality Sections Of Sites
• Important grandparents and parents
begets ’important’ children and
grandchild URLs
• Higher quality site sections
(descendants) get crawled more
#pubcon
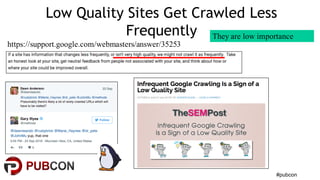
Low Quality Sites Get Crawled Less
Frequently
https://support.google.com/webmasters/answer/35253
They are low importance
#pubcon
Myth – It’s Based Just On PageRank
”There’s a ‘shit-ton’ of other
stuff going on which plays an
important role” (Illyes,
Google)
#pubcon
PageRank Has Become Just One Of Very
Many Things
“WHATEVERYOU ARE THINKING…
WHETHER IT BE ABOUTCRAWLING OR
RANKING… IT (PAGERANK)HAS
BECOME JUSTONE OFVERYMANY
THINGS” (Andrey Lipattsev, Google, 2016)
#pubcon
It’s Mostly Driven By ‘Importance’
“SCHEDULING  IS  MOSTLY  
DRIVEN  BY
IMPORTANCE”  (Illyes,  Google)
IMPORTANCE  MAY  INCLUDE  
PAGERANK  (Patents)  …  BUT  IT  IS  
ONLY  A  PART  OF  IT
RANKING  IS  ALSO  DRIVEN  BY  
IMPORTANCE  (IN  PART)
#pubcon
Page (URL) Importance Is Mahoossively
Important (May Include PageRank)
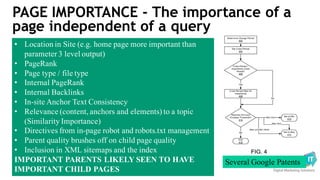
PAGE IMPORTANCE - The importance of a
page independent of a query
• Location in Site (e.g. home page more important than
parameter 3 level output)
• PageRank
• Page type / file type
• Internal PageRank
• Internal Backlinks
• In-site Anchor Text Consistency
• Relevance (content, anchors and elements) to a topic
(Similarity Importance)
• Directives from in-page robot and robots.txt management
• Parent quality brushes off on child page quality
• Inclusion in XML sitemaps and the index
IMPORTANT PARENTS LIKELY SEEN TO HAVE
IMPORTANT CHILD PAGES
Several Google Patents
#pubcon
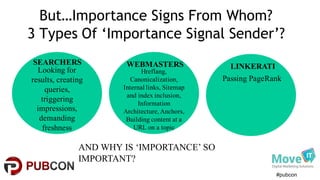
But…Importance Signs From Whom?
3 Types Of ‘Importance Signal Sender’?
SEARCHERS WEBMASTERS LINKERATILooking for
results, creating
queries,
triggering
impressions,
demanding
freshness
Hreflang,
Canonicalization,
Internal links, Sitemap
and index inclusion,
Information
Architecture,Anchors,
Building content at a
URL on a topic
Passing PageRank
AND WHY IS ‘IMPORTANCE’ SO
IMPORTANT?
#pubcon
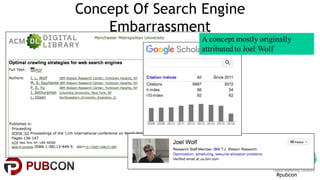
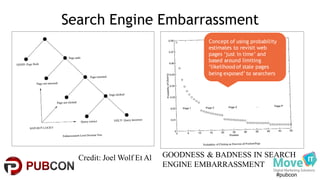
Concept Of Search Engine
Embarrassment
A concept mostly originally
attributed to Joel Wolf
#pubcon
Search Engine Embarrassment
Credit: Joel Wolf Et Al GOODNESS & BADNESS IN SEARCH
ENGINE EMBARRASSMENT
Concept of using probability
estimates to revisit web
pages ‘just in time’ and
based around limiting
‘likelihood of stale pages
being exposed’ to searchers
#pubcon
Search Engine Embarrassment
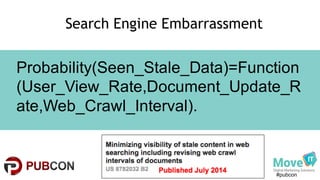
Probability(Seen_Stale_Data)=Function
(User_View_Rate,Document_Update_R
ate,Web_Crawl_Interval).
#pubcon
Search Engine Embarrassment
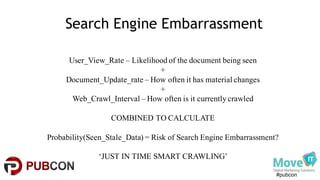
User_View_Rate – Likelihood of the document being seen
+
Document_Update_rate – How often it has material changes
+
Web_Crawl_Interval – How often is it currently crawled
COMBINED TO CALCULATE
Probability(Seen_Stale_Data) = Risk of Search Engine Embarrassment?
‘JUST IN TIME SMART CRAWLING’
#pubcon
THEORY - Search Engine Embarrassment
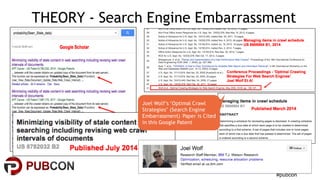
Joel Wolf’s ‘Optimal Crawl
Strategies’ (Search Engine
Embarrassment) Paper is Cited
in this Google Patent
#pubcon
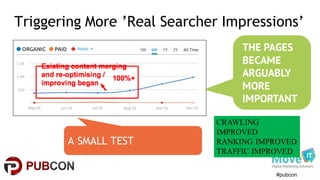
Triggering More ’Real Searcher Impressions’
A SMALL TEST
THE PAGES
BECAME
ARGUABLY
MORE
IMPORTANT
CRAWLING
IMPROVED
RANKING IMPROVED
TRAFFIC IMPROVED
#pubcon
Myth – Don’t We Just Have To Make Random
Changes To Get Crawled More?
NOT ALL CHANGE IS
CREATED EQUAL
#pubcon
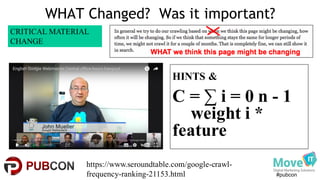
WHAT Changed? Was it important?
https://www.seroundtable.com/google-crawl-
frequency-ranking-21153.html
HINTS &
C = ∑ i = 0 n - 1
weight i *
feature
CRITICAL MATERIAL
CHANGE
#pubcon
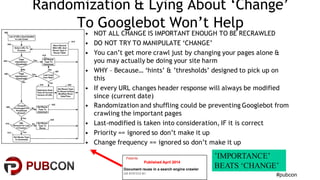
Randomization & Lying About ‘Change’
To Googlebot Won’t Help
• NOT ALL CHANGE IS IMPORTANT ENOUGH TO BE RECRAWLED
• DO NOT TRY TO MANIPULATE ‘CHANGE’
• You can’t get more crawl just by changing your pages alone &
you may actually be doing your site harm
• WHY – Because… ‘hints’ & ’thresholds’ designed to pick up on
this
• If every URL changes header response will always be modified
since (current date)
• Randomization and shuffling could be preventing Googlebot from
crawling the important pages
• Last-modified is taken into consideration, IF it is correct
• Priority == ignored so don’t make it up
• Change frequency == ignored so don’t make it up
’IMPORTANCE’
BEATS ‘CHANGE’
#pubcon
‘Crawl Rank’ – Causation or Correlation?
• By getting your URL crawled more frequently do
they automatically rank higher?
• “A lot of people confuse crawling with ranking”
(John Mu)
• Crawl Rank - It seems this is more correlation
than causation
• You got your URLs crawled more by making
them more important (e.g. via internal linking
strategies), canonicalization, hreflang, merging
and improving thin content, etc, updating with
fresh and rich content to a topic… and
subsequently ranked higher
“Often times, it is kind of a
relationship that, when we think
something is important we tend to
crawl it more frequently and that
might be more visible in search”
John Mueller, Google
#pubcon
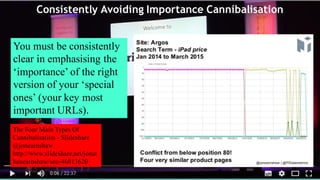
The Four Main Types Of
Cannibalisation– Slideshare
@jonearnshaw
http://www.slideshare.net/jonat
hanearnshaw/seo-46813620
Consistently Avoiding Importance Cannibalisation
You must be consistently
clear in emphasising the
‘importance’ of the right
version of your ‘special
ones’ (your key most
important URLs).
#pubcon
Consistently avoiding ‘Mixed Signals’ & Skewed
URL Importance
GOOGLE CAN GET
CONFUSED AS TO WHICH
PAGE IT SHOULD RANK
FROM YOUR SITE FOR
KEY TERMS – BE CLEAR
ON TARGETS
#pubcon
Consistency - Avoiding ‘importance
dissipation’ from generational cruft
Consider keeping the
same URL for annual
events and optimise
the content for
current year
“Choose a URL
structure that can
stand the test of
time” (John Mu,
Google)
#pubcon
Cool URIs (And URLs) Don’t Change
• The iterative drip, drip, drip of Importance
• Nurture & mature (grow) importance
• Consistent importance signals ongoing
• Think URL as well as URI
“…many, many things can change and your URIs
can and should stay the same” (Sir Tim Berners-
Lee)
COOL URIs DON’T CHANGE
https://www.w3.org/Provider/Style/URI
“allocate URIs which
you will be able to
stand by in 2 years, in
20 years, in 200
years” (Sir Tim-
Berners Lee)
IMPORTANCE VIA
CONSISTENCY
#pubcon
“all over the Web, webmasters are
making decisions which will make
it really difficult for themselves in
the future” (Sir Tim Berners-Lee)
Don’t Let That Be You
#pubcon
THANK	
  YOU
TWITTER - @dawnieando
GOOGLE+ -+DawnAnderson888
LINKEDIN – msdawnanderson
www.move-it-marketing.co.uk
#pubcon
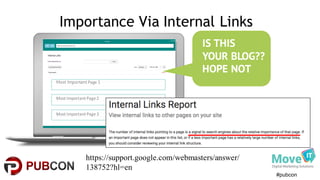
Importance Via Internal Links
Most Important Page 1
Most	
  Important	
  Page	
  2
Most	
  Important	
  Page	
  3
IS THIS
YOUR BLOG??
HOPE NOT
https://support.google.com/webmasters/answer/
138752?hl=en
#pubcon
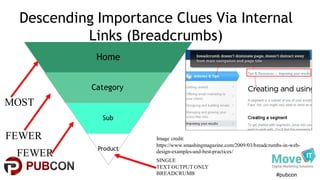
Descending Importance Clues Via Internal
Links (Breadcrumbs)
SINGLE
TEXT OUTPUT ONLY
BREADCRUMB
FEWER
FEWER
MOST
Image credit:
https://www.smashingmagazine.com/2009/03/breadcrumbs-in-web-
design-examples-and-best-practices/
Home
Category
Sub
Product
#pubcon
YES? … YOU’RE IN
NO? … YOU’RE OUT
(sitemaps and index)
Importance By Inclusion (& Unimportance via
Exclusion
#pubcon
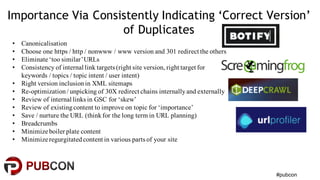
Importance Via Consistently Indicating ‘Correct Version’
of Duplicates
• Canonicalisation
• Choose one https / http / nonwww / www version and 301 redirect the others
• Eliminate ‘too similar’URLs
• Consistency of internal link targets (right site version, right target for
keywords / topics / topic intent / user intent)
• Right version inclusionin XML sitemaps
• Re-optimization/ unpicking of 30X redirect chains internallyand externally
• Review of internal links in GSC for ‘skew’
• Review of existingcontent to improve on topic for ‘importance’
• Save / nurture the URL (thinkfor the long term in URL planning)
• Breadcrumbs
• Minimize boiler plate content
• Minimize regurgitatedcontent in various parts of your site
#pubcon
SOURCES
• Scheduler For Search Engine Crawler -http://www.google.ch/patents/US20120317089
• We Knew The Web Was Big - https://googleblog.blogspot.co.uk/2008/07/we-knew-
web-was-big.html
• https://www.youtube.com/watch?v=GVKcMU7YNOQ
• http://webpromo.expert/google-qa-duplicate-content/
#pubcon
SOURCES
• http://webpromo.expert/google-qa-crawlingrendering/
• https://twitter.com/dergal/status/777782401497980928
• Cool URIs Don’t Change -https://www.w3.org/Provider/Style/URI
• https://searchenginewatch.com/2016/04/06/webpromos-qa-with-googles-andrey-
lipattsev-transcript/
• https://www.youtube.com/watch?v=Wcnz1kCoiks
• https://www.youtube.com/watch?v=MryA3F0ySew
• ‘Optimal Crawling Strategies For Web Search Engines’ -
http://dl.acm.org/citation.cfm?id=511465