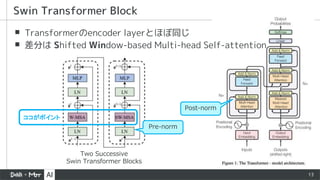
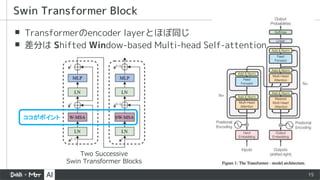
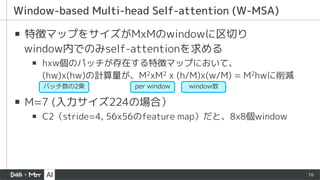
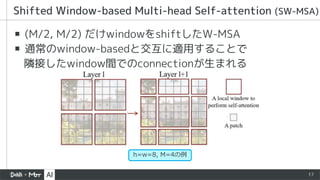
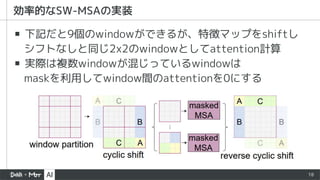
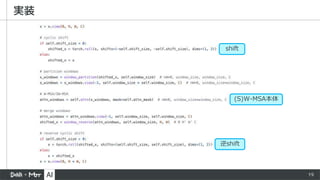
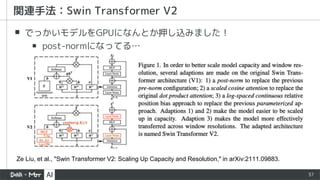
14
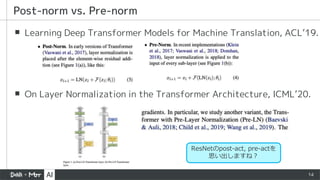
▪ Learning DeepTransformer Models for Machine Translation, ACL’19.
▪ On Layer Normalization in the Transformer Architecture, ICML’20.
Post-norm vs. Pre-norm
ResNetのpost-act, pre-actを
思い出しますね?
20
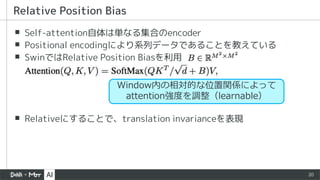
▪ Self-attention自体は単なる集合のencoder
▪ Positionalencodingにより系列データであることを教えている
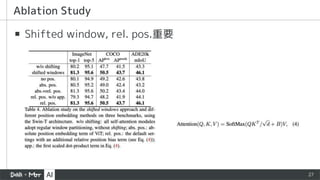
▪ SwinではRelative Position Biasを利用
▪ Relativeにすることで、translation invarianceを表現
Relative Position Bias
Window内の相対的な位置関係によって
attention強度を調整(learnable)
21.
21
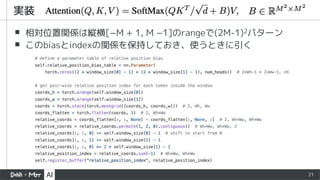
▪ 相対位置関係は縦横[−M +1, M −1]のrangeで(2M-1)2パターン
▪ このbiasとindexの関係を保持しておき、使うときに引く
実装
22.
22
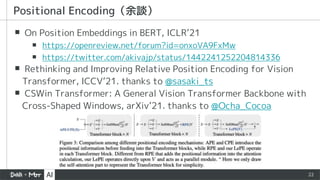
▪ On PositionEmbeddings in BERT, ICLR’21
▪ https://openreview.net/forum?id=onxoVA9FxMw
▪ https://twitter.com/akivajp/status/1442241252204814336
▪ Rethinking and Improving Relative Position Encoding for Vision
Transformer, ICCV’21. thanks to @sasaki_ts
▪ CSWin Transformer: A General Vision Transformer Backbone with
Cross-Shaped Windows, arXiv’21. thanks to @Ocha_Cocoa
Positional Encoding(余談)
23.
23
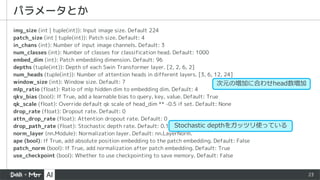
img_size (int |tuple(int)): Input image size. Default 224
patch_size (int | tuple(int)): Patch size. Default: 4
in_chans (int): Number of input image channels. Default: 3
num_classes (int): Number of classes for classification head. Default: 1000
embed_dim (int): Patch embedding dimension. Default: 96
depths (tuple(int)): Depth of each Swin Transformer layer. [2, 2, 6, 2]
num_heads (tuple(int)): Number of attention heads in different layers. [3, 6, 12, 24]
window_size (int): Window size. Default: 7
mlp_ratio (float): Ratio of mlp hidden dim to embedding dim. Default: 4
qkv_bias (bool): If True, add a learnable bias to query, key, value. Default: True
qk_scale (float): Override default qk scale of head_dim ** -0.5 if set. Default: None
drop_rate (float): Dropout rate. Default: 0
attn_drop_rate (float): Attention dropout rate. Default: 0
drop_path_rate (float): Stochastic depth rate. Default: 0.1
norm_layer (nn.Module): Normalization layer. Default: nn.LayerNorm.
ape (bool): If True, add absolute position embedding to the patch embedding. Default: False
patch_norm (bool): If True, add normalization after patch embedding. Default: True
use_checkpoint (bool): Whether to use checkpointing to save memory. Default: False
パラメータとか
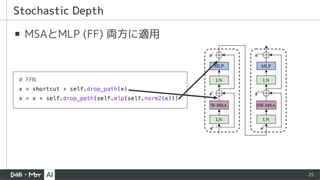
Stochastic depthをガッツリ使っている
次元の増加に合わせhead数増加
30
関連手法:Pyramid Vision Transformer
W.Wang, et al., "Pyramid Vision Transformer: A Versatile Backbone for Dense Prediction without
Convolutions," in Proc. of ICCV, 2021.
https://github.com/whai362/PVT
31.
31
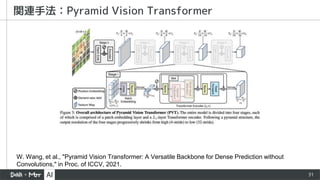
関連手法:Pyramid Vision Transformer
W.Wang, et al., "Pyramid Vision Transformer: A Versatile Backbone for Dense Prediction without
Convolutions," in Proc. of ICCV, 2021.
32.
32
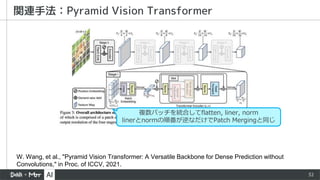
関連手法:Pyramid Vision Transformer
W.Wang, et al., "Pyramid Vision Transformer: A Versatile Backbone for Dense Prediction without
Convolutions," in Proc. of ICCV, 2021.
複数パッチを統合してflatten, liner, norm
linerとnormの順番が逆なだけでPatch Mergingと同じ
33.
33
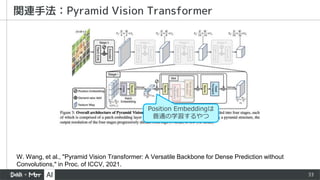
関連手法:Pyramid Vision Transformer
W.Wang, et al., "Pyramid Vision Transformer: A Versatile Backbone for Dense Prediction without
Convolutions," in Proc. of ICCV, 2021.
Position Embeddingは
普通の学習するやつ
34.
34
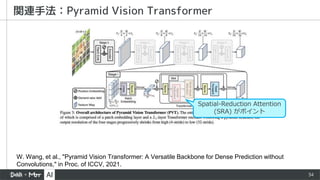
関連手法:Pyramid Vision Transformer
W.Wang, et al., "Pyramid Vision Transformer: A Versatile Backbone for Dense Prediction without
Convolutions," in Proc. of ICCV, 2021.
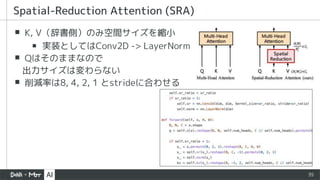
Spatial-Reduction Attention
(SRA) がポイント
38
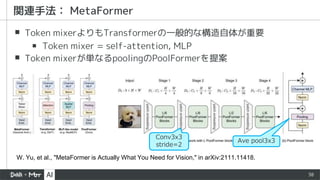
▪ Token mixerよりもTransformerの一般的な構造自体が重要
▪Token mixer = self-attention, MLP
▪ Token mixerが単なるpoolingのPoolFormerを提案
関連手法: MetaFormer
W. Yu, et al., "MetaFormer is Actually What You Need for Vision," in arXiv:2111.11418.
Conv3x3
stride=2
Ave pool3x3