Structured Streaming in
Spark
Vikram Agrawal
Qubole
About Me
● Pursued Computer Science and Engineering from IIT Delhi
● Co-founded a web conferencing solution company before joining Qubole
● In last 5 years at Qubole, I wore multiple hats and worked across stacks to
provide big-data solutions over cloud
● Currently leading the Streaming Team At Qubole
Who should watch this?
● Big Data Engineer (DevOps, Architect, Software, Engineer, Admin)
● Data Platform Manager
● Big Data Enthusiast (Consultant, Executive, Data User, Analyst)
How is streaming used in production?
● Identifying sessions based on user behavior from real time activity streams
● Anomaly and fraud detection: running ML predictions on data streaming in to
keep the model updated continuously as new data comes in
● Time-based window aggregations: using window functions to do associative
aggregations and run real time stats
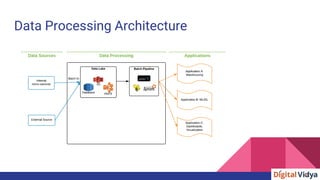
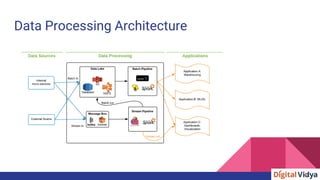
Data Processing Architecture
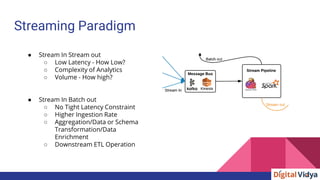
Streaming Paradigm
● Stream In Stream out
○ Low Latency - How Low?
○ Complexity of Analytics
○ Volume - How high?
● Stream In Batch out
○ No Tight Latency Constraint
○ Higher Ingestion Rate
○ Aggregation/Data or Schema
Transformation/Data
Enrichment
○ Downstream ETL Operation
Why use Spark Streaming
● No ultra low Latency requirement
○ Processing time of few secs is acceptable
● Scalable and Mature Processing engine
● Higher Level API abstraction
○ Ease of Code Reuse from Batch jobs
○ Simple and Modular
● Vibrant Community
○ Active Development on new features
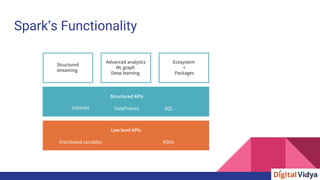
Spark’s Functionality
Structured Streaming - under the hood
● Abstractions of Repeated Queries
○ Data Streams as unbounded
Table
○ Streaming query is a batch-
like operation on this table
Structured Streaming - under the hood
● Query Planning & Execution
○ In Batch Execution, Planner creates code & memory optimized execution plan
○ For Streaming Query, Planner convert streaming Logical plans to a series of incremental
execution plan to process next chunk of data
DataFrame Logical Plan Planner Execution Plan
Planner
Incremental Execution 1
Incremental Execution 2
Incremental Execution 3
Programming Paradigm
Start with Spark Session
Specify Data Source, schema and
other options (create input df)
Write your incremental query to
generate output
Specify Data Sink and other
options to export your data
Val S= SparkSession.builder.appName("kafka
streaming Example").getOrCreate()
val ds = S.readStream.format("kafka")
.option("kafka.bootstrap.servers", brokers)
option("subscribe",
topics).load().selectExpr("CAST(key AS STRING)",
"CAST(value AS STRING)").as[(String, String)
val c= ds.groupBy("value").count()
c.writeStream.queryName("aggregates").format("
memory").outputMode("complete").start()
Productionizing Streaming Application
● Monitoring
○ Throughput
○ Latency
○ Time Lag
● Fault Tolerance
○ Checkpointing
○ Exactly Once or At Least Once
Q&A
Structured Streaming in Spark