A ScyllaDB Community
ScyllaDB Vector Search
A Technical Deep Dive on Real-Time
Performance at Billion-Vector Scale
Prof. Szymon Wąsik
Director of Engineering
Szymon Wąsik
■ 2007-2018: Research work on discrete optimization
and modeling in bioinformatics
■ 2018-2024: Software Engineering at Google, working
on auto-scaling and analytical infrastructure
■ Currently:
■ Engineering Director at ScyllaDB
■ Professor at Merito University Poznań, Poland
Intelligence is the ability to
adapt to change
Stephen Hawking
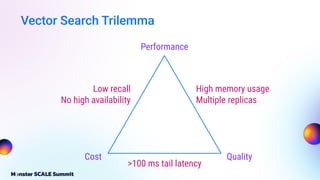
Vector Search Trilemma
Performance
Cost Quality
Low recall
No high availability
High memory usage
Multiple replicas
>100 ms tail latency
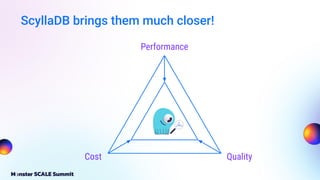
ScyllaDB brings them much closer!
Performance
Cost Quality
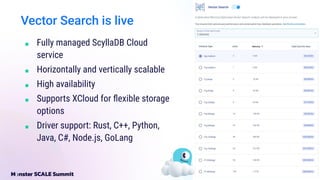
■ Fully managed ScyllaDB Cloud
service
■ Horizontally and vertically scalable
■ High availability
■ Supports XCloud for flexible storage
options
■ Driver support: Rust, C++, Python,
Java, C#, Node.js, GoLang
Vector Search is live
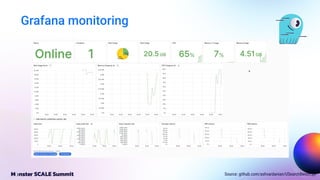
Grafana monitoring
Source: github.com/ashvardanian/USearchBench.py
Designed for real-time AI
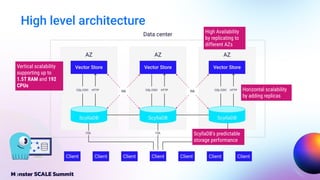
High level architecture
ScyllaDB’s predictable
storage performance
High Availability
by replicating to
different AZs
Horizontal scalability
by adding replicas
Vertical scalability
supporting up to
1.5T RAM and 192
CPUs
HA
HA
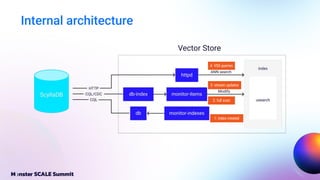
Internal architecture
1: index created
2: full scan
3: stream updates
4: VSS queries
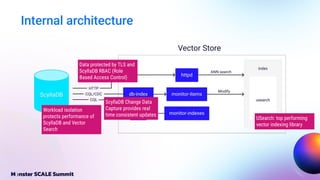
Internal architecture
Workload isolation
protects performance of
ScyllaDB and Vector
Search
USearch: top performing
vector indexing library
Data protected by TLS and
ScyllaDB RBAC (Role
Based Access Control)
ScyllaDB Change Data
Capture provides real
time consistent updates
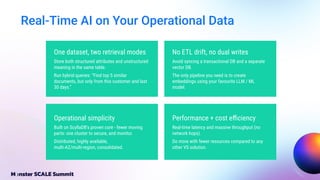
Real-Time AI on Your Operational Data
No ETL drift, no dual writes
Avoid syncing a transactional DB and a separate
vector DB.
The only pipeline you need is to create
embeddings using your favourite LLM / ML
model.
Performance + cost efficiency
Real-time latency and massive throughput (no
network hops).
Do more with fewer resources compared to any
other VS solution.
Operational simplicity
Built on ScyllaDB’s proven core - fewer moving
parts: one cluster to secure, and monitor.
Distributed, highly available,
multi-AZ/multi-region, consolidated.
One dataset, two retrieval modes
Store both structured attributes and unstructured
meaning in the same table.
Run hybrid queries: “Find top 5 similar
documents, but only from this customer and last
30 days.”
Stunning performance
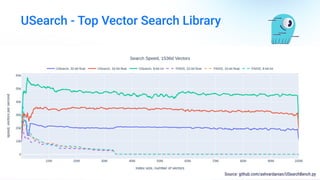
USearch - Top Vector Search Library
Source: github.com/ashvardanian/USearchBench.py
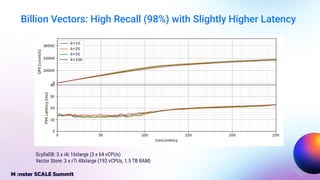
Billion Vectors: High Recall (98%) with Slightly Higher Latency
ScyllaDB: 3 x i4i.16xlarge (3 x 64 vCPUs)
Vector Store: 3 x r7i.48xlarge (192 vCPUs, 1.5 TB RAM)
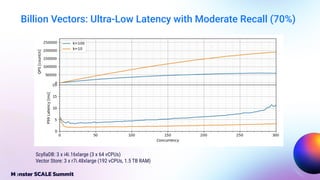
Billion Vectors: Ultra-Low Latency with Moderate Recall (70%)
ScyllaDB: 3 x i4i.16xlarge (3 x 64 vCPUs)
Vector Store: 3 x r7i.48xlarge (192 vCPUs, 1.5 TB RAM)
New in ScyllaDB 2026.1
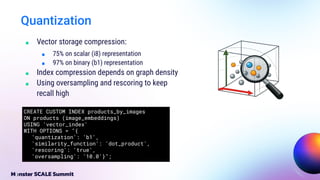
■ Vector storage compression:
■ 75% on scalar (i8) representation
■ 97% on binary (b1) representation
■ Index compression depends on graph density
■ Using oversampling and rescoring to keep
recall high
Quantization
CREATE CUSTOM INDEX products_by_images
ON products (image_embeddings)
USING 'vector_index'
WITH OPTIONS = "{
'quantization': 'b1',
'similarity_function': 'dot_product',
'rescoring': 'true',
'oversampling': '10.0'}";
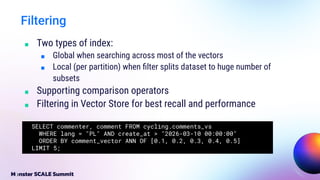
■ Two types of index:
■ Global when searching across most of the vectors
■ Local (per partition) when filter splits dataset to huge number of
subsets
■ Supporting comparison operators
■ Filtering in Vector Store for best recall and performance
Filtering
SELECT commenter, comment FROM cycling.comments_vs
WHERE lang = "PL" AND create_at > "2026-03-10 00:00:00"
ORDER BY comment_vector ANN OF [0.1, 0.2, 0.3, 0.4, 0.5]
LIMIT 5;
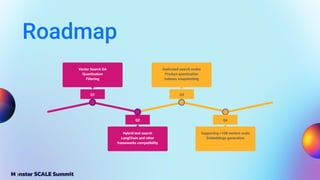
Roadmap
Q4
Supporting >10B vectors scale
Embeddings generation
Q3
Dedicated search nodes
Product quantization
Indexes snapshotting
Q2
Hybrid text search
LangChain and other
frameworks compatibility
Q1
Vector Search GA
Quantization
Filtering
Additional Resources
Videos:
● ⏱ 1 min — Quick Intro
● 🎛 2 min — Live Demo
● 🧭 10 min — Product Overview
● 󰳓 15 min — Step-by-Step Tutorial
Sample Use Cases
● 🎬 Movie Recommendation
● 💬 RAG Chatbot
● ⚡ Semantic Cache (reduce LLM latency & cost)
Sample Applications Learn More
● 📚 Vector Search Documentation
● 🎓 ScyllaDB University Course
● 🎤 P99 Talk - Engineering a Low-Latency
Vector Search Engine for ScyllaDB
ScyllaDB Monsters
ScyllaDB Summit 2025 Styles
The default body font is Roboto Condensed.
You can adjust the size as needed.
You can also use Roboto (the uncondensed version).
For code you should use Roboto Mono and you can set it on
this dark background
Header font is Archivo:
Monster Scale Color palette (base for the gradient): Accent colors:
#15D2A8 #0D72FF #7933FF #0F1040 #F0581E #CE1576
#A3E3FF
https://fonts.google.com/specimen/Archivo
#FFB32B
Body copy font is Roboto
Stay in Touch
Szymon Wąsik
szymon.wasik@scylladb.com
github.com/swasik
https://www.linkedin.com/in/szymon-wasik/