A ScyllaDB Community
Scaling Freshworks’ AI Data
Platform with ScyllaDB
Vigneshkumar AK
Lead Software Engineer
Premkumar Patturaj
Director - Engineering
Vigneshkumar AK, Lead Software Engineer
■ 10+ years of software engineering experience
■ Driving the reliability, scalability, and high availability of distributed database systems, ensuring
efficient operation at scale.
■ 16+ years of IT experience, with 10+ years at Freshworks.
■ Expertise in Relational and NoSQL databases, specializing in designing and optimizing scalable,
high-performance systems.
■ Experienced in solving complex technical challenges, mentoring teams, and fostering a culture of
continuous learning.
Premkumar Patturaj, Director - Engineering
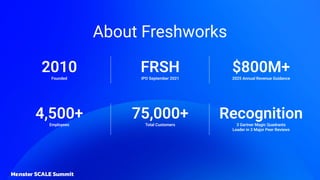
2010
Founded
FRSH
IPO September 2021
$800M+
2025 Annual Revenue Guidance
4,500+
Employees
75,000+
Total Customers
Recognition
3 Gartner Magic Quadrants
Leader in 3 Major Peer Reviews
About Freshworks
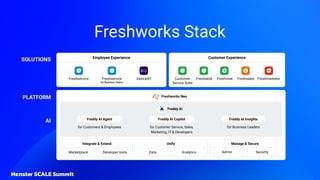
Freddy AI Insights
Freddy AI Copilot
Integrate & Extend
Developer tools
Marketplace
Unify
Data Analytics Admin Security
Manage & Secure
Employee Experience Customer Experience
SOLUTIONS
Freshservice Customer
Service Suite
Freshdesk Freshchat Freshsales Freshmarketer
Freshservice
for Business Teams
Device42
PLATFORM
AI
Freddy AI
for Customer Service, Sales,
Marketing, IT & Developers
for Business Leaders
Freshworks Neo
Freddy AI Agent
for Customers & Employees
Freshworks Stack
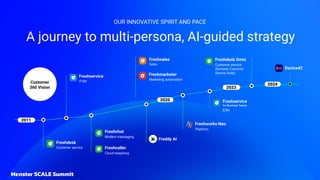
A journey to multi-persona, AI-guided strategy
OUR INNOVATIVE SPIRIT AND PACE
Freddy AI
Customer
360 Vision
ITSM
Freshservice
Freshservice
for Business Teams
Modern messaging
Freshchat
Cloud telephony
Freshcaller
2023
2020
2011
Freshworks Neo
Customer service
Freshdesk
Platform
Marketing automation
Freshmarketer
Freshsales
Sales
Freshdesk Omni
Customer service
(formerly Customer
Service Suite)
ESM
2024
Device42
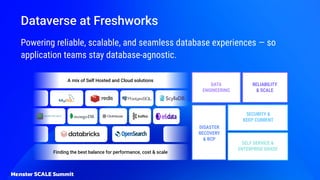
Powering reliable, scalable, and seamless database experiences — so
application teams stay database-agnostic.
A mix of Self Hosted and Cloud solutions
DATA
ENGINEERING
RELIABILITY
& SCALE
SECURITY &
KEEP CURRENT
SELF SERVICE &
ENTERPRISE GRADE
DISASTER
RECOVERY
& BCP
Finding the best balance for performance, cost & scale
Dataverse at Freshworks
Deployment model
BYOA
ScyllaDB @
Freshworks
Performance and
scale factors
ScyllaDB use cases
in Freshworks
Migration Journey
Future Use cases
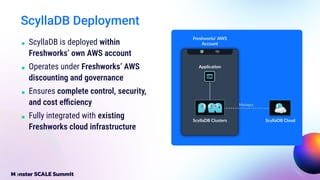
ScyllaDB Deployment
■ ScyllaDB is deployed within
Freshworks’ own AWS account
■ Operates under Freshworks’ AWS
discounting and governance
■ Ensures complete control, security,
and cost efficiency
■ Fully integrated with existing
Freshworks cloud infrastructure
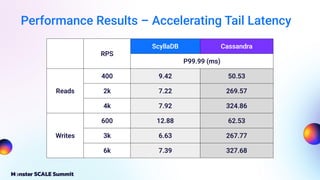
Performance Results – Accelerating Tail Latency
RPS
ScyllaDB Cassandra
P99.99 (ms)
Reads
400 9.42 50.53
2k 7.22 269.57
4k 7.92 324.86
Writes
600 12.88 62.53
3k 6.63 267.77
6k 7.39 327.68
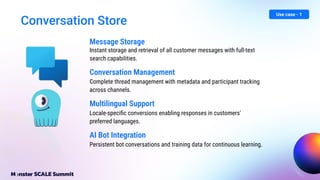
Conversation Store
Message Storage
Instant storage and retrieval of all customer messages with full-text
search capabilities.
Conversation Management
Complete thread management with metadata and participant tracking
across channels.
Multilingual Support
Locale-specific conversions enabling responses in customers'
preferred languages.
AI Bot Integration
Persistent bot conversations and training data for continuous learning.
Use case - 1
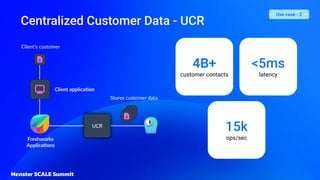
4B+
customer contacts
<5ms
latency
15k
ops/sec
Use case - 2
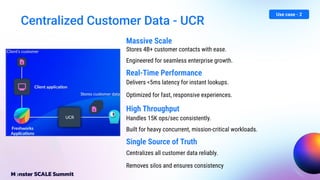
Centralized Customer Data - UCR
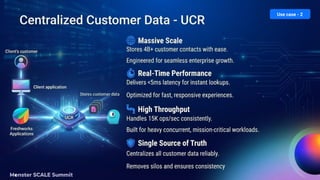
Use case - 2
Centralized Customer Data - UCR
Massive Scale
Stores 4B+ customer contacts with ease.
Engineered for seamless enterprise growth.
Real-Time Performance
Delivers <5ms latency for instant lookups.
Optimized for fast, responsive experiences.
High Throughput
Handles 15K ops/sec consistently.
Built for heavy concurrent, mission-critical workloads.
Single Source of Truth
Centralizes all customer data reliably.
Removes silos and ensures consistency
Use case - 2
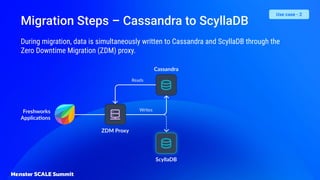
During migration, data is simultaneously written to Cassandra and ScyllaDB through the
Zero Downtime Migration (ZDM) proxy.
Migration Steps – Cassandra to ScyllaDB
Use case - 2
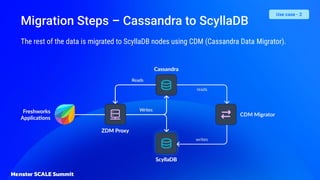
The rest of the data is migrated to ScyllaDB nodes using CDM (Cassandra Data Migrator).
Migration Steps – Cassandra to ScyllaDB
Use case - 2
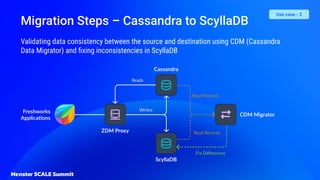
Validating data consistency between the source and destination using CDM (Cassandra
Data Migrator) and fixing inconsistencies in ScyllaDB
Migration Steps – Cassandra to ScyllaDB
Use case - 2
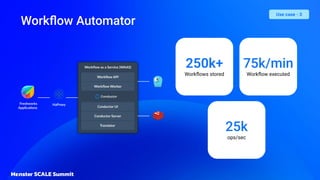
250k+
Workflows stored
75k/min
Workflow executed
25k
ops/sec
Workflow Automator
Use case - 3
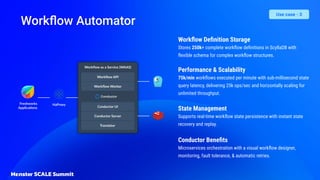
Workflow Automator
Use case - 3
Workflow Definition Storage
Stores 250k+ complete workflow definitions in ScyllaDB with
flexible schema for complex workflow structures.
Performance & Scalability
75k/min workflows executed per minute with sub-millisecond state
query latency, delivering 25k ops/sec and horizontally scaling for
unlimited throughput.
State Management
Supports real-time workflow state persistence with instant state
recovery and replay.
Conductor Benefits
Microservices orchestration with a visual workflow designer,
monitoring, fault tolerance, & automatic retries.
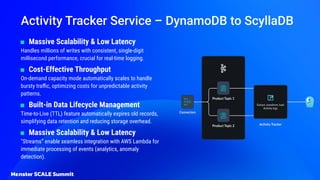
■ Massive Scalability & Low Latency
Handles millions of writes with consistent, single-digit
millisecond performance, crucial for real-time logging.
■ Cost-Effective Throughput
On-demand capacity mode automatically scales to handle
bursty traffic, optimizing costs for unpredictable activity
patterns.
■ Built-in Data Lifecycle Management
Time-to-Live (TTL) feature automatically expires old records,
simplifying data retention and reducing storage overhead.
■ Massive Scalability & Low Latency
"Streams” enable seamless integration with AWS Lambda for
immediate processing of events (analytics, anomaly
detection).
Activity Tracker Service – DynamoDB to ScyllaDB
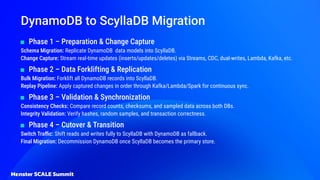
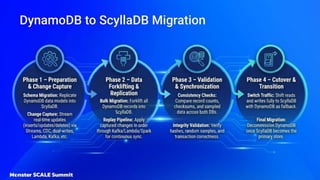
■ Phase 1 – Preparation & Change Capture
Schema Migration: Replicate DynamoDB data models into ScyllaDB.
Change Capture: Stream real-time updates (inserts/updates/deletes) via Streams, CDC, dual-writes, Lambda, Kafka, etc.
■ Phase 2 – Data Forklifting & Replication
Bulk Migration: Forklift all DynamoDB records into ScyllaDB.
Replay Pipeline: Apply captured changes in order through Kafka/Lambda/Spark for continuous sync.
■ Phase 3 – Validation & Synchronization
Consistency Checks: Compare record counts, checksums, and sampled data across both DBs.
Integrity Validation: Verify hashes, random samples, and transaction correctness.
■ Phase 4 – Cutover & Transition
Switch Traffic: Shift reads and writes fully to ScyllaDB with DynamoDB as fallback.
Final Migration: Decommission DynamoDB once ScyllaDB becomes the primary store.
DynamoDB to ScyllaDB Migration
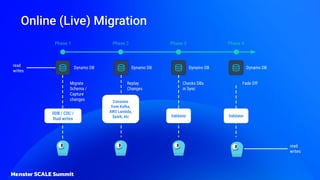
Online (Live) Migration
DDB / CDC /
Dual writes
read
writes
Dynamo DB Dynamo DB
Migrate
Schema /
Capture
changes
Replay
Changes
Consume
from Kafka,
AWS Lambda,
Spark, etc
Dynamo DB
Validator
Checks DBs
in Sync
Dynamo DB
Validator
Fade Off
read
writes
Phase 2
Phase 1 Phase 3 Phase 4
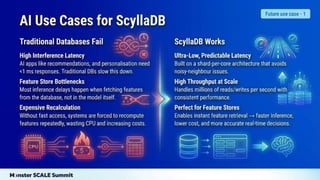
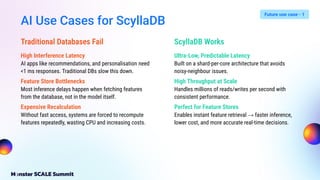
AI Use Cases for ScyllaDB
Traditional Databases Fail
High Interference Latency
AI apps like recommendations, and personalisation need
<1 ms responses. Traditional DBs slow this down.
Feature Store Bottlenecks
Most inference delays happen when fetching features
from the database, not in the model itself.
Expensive Recalculation
Without fast access, systems are forced to recompute
features repeatedly, wasting CPU and increasing costs.
ScyllaDB Works
Ultra-Low, Predictable Latency
Built on a shard-per-core architecture that avoids
noisy-neighbour issues.
High Throughput at Scale
Handles millions of reads/writes per second with
consistent performance.
Perfect for Feature Stores
Enables instant feature retrieval → faster inference,
lower cost, and more accurate real-time decisions.
Future use case - 1
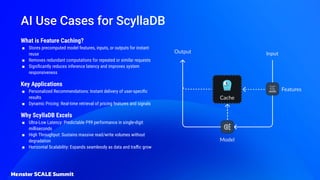
AI Use Cases for ScyllaDB
What is Feature Caching?
■ Stores precomputed model features, inputs, or outputs for instant
reuse
■ Removes redundant computations for repeated or similar requests
■ Significantly reduces inference latency and improves system
responsiveness
Key Applications
■ Personalized Recommendations: Instant delivery of user-specific
results
■ Dynamic Pricing: Real-time retrieval of pricing features and signals
Why ScyllaDB Excels
■ Ultra-Low Latency: Predictable P99 performance in single-digit
milliseconds
■ High Throughput: Sustains massive read/write volumes without
degradation
■ Horizontal Scalability: Expands seamlessly as data and traffic grow
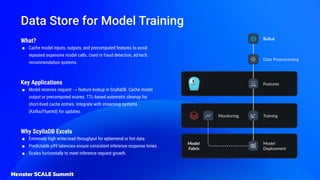
Data Store for Model Training
What?
■ Cache model inputs, outputs, and precomputed features to avoid
repeated expensive model calls. Used in fraud detection, ad-tech,
recommendation systems.
Key Applications
■ Model receives request → feature lookup in ScyllaDB. Cache model
output or precomputed scores. TTL-based automatic cleanup for
short-lived cache entries. Integrate with streaming systems
(Kafka/Fluentd) for updates.
Why ScyllaDB Excels
■ Extremely high write/read throughput for ephemeral or hot data.
■ Predictable p99 latencies ensure consistent inference response times.
■ Scales horizontally to meet inference request growth.
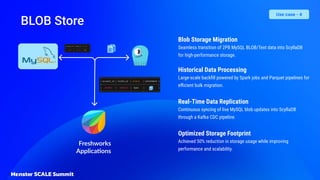
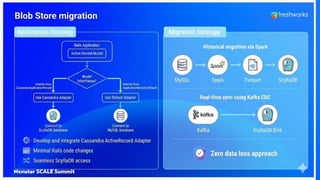
BLOB Store
Use case - 4
Blob Storage Migration
Seamless transition of 2PB MySQL BLOB/Text data into ScyllaDB
for high-performance storage.
Historical Data Processing
Large-scale backfill powered by Spark jobs and Parquet pipelines for
efficient bulk migration.
Real-Time Data Replication
Continuous syncing of live MySQL blob updates into ScyllaDB
through a Kafka CDC pipeline.
Optimized Storage Footprint
Achieved 50% reduction in storage usage while improving
performance and scalability.
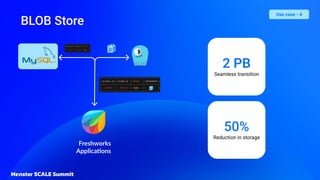
BLOB Store
Use case - 4
2 PB
Seamless transition
50%
Reduction in storage
Takeaways
■ Low Tail Latency
■ BYOA
■ Scales for Enterprise workloads
■ Cache Workloads, DynamoDB Workloads and Cassandra Workloads
■ Zero Downtime Patching for Version Upgrades
■ Dynamic Scaling Capabilities
Stay in Touch
Vigneshkumar AK
vigneshkumar.ak@freshworks.com
www.linkedin.com/in/vigneshkumarak
Premkumar Patturaj
premkumar.patturaj@freshworks.com
https://x.com/iam_prem
https://www.linkedin.com/in/prem-k
umar-patturaj-27217933/