Search, download and analyse KB
data sets: a practical introduction
Rene Voorburg & Juliette Lonij
Introduction
Motivation
• Digital humanities scholars, students and other users with limited
technical background
• Practical, hands-on introduction to some of the key steps involved in
computer-assisted research
• Small-scale, not fully automated
Example
• KB Fellow Joris van Eijnatten
• https://www.youtube.com/watch?v=keaKQPOpMQM
Workflow
• Research question: popular perspectives on Europe
• Data gathering: thematically related sets of newspaper articles
• Data preparation: formatting, cleaning OCR errors, spelling variation
• Data analysis: topic, keyword, collocate extraction
• Interpretation: focus on institutional technocracy
Workshop overview
• Data gathering (Rene Voorburg)
• Types of files and metadata associated with digital objects
• Downloading data sets with OAI-PMH and the resolver
• Searching a collection with the SRU search API
• Data analysis (Juliette Lonij)
• Extracting keywords and their context with the Frame generator
APIs
Frame generator
Background
• Created in collaboration with prof. dr. Joris van Eijnatten (UU) during
his KB Digital Humanities Fellowship in 2016
• Building on Keyword generator developed with KB Reseacher-in-
residence dr. Pim Huijnen (UU) in 2015
• Meaningfully reduce a set of documents to word patterns to provide
some insight into the semantic content of dataset
Features
• Generate topics with the Mallet or Gensim topic modelling library
• Extract a single, ranked list of keywords based on either topics or tf-idf
scores
• Find co-occurrence patterns for the keywords in the texts from which
they were originally extracted (forming so-called frames)
• Lemmatize and pos-tag the input texts with NLP suite Frog and restrict
the keywords and collocates to specific part-of-speech tags
Interfaces
• Online demo
• Showcase main functionality for small dataset (max. 25KB)
• Graphical user interface and simple visualisation
• Source code GitHub
• Larger datasets and extended functionality (e.g. regular expressions, document
splitting, results as comma-separated values files)
• Use from the command line, as a Python library or web application
Online demo
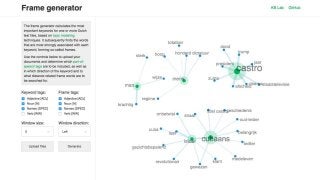
• Upload text files with the button 'Upload files’
• Control settings:
• Select the part-of-speech tags to be included as keywords under 'Keyword tags’
• Select the part-of-speech tags to be included as collocates under 'Frame tags’
• Set the the maximum distance of a frame word to a keyword with 'Window size’
• Set the direction in which frame words are searched for with 'Window direction’
• Once all options are set, press the 'Generate' button
Command line interface (1)
• Clone or download the GitHub repository:
$ git clone https://github.com/jlonij/frame-generator
• Install the required Python packages:
$ pip install -r requirements.txt
• Basic command line execution with the default values for all options:
$ ./generator.py
Command line interface (2)
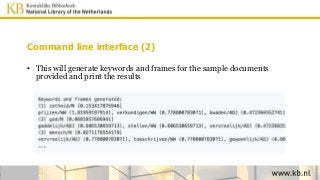
• This will generate keywords and frames for the sample documents
provided and print the results
Command line interface (3)
• User-provided stop word lists and regular expressions
• Accepts a large number of options to control the process, e.g.:
• --gtype: the type of results to be generated (topics, keywords or frames)
• --dlen: the number of sentences the subdocuments used for analysis are to contain
• --tcount, --kcount, --fsize: the number of topics, keywords, frame words
• Accepts main tags from the CGN tag set as part-of-speech tags with the
--ktags and --ftags options
Any questions?