Regression analysis - Estimation of relationships between the variables
Regression analysis is a set of statistical methods used for the estimation of relationships between a dependent variable and one or more independent variables
Regression analysis - Estimation of relationships between the variables
1.
Dr. S. Parasuraman,M.Pharm., Ph.D.,
Senior Associate Professor,
Faculty of Pharmacy,
AIMST University
Malaysia
Regression analysis
2.
Learning Outcomes
• Uponsuccessful completion of this topic, students
should be able to:
• outline the assumption of regression analysis.
• explain the line of best fit.
• compute the equation of the regression line.
3.
Introduction to regressionanalysis
• Regression analysis is a key part of predictive
analysis.
• Regression analysis is helpful in assessing specific
forms of the relationship between variables.
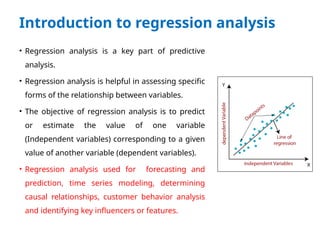
• The objective of regression analysis is to predict
or estimate the value of one variable
(Independent variables) corresponding to a given
value of another variable (dependent variables).
• Regression analysis used for forecasting and
prediction, time series modeling, determining
causal relationships, customer behavior analysis
and identifying key influencers or features.
4.
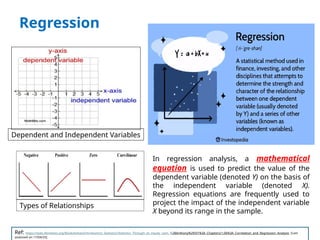
Independent vs. DependentVariables
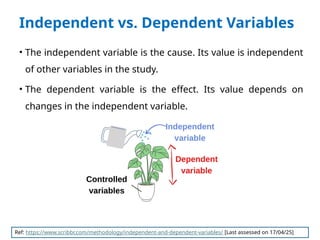
• The independent variable is the cause. Its value is independent
of other variables in the study.
• The dependent variable is the effect. Its value depends on
changes in the independent variable.
Ref: https://www.scribbr.com/methodology/independent-and-dependent-variables/ [Last assessed on 17/04/25]
Regression
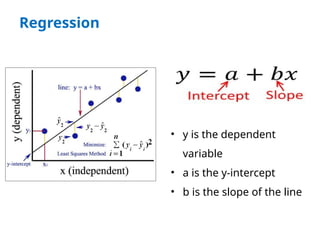
• y isthe dependent
variable
• a is the y-intercept
• b is the slope of the line
7.
Regression
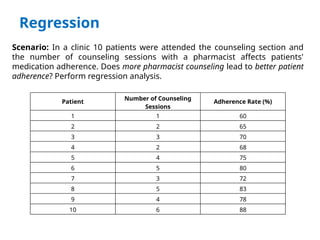
Scenario: In aclinic 10 patients were attended the counseling section and
the number of counseling sessions with a pharmacist affects patients'
medication adherence. Does more pharmacist counseling lead to better patient
adherence? Perform regression analysis.
Patient
Number of Counseling
Sessions
Adherence Rate (%)
1 1 60
2 2 65
3 3 70
4 2 68
5 4 75
6 5 80
7 3 72
8 5 83
9 4 78
10 6 88
8.
Regression
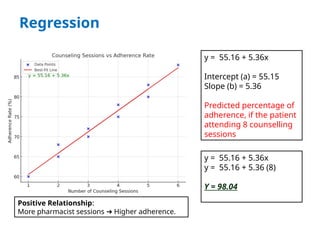
Positive Relationship:
More pharmacistsessions Higher adherence.
➔
y = 55.16 + 5.36x
Intercept (a) = 55.15
Slope (b) = 5.36
Predicted percentage of
adherence, if the patient
attending 8 counselling
sessions
y = 55.16 + 5.36x
y = 55.16 + 5.36 (8)
Y = 98.04
9.
Types of regression
•Linear regression: Simple linear regression is used to model the
relationship between two variables, where one is considered the
independent variable (predictor) and the other is the dependent
variable (outcome).
• Multiple linear regression: Multiple linear regression extends
simple linear regression to model relationships between multiple
independent variables and a single dependent variable.
• Logistic regression: Logistic regression is used when the
dependent variable is binary (two possible outcomes). It models
the probability of a particular outcome occurring.
Ref: https://www.simplilearn.com/tutorials/excel-tutorial/regression-analysis [Last assessed on 17/04/25]
10.
Types of regression
•Polynomial regression: Polynomial regression is used when the
relationship between the independent and dependent variables follows a
polynomial curve and is not linear.
• Non-linear Regression: Non-linear regression is used when the
relationship between the dependent and independent variables can take
various functional forms.
• Multivariate Linear Regression: Multivariate linear regression expands
on multiple linear regression by including more than one dependent
variable in the analysis, alongside multiple independent variables. This
method is particularly valuable for addressing complex real-world
situations where multiple outcomes are influenced by various factors.
Ref: https://www.simplilearn.com/tutorials/excel-tutorial/regression-analysis [Last assessed on 17/04/25]
11.
Assumption of regressionanalysis
• Linear assumptions
• The mean of the distribution of errors is 0
• The variance of errors is constant across all levels of the
independent variable (homoscedasticity), to check plot the
residuals versus the predicted values of y
• The distribution of errors is normal (can test this using a
histogram, Q-Q plot, or statistical tests like Shapiro-Wilk).
• All the errors are independent.
Ref: Assumptions of Regression Analysis.
https://www.ncl.ac.uk/webtemplate/ask-assets/external/maths-resources/statistics/regression-and-correlation/assu
mptions-of-regression-analysis.html
12.
Assumption of regressionanalysis
• For the simple and multiple regression model
• The chosen sample is representative of the population.
• There is a linear relationship between the independent
variable(s) and the dependent variable.
• All the variables are normally distributed.
• There are no outliers, (if there are outliers they need to be
removed).
• The independent variables are all linearly independent
• For multiple regression there should be at least five times as
many pairs of data than dependent variables.
Ref: Assumptions of Regression Analysis.
https://www.ncl.ac.uk/webtemplate/ask-assets/external/maths-resources/statistics/regression-and-correlation/assu
mptions-of-regression-analysis.html
13.
Disadvantages of RegressionAnalysis
• Assumptions and limitations: Regression analysis assumes
linearity, independence, and constant variance, which may not
always hold in real-world scenarios.
• Overfitting and underfitting: Models can be overly complex
(overfitting) or too simplistic (underfitting) if not carefully tuned.
• Outliers and influential points: Extreme data points can
disproportionately affect regression results, leading to inaccurate
conclusions.
• Misinterpretation of results: Users may misinterpret regression output
without proper understanding, leading to flawed decisions or actions.
Ref: https://www.simplilearn.com/tutorials/excel-tutorial/regression-analysis/ [Last assessed on 17/04/25]
14.
Line of bestfit
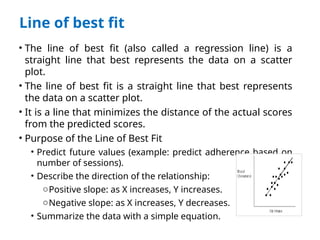
• The line of best fit (also called a regression line) is a
straight line that best represents the data on a scatter
plot.
• The line of best fit is a straight line that best represents
the data on a scatter plot.
• It is a line that minimizes the distance of the actual scores
from the predicted scores.
• Purpose of the Line of Best Fit
• Predict future values (example: predict adherence based on
number of sessions).
• Describe the direction of the relationship:
oPositive slope: as X increases, Y increases.
oNegative slope: as X increases, Y decreases.
• Summarize the data with a simple equation.
15.
Differences from correlation
FeatureRegression Correlation
Purpose
Predicts one variable from
another
Measures strength &
direction of association
Direction
One-way: X affects Y
(cause-effect, potentially)
No direction: just shows
association
Equation Yes
No equation, just a single
coefficient
Output
Predictive model
(line of best fit) +
coefficients
Correlation coefficient (r)
Type of
Variables
One dependent and
one/more independent
variables
Two variables treated equally
Units Units matter
Unitless
(always between -1 and +1)
Forecasting, causal Measuring strength of