Skip to main content
Recommended
PPTX
RAG_Presentation_detail_explanation.pptx
PPTX
Retrieval_Augmented_Generation_Presentation.pptx
PPTX
Natural Language Processing (NLP), RAG and its applications .pptx
PDF
Maximizing AI Performance with Retrieval Augmented Generation (RAG).pdf
PPTX
RAG_Presentation_Overview_Concept11.pptx
PPTX
Conference_RAG_Presentation_entire_.pptx
PPTX
RAG Model Retrieval Augmented model for LLms
PDF
introductiontoragretrievalaugmentedgenerationanditsapplication-240312101523-6...
PPTX
Introduction to RAG (Retrieval Augmented Generation) and its application
PPTX
New Microsoft PowerPoint Presentation.pptx
PDF
RAG App Development and Its Applications in AI.pdf
PDF
RAG App Development and Its Applications in AI.pdf
PPTX
Retrieval-Augmented-Generation-Powering-AI-with-Real-World-Knowledge.pptx
PPTX
Practical_RAG_Presentation_RetrivalAugumentedGeneration.pptx
PPTX
RAG_classnoteswith having various ways of publishing the model.pptx
PDF
社内勉強会資料_StepByStep Build own RAG. .
PPTX
Retrieval Augmented Generation_Overview.pptx
PPTX
Retrieval-Augmented_Generation_Syestems.pptx
PDF
What is RAG? Understanding_Retrieval-Augmented_Generation_(RAG).pdf
PDF
RETRIEVAL AUGMENTED GENERATION (RAG) FOR PRECISION LANGUAGE MODELS
PDF
Comprehensive Overview of Retrieval-Augmented Generation (RAG) Architectures ...
PDF
Using Agentic RAG for Research - Demonstration of NotebookLM
PDF
A Comprehensive Technical Report on Retrieval.pdf
PPTX
TechDayPakistan-Slides RAG with Cosmos DB.pptx
PPTX
RAG_From_Basics_to_Advanced_Full_Architecture_Demo_Presentation.pptx
PDF
Agentic RAG vs Traditional RAG: Architecture, Workflows, Trade-offs, and Prod...
PPTX
RAG_Presentation_on_transformers_in.pptx
PPTX
✅ Recommended (Academic / Training) RAG_Full_Introduction_Architecture_Workf...
PPTX
Comprehensive Guide to Plastifloor and Plastipur Resin Coatings
PPTX
Corpus, Language Modeling, N-gram models, Probability estimation
More Related Content
PPTX
RAG_Presentation_detail_explanation.pptx
PPTX
Retrieval_Augmented_Generation_Presentation.pptx
PPTX
Natural Language Processing (NLP), RAG and its applications .pptx
PDF
Maximizing AI Performance with Retrieval Augmented Generation (RAG).pdf
PPTX
RAG_Presentation_Overview_Concept11.pptx
PPTX
Conference_RAG_Presentation_entire_.pptx
PPTX
RAG Model Retrieval Augmented model for LLms
PDF
introductiontoragretrievalaugmentedgenerationanditsapplication-240312101523-6...
Similar to RAG_Master_Deck_AI_Engineer, Course For AI Engineers
PPTX
Introduction to RAG (Retrieval Augmented Generation) and its application
PPTX
New Microsoft PowerPoint Presentation.pptx
PDF
RAG App Development and Its Applications in AI.pdf
PDF
RAG App Development and Its Applications in AI.pdf
PPTX
Retrieval-Augmented-Generation-Powering-AI-with-Real-World-Knowledge.pptx
PPTX
Practical_RAG_Presentation_RetrivalAugumentedGeneration.pptx
PPTX
RAG_classnoteswith having various ways of publishing the model.pptx
PDF
社内勉強会資料_StepByStep Build own RAG. .
PPTX
Retrieval Augmented Generation_Overview.pptx
PPTX
Retrieval-Augmented_Generation_Syestems.pptx
PDF
What is RAG? Understanding_Retrieval-Augmented_Generation_(RAG).pdf
PDF
RETRIEVAL AUGMENTED GENERATION (RAG) FOR PRECISION LANGUAGE MODELS
PDF
Comprehensive Overview of Retrieval-Augmented Generation (RAG) Architectures ...
PDF
Using Agentic RAG for Research - Demonstration of NotebookLM
PDF
A Comprehensive Technical Report on Retrieval.pdf
PPTX
TechDayPakistan-Slides RAG with Cosmos DB.pptx
PPTX
RAG_From_Basics_to_Advanced_Full_Architecture_Demo_Presentation.pptx
PDF
Agentic RAG vs Traditional RAG: Architecture, Workflows, Trade-offs, and Prod...
PPTX
RAG_Presentation_on_transformers_in.pptx
PPTX
✅ Recommended (Academic / Training) RAG_Full_Introduction_Architecture_Workf...
Recently uploaded
PPTX
Comprehensive Guide to Plastifloor and Plastipur Resin Coatings
PPTX
Corpus, Language Modeling, N-gram models, Probability estimation
PDF
DL Unit_2 _Part_1_Combinational_logic.pdf
PDF
Cyber Security Course_ Learn Cybersecurity from Basics to Advanced.pdf
PDF
Comprehensive Guide to Timber Tie-Down, Bracing, and Structural Fixings for W...
PDF
Multiple Choice Questions on Alloys and Phase Diagrams
PDF
Comprehensive Overview of Electric Vehicle Design and Components
PDF
Comprehensive Overview of Electric Vehicle Components and Their Functions
PDF
Comprehensive Introduction to Electric and Hybrid Vehicle Design for Mechanic...
PDF
Unit 2 part 2_COMBINATIONAL LOGIC CIRCUITS.pdf
PPTX
HACKERS VS DEFENDERS: Protecting digital world
PDF
Comprehensive Overview of Hybrid and Electric Vehicle Design and Operation
PDF
Resume - Mark Mazanec 2026 - Desire to add value to the manufacturing industry
PPTX
Unit II Coordinate Measuring Machines (CMM).pptx
PDF
Training Manual on Emerging Post-Harvest Engineering and Technological Interv...
PPTX
Unit 1 – Foundations of Research(OEC).pptx
PDF
Comprehensive Overview of Electric Vehicle Benefits and Motivation
PPTX
Comprehensive Introduction to Manufacturing Processes and Production Systems
PDF
Practical_No_3_Assignment on applications of Multiplexers & Decoders. .pdf
PDF
Multiple Choice Questions on Ferrous and Non-Ferrous Metals and Their Applica...
RAG_Master_Deck_AI_Engineer, Course For AI Engineers 1. RAG – Retrieval Augmented
Generation
Complete Interview & Production Guide
For AI Engineer Roles
2. What is RAG?
RAG combines LLMs with external knowledge retrieval to generate
accurate, grounded answers.
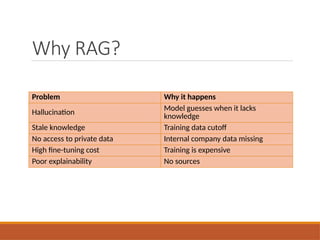
3. Why RAG?
Problem Why it happens
Hallucination Model guesses when it lacks
knowledge
Stale knowledge Training data cutoff
No access to private data Internal company data missing
High fine-tuning cost Training is expensive
Poor explainability No sources
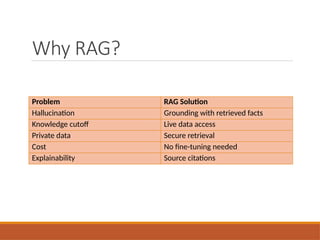
4. Why RAG?
Problem RAG Solution
Hallucination Grounding with retrieved facts
Knowledge cutoff Live data access
Private data Secure retrieval
Cost No fine-tuning needed
Explainability Source citations
5. 6. 7. 8. 9. 10. 11. 12. 13. 14. 15. 16. 17. 18. 19. 20. 21. 22. 23. 24.