powered by
Wes McKinney
Python for
Data Analysis
DATA WRANGLING WITH PANDAS,
NUMPY, AND IPYTHON
2
n
d
E
d
i
t
i
o
n
Wes McKinney
Python for Data Analysis
Data Wrangling with Pandas, NumPy,
and IPython
SECOND EDITION
Boston Farnham Sebastopol Tokyo
Beijing Boston Farnham Sebastopol Tokyo
Beijing
978-1-491-95766-0
[LSI]
Python for Data Analysis
by Wes McKinney
Copyright © 2018 William McKinney. All rights reserved.
Printed in the United States of America.
Published by O’Reilly Media, Inc., 1005 Gravenstein Highway North, Sebastopol, CA 95472.
O’Reilly books may be purchased for educational, business, or sales promotional use. Online editions are
also available for most titles (http://oreilly.com/safari). For more information, contact our corporate/insti‐
tutional sales department: 800-998-9938 or corporate@oreilly.com.
Editor: Marie Beaugureau
Production Editor: Kristen Brown
Copyeditor: Jasmine Kwityn
Proofreader: Rachel Monaghan
Indexer: Lucie Haskins
Interior Designer: David Futato
Cover Designer: Karen Montgomery
Illustrator: Rebecca Demarest
October 2012: First Edition
October 2017: Second Edition
Revision History for the Second Edition
2017-09-25: First Release
See http://oreilly.com/catalog/errata.csp?isbn=9781491957660 for release details.
The O’Reilly logo is a registered trademark of O’Reilly Media, Inc. Python for Data Analysis, the cover
image, and related trade dress are trademarks of O’Reilly Media, Inc.
While the publisher and the author have used good faith efforts to ensure that the information and
instructions contained in this work are accurate, the publisher and the author disclaim all responsibility
for errors or omissions, including without limitation responsibility for damages resulting from the use of
or reliance on this work. Use of the information and instructions contained in this work is at your own
risk. If any code samples or other technology this work contains or describes is subject to open source
licenses or the intellectual property rights of others, it is your responsibility to ensure that your use
thereof complies with such licenses and/or rights.
Table of Contents
Preface. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . xi
1. Preliminaries. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 1
1.1 What Is This Book About? 1
What Kinds of Data? 1
1.2 Why Python for Data Analysis? 2
Python as Glue 2
Solving the “Two-Language” Problem 3
Why Not Python? 3
1.3 Essential Python Libraries 4
NumPy 4
pandas 4
matplotlib 5
IPython and Jupyter 6
SciPy 6
scikit-learn 7
statsmodels 8
1.4 Installation and Setup 8
Windows 9
Apple (OS X, macOS) 9
GNU/Linux 9
Installing or Updating Python Packages 10
Python 2 and Python 3 11
Integrated Development Environments (IDEs) and Text Editors 11
1.5 Community and Conferences 12
1.6 Navigating This Book 12
Code Examples 13
Data for Examples 13
iii
Import Conventions 14
Jargon 14
2. Python Language Basics, IPython, and Jupyter Notebooks. . . . . . . . . . . . . . . . . . . . . . . . 15
2.1 The Python Interpreter 16
2.2 IPython Basics 17
Running the IPython Shell 17
Running the Jupyter Notebook 18
Tab Completion 21
Introspection 23
The %run Command 25
Executing Code from the Clipboard 26
Terminal Keyboard Shortcuts 27
About Magic Commands 28
Matplotlib Integration 29
2.3 Python Language Basics 30
Language Semantics 30
Scalar Types 38
Control Flow 46
3. Built-in Data Structures, Functions, and Files. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 51
3.1 Data Structures and Sequences 51
Tuple 51
List 54
Built-in Sequence Functions 59
dict 61
set 65
List, Set, and Dict Comprehensions 67
3.2 Functions 69
Namespaces, Scope, and Local Functions 70
Returning Multiple Values 71
Functions Are Objects 72
Anonymous (Lambda) Functions 73
Currying: Partial Argument Application 74
Generators 75
Errors and Exception Handling 77
3.3 Files and the Operating System 80
Bytes and Unicode with Files 83
3.4 Conclusion 84
4. NumPy Basics: Arrays and Vectorized Computation. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 85
4.1 The NumPy ndarray: A Multidimensional Array Object 87
iv | Table of Contents
Creating ndarrays 88
Data Types for ndarrays 90
Arithmetic with NumPy Arrays 93
Basic Indexing and Slicing 94
Boolean Indexing 99
Fancy Indexing 102
Transposing Arrays and Swapping Axes 103
4.2 Universal Functions: Fast Element-Wise Array Functions 105
4.3 Array-Oriented Programming with Arrays 108
Expressing Conditional Logic as Array Operations 109
Mathematical and Statistical Methods 111
Methods for Boolean Arrays 113
Sorting 113
Unique and Other Set Logic 114
4.4 File Input and Output with Arrays 115
4.5 Linear Algebra 116
4.6 Pseudorandom Number Generation 118
4.7 Example: Random Walks 119
Simulating Many Random Walks at Once 121
4.8 Conclusion 122
5. Getting Started with pandas. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 123
5.1 Introduction to pandas Data Structures 124
Series 124
DataFrame 128
Index Objects 134
5.2 Essential Functionality 136
Reindexing 136
Dropping Entries from an Axis 138
Indexing, Selection, and Filtering 140
Integer Indexes 145
Arithmetic and Data Alignment 146
Function Application and Mapping 151
Sorting and Ranking 153
Axis Indexes with Duplicate Labels 157
5.3 Summarizing and Computing Descriptive Statistics 158
Correlation and Covariance 160
Unique Values, Value Counts, and Membership 162
5.4 Conclusion 165
6. Data Loading, Storage, and File Formats. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 167
6.1 Reading and Writing Data in Text Format 167
Table of Contents | v
Reading Text Files in Pieces 173
Writing Data to Text Format 175
Working with Delimited Formats 176
JSON Data 178
XML and HTML: Web Scraping 180
6.2 Binary Data Formats 183
Using HDF5 Format 184
Reading Microsoft Excel Files 186
6.3 Interacting with Web APIs 187
6.4 Interacting with Databases 188
6.5 Conclusion 190
7. Data Cleaning and Preparation. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 191
7.1 Handling Missing Data 191
Filtering Out Missing Data 193
Filling In Missing Data 195
7.2 Data Transformation 197
Removing Duplicates 197
Transforming Data Using a Function or Mapping 198
Replacing Values 200
Renaming Axis Indexes 201
Discretization and Binning 203
Detecting and Filtering Outliers 205
Permutation and Random Sampling 206
Computing Indicator/Dummy Variables 208
7.3 String Manipulation 211
String Object Methods 211
Regular Expressions 213
Vectorized String Functions in pandas 216
7.4 Conclusion 219
8. Data Wrangling: Join, Combine, and Reshape. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 221
8.1 Hierarchical Indexing 221
Reordering and Sorting Levels 224
Summary Statistics by Level 225
Indexing with a DataFrame’s columns 225
8.2 Combining and Merging Datasets 227
Database-Style DataFrame Joins 227
Merging on Index 232
Concatenating Along an Axis 236
Combining Data with Overlap 241
8.3 Reshaping and Pivoting 242
vi | Table of Contents
Reshaping with Hierarchical Indexing 243
Pivoting “Long” to “Wide” Format 246
Pivoting “Wide” to “Long” Format 249
8.4 Conclusion 251
9. Plotting and Visualization. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 253
9.1 A Brief matplotlib API Primer 253
Figures and Subplots 255
Colors, Markers, and Line Styles 259
Ticks, Labels, and Legends 261
Annotations and Drawing on a Subplot 265
Saving Plots to File 267
matplotlib Configuration 268
9.2 Plotting with pandas and seaborn 268
Line Plots 269
Bar Plots 272
Histograms and Density Plots 277
Scatter or Point Plots 280
Facet Grids and Categorical Data 283
9.3 Other Python Visualization Tools 285
9.4 Conclusion 286
10. Data Aggregation and Group Operations. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 287
10.1 GroupBy Mechanics 288
Iterating Over Groups 291
Selecting a Column or Subset of Columns 293
Grouping with Dicts and Series 294
Grouping with Functions 295
Grouping by Index Levels 295
10.2 Data Aggregation 296
Column-Wise and Multiple Function Application 298
Returning Aggregated Data Without Row Indexes 301
10.3 Apply: General split-apply-combine 302
Suppressing the Group Keys 304
Quantile and Bucket Analysis 305
Example: Filling Missing Values with Group-Specific Values 306
Example: Random Sampling and Permutation 308
Example: Group Weighted Average and Correlation 310
Example: Group-Wise Linear Regression 312
10.4 Pivot Tables and Cross-Tabulation 313
Cross-Tabulations: Crosstab 315
10.5 Conclusion 316
Table of Contents | vii
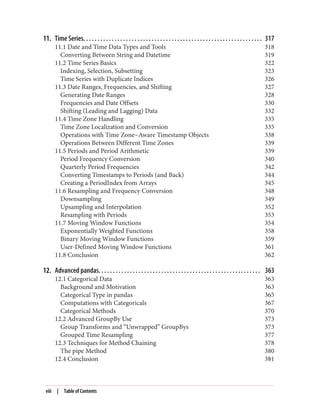
11. Time Series. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 317
11.1 Date and Time Data Types and Tools 318
Converting Between String and Datetime 319
11.2 Time Series Basics 322
Indexing, Selection, Subsetting 323
Time Series with Duplicate Indices 326
11.3 Date Ranges, Frequencies, and Shifting 327
Generating Date Ranges 328
Frequencies and Date Offsets 330
Shifting (Leading and Lagging) Data 332
11.4 Time Zone Handling 335
Time Zone Localization and Conversion 335
Operations with Time Zone−Aware Timestamp Objects 338
Operations Between Different Time Zones 339
11.5 Periods and Period Arithmetic 339
Period Frequency Conversion 340
Quarterly Period Frequencies 342
Converting Timestamps to Periods (and Back) 344
Creating a PeriodIndex from Arrays 345
11.6 Resampling and Frequency Conversion 348
Downsampling 349
Upsampling and Interpolation 352
Resampling with Periods 353
11.7 Moving Window Functions 354
Exponentially Weighted Functions 358
Binary Moving Window Functions 359
User-Defined Moving Window Functions 361
11.8 Conclusion 362
12. Advanced pandas. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 363
12.1 Categorical Data 363
Background and Motivation 363
Categorical Type in pandas 365
Computations with Categoricals 367
Categorical Methods 370
12.2 Advanced GroupBy Use 373
Group Transforms and “Unwrapped” GroupBys 373
Grouped Time Resampling 377
12.3 Techniques for Method Chaining 378
The pipe Method 380
12.4 Conclusion 381
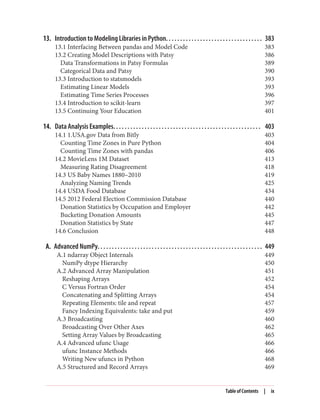
viii | Table of Contents
13. Introduction to Modeling Libraries in Python. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 383
13.1 Interfacing Between pandas and Model Code 383
13.2 Creating Model Descriptions with Patsy 386
Data Transformations in Patsy Formulas 389
Categorical Data and Patsy 390
13.3 Introduction to statsmodels 393
Estimating Linear Models 393
Estimating Time Series Processes 396
13.4 Introduction to scikit-learn 397
13.5 Continuing Your Education 401
14. Data Analysis Examples. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 403
14.1 1.USA.gov Data from Bitly 403
Counting Time Zones in Pure Python 404
Counting Time Zones with pandas 406
14.2 MovieLens 1M Dataset 413
Measuring Rating Disagreement 418
14.3 US Baby Names 1880–2010 419
Analyzing Naming Trends 425
14.4 USDA Food Database 434
14.5 2012 Federal Election Commission Database 440
Donation Statistics by Occupation and Employer 442
Bucketing Donation Amounts 445
Donation Statistics by State 447
14.6 Conclusion 448
A. Advanced NumPy. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 449
A.1 ndarray Object Internals 449
NumPy dtype Hierarchy 450
A.2 Advanced Array Manipulation 451
Reshaping Arrays 452
C Versus Fortran Order 454
Concatenating and Splitting Arrays 454
Repeating Elements: tile and repeat 457
Fancy Indexing Equivalents: take and put 459
A.3 Broadcasting 460
Broadcasting Over Other Axes 462
Setting Array Values by Broadcasting 465
A.4 Advanced ufunc Usage 466
ufunc Instance Methods 466
Writing New ufuncs in Python 468
A.5 Structured and Record Arrays 469
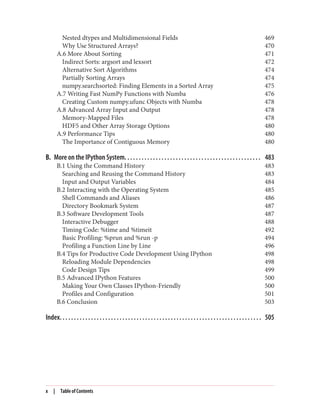
Table of Contents | ix
Nested dtypes and Multidimensional Fields 469
Why Use Structured Arrays? 470
A.6 More About Sorting 471
Indirect Sorts: argsort and lexsort 472
Alternative Sort Algorithms 474
Partially Sorting Arrays 474
numpy.searchsorted: Finding Elements in a Sorted Array 475
A.7 Writing Fast NumPy Functions with Numba 476
Creating Custom numpy.ufunc Objects with Numba 478
A.8 Advanced Array Input and Output 478
Memory-Mapped Files 478
HDF5 and Other Array Storage Options 480
A.9 Performance Tips 480
The Importance of Contiguous Memory 480
B. More on the IPython System. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 483
B.1 Using the Command History 483
Searching and Reusing the Command History 483
Input and Output Variables 484
B.2 Interacting with the Operating System 485
Shell Commands and Aliases 486
Directory Bookmark System 487
B.3 Software Development Tools 487
Interactive Debugger 488
Timing Code: %time and %timeit 492
Basic Profiling: %prun and %run -p 494
Profiling a Function Line by Line 496
B.4 Tips for Productive Code Development Using IPython 498
Reloading Module Dependencies 498
Code Design Tips 499
B.5 Advanced IPython Features 500
Making Your Own Classes IPython-Friendly 500
Profiles and Configuration 501
B.6 Conclusion 503
Index. . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . . 505
x | Table of Contents
Preface
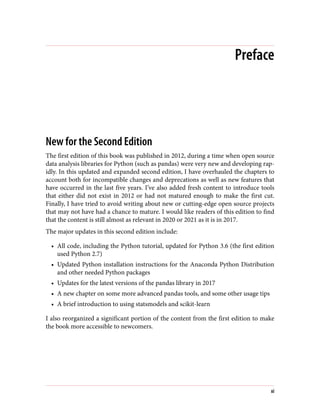
New for the Second Edition
The first edition of this book was published in 2012, during a time when open source
data analysis libraries for Python (such as pandas) were very new and developing rap‐
idly. In this updated and expanded second edition, I have overhauled the chapters to
account both for incompatible changes and deprecations as well as new features that
have occurred in the last five years. I’ve also added fresh content to introduce tools
that either did not exist in 2012 or had not matured enough to make the first cut.
Finally, I have tried to avoid writing about new or cutting-edge open source projects
that may not have had a chance to mature. I would like readers of this edition to find
that the content is still almost as relevant in 2020 or 2021 as it is in 2017.
The major updates in this second edition include:
• All code, including the Python tutorial, updated for Python 3.6 (the first edition
used Python 2.7)
• Updated Python installation instructions for the Anaconda Python Distribution
and other needed Python packages
• Updates for the latest versions of the pandas library in 2017
• A new chapter on some more advanced pandas tools, and some other usage tips
• A brief introduction to using statsmodels and scikit-learn
I also reorganized a significant portion of the content from the first edition to make
the book more accessible to newcomers.
xi
Conventions Used in This Book
The following typographical conventions are used in this book:
Italic
Indicates new terms, URLs, email addresses, filenames, and file extensions.
Constant width
Used for program listings, as well as within paragraphs to refer to program ele‐
ments such as variable or function names, databases, data types, environment
variables, statements, and keywords.
Constant width bold
Shows commands or other text that should be typed literally by the user.
Constant width italic
Shows text that should be replaced with user-supplied values or by values deter‐
mined by context.
This element signifies a tip or suggestion.
This element signifies a general note.
This element indicates a warning or caution.
Using Code Examples
You can find data files and related material for each chapter is available in this book’s
GitHub repository at http://github.com/wesm/pydata-book.
This book is here to help you get your job done. In general, if example code is offered
with this book, you may use it in your programs and documentation. You do not
need to contact us for permission unless you’re reproducing a significant portion of
the code. For example, writing a program that uses several chunks of code from this
xii | Preface
book does not require permission. Selling or distributing a CD-ROM of examples
from O’Reilly books does require permission. Answering a question by citing this
book and quoting example code does not require permission. Incorporating a signifi‐
cant amount of example code from this book into your product’s documentation does
require permission.
We appreciate, but do not require, attribution. An attribution usually includes the
title, author, publisher, and ISBN. For example: “Python for Data Analysis by Wes
McKinney (O’Reilly). Copyright 2017 Wes McKinney, 978-1-491-95766-0.”
If you feel your use of code examples falls outside fair use or the permission given
above, feel free to contact us at permissions@oreilly.com.
O’Reilly Safari
Safari (formerly Safari Books Online) is a membership-based
training and reference platform for enterprise, government,
educators, and individuals.
Members have access to thousands of books, training videos, Learning Paths, interac‐
tive tutorials, and curated playlists from over 250 publishers, including O’Reilly
Media, Harvard Business Review, Prentice Hall Professional, Addison-Wesley Profes‐
sional, Microsoft Press, Sams, Que, Peachpit Press, Adobe, Focal Press, Cisco Press,
John Wiley & Sons, Syngress, Morgan Kaufmann, IBM Redbooks, Packt, Adobe
Press, FT Press, Apress, Manning, New Riders, McGraw-Hill, Jones & Bartlett, and
Course Technology, among others.
For more information, please visit http://oreilly.com/safari.
How to Contact Us
Please address comments and questions concerning this book to the publisher:
O’Reilly Media, Inc.
1005 Gravenstein Highway North
Sebastopol, CA 95472
800-998-9938 (in the United States or Canada)
707-829-0515 (international or local)
707-829-0104 (fax)
We have a web page for this book, where we list errata, examples, and any additional
information. You can access this page at http://bit.ly/python_data_analysis_2e.
Preface | xiii
To comment or ask technical questions about this book, send email to bookques‐
tions@oreilly.com.
For more information about our books, courses, conferences, and news, see our web‐
site at http://www.oreilly.com.
Find us on Facebook: http://facebook.com/oreilly
Follow us on Twitter: http://twitter.com/oreillymedia
Watch us on YouTube: http://www.youtube.com/oreillymedia
Acknowledgments
This work is the product of many years of fruitful discussions, collaborations, and
assistance with and from many people around the world. I’d like to thank a few of
them.
In Memoriam: John D. Hunter (1968–2012)
Our dear friend and colleague John D. Hunter passed away after a battle with colon
cancer on August 28, 2012. This was only a short time after I’d completed the final
manuscript for this book’s first edition.
John’s impact and legacy in the Python scientific and data communities would be
hard to overstate. In addition to developing matplotlib in the early 2000s (a time
when Python was not nearly so popular), he helped shape the culture of a critical gen‐
eration of open source developers who’ve become pillars of the Python ecosystem that
we now often take for granted.
I was lucky enough to connect with John early in my open source career in January
2010, just after releasing pandas 0.1. His inspiration and mentorship helped me push
forward, even in the darkest of times, with my vision for pandas and Python as a
first-class data analysis language.
John was very close with Fernando Pérez and Brian Granger, pioneers of IPython,
Jupyter, and many other initiatives in the Python community. We had hoped to work
on a book together, the four of us, but I ended up being the one with the most free
time. I am sure he would be proud of what we’ve accomplished, as individuals and as
a community, over the last five years.
Acknowledgments for the Second Edition (2017)
It has been five years almost to the day since I completed the manuscript for this
book’s first edition in July 2012. A lot has changed. The Python community has
grown immensely, and the ecosystem of open source software around it has
flourished.
xiv | Preface
This new edition of the book would not exist if not for the tireless efforts of the pan‐
das core developers, who have grown the project and its user community into one of
the cornerstones of the Python data science ecosystem. These include, but are not
limited to, Tom Augspurger, Joris van den Bossche, Chris Bartak, Phillip Cloud,
gfyoung, Andy Hayden, Masaaki Horikoshi, Stephan Hoyer, Adam Klein, Wouter
Overmeire, Jeff Reback, Chang She, Skipper Seabold, Jeff Tratner, and y-p.
On the actual writing of this second edition, I would like to thank the O’Reilly staff
who helped me patiently with the writing process. This includes Marie Beaugureau,
Ben Lorica, and Colleen Toporek. I again had outstanding technical reviewers with
Tom Augpurger, Paul Barry, Hugh Brown, Jonathan Coe, and Andreas Müller contri‐
buting. Thank you.
This book’s first edition has been translated into many foreign languages, including
Chinese, French, German, Japanese, Korean, and Russian. Translating all this content
and making it available to a broader audience is a huge and often thankless effort.
Thank you for helping more people in the world learn how to program and use data
analysis tools.
I am also lucky to have had support for my continued open source development
efforts from Cloudera and Two Sigma Investments over the last few years. With open
source software projects more thinly resourced than ever relative to the size of user
bases, it is becoming increasingly important for businesses to provide support for
development of key open source projects. It’s the right thing to do.
Acknowledgments for the First Edition (2012)
It would have been difficult for me to write this book without the support of a large
number of people.
On the O’Reilly staff, I’m very grateful for my editors, Meghan Blanchette and Julie
Steele, who guided me through the process. Mike Loukides also worked with me in
the proposal stages and helped make the book a reality.
I received a wealth of technical review from a large cast of characters. In particular,
Martin Blais and Hugh Brown were incredibly helpful in improving the book’s exam‐
ples, clarity, and organization from cover to cover. James Long, Drew Conway, Fer‐
nando Pérez, Brian Granger, Thomas Kluyver, Adam Klein, Josh Klein, Chang She,
and Stéfan van der Walt each reviewed one or more chapters, providing pointed feed‐
back from many different perspectives.
I got many great ideas for examples and datasets from friends and colleagues in the
data community, among them: Mike Dewar, Jeff Hammerbacher, James Johndrow,
Kristian Lum, Adam Klein, Hilary Mason, Chang She, and Ashley Williams.
Preface | xv
I am of course indebted to the many leaders in the open source scientific Python
community who’ve built the foundation for my development work and gave encour‐
agement while I was writing this book: the IPython core team (Fernando Pérez, Brian
Granger, Min Ragan-Kelly, Thomas Kluyver, and others), John Hunter, Skipper Sea‐
bold, Travis Oliphant, Peter Wang, Eric Jones, Robert Kern, Josef Perktold, Francesc
Alted, Chris Fonnesbeck, and too many others to mention. Several other people pro‐
vided a great deal of support, ideas, and encouragement along the way: Drew Con‐
way, Sean Taylor, Giuseppe Paleologo, Jared Lander, David Epstein, John Krowas,
Joshua Bloom, Den Pilsworth, John Myles-White, and many others I’ve forgotten.
I’d also like to thank a number of people from my formative years. First, my former
AQR colleagues who’ve cheered me on in my pandas work over the years: Alex Reyf‐
man, Michael Wong, Tim Sargen, Oktay Kurbanov, Matthew Tschantz, Roni Israelov,
Michael Katz, Chris Uga, Prasad Ramanan, Ted Square, and Hoon Kim. Lastly, my
academic advisors Haynes Miller (MIT) and Mike West (Duke).
I received significant help from Phillip Cloud and Joris Van den Bossche in 2014 to
update the book’s code examples and fix some other inaccuracies due to changes in
pandas.
On the personal side, Casey provided invaluable day-to-day support during the writ‐
ing process, tolerating my highs and lows as I hacked together the final draft on top
of an already overcommitted schedule. Lastly, my parents, Bill and Kim, taught me to
always follow my dreams and to never settle for less.
xvi | Preface
CHAPTER 1
Preliminaries
1.1 What Is This Book About?
This book is concerned with the nuts and bolts of manipulating, processing, cleaning,
and crunching data in Python. My goal is to offer a guide to the parts of the Python
programming language and its data-oriented library ecosystem and tools that will
equip you to become an effective data analyst. While “data analysis” is in the title of
the book, the focus is specifically on Python programming, libraries, and tools as
opposed to data analysis methodology. This is the Python programming you need for
data analysis.
What Kinds of Data?
When I say “data,” what am I referring to exactly? The primary focus is on structured
data, a deliberately vague term that encompasses many different common forms of
data, such as:
• Tabular or spreadsheet-like data in which each column may be a different type
(string, numeric, date, or otherwise). This includes most kinds of data commonly
stored in relational databases or tab- or comma-delimited text files.
• Multidimensional arrays (matrices).
• Multiple tables of data interrelated by key columns (what would be primary or
foreign keys for a SQL user).
• Evenly or unevenly spaced time series.
This is by no means a complete list. Even though it may not always be obvious, a large
percentage of datasets can be transformed into a structured form that is more suitable
for analysis and modeling. If not, it may be possible to extract features from a dataset
1
into a structured form. As an example, a collection of news articles could be pro‐
cessed into a word frequency table, which could then be used to perform sentiment
analysis.
Most users of spreadsheet programs like Microsoft Excel, perhaps the most widely
used data analysis tool in the world, will not be strangers to these kinds of data.
1.2 Why Python for Data Analysis?
For many people, the Python programming language has strong appeal. Since its first
appearance in 1991, Python has become one of the most popular interpreted pro‐
gramming languages, along with Perl, Ruby, and others. Python and Ruby have
become especially popular since 2005 or so for building websites using their numer‐
ous web frameworks, like Rails (Ruby) and Django (Python). Such languages are
often called scripting languages, as they can be used to quickly write small programs,
or scripts to automate other tasks. I don’t like the term “scripting language,” as it car‐
ries a connotation that they cannot be used for building serious software. Among
interpreted languages, for various historical and cultural reasons, Python has devel‐
oped a large and active scientific computing and data analysis community. In the last
10 years, Python has gone from a bleeding-edge or “at your own risk” scientific com‐
puting language to one of the most important languages for data science, machine
learning, and general software development in academia and industry.
For data analysis and interactive computing and data visualization, Python will inevi‐
tably draw comparisons with other open source and commercial programming lan‐
guages and tools in wide use, such as R, MATLAB, SAS, Stata, and others. In recent
years, Python’s improved support for libraries (such as pandas and scikit-learn) has
made it a popular choice for data analysis tasks. Combined with Python’s overall
strength for general-purpose software engineering, it is an excellent option as a pri‐
mary language for building data applications.
Python as Glue
Part of Python’s success in scientific computing is the ease of integrating C, C++, and
FORTRAN code. Most modern computing environments share a similar set of legacy
FORTRAN and C libraries for doing linear algebra, optimization, integration, fast
Fourier transforms, and other such algorithms. The same story has held true for
many companies and national labs that have used Python to glue together decades’
worth of legacy software.
Many programs consist of small portions of code where most of the time is spent,
with large amounts of “glue code” that doesn’t run often. In many cases, the execution
time of the glue code is insignificant; effort is most fruitfully invested in optimizing
2 | Chapter 1: Preliminaries
the computational bottlenecks, sometimes by moving the code to a lower-level lan‐
guage like C.
Solving the “Two-Language” Problem
In many organizations, it is common to research, prototype, and test new ideas using
a more specialized computing language like SAS or R and then later port those ideas
to be part of a larger production system written in, say, Java, C#, or C++. What people
are increasingly finding is that Python is a suitable language not only for doing
research and prototyping but also for building the production systems. Why main‐
tain two development environments when one will suffice? I believe that more and
more companies will go down this path, as there are often significant organizational
benefits to having both researchers and software engineers using the same set of pro‐
gramming tools.
Why Not Python?
While Python is an excellent environment for building many kinds of analytical
applications and general-purpose systems, there are a number of uses for which
Python may be less suitable.
As Python is an interpreted programming language, in general most Python code will
run substantially slower than code written in a compiled language like Java or C++.
As programmer time is often more valuable than CPU time, many are happy to make
this trade-off. However, in an application with very low latency or demanding
resource utilization requirements (e.g., a high-frequency trading system), the time
spent programming in a lower-level (but also lower-productivity) language like C++
to achieve the maximum possible performance might be time well spent.
Python can be a challenging language for building highly concurrent, multithreaded
applications, particularly applications with many CPU-bound threads. The reason for
this is that it has what is known as the global interpreter lock (GIL), a mechanism that
prevents the interpreter from executing more than one Python instruction at a time.
The technical reasons for why the GIL exists are beyond the scope of this book. While
it is true that in many big data processing applications, a cluster of computers may be
required to process a dataset in a reasonable amount of time, there are still situations
where a single-process, multithreaded system is desirable.
This is not to say that Python cannot execute truly multithreaded, parallel code.
Python C extensions that use native multithreading (in C or C++) can run code in
parallel without being impacted by the GIL, so long as they do not need to regularly
interact with Python objects.
1.2 Why Python for Data Analysis? | 3
1.3 Essential Python Libraries
For those who are less familiar with the Python data ecosystem and the libraries used
throughout the book, I will give a brief overview of some of them.
NumPy
NumPy, short for Numerical Python, has long been a cornerstone of numerical com‐
puting in Python. It provides the data structures, algorithms, and library glue needed
for most scientific applications involving numerical data in Python. NumPy contains,
among other things:
• A fast and efficient multidimensional array object ndarray
• Functions for performing element-wise computations with arrays or mathemati‐
cal operations between arrays
• Tools for reading and writing array-based datasets to disk
• Linear algebra operations, Fourier transform, and random number generation
• A mature C API to enable Python extensions and native C or C++ code to access
NumPy’s data structures and computational facilities
Beyond the fast array-processing capabilities that NumPy adds to Python, one of its
primary uses in data analysis is as a container for data to be passed between algo‐
rithms and libraries. For numerical data, NumPy arrays are more efficient for storing
and manipulating data than the other built-in Python data structures. Also, libraries
written in a lower-level language, such as C or Fortran, can operate on the data stored
in a NumPy array without copying data into some other memory representation.
Thus, many numerical computing tools for Python either assume NumPy arrays as a
primary data structure or else target seamless interoperability with NumPy.
pandas
pandas provides high-level data structures and functions designed to make working
with structured or tabular data fast, easy, and expressive. Since its emergence in 2010,
it has helped enable Python to be a powerful and productive data analysis environ‐
ment. The primary objects in pandas that will be used in this book are the DataFrame,
a tabular, column-oriented data structure with both row and column labels, and the
Series, a one-dimensional labeled array object.
pandas blends the high-performance, array-computing ideas of NumPy with the flex‐
ible data manipulation capabilities of spreadsheets and relational databases (such as
SQL). It provides sophisticated indexing functionality to make it easy to reshape, slice
and dice, perform aggregations, and select subsets of data. Since data manipulation,
4 | Chapter 1: Preliminaries
preparation, and cleaning is such an important skill in data analysis, pandas is one of
the primary focuses of this book.
As a bit of background, I started building pandas in early 2008 during my tenure at
AQR Capital Management, a quantitative investment management firm. At the time,
I had a distinct set of requirements that were not well addressed by any single tool at
my disposal:
• Data structures with labeled axes supporting automatic or explicit data alignment
—this prevents common errors resulting from misaligned data and working with
differently indexed data coming from different sources
• Integrated time series functionality
• The same data structures handle both time series data and non–time series data
• Arithmetic operations and reductions that preserve metadata
• Flexible handling of missing data
• Merge and other relational operations found in popular databases (SQL-based,
for example)
I wanted to be able to do all of these things in one place, preferably in a language well
suited to general-purpose software development. Python was a good candidate lan‐
guage for this, but at that time there was not an integrated set of data structures and
tools providing this functionality. As a result of having been built initially to solve
finance and business analytics problems, pandas features especially deep time series
functionality and tools well suited for working with time-indexed data generated by
business processes.
For users of the R language for statistical computing, the DataFrame name will be
familiar, as the object was named after the similar R data.frame object. Unlike
Python, data frames are built into the R programming language and its standard
library. As a result, many features found in pandas are typically either part of the R
core implementation or provided by add-on packages.
The pandas name itself is derived from panel data, an econometrics term for multidi‐
mensional structured datasets, and a play on the phrase Python data analysis itself.
matplotlib
matplotlib is the most popular Python library for producing plots and other two-
dimensional data visualizations. It was originally created by John D. Hunter and is
now maintained by a large team of developers. It is designed for creating plots suit‐
able for publication. While there are other visualization libraries available to Python
programmers, matplotlib is the most widely used and as such has generally good inte‐
1.3 Essential Python Libraries | 5
gration with the rest of the ecosystem. I think it is a safe choice as a default visualiza‐
tion tool.
IPython and Jupyter
The IPython project began in 2001 as Fernando Pérez’s side project to make a better
interactive Python interpreter. In the subsequent 16 years it has become one of the
most important tools in the modern Python data stack. While it does not provide any
computational or data analytical tools by itself, IPython is designed from the ground
up to maximize your productivity in both interactive computing and software devel‐
opment. It encourages an execute-explore workflow instead of the typical edit-compile-
run workflow of many other programming languages. It also provides easy access to
your operating system’s shell and filesystem. Since much of data analysis coding
involves exploration, trial and error, and iteration, IPython can help you get the job
done faster.
In 2014, Fernando and the IPython team announced the Jupyter project, a broader
initiative to design language-agnostic interactive computing tools. The IPython web
notebook became the Jupyter notebook, with support now for over 40 programming
languages. The IPython system can now be used as a kernel (a programming language
mode) for using Python with Jupyter.
IPython itself has become a component of the much broader Jupyter open source
project, which provides a productive environment for interactive and exploratory
computing. Its oldest and simplest “mode” is as an enhanced Python shell designed to
accelerate the writing, testing, and debugging of Python code. You can also use the
IPython system through the Jupyter Notebook, an interactive web-based code “note‐
book” offering support for dozens of programming languages. The IPython shell and
Jupyter notebooks are especially useful for data exploration and visualization.
The Jupyter notebook system also allows you to author content in Markdown and
HTML, providing you a means to create rich documents with code and text. Other
programming languages have also implemented kernels for Jupyter to enable you to
use languages other than Python in Jupyter.
For me personally, IPython is usually involved with the majority of my Python work,
including running, debugging, and testing code.
In the accompanying book materials, you will find Jupyter notebooks containing all
the code examples from each chapter.
SciPy
SciPy is a collection of packages addressing a number of different standard problem
domains in scientific computing. Here is a sampling of the packages included:
6 | Chapter 1: Preliminaries
scipy.integrate
Numerical integration routines and differential equation solvers
scipy.linalg
Linear algebra routines and matrix decompositions extending beyond those pro‐
vided in numpy.linalg
scipy.optimize
Function optimizers (minimizers) and root finding algorithms
scipy.signal
Signal processing tools
scipy.sparse
Sparse matrices and sparse linear system solvers
scipy.special
Wrapper around SPECFUN, a Fortran library implementing many common
mathematical functions, such as the gamma function
scipy.stats
Standard continuous and discrete probability distributions (density functions,
samplers, continuous distribution functions), various statistical tests, and more
descriptive statistics
Together NumPy and SciPy form a reasonably complete and mature computational
foundation for many traditional scientific computing applications.
scikit-learn
Since the project’s inception in 2010, scikit-learn has become the premier general-
purpose machine learning toolkit for Python programmers. In just seven years, it has
had over 1,500 contributors from around the world. It includes submodules for such
models as:
• Classification: SVM, nearest neighbors, random forest, logistic regression, etc.
• Regression: Lasso, ridge regression, etc.
• Clustering: k-means, spectral clustering, etc.
• Dimensionality reduction: PCA, feature selection, matrix factorization, etc.
• Model selection: Grid search, cross-validation, metrics
• Preprocessing: Feature extraction, normalization
Along with pandas, statsmodels, and IPython, scikit-learn has been critical for ena‐
bling Python to be a productive data science programming language. While I won’t
1.3 Essential Python Libraries | 7
be able to include a comprehensive guide to scikit-learn in this book, I will give a
brief introduction to some of its models and how to use them with the other tools
presented in the book.
statsmodels
statsmodels is a statistical analysis package that was seeded by work from Stanford
University statistics professor Jonathan Taylor, who implemented a number of regres‐
sion analysis models popular in the R programming language. Skipper Seabold and
Josef Perktold formally created the new statsmodels project in 2010 and since then
have grown the project to a critical mass of engaged users and contributors. Nathaniel
Smith developed the Patsy project, which provides a formula or model specification
framework for statsmodels inspired by R’s formula system.
Compared with scikit-learn, statsmodels contains algorithms for classical (primarily
frequentist) statistics and econometrics. This includes such submodules as:
• Regression models: Linear regression, generalized linear models, robust linear
models, linear mixed effects models, etc.
• Analysis of variance (ANOVA)
• Time series analysis: AR, ARMA, ARIMA, VAR, and other models
• Nonparametric methods: Kernel density estimation, kernel regression
• Visualization of statistical model results
statsmodels is more focused on statistical inference, providing uncertainty estimates
and p-values for parameters. scikit-learn, by contrast, is more prediction-focused.
As with scikit-learn, I will give a brief introduction to statsmodels and how to use it
with NumPy and pandas.
1.4 Installation and Setup
Since everyone uses Python for different applications, there is no single solution for
setting up Python and required add-on packages. Many readers will not have a com‐
plete Python development environment suitable for following along with this book,
so here I will give detailed instructions to get set up on each operating system. I rec‐
ommend using the free Anaconda distribution. At the time of this writing, Anaconda
is offered in both Python 2.7 and 3.6 forms, though this might change at some point
in the future. This book uses Python 3.6, and I encourage you to use Python 3.6 or
higher.
8 | Chapter 1: Preliminaries
Windows
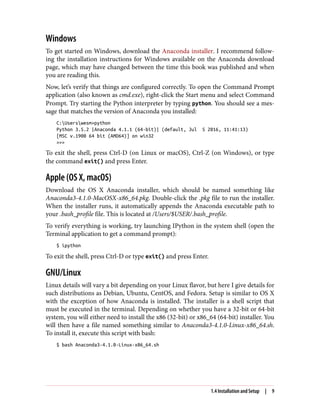
To get started on Windows, download the Anaconda installer. I recommend follow‐
ing the installation instructions for Windows available on the Anaconda download
page, which may have changed between the time this book was published and when
you are reading this.
Now, let’s verify that things are configured correctly. To open the Command Prompt
application (also known as cmd.exe), right-click the Start menu and select Command
Prompt. Try starting the Python interpreter by typing python. You should see a mes‐
sage that matches the version of Anaconda you installed:
C:Userswesm>python
Python 3.5.2 |Anaconda 4.1.1 (64-bit)| (default, Jul 5 2016, 11:41:13)
[MSC v.1900 64 bit (AMD64)] on win32
>>>
To exit the shell, press Ctrl-D (on Linux or macOS), Ctrl-Z (on Windows), or type
the command exit() and press Enter.
Apple (OS X, macOS)
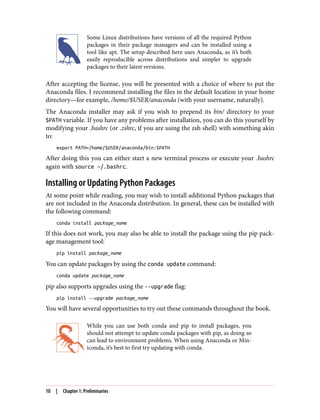
Download the OS X Anaconda installer, which should be named something like
Anaconda3-4.1.0-MacOSX-x86_64.pkg. Double-click the .pkg file to run the installer.
When the installer runs, it automatically appends the Anaconda executable path to
your .bash_profile file. This is located at /Users/$USER/.bash_profile.
To verify everything is working, try launching IPython in the system shell (open the
Terminal application to get a command prompt):
$ ipython
To exit the shell, press Ctrl-D or type exit() and press Enter.
GNU/Linux
Linux details will vary a bit depending on your Linux flavor, but here I give details for
such distributions as Debian, Ubuntu, CentOS, and Fedora. Setup is similar to OS X
with the exception of how Anaconda is installed. The installer is a shell script that
must be executed in the terminal. Depending on whether you have a 32-bit or 64-bit
system, you will either need to install the x86 (32-bit) or x86_64 (64-bit) installer. You
will then have a file named something similar to Anaconda3-4.1.0-Linux-x86_64.sh.
To install it, execute this script with bash:
$ bash Anaconda3-4.1.0-Linux-x86_64.sh
1.4 Installation and Setup | 9
Some Linux distributions have versions of all the required Python
packages in their package managers and can be installed using a
tool like apt. The setup described here uses Anaconda, as it’s both
easily reproducible across distributions and simpler to upgrade
packages to their latest versions.
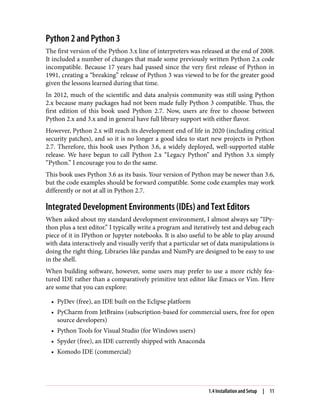
After accepting the license, you will be presented with a choice of where to put the
Anaconda files. I recommend installing the files in the default location in your home
directory—for example, /home/$USER/anaconda (with your username, naturally).
The Anaconda installer may ask if you wish to prepend its bin/ directory to your
$PATH variable. If you have any problems after installation, you can do this yourself by
modifying your .bashrc (or .zshrc, if you are using the zsh shell) with something akin
to:
export PATH=/home/$USER/anaconda/bin:$PATH
After doing this you can either start a new terminal process or execute your .bashrc
again with source ~/.bashrc.
Installing or Updating Python Packages
At some point while reading, you may wish to install additional Python packages that
are not included in the Anaconda distribution. In general, these can be installed with
the following command:
conda install package_name
If this does not work, you may also be able to install the package using the pip pack‐
age management tool:
pip install package_name
You can update packages by using the conda update command:
conda update package_name
pip also supports upgrades using the --upgrade flag:
pip install --upgrade package_name
You will have several opportunities to try out these commands throughout the book.
While you can use both conda and pip to install packages, you
should not attempt to update conda packages with pip, as doing so
can lead to environment problems. When using Anaconda or Min‐
iconda, it’s best to first try updating with conda.
10 | Chapter 1: Preliminaries
Python 2 and Python 3
The first version of the Python 3.x line of interpreters was released at the end of 2008.
It included a number of changes that made some previously written Python 2.x code
incompatible. Because 17 years had passed since the very first release of Python in
1991, creating a “breaking” release of Python 3 was viewed to be for the greater good
given the lessons learned during that time.
In 2012, much of the scientific and data analysis community was still using Python
2.x because many packages had not been made fully Python 3 compatible. Thus, the
first edition of this book used Python 2.7. Now, users are free to choose between
Python 2.x and 3.x and in general have full library support with either flavor.
However, Python 2.x will reach its development end of life in 2020 (including critical
security patches), and so it is no longer a good idea to start new projects in Python
2.7. Therefore, this book uses Python 3.6, a widely deployed, well-supported stable
release. We have begun to call Python 2.x “Legacy Python” and Python 3.x simply
“Python.” I encourage you to do the same.
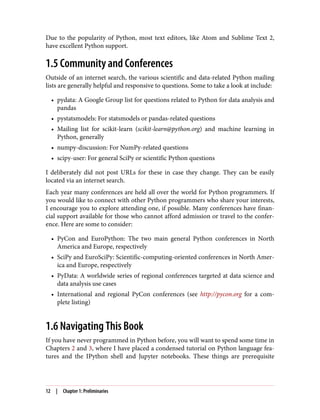
This book uses Python 3.6 as its basis. Your version of Python may be newer than 3.6,
but the code examples should be forward compatible. Some code examples may work
differently or not at all in Python 2.7.
Integrated Development Environments (IDEs) and Text Editors
When asked about my standard development environment, I almost always say “IPy‐
thon plus a text editor.” I typically write a program and iteratively test and debug each
piece of it in IPython or Jupyter notebooks. It is also useful to be able to play around
with data interactively and visually verify that a particular set of data manipulations is
doing the right thing. Libraries like pandas and NumPy are designed to be easy to use
in the shell.
When building software, however, some users may prefer to use a more richly fea‐
tured IDE rather than a comparatively primitive text editor like Emacs or Vim. Here
are some that you can explore:
• PyDev (free), an IDE built on the Eclipse platform
• PyCharm from JetBrains (subscription-based for commercial users, free for open
source developers)
• Python Tools for Visual Studio (for Windows users)
• Spyder (free), an IDE currently shipped with Anaconda
• Komodo IDE (commercial)
1.4 Installation and Setup | 11
Due to the popularity of Python, most text editors, like Atom and Sublime Text 2,
have excellent Python support.
1.5 Community and Conferences
Outside of an internet search, the various scientific and data-related Python mailing
lists are generally helpful and responsive to questions. Some to take a look at include:
• pydata: A Google Group list for questions related to Python for data analysis and
pandas
• pystatsmodels: For statsmodels or pandas-related questions
• Mailing list for scikit-learn (scikit-learn@python.org) and machine learning in
Python, generally
• numpy-discussion: For NumPy-related questions
• scipy-user: For general SciPy or scientific Python questions
I deliberately did not post URLs for these in case they change. They can be easily
located via an internet search.
Each year many conferences are held all over the world for Python programmers. If
you would like to connect with other Python programmers who share your interests,
I encourage you to explore attending one, if possible. Many conferences have finan‐
cial support available for those who cannot afford admission or travel to the confer‐
ence. Here are some to consider:
• PyCon and EuroPython: The two main general Python conferences in North
America and Europe, respectively
• SciPy and EuroSciPy: Scientific-computing-oriented conferences in North Amer‐
ica and Europe, respectively
• PyData: A worldwide series of regional conferences targeted at data science and
data analysis use cases
• International and regional PyCon conferences (see http://pycon.org for a com‐
plete listing)
1.6 Navigating This Book
If you have never programmed in Python before, you will want to spend some time in
Chapters 2 and 3, where I have placed a condensed tutorial on Python language fea‐
tures and the IPython shell and Jupyter notebooks. These things are prerequisite
12 | Chapter 1: Preliminaries
knowledge for the remainder of the book. If you have Python experience already, you
may instead choose to skim or skip these chapters.
Next, I give a short introduction to the key features of NumPy, leaving more
advanced NumPy use for Appendix A. Then, I introduce pandas and devote the rest
of the book to data analysis topics applying pandas, NumPy, and matplotlib (for visu‐
alization). I have structured the material in the most incremental way possible,
though there is occasionally some minor cross-over between chapters, with a few iso‐
lated cases where concepts are used that haven’t necessarily been introduced yet.
While readers may have many different end goals for their work, the tasks required
generally fall into a number of different broad groups:
Interacting with the outside world
Reading and writing with a variety of file formats and data stores
Preparation
Cleaning, munging, combining, normalizing, reshaping, slicing and dicing, and
transforming data for analysis
Transformation
Applying mathematical and statistical operations to groups of datasets to derive
new datasets (e.g., aggregating a large table by group variables)
Modeling and computation
Connecting your data to statistical models, machine learning algorithms, or other
computational tools
Presentation
Creating interactive or static graphical visualizations or textual summaries
Code Examples
Most of the code examples in the book are shown with input and output as it would
appear executed in the IPython shell or in Jupyter notebooks:
In [5]: CODE EXAMPLE
Out[5]: OUTPUT
When you see a code example like this, the intent is for you to type in the example
code in the In block in your coding environment and execute it by pressing the Enter
key (or Shift-Enter in Jupyter). You should see output similar to what is shown in the
Out block.
Data for Examples
Datasets for the examples in each chapter are hosted in a GitHub repository. You can
download this data either by using the Git version control system on the command
1.6 Navigating This Book | 13
line or by downloading a zip file of the repository from the website. If you run into
problems, navigate to my website for up-to-date instructions about obtaining the
book materials.
I have made every effort to ensure that it contains everything necessary to reproduce
the examples, but I may have made some mistakes or omissions. If so, please send me
an email: book@wesmckinney.com. The best way to report errors in the book is on the
errata page on the O’Reilly website.
Import Conventions
The Python community has adopted a number of naming conventions for commonly
used modules:
import numpy as np
import matplotlib.pyplot as plt
import pandas as pd
import seaborn as sns
import statsmodels as sm
This means that when you see np.arange, this is a reference to the arange function in
NumPy. This is done because it’s considered bad practice in Python software develop‐
ment to import everything (from numpy import *) from a large package like NumPy.
Jargon
I’ll use some terms common both to programming and data science that you may not
be familiar with. Thus, here are some brief definitions:
Munge/munging/wrangling
Describes the overall process of manipulating unstructured and/or messy data
into a structured or clean form. The word has snuck its way into the jargon of
many modern-day data hackers. “Munge” rhymes with “grunge.”
Pseudocode
A description of an algorithm or process that takes a code-like form while likely
not being actual valid source code.
Syntactic sugar
Programming syntax that does not add new features, but makes something more
convenient or easier to type.
14 | Chapter 1: Preliminaries
CHAPTER 2
Python Language Basics, IPython, and
Jupyter Notebooks
When I wrote the first edition of this book in 2011 and 2012, there were fewer resour‐
ces available for learning about doing data analysis in Python. This was partially a
chicken-and-egg problem; many libraries that we now take for granted, like pandas,
scikit-learn, and statsmodels, were comparatively immature back then. In 2017, there
is now a growing literature on data science, data analysis, and machine learning, sup‐
plementing the prior works on general-purpose scientific computing geared toward
computational scientists, physicists, and professionals in other research fields. There
are also excellent books about learning the Python programming language itself and
becoming an effective software engineer.
As this book is intended as an introductory text in working with data in Python, I feel
it is valuable to have a self-contained overview of some of the most important fea‐
tures of Python’s built-in data structures and libraries from the perspective of data
manipulation. So, I will only present roughly enough information in this chapter and
Chapter 3 to enable you to follow along with the rest of the book.
In my opinion, it is not necessary to become proficient at building good software in
Python to be able to productively do data analysis. I encourage you to use the IPy‐
thon shell and Jupyter notebooks to experiment with the code examples and to
explore the documentation for the various types, functions, and methods. While I’ve
made best efforts to present the book material in an incremental form, you may occa‐
sionally encounter things that have not yet been fully introduced.
Much of this book focuses on table-based analytics and data preparation tools for
working with large datasets. In order to use those tools you must often first do some
munging to corral messy data into a more nicely tabular (or structured) form. Fortu‐
nately, Python is an ideal language for rapidly whipping your data into shape. The
15
greater your facility with Python the language, the easier it will be for you to prepare
new datasets for analysis.
Some of the tools in this book are best explored from a live IPython or Jupyter ses‐
sion. Once you learn how to start up IPython and Jupyter, I recommend that you fol‐
low along with the examples so you can experiment and try different things. As with
any keyboard-driven console-like environment, developing muscle-memory for the
common commands is also part of the learning curve.
There are introductory Python concepts that this chapter does not
cover, like classes and object-oriented programming, which you
may find useful in your foray into data analysis in Python.
To deepen your Python language knowledge, I recommend that
you supplement this chapter with the official Python tutorial and
potentially one of the many excellent books on general-purpose
Python programming. Some recommendations to get you started
include:
• Python Cookbook, Third Edition, by David Beazley and Brian
K. Jones (O’Reilly)
• Fluent Python by Luciano Ramalho (O’Reilly)
• Effective Python by Brett Slatkin (Pearson)
2.1 The Python Interpreter
Python is an interpreted language. The Python interpreter runs a program by execut‐
ing one statement at a time. The standard interactive Python interpreter can be
invoked on the command line with the python command:
$ python
Python 3.6.0 | packaged by conda-forge | (default, Jan 13 2017, 23:17:12)
[GCC 4.8.2 20140120 (Red Hat 4.8.2-15)] on linux
Type "help", "copyright", "credits" or "license" for more information.
>>> a = 5
>>> print(a)
5
The >>> you see is the prompt where you’ll type code expressions. To exit the Python
interpreter and return to the command prompt, you can either type exit() or press
Ctrl-D.
Running Python programs is as simple as calling python with a .py file as its first
argument. Suppose we had created hello_world.py with these contents:
print('Hello world')
16 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
You can run it by executing the following command (the hello_world.py file must be
in your current working terminal directory):
$ python hello_world.py
Hello world
While some Python programmers execute all of their Python code in this way, those
doing data analysis or scientific computing make use of IPython, an enhanced Python
interpreter, or Jupyter notebooks, web-based code notebooks originally created
within the IPython project. I give an introduction to using IPython and Jupyter in
this chapter and have included a deeper look at IPython functionality in Appendix A.
When you use the %run command, IPython executes the code in the specified file in
the same process, enabling you to explore the results interactively when it’s done:
$ ipython
Python 3.6.0 | packaged by conda-forge | (default, Jan 13 2017, 23:17:12)
Type "copyright", "credits" or "license" for more information.
IPython 5.1.0 -- An enhanced Interactive Python.
? -> Introduction and overview of IPython's features.
%quickref -> Quick reference.
help -> Python's own help system.
object? -> Details about 'object', use 'object??' for extra details.
In [1]: %run hello_world.py
Hello world
In [2]:
The default IPython prompt adopts the numbered In [2]: style compared with the
standard >>> prompt.
2.2 IPython Basics
In this section, we’ll get you up and running with the IPython shell and Jupyter note‐
book, and introduce you to some of the essential concepts.
Running the IPython Shell
You can launch the IPython shell on the command line just like launching the regular
Python interpreter except with the ipython command:
$ ipython
Python 3.6.0 | packaged by conda-forge | (default, Jan 13 2017, 23:17:12)
Type "copyright", "credits" or "license" for more information.
IPython 5.1.0 -- An enhanced Interactive Python.
? -> Introduction and overview of IPython's features.
%quickref -> Quick reference.
help -> Python's own help system.
2.2 IPython Basics | 17
object? -> Details about 'object', use 'object??' for extra details.
In [1]: a = 5
In [2]: a
Out[2]: 5
You can execute arbitrary Python statements by typing them in and pressing Return
(or Enter). When you type just a variable into IPython, it renders a string representa‐
tion of the object:
In [5]: import numpy as np
In [6]: data = {i : np.random.randn() for i in range(7)}
In [7]: data
Out[7]:
{0: -0.20470765948471295,
1: 0.47894333805754824,
2: -0.5194387150567381,
3: -0.55573030434749,
4: 1.9657805725027142,
5: 1.3934058329729904,
6: 0.09290787674371767}
The first two lines are Python code statements; the second statement creates a vari‐
able named data that refers to a newly created Python dictionary. The last line prints
the value of data in the console.
Many kinds of Python objects are formatted to be more readable, or pretty-printed,
which is distinct from normal printing with print. If you printed the above data
variable in the standard Python interpreter, it would be much less readable:
>>> from numpy.random import randn
>>> data = {i : randn() for i in range(7)}
>>> print(data)
{0: -1.5948255432744511, 1: 0.10569006472787983, 2: 1.972367135977295,
3: 0.15455217573074576, 4: -0.24058577449429575, 5: -1.2904897053651216,
6: 0.3308507317325902}
IPython also provides facilities to execute arbitrary blocks of code (via a somewhat
glorified copy-and-paste approach) and whole Python scripts. You can also use the
Jupyter notebook to work with larger blocks of code, as we’ll soon see.
Running the Jupyter Notebook
One of the major components of the Jupyter project is the notebook, a type of interac‐
tive document for code, text (with or without markup), data visualizations, and other
output. The Jupyter notebook interacts with kernels, which are implementations of
18 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
the Jupyter interactive computing protocol in any number of programming lan‐
guages. Python’s Jupyter kernel uses the IPython system for its underlying behavior.
To start up Jupyter, run the command jupyter notebook in a terminal:
$ jupyter notebook
[I 15:20:52.739 NotebookApp] Serving notebooks from local directory:
/home/wesm/code/pydata-book
[I 15:20:52.739 NotebookApp] 0 active kernels
[I 15:20:52.739 NotebookApp] The Jupyter Notebook is running at:
http://localhost:8888/
[I 15:20:52.740 NotebookApp] Use Control-C to stop this server and shut down
all kernels (twice to skip confirmation).
Created new window in existing browser session.
On many platforms, Jupyter will automatically open up in your default web browser
(unless you start it with --no-browser). Otherwise, you can navigate to the HTTP
address printed when you started the notebook, here http://localhost:8888/. See
Figure 2-1 for what this looks like in Google Chrome.
Many people use Jupyter as a local computing environment, but it
can also be deployed on servers and accessed remotely. I won’t
cover those details here, but encourage you to explore this topic on
the internet if it’s relevant to your needs.
Figure 2-1. Jupyter notebook landing page
2.2 IPython Basics | 19
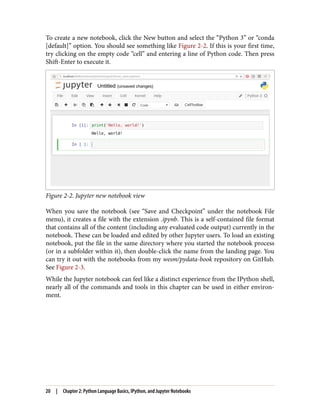
To create a new notebook, click the New button and select the “Python 3” or “conda
[default]” option. You should see something like Figure 2-2. If this is your first time,
try clicking on the empty code “cell” and entering a line of Python code. Then press
Shift-Enter to execute it.
Figure 2-2. Jupyter new notebook view
When you save the notebook (see “Save and Checkpoint” under the notebook File
menu), it creates a file with the extension .ipynb. This is a self-contained file format
that contains all of the content (including any evaluated code output) currently in the
notebook. These can be loaded and edited by other Jupyter users. To load an existing
notebook, put the file in the same directory where you started the notebook process
(or in a subfolder within it), then double-click the name from the landing page. You
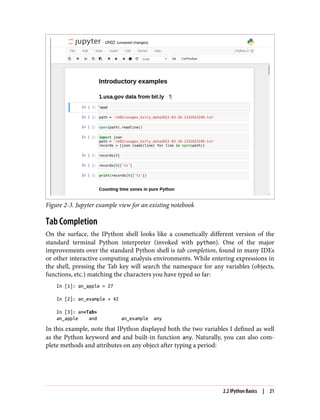
can try it out with the notebooks from my wesm/pydata-book repository on GitHub.
See Figure 2-3.
While the Jupyter notebook can feel like a distinct experience from the IPython shell,
nearly all of the commands and tools in this chapter can be used in either environ‐
ment.
20 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
Figure 2-3. Jupyter example view for an existing notebook
Tab Completion
On the surface, the IPython shell looks like a cosmetically different version of the
standard terminal Python interpreter (invoked with python). One of the major
improvements over the standard Python shell is tab completion, found in many IDEs
or other interactive computing analysis environments. While entering expressions in
the shell, pressing the Tab key will search the namespace for any variables (objects,
functions, etc.) matching the characters you have typed so far:
In [1]: an_apple = 27
In [2]: an_example = 42
In [3]: an<Tab>
an_apple and an_example any
In this example, note that IPython displayed both the two variables I defined as well
as the Python keyword and and built-in function any. Naturally, you can also com‐
plete methods and attributes on any object after typing a period:
2.2 IPython Basics | 21
In [3]: b = [1, 2, 3]
In [4]: b.<Tab>
b.append b.count b.insert b.reverse
b.clear b.extend b.pop b.sort
b.copy b.index b.remove
The same goes for modules:
In [1]: import datetime
In [2]: datetime.<Tab>
datetime.date datetime.MAXYEAR datetime.timedelta
datetime.datetime datetime.MINYEAR datetime.timezone
datetime.datetime_CAPI datetime.time datetime.tzinfo
In the Jupyter notebook and newer versions of IPython (5.0 and higher), the auto‐
completions show up in a drop-down box rather than as text output.
Note that IPython by default hides methods and attributes starting
with underscores, such as magic methods and internal “private”
methods and attributes, in order to avoid cluttering the display
(and confusing novice users!). These, too, can be tab-completed,
but you must first type an underscore to see them. If you prefer to
always see such methods in tab completion, you can change this
setting in the IPython configuration. See the IPython documenta‐
tion to find out how to do this.
Tab completion works in many contexts outside of searching the interactive name‐
space and completing object or module attributes. When typing anything that looks
like a file path (even in a Python string), pressing the Tab key will complete anything
on your computer’s filesystem matching what you’ve typed:
In [7]: datasets/movielens/<Tab>
datasets/movielens/movies.dat datasets/movielens/README
datasets/movielens/ratings.dat datasets/movielens/users.dat
In [7]: path = 'datasets/movielens/<Tab>
datasets/movielens/movies.dat datasets/movielens/README
datasets/movielens/ratings.dat datasets/movielens/users.dat
Combined with the %run command (see “The %run Command” on page 25), this
functionality can save you many keystrokes.
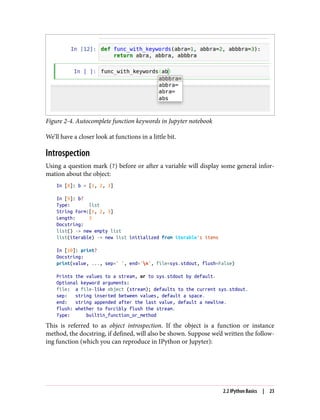
Another area where tab completion saves time is in the completion of function key‐
word arguments (and including the = sign!). See Figure 2-4.
22 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
Figure 2-4. Autocomplete function keywords in Jupyter notebook
We’ll have a closer look at functions in a little bit.
Introspection
Using a question mark (?) before or after a variable will display some general infor‐
mation about the object:
In [8]: b = [1, 2, 3]
In [9]: b?
Type: list
String Form:[1, 2, 3]
Length: 3
Docstring:
list() -> new empty list
list(iterable) -> new list initialized from iterable's items
In [10]: print?
Docstring:
print(value, ..., sep=' ', end='n', file=sys.stdout, flush=False)
Prints the values to a stream, or to sys.stdout by default.
Optional keyword arguments:
file: a file-like object (stream); defaults to the current sys.stdout.
sep: string inserted between values, default a space.
end: string appended after the last value, default a newline.
flush: whether to forcibly flush the stream.
Type: builtin_function_or_method
This is referred to as object introspection. If the object is a function or instance
method, the docstring, if defined, will also be shown. Suppose we’d written the follow‐
ing function (which you can reproduce in IPython or Jupyter):
2.2 IPython Basics | 23
def add_numbers(a, b):
"""
Add two numbers together
Returns
-------
the_sum : type of arguments
"""
return a + b
Then using ? shows us the docstring:
In [11]: add_numbers?
Signature: add_numbers(a, b)
Docstring:
Add two numbers together
Returns
-------
the_sum : type of arguments
File: <ipython-input-9-6a548a216e27>
Type: function
Using ?? will also show the function’s source code if possible:
In [12]: add_numbers??
Signature: add_numbers(a, b)
Source:
def add_numbers(a, b):
"""
Add two numbers together
Returns
-------
the_sum : type of arguments
"""
return a + b
File: <ipython-input-9-6a548a216e27>
Type: function
? has a final usage, which is for searching the IPython namespace in a manner similar
to the standard Unix or Windows command line. A number of characters combined
with the wildcard (*) will show all names matching the wildcard expression. For
example, we could get a list of all functions in the top-level NumPy namespace con‐
taining load:
In [13]: np.*load*?
np.__loader__
np.load
np.loads
np.loadtxt
np.pkgload
24 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
The %run Command
You can run any file as a Python program inside the environment of your IPython
session using the %run command. Suppose you had the following simple script stored
in ipython_script_test.py:
def f(x, y, z):
return (x + y) / z
a = 5
b = 6
c = 7.5
result = f(a, b, c)
You can execute this by passing the filename to %run:
In [14]: %run ipython_script_test.py
The script is run in an empty namespace (with no imports or other variables defined)
so that the behavior should be identical to running the program on the command line
using python script.py. All of the variables (imports, functions, and globals)
defined in the file (up until an exception, if any, is raised) will then be accessible in
the IPython shell:
In [15]: c
Out [15]: 7.5
In [16]: result
Out[16]: 1.4666666666666666
If a Python script expects command-line arguments (to be found in sys.argv), these
can be passed after the file path as though run on the command line.
Should you wish to give a script access to variables already defined
in the interactive IPython namespace, use %run -i instead of plain
%run.
In the Jupyter notebook, you may also use the related %load magic function, which
imports a script into a code cell:
>>> %load ipython_script_test.py
def f(x, y, z):
return (x + y) / z
a = 5
b = 6
c = 7.5
2.2 IPython Basics | 25
result = f(a, b, c)
Interrupting running code
Pressing Ctrl-C while any code is running, whether a script through %run or a long-
running command, will cause a KeyboardInterrupt to be raised. This will cause
nearly all Python programs to stop immediately except in certain unusual cases.
When a piece of Python code has called into some compiled exten‐
sion modules, pressing Ctrl-C will not always cause the program
execution to stop immediately. In such cases, you will have to
either wait until control is returned to the Python interpreter, or in
more dire circumstances, forcibly terminate the Python process.
Executing Code from the Clipboard
If you are using the Jupyter notebook, you can copy and paste code into any code cell
and execute it. It is also possible to run code from the clipboard in the IPython shell.
Suppose you had the following code in some other application:
x = 5
y = 7
if x > 5:
x += 1
y = 8
The most foolproof methods are the %paste and %cpaste magic functions. %paste
takes whatever text is in the clipboard and executes it as a single block in the shell:
In [17]: %paste
x = 5
y = 7
if x > 5:
x += 1
y = 8
## -- End pasted text --
%cpaste is similar, except that it gives you a special prompt for pasting code into:
In [18]: %cpaste
Pasting code; enter '--' alone on the line to stop or use Ctrl-D.
:x = 5
:y = 7
:if x > 5:
: x += 1
:
26 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
: y = 8
:--
With the %cpaste block, you have the freedom to paste as much code as you like
before executing it. You might decide to use %cpaste in order to look at the pasted
code before executing it. If you accidentally paste the wrong code, you can break out
of the %cpaste prompt by pressing Ctrl-C.
Terminal Keyboard Shortcuts
IPython has many keyboard shortcuts for navigating the prompt (which will be famil‐
iar to users of the Emacs text editor or the Unix bash shell) and interacting with the
shell’s command history. Table 2-1 summarizes some of the most commonly used
shortcuts. See Figure 2-5 for an illustration of a few of these, such as cursor
movement.
Figure 2-5. Illustration of some keyboard shortcuts in the IPython shell
Table 2-1. Standard IPython keyboard shortcuts
Keyboard shortcut Description
Ctrl-P or up-arrow Search backward in command history for commands starting with currently entered text
Ctrl-N or down-arrow Search forward in command history for commands starting with currently entered text
Ctrl-R Readline-style reverse history search (partial matching)
Ctrl-Shift-V Paste text from clipboard
Ctrl-C Interrupt currently executing code
Ctrl-A Move cursor to beginning of line
Ctrl-E Move cursor to end of line
Ctrl-K Delete text from cursor until end of line
Ctrl-U Discard all text on current line
Ctrl-F Move cursor forward one character
Ctrl-B Move cursor back one character
Ctrl-L Clear screen
Note that Jupyter notebooks have a largely separate set of keyboard shortcuts for nav‐
igation and editing. Since these shortcuts have evolved more rapidly than IPython’s, I
encourage you to explore the integrated help system in the Jupyter notebook’s menus.
2.2 IPython Basics | 27
About Magic Commands
IPython’s special commands (which are not built into Python itself) are known as
“magic” commands. These are designed to facilitate common tasks and enable you to
easily control the behavior of the IPython system. A magic command is any com‐
mand prefixed by the percent symbol %. For example, you can check the execution
time of any Python statement, such as a matrix multiplication, using the %timeit
magic function (which will be discussed in more detail later):
In [20]: a = np.random.randn(100, 100)
In [20]: %timeit np.dot(a, a)
10000 loops, best of 3: 20.9 µs per loop
Magic commands can be viewed as command-line programs to be run within the
IPython system. Many of them have additional “command-line” options, which can
all be viewed (as you might expect) using ?:
In [21]: %debug?
Docstring:
::
%debug [--breakpoint FILE:LINE] [statement [statement ...]]
Activate the interactive debugger.
This magic command support two ways of activating debugger.
One is to activate debugger before executing code. This way, you
can set a break point, to step through the code from the point.
You can use this mode by giving statements to execute and optionally
a breakpoint.
The other one is to activate debugger in post-mortem mode. You can
activate this mode simply running %debug without any argument.
If an exception has just occurred, this lets you inspect its stack
frames interactively. Note that this will always work only on the last
traceback that occurred, so you must call this quickly after an
exception that you wish to inspect has fired, because if another one
occurs, it clobbers the previous one.
If you want IPython to automatically do this on every exception, see
the %pdb magic for more details.
positional arguments:
statement Code to run in debugger. You can omit this in cell
magic mode.
optional arguments:
--breakpoint <FILE:LINE>, -b <FILE:LINE>
Set break point at LINE in FILE.
28 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
Magic functions can be used by default without the percent sign, as long as no vari‐
able is defined with the same name as the magic function in question. This feature is
called automagic and can be enabled or disabled with %automagic.
Some magic functions behave like Python functions and their output can be assigned
to a variable:
In [22]: %pwd
Out[22]: '/home/wesm/code/pydata-book
In [23]: foo = %pwd
In [24]: foo
Out[24]: '/home/wesm/code/pydata-book'
Since IPython’s documentation is accessible from within the system, I encourage you
to explore all of the special commands available by typing %quickref or %magic.
Table 2-2 highlights some of the most critical ones for being productive in interactive
computing and Python development in IPython.
Table 2-2. Some frequently used IPython magic commands
Command Description
%quickref Display the IPython Quick Reference Card
%magic Display detailed documentation for all of the available magic commands
%debug Enter the interactive debugger at the bottom of the last exception traceback
%hist Print command input (and optionally output) history
%pdb Automatically enter debugger after any exception
%paste Execute preformatted Python code from clipboard
%cpaste Open a special prompt for manually pasting Python code to be executed
%reset Delete all variables/names defined in interactive namespace
%page OBJECT Pretty-print the object and display it through a pager
%run script.py Run a Python script inside IPython
%prun statement Execute statement with cProfile and report the profiler output
%time statement Report the execution time of a single statement
%timeit statement Run a statement multiple times to compute an ensemble average execution time; useful for
timing code with very short execution time
%who, %who_ls, %whos Display variables defined in interactive namespace, with varying levels of information/
verbosity
%xdel variable Delete a variable and attempt to clear any references to the object in the IPython internals
Matplotlib Integration
One reason for IPython’s popularity in analytical computing is that it integrates well
with data visualization and other user interface libraries like matplotlib. Don’t worry
if you have never used matplotlib before; it will be discussed in more detail later in
2.2 IPython Basics | 29
this book. The %matplotlib magic function configures its integration with the IPy‐
thon shell or Jupyter notebook. This is important, as otherwise plots you create will
either not appear (notebook) or take control of the session until closed (shell).
In the IPython shell, running %matplotlib sets up the integration so you can create
multiple plot windows without interfering with the console session:
In [26]: %matplotlib
Using matplotlib backend: Qt4Agg
In Jupyter, the command is a little different (Figure 2-6):
In [26]: %matplotlib inline
Figure 2-6. Jupyter inline matplotlib plotting
2.3 Python Language Basics
In this section, I will give you an overview of essential Python programming concepts
and language mechanics. In the next chapter, I will go into more detail about Python’s
data structures, functions, and other built-in tools.
Language Semantics
The Python language design is distinguished by its emphasis on readability, simplic‐
ity, and explicitness. Some people go so far as to liken it to “executable pseudocode.”
Indentation, not braces
Python uses whitespace (tabs or spaces) to structure code instead of using braces as in
many other languages like R, C++, Java, and Perl. Consider a for loop from a sorting
algorithm:
30 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
for x in array:
if x < pivot:
less.append(x)
else:
greater.append(x)
A colon denotes the start of an indented code block after which all of the code must
be indented by the same amount until the end of the block.
Love it or hate it, significant whitespace is a fact of life for Python programmers, and
in my experience it can make Python code more readable than other languages I’ve
used. While it may seem foreign at first, you will hopefully grow accustomed in time.
I strongly recommend using four spaces as your default indentation
and replacing tabs with four spaces. Many text editors have a set‐
ting that will replace tab stops with spaces automatically (do this!).
Some people use tabs or a different number of spaces, with two
spaces not being terribly uncommon. By and large, four spaces is
the standard adopted by the vast majority of Python programmers,
so I recommend doing that in the absence of a compelling reason
otherwise.
As you can see by now, Python statements also do not need to be terminated by semi‐
colons. Semicolons can be used, however, to separate multiple statements on a single
line:
a = 5; b = 6; c = 7
Putting multiple statements on one line is generally discouraged in Python as it often
makes code less readable.
Everything is an object
An important characteristic of the Python language is the consistency of its object
model. Every number, string, data structure, function, class, module, and so on exists
in the Python interpreter in its own “box,” which is referred to as a Python object.
Each object has an associated type (e.g., string or function) and internal data. In prac‐
tice this makes the language very flexible, as even functions can be treated like any
other object.
Comments
Any text preceded by the hash mark (pound sign) # is ignored by the Python inter‐
preter. This is often used to add comments to code. At times you may also want to
exclude certain blocks of code without deleting them. An easy solution is to comment
out the code:
2.3 Python Language Basics | 31
results = []
for line in file_handle:
# keep the empty lines for now
# if len(line) == 0:
# continue
results.append(line.replace('foo', 'bar'))
Comments can also occur after a line of executed code. While some programmers
prefer comments to be placed in the line preceding a particular line of code, this can
be useful at times:
print("Reached this line") # Simple status report
Function and object method calls
You call functions using parentheses and passing zero or more arguments, optionally
assigning the returned value to a variable:
result = f(x, y, z)
g()
Almost every object in Python has attached functions, known as methods, that have
access to the object’s internal contents. You can call them using the following syntax:
obj.some_method(x, y, z)
Functions can take both positional and keyword arguments:
result = f(a, b, c, d=5, e='foo')
More on this later.
Variables and argument passing
When assigning a variable (or name) in Python, you are creating a reference to the
object on the righthand side of the equals sign. In practical terms, consider a list of
integers:
In [8]: a = [1, 2, 3]
Suppose we assign a to a new variable b:
In [9]: b = a
In some languages, this assignment would cause the data [1, 2, 3] to be copied. In
Python, a and b actually now refer to the same object, the original list [1, 2, 3] (see
Figure 2-7 for a mockup). You can prove this to yourself by appending an element to
a and then examining b:
In [10]: a.append(4)
In [11]: b
Out[11]: [1, 2, 3, 4]
32 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
Figure 2-7. Two references for the same object
Understanding the semantics of references in Python and when, how, and why data is
copied is especially critical when you are working with larger datasets in Python.
Assignment is also referred to as binding, as we are binding a name
to an object. Variable names that have been assigned may occasion‐
ally be referred to as bound variables.
When you pass objects as arguments to a function, new local variables are created ref‐
erencing the original objects without any copying. If you bind a new object to a vari‐
able inside a function, that change will not be reflected in the parent scope. It is
therefore possible to alter the internals of a mutable argument. Suppose we had the
following function:
def append_element(some_list, element):
some_list.append(element)
Then we have:
In [27]: data = [1, 2, 3]
In [28]: append_element(data, 4)
In [29]: data
Out[29]: [1, 2, 3, 4]
Dynamic references, strong types
In contrast with many compiled languages, such as Java and C++, object references in
Python have no type associated with them. There is no problem with the following:
In [12]: a = 5
In [13]: type(a)
Out[13]: int
In [14]: a = 'foo'
2.3 Python Language Basics | 33
In [15]: type(a)
Out[15]: str
Variables are names for objects within a particular namespace; the type information is
stored in the object itself. Some observers might hastily conclude that Python is not a
“typed language.” This is not true; consider this example:
In [16]: '5' + 5
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-16-f9dbf5f0b234> in <module>()
----> 1 '5' + 5
TypeError: must be str, not int
In some languages, such as Visual Basic, the string '5' might get implicitly converted
(or casted) to an integer, thus yielding 10. Yet in other languages, such as JavaScript,
the integer 5 might be casted to a string, yielding the concatenated string '55'. In this
regard Python is considered a strongly typed language, which means that every object
has a specific type (or class), and implicit conversions will occur only in certain obvi‐
ous circumstances, such as the following:
In [17]: a = 4.5
In [18]: b = 2
# String formatting, to be visited later
In [19]: print('a is {0}, b is {1}'.format(type(a), type(b)))
a is <class 'float'>, b is <class 'int'>
In [20]: a / b
Out[20]: 2.25
Knowing the type of an object is important, and it’s useful to be able to write func‐
tions that can handle many different kinds of input. You can check that an object is an
instance of a particular type using the isinstance function:
In [21]: a = 5
In [22]: isinstance(a, int)
Out[22]: True
isinstance can accept a tuple of types if you want to check that an object’s type is
among those present in the tuple:
In [23]: a = 5; b = 4.5
In [24]: isinstance(a, (int, float))
Out[24]: True
In [25]: isinstance(b, (int, float))
Out[25]: True
34 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
Attributes and methods
Objects in Python typically have both attributes (other Python objects stored “inside”
the object) and methods (functions associated with an object that can have access to
the object’s internal data). Both of them are accessed via the syntax
obj.attribute_name:
In [1]: a = 'foo'
In [2]: a.<Press Tab>
a.capitalize a.format a.isupper a.rindex a.strip
a.center a.index a.join a.rjust a.swapcase
a.count a.isalnum a.ljust a.rpartition a.title
a.decode a.isalpha a.lower a.rsplit a.translate
a.encode a.isdigit a.lstrip a.rstrip a.upper
a.endswith a.islower a.partition a.split a.zfill
a.expandtabs a.isspace a.replace a.splitlines
a.find a.istitle a.rfind a.startswith
Attributes and methods can also be accessed by name via the getattr function:
In [27]: getattr(a, 'split')
Out[27]: <function str.split>
In other languages, accessing objects by name is often referred to as “reflection.”
While we will not extensively use the functions getattr and related functions
hasattr and setattr in this book, they can be used very effectively to write generic,
reusable code.
Duck typing
Often you may not care about the type of an object but rather only whether it has
certain methods or behavior. This is sometimes called “duck typing,” after the saying
“If it walks like a duck and quacks like a duck, then it’s a duck.” For example, you can
verify that an object is iterable if it implemented the iterator protocol. For many
objects, this means it has a __iter__ “magic method,” though an alternative and bet‐
ter way to check is to try using the iter function:
def isiterable(obj):
try:
iter(obj)
return True
except TypeError: # not iterable
return False
This function would return True for strings as well as most Python collection types:
In [29]: isiterable('a string')
Out[29]: True
In [30]: isiterable([1, 2, 3])
2.3 Python Language Basics | 35
Out[30]: True
In [31]: isiterable(5)
Out[31]: False
A place where I use this functionality all the time is to write functions that can accept
multiple kinds of input. A common case is writing a function that can accept any
kind of sequence (list, tuple, ndarray) or even an iterator. You can first check if the
object is a list (or a NumPy array) and, if it is not, convert it to be one:
if not isinstance(x, list) and isiterable(x):
x = list(x)
Imports
In Python a module is simply a file with the .py extension containing Python code.
Suppose that we had the following module:
# some_module.py
PI = 3.14159
def f(x):
return x + 2
def g(a, b):
return a + b
If we wanted to access the variables and functions defined in some_module.py, from
another file in the same directory we could do:
import some_module
result = some_module.f(5)
pi = some_module.PI
Or equivalently:
from some_module import f, g, PI
result = g(5, PI)
By using the as keyword you can give imports different variable names:
import some_module as sm
from some_module import PI as pi, g as gf
r1 = sm.f(pi)
r2 = gf(6, pi)
Binary operators and comparisons
Most of the binary math operations and comparisons are as you might expect:
In [32]: 5 - 7
Out[32]: -2
36 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
In [33]: 12 + 21.5
Out[33]: 33.5
In [34]: 5 <= 2
Out[34]: False
See Table 2-3 for all of the available binary operators.
To check if two references refer to the same object, use the is keyword. is not is also
perfectly valid if you want to check that two objects are not the same:
In [35]: a = [1, 2, 3]
In [36]: b = a
In [37]: c = list(a)
In [38]: a is b
Out[38]: True
In [39]: a is not c
Out[39]: True
Since list always creates a new Python list (i.e., a copy), we can be sure that c is dis‐
tinct from a. Comparing with is is not the same as the == operator, because in this
case we have:
In [40]: a == c
Out[40]: True
A very common use of is and is not is to check if a variable is None, since there is
only one instance of None:
In [41]: a = None
In [42]: a is None
Out[42]: True
Table 2-3. Binary operators
Operation Description
a + b Add a and b
a - b Subtract b from a
a * b Multiply a by b
a / b Divide a by b
a // b Floor-divide a by b, dropping any fractional remainder
a ** b Raise a to the b power
a & b True if both a and b are True; for integers, take the bitwise AND
a | b True if either a or b is True; for integers, take the bitwise OR
a ^ b For booleans, True if a or b is True, but not both; for integers, take the bitwise EXCLUSIVE-OR
2.3 Python Language Basics | 37
Operation Description
a == b True if a equals b
a != b True if a is not equal to b
a <= b, a < b True if a is less than (less than or equal) to b
a > b, a >= b True if a is greater than (greater than or equal) to b
a is b True if a and b reference the same Python object
a is not b True if a and b reference different Python objects
Mutable and immutable objects
Most objects in Python, such as lists, dicts, NumPy arrays, and most user-defined
types (classes), are mutable. This means that the object or values that they contain can
be modified:
In [43]: a_list = ['foo', 2, [4, 5]]
In [44]: a_list[2] = (3, 4)
In [45]: a_list
Out[45]: ['foo', 2, (3, 4)]
Others, like strings and tuples, are immutable:
In [46]: a_tuple = (3, 5, (4, 5))
In [47]: a_tuple[1] = 'four'
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-47-b7966a9ae0f1> in <module>()
----> 1 a_tuple[1] = 'four'
TypeError: 'tuple' object does not support item assignment
Remember that just because you can mutate an object does not mean that you always
should. Such actions are known as side effects. For example, when writing a function,
any side effects should be explicitly communicated to the user in the function’s docu‐
mentation or comments. If possible, I recommend trying to avoid side effects and
favor immutability, even though there may be mutable objects involved.
Scalar Types
Python along with its standard library has a small set of built-in types for handling
numerical data, strings, boolean (True or False) values, and dates and time. These
“single value” types are sometimes called scalar types and we refer to them in this
book as scalars. See Table 2-4 for a list of the main scalar types. Date and time han‐
dling will be discussed separately, as these are provided by the datetime module in
the standard library.
38 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
Table 2-4. Standard Python scalar types
Type Description
None The Python “null” value (only one instance of the None object exists)
str String type; holds Unicode (UTF-8 encoded) strings
bytes Raw ASCII bytes (or Unicode encoded as bytes)
float Double-precision (64-bit) floating-point number (note there is no separate double type)
bool A True or False value
int Arbitrary precision signed integer
Numeric types
The primary Python types for numbers are int and float. An int can store arbitrar‐
ily large numbers:
In [48]: ival = 17239871
In [49]: ival ** 6
Out[49]: 26254519291092456596965462913230729701102721
Floating-point numbers are represented with the Python float type. Under the hood
each one is a double-precision (64-bit) value. They can also be expressed with scien‐
tific notation:
In [50]: fval = 7.243
In [51]: fval2 = 6.78e-5
Integer division not resulting in a whole number will always yield a floating-point
number:
In [52]: 3 / 2
Out[52]: 1.5
To get C-style integer division (which drops the fractional part if the result is not a
whole number), use the floor division operator //:
In [53]: 3 // 2
Out[53]: 1
Strings
Many people use Python for its powerful and flexible built-in string processing capa‐
bilities. You can write string literals using either single quotes ' or double quotes ":
a = 'one way of writing a string'
b = "another way"
For multiline strings with line breaks, you can use triple quotes, either ''' or """:
2.3 Python Language Basics | 39
c = """
This is a longer string that
spans multiple lines
"""
It may surprise you that this string c actually contains four lines of text; the line
breaks after """ and after lines are included in the string. We can count the new line
characters with the count method on c:
In [55]: c.count('n')
Out[55]: 3
Python strings are immutable; you cannot modify a string:
In [56]: a = 'this is a string'
In [57]: a[10] = 'f'
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-57-5ca625d1e504> in <module>()
----> 1 a[10] = 'f'
TypeError: 'str' object does not support item assignment
In [58]: b = a.replace('string', 'longer string')
In [59]: b
Out[59]: 'this is a longer string'
Afer this operation, the variable a is unmodified:
In [60]: a
Out[60]: 'this is a string'
Many Python objects can be converted to a string using the str function:
In [61]: a = 5.6
In [62]: s = str(a)
In [63]: print(s)
5.6
Strings are a sequence of Unicode characters and therefore can be treated like other
sequences, such as lists and tuples (which we will explore in more detail in the next
chapter):
In [64]: s = 'python'
In [65]: list(s)
Out[65]: ['p', 'y', 't', 'h', 'o', 'n']
In [66]: s[:3]
Out[66]: 'pyt'
40 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
The syntax s[:3] is called slicing and is implemented for many kinds of Python
sequences. This will be explained in more detail later on, as it is used extensively in
this book.
The backslash character  is an escape character, meaning that it is used to specify
special characters like newline n or Unicode characters. To write a string literal with
backslashes, you need to escape them:
In [67]: s = '1234'
In [68]: print(s)
1234
If you have a string with a lot of backslashes and no special characters, you might find
this a bit annoying. Fortunately you can preface the leading quote of the string with r,
which means that the characters should be interpreted as is:
In [69]: s = r'thishasnospecialcharacters'
In [70]: s
Out[70]: 'thishasnospecialcharacters'
The r stands for raw.
Adding two strings together concatenates them and produces a new string:
In [71]: a = 'this is the first half '
In [72]: b = 'and this is the second half'
In [73]: a + b
Out[73]: 'this is the first half and this is the second half'
String templating or formatting is another important topic. The number of ways to
do so has expanded with the advent of Python 3, and here I will briefly describe the
mechanics of one of the main interfaces. String objects have a format method that
can be used to substitute formatted arguments into the string, producing a new
string:
In [74]: template = '{0:.2f} {1:s} are worth US${2:d}'
In this string,
• {0:.2f} means to format the first argument as a floating-point number with two
decimal places.
• {1:s} means to format the second argument as a string.
• {2:d} means to format the third argument as an exact integer.
To substitute arguments for these format parameters, we pass a sequence of argu‐
ments to the format method:
2.3 Python Language Basics | 41
In [75]: template.format(4.5560, 'Argentine Pesos', 1)
Out[75]: '4.56 Argentine Pesos are worth US$1'
String formatting is a deep topic; there are multiple methods and numerous options
and tweaks available to control how values are formatted in the resulting string. To
learn more, I recommend consulting the official Python documentation.
I discuss general string processing as it relates to data analysis in more detail in Chap‐
ter 8.
Bytes and Unicode
In modern Python (i.e., Python 3.0 and up), Unicode has become the first-class string
type to enable more consistent handling of ASCII and non-ASCII text. In older ver‐
sions of Python, strings were all bytes without any explicit Unicode encoding. You
could convert to Unicode assuming you knew the character encoding. Let’s look at an
example:
In [76]: val = "español"
In [77]: val
Out[77]: 'español'
We can convert this Unicode string to its UTF-8 bytes representation using the
encode method:
In [78]: val_utf8 = val.encode('utf-8')
In [79]: val_utf8
Out[79]: b'espaxc3xb1ol'
In [80]: type(val_utf8)
Out[80]: bytes
Assuming you know the Unicode encoding of a bytes object, you can go back using
the decode method:
In [81]: val_utf8.decode('utf-8')
Out[81]: 'español'
While it’s become preferred to use UTF-8 for any encoding, for historical reasons you
may encounter data in any number of different encodings:
In [82]: val.encode('latin1')
Out[82]: b'espaxf1ol'
In [83]: val.encode('utf-16')
Out[83]: b'xffxfeex00sx00px00ax00xf1x00ox00lx00'
In [84]: val.encode('utf-16le')
Out[84]: b'ex00sx00px00ax00xf1x00ox00lx00'
42 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
It is most common to encounter bytes objects in the context of working with files,
where implicitly decoding all data to Unicode strings may not be desired.
Though you may seldom need to do so, you can define your own byte literals by pre‐
fixing a string with b:
In [85]: bytes_val = b'this is bytes'
In [86]: bytes_val
Out[86]: b'this is bytes'
In [87]: decoded = bytes_val.decode('utf8')
In [88]: decoded # this is str (Unicode) now
Out[88]: 'this is bytes'
Booleans
The two boolean values in Python are written as True and False. Comparisons and
other conditional expressions evaluate to either True or False. Boolean values are
combined with the and and or keywords:
In [89]: True and True
Out[89]: True
In [90]: False or True
Out[90]: True
Type casting
The str, bool, int, and float types are also functions that can be used to cast values
to those types:
In [91]: s = '3.14159'
In [92]: fval = float(s)
In [93]: type(fval)
Out[93]: float
In [94]: int(fval)
Out[94]: 3
In [95]: bool(fval)
Out[95]: True
In [96]: bool(0)
Out[96]: False
2.3 Python Language Basics | 43
None
None is the Python null value type. If a function does not explicitly return a value, it
implicitly returns None:
In [97]: a = None
In [98]: a is None
Out[98]: True
In [99]: b = 5
In [100]: b is not None
Out[100]: True
None is also a common default value for function arguments:
def add_and_maybe_multiply(a, b, c=None):
result = a + b
if c is not None:
result = result * c
return result
While a technical point, it’s worth bearing in mind that None is not only a reserved
keyword but also a unique instance of NoneType:
In [101]: type(None)
Out[101]: NoneType
Dates and times
The built-in Python datetime module provides datetime, date, and time types. The
datetime type, as you may imagine, combines the information stored in date and
time and is the most commonly used:
In [102]: from datetime import datetime, date, time
In [103]: dt = datetime(2011, 10, 29, 20, 30, 21)
In [104]: dt.day
Out[104]: 29
In [105]: dt.minute
Out[105]: 30
Given a datetime instance, you can extract the equivalent date and time objects by
calling methods on the datetime of the same name:
In [106]: dt.date()
Out[106]: datetime.date(2011, 10, 29)
44 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
In [107]: dt.time()
Out[107]: datetime.time(20, 30, 21)
The strftime method formats a datetime as a string:
In [108]: dt.strftime('%m/%d/%Y %H:%M')
Out[108]: '10/29/2011 20:30'
Strings can be converted (parsed) into datetime objects with the strptime function:
In [109]: datetime.strptime('20091031', '%Y%m%d')
Out[109]: datetime.datetime(2009, 10, 31, 0, 0)
See Table 2-5 for a full list of format specifications.
When you are aggregating or otherwise grouping time series data, it will occasionally
be useful to replace time fields of a series of datetimes—for example, replacing the
minute and second fields with zero:
In [110]: dt.replace(minute=0, second=0)
Out[110]: datetime.datetime(2011, 10, 29, 20, 0)
Since datetime.datetime is an immutable type, methods like these always produce
new objects.
The difference of two datetime objects produces a datetime.timedelta type:
In [111]: dt2 = datetime(2011, 11, 15, 22, 30)
In [112]: delta = dt2 - dt
In [113]: delta
Out[113]: datetime.timedelta(17, 7179)
In [114]: type(delta)
Out[114]: datetime.timedelta
The output timedelta(17, 7179) indicates that the timedelta encodes an offset of 17
days and 7,179 seconds.
Adding a timedelta to a datetime produces a new shifted datetime:
In [115]: dt
Out[115]: datetime.datetime(2011, 10, 29, 20, 30, 21)
In [116]: dt + delta
Out[116]: datetime.datetime(2011, 11, 15, 22, 30)
Table 2-5. Datetime format specification (ISO C89 compatible)
Type Description
%Y Four-digit year
%y Two-digit year
2.3 Python Language Basics | 45
Type Description
%m Two-digit month [01, 12]
%d Two-digit day [01, 31]
%H Hour (24-hour clock) [00, 23]
%I Hour (12-hour clock) [01, 12]
%M Two-digit minute [00, 59]
%S Second [00, 61] (seconds 60, 61 account for leap seconds)
%w Weekday as integer [0 (Sunday), 6]
%U Week number of the year [00, 53]; Sunday is considered the first day of the week, and days before the first Sunday of
the year are “week 0”
%W Week number of the year [00, 53]; Monday is considered the first day of the week, and days before the first Monday of
the year are “week 0”
%z UTC time zone offset as +HHMM or -HHMM; empty if time zone naive
%F Shortcut for %Y-%m-%d (e.g., 2012-4-18)
%D Shortcut for %m/%d/%y (e.g., 04/18/12)
Control Flow
Python has several built-in keywords for conditional logic, loops, and other standard
control flow concepts found in other programming languages.
if, elif, and else
The if statement is one of the most well-known control flow statement types. It
checks a condition that, if True, evaluates the code in the block that follows:
if x < 0:
print('It's negative')
An if statement can be optionally followed by one or more elif blocks and a catch-
all else block if all of the conditions are False:
if x < 0:
print('It's negative')
elif x == 0:
print('Equal to zero')
elif 0 < x < 5:
print('Positive but smaller than 5')
else:
print('Positive and larger than or equal to 5')
If any of the conditions is True, no further elif or else blocks will be reached. With
a compound condition using and or or, conditions are evaluated left to right and will
short-circuit:
In [117]: a = 5; b = 7
In [118]: c = 8; d = 4
46 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
In [119]: if a < b or c > d:
.....: print('Made it')
Made it
In this example, the comparison c > d never gets evaluated because the first compar‐
ison was True.
It is also possible to chain comparisons:
In [120]: 4 > 3 > 2 > 1
Out[120]: True
for loops
for loops are for iterating over a collection (like a list or tuple) or an iterater. The
standard syntax for a for loop is:
for value in collection:
# do something with value
You can advance a for loop to the next iteration, skipping the remainder of the block,
using the continue keyword. Consider this code, which sums up integers in a list and
skips None values:
sequence = [1, 2, None, 4, None, 5]
total = 0
for value in sequence:
if value is None:
continue
total += value
A for loop can be exited altogether with the break keyword. This code sums ele‐
ments of the list until a 5 is reached:
sequence = [1, 2, 0, 4, 6, 5, 2, 1]
total_until_5 = 0
for value in sequence:
if value == 5:
break
total_until_5 += value
The break keyword only terminates the innermost for loop; any outer for loops will
continue to run:
In [121]: for i in range(4):
.....: for j in range(4):
.....: if j > i:
.....: break
.....: print((i, j))
.....:
(0, 0)
(1, 0)
2.3 Python Language Basics | 47
(1, 1)
(2, 0)
(2, 1)
(2, 2)
(3, 0)
(3, 1)
(3, 2)
(3, 3)
As we will see in more detail, if the elements in the collection or iterator are sequen‐
ces (tuples or lists, say), they can be conveniently unpacked into variables in the for
loop statement:
for a, b, c in iterator:
# do something
while loops
A while loop specifies a condition and a block of code that is to be executed until the
condition evaluates to False or the loop is explicitly ended with break:
x = 256
total = 0
while x > 0:
if total > 500:
break
total += x
x = x // 2
pass
pass is the “no-op” statement in Python. It can be used in blocks where no action is to
be taken (or as a placeholder for code not yet implemented); it is only required
because Python uses whitespace to delimit blocks:
if x < 0:
print('negative!')
elif x == 0:
# TODO: put something smart here
pass
else:
print('positive!')
range
The range function returns an iterator that yields a sequence of evenly spaced
integers:
In [122]: range(10)
Out[122]: range(0, 10)
48 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
In [123]: list(range(10))
Out[123]: [0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
Both a start, end, and step (which may be negative) can be given:
In [124]: list(range(0, 20, 2))
Out[124]: [0, 2, 4, 6, 8, 10, 12, 14, 16, 18]
In [125]: list(range(5, 0, -1))
Out[125]: [5, 4, 3, 2, 1]
As you can see, range produces integers up to but not including the endpoint. A
common use of range is for iterating through sequences by index:
seq = [1, 2, 3, 4]
for i in range(len(seq)):
val = seq[i]
While you can use functions like list to store all the integers generated by range in
some other data structure, often the default iterator form will be what you want. This
snippet sums all numbers from 0 to 99,999 that are multiples of 3 or 5:
sum = 0
for i in range(100000):
# % is the modulo operator
if i % 3 == 0 or i % 5 == 0:
sum += i
While the range generated can be arbitrarily large, the memory use at any given time
may be very small.
Ternary expressions
A ternary expression in Python allows you to combine an if-else block that pro‐
duces a value into a single line or expression. The syntax for this in Python is:
value = true-expr if condition else false-expr
Here, true-expr and false-expr can be any Python expressions. It has the identical
effect as the more verbose:
if condition:
value = true-expr
else:
value = false-expr
This is a more concrete example:
In [126]: x = 5
In [127]: 'Non-negative' if x >= 0 else 'Negative'
Out[127]: 'Non-negative'
2.3 Python Language Basics | 49
As with if-else blocks, only one of the expressions will be executed. Thus, the “if”
and “else” sides of the ternary expression could contain costly computations, but only
the true branch is ever evaluated.
While it may be tempting to always use ternary expressions to condense your code,
realize that you may sacrifice readability if the condition as well as the true and false
expressions are very complex.
50 | Chapter 2: Python Language Basics, IPython, and Jupyter Notebooks
CHAPTER 3
Built-in Data Structures, Functions,
and Files
This chapter discusses capabilities built into the Python language that will be used
ubiquitously throughout the book. While add-on libraries like pandas and NumPy
add advanced computational functionality for larger datasets, they are designed to be
used together with Python’s built-in data manipulation tools.
We’ll start with Python’s workhorse data structures: tuples, lists, dicts, and sets. Then,
we’ll discuss creating your own reusable Python functions. Finally, we’ll look at the
mechanics of Python file objects and interacting with your local hard drive.
3.1 Data Structures and Sequences
Python’s data structures are simple but powerful. Mastering their use is a critical part
of becoming a proficient Python programmer.
Tuple
A tuple is a fixed-length, immutable sequence of Python objects. The easiest way to
create one is with a comma-separated sequence of values:
In [1]: tup = 4, 5, 6
In [2]: tup
Out[2]: (4, 5, 6)
When you’re defining tuples in more complicated expressions, it’s often necessary to
enclose the values in parentheses, as in this example of creating a tuple of tuples:
51
In [3]: nested_tup = (4, 5, 6), (7, 8)
In [4]: nested_tup
Out[4]: ((4, 5, 6), (7, 8))
You can convert any sequence or iterator to a tuple by invoking tuple:
In [5]: tuple([4, 0, 2])
Out[5]: (4, 0, 2)
In [6]: tup = tuple('string')
In [7]: tup
Out[7]: ('s', 't', 'r', 'i', 'n', 'g')
Elements can be accessed with square brackets [] as with most other sequence types.
As in C, C++, Java, and many other languages, sequences are 0-indexed in Python:
In [8]: tup[0]
Out[8]: 's'
While the objects stored in a tuple may be mutable themselves, once the tuple is cre‐
ated it’s not possible to modify which object is stored in each slot:
In [9]: tup = tuple(['foo', [1, 2], True])
In [10]: tup[2] = False
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-10-c7308343b841> in <module>()
----> 1 tup[2] = False
TypeError: 'tuple' object does not support item assignment
If an object inside a tuple is mutable, such as a list, you can modify it in-place:
In [11]: tup[1].append(3)
In [12]: tup
Out[12]: ('foo', [1, 2, 3], True)
You can concatenate tuples using the + operator to produce longer tuples:
In [13]: (4, None, 'foo') + (6, 0) + ('bar',)
Out[13]: (4, None, 'foo', 6, 0, 'bar')
Multiplying a tuple by an integer, as with lists, has the effect of concatenating together
that many copies of the tuple:
In [14]: ('foo', 'bar') * 4
Out[14]: ('foo', 'bar', 'foo', 'bar', 'foo', 'bar', 'foo', 'bar')
Note that the objects themselves are not copied, only the references to them.
52 | Chapter 3: Built-in Data Structures, Functions, and Files
Unpacking tuples
If you try to assign to a tuple-like expression of variables, Python will attempt to
unpack the value on the righthand side of the equals sign:
In [15]: tup = (4, 5, 6)
In [16]: a, b, c = tup
In [17]: b
Out[17]: 5
Even sequences with nested tuples can be unpacked:
In [18]: tup = 4, 5, (6, 7)
In [19]: a, b, (c, d) = tup
In [20]: d
Out[20]: 7
Using this functionality you can easily swap variable names, a task which in many
languages might look like:
tmp = a
a = b
b = tmp
But, in Python, the swap can be done like this:
In [21]: a, b = 1, 2
In [22]: a
Out[22]: 1
In [23]: b
Out[23]: 2
In [24]: b, a = a, b
In [25]: a
Out[25]: 2
In [26]: b
Out[26]: 1
A common use of variable unpacking is iterating over sequences of tuples or lists:
In [27]: seq = [(1, 2, 3), (4, 5, 6), (7, 8, 9)]
In [28]: for a, b, c in seq:
....: print('a={0}, b={1}, c={2}'.format(a, b, c))
a=1, b=2, c=3
a=4, b=5, c=6
a=7, b=8, c=9
3.1 Data Structures and Sequences | 53
Another common use is returning multiple values from a function. I’ll cover this in
more detail later.
The Python language recently acquired some more advanced tuple unpacking to help
with situations where you may want to “pluck” a few elements from the beginning of
a tuple. This uses the special syntax *rest, which is also used in function signatures
to capture an arbitrarily long list of positional arguments:
In [29]: values = 1, 2, 3, 4, 5
In [30]: a, b, *rest = values
In [31]: a, b
Out[31]: (1, 2)
In [32]: rest
Out[32]: [3, 4, 5]
This rest bit is sometimes something you want to discard; there is nothing special
about the rest name. As a matter of convention, many Python programmers will use
the underscore (_) for unwanted variables:
In [33]: a, b, *_ = values
Tuple methods
Since the size and contents of a tuple cannot be modified, it is very light on instance
methods. A particularly useful one (also available on lists) is count, which counts the
number of occurrences of a value:
In [34]: a = (1, 2, 2, 2, 3, 4, 2)
In [35]: a.count(2)
Out[35]: 4
List
In contrast with tuples, lists are variable-length and their contents can be modified
in-place. You can define them using square brackets [] or using the list type func‐
tion:
In [36]: a_list = [2, 3, 7, None]
In [37]: tup = ('foo', 'bar', 'baz')
In [38]: b_list = list(tup)
In [39]: b_list
Out[39]: ['foo', 'bar', 'baz']
In [40]: b_list[1] = 'peekaboo'
54 | Chapter 3: Built-in Data Structures, Functions, and Files
In [41]: b_list
Out[41]: ['foo', 'peekaboo', 'baz']
Lists and tuples are semantically similar (though tuples cannot be modified) and can
be used interchangeably in many functions.
The list function is frequently used in data processing as a way to materialize an
iterator or generator expression:
In [42]: gen = range(10)
In [43]: gen
Out[43]: range(0, 10)
In [44]: list(gen)
Out[44]: [0, 1, 2, 3, 4, 5, 6, 7, 8, 9]
Adding and removing elements
Elements can be appended to the end of the list with the append method:
In [45]: b_list.append('dwarf')
In [46]: b_list
Out[46]: ['foo', 'peekaboo', 'baz', 'dwarf']
Using insert you can insert an element at a specific location in the list:
In [47]: b_list.insert(1, 'red')
In [48]: b_list
Out[48]: ['foo', 'red', 'peekaboo', 'baz', 'dwarf']
The insertion index must be between 0 and the length of the list, inclusive.
insert is computationally expensive compared with append,
because references to subsequent elements have to be shifted inter‐
nally to make room for the new element. If you need to insert ele‐
ments at both the beginning and end of a sequence, you may wish
to explore collections.deque, a double-ended queue, for this pur‐
pose.
The inverse operation to insert is pop, which removes and returns an element at a
particular index:
In [49]: b_list.pop(2)
Out[49]: 'peekaboo'
In [50]: b_list
Out[50]: ['foo', 'red', 'baz', 'dwarf']
3.1 Data Structures and Sequences | 55
Elements can be removed by value with remove, which locates the first such value and
removes it from the last:
In [51]: b_list.append('foo')
In [52]: b_list
Out[52]: ['foo', 'red', 'baz', 'dwarf', 'foo']
In [53]: b_list.remove('foo')
In [54]: b_list
Out[54]: ['red', 'baz', 'dwarf', 'foo']
If performance is not a concern, by using append and remove, you can use a Python
list as a perfectly suitable “multiset” data structure.
Check if a list contains a value using the in keyword:
In [55]: 'dwarf' in b_list
Out[55]: True
The keyword not can be used to negate in:
In [56]: 'dwarf' not in b_list
Out[56]: False
Checking whether a list contains a value is a lot slower than doing so with dicts and
sets (to be introduced shortly), as Python makes a linear scan across the values of the
list, whereas it can check the others (based on hash tables) in constant time.
Concatenating and combining lists
Similar to tuples, adding two lists together with + concatenates them:
In [57]: [4, None, 'foo'] + [7, 8, (2, 3)]
Out[57]: [4, None, 'foo', 7, 8, (2, 3)]
If you have a list already defined, you can append multiple elements to it using the
extend method:
In [58]: x = [4, None, 'foo']
In [59]: x.extend([7, 8, (2, 3)])
In [60]: x
Out[60]: [4, None, 'foo', 7, 8, (2, 3)]
Note that list concatenation by addition is a comparatively expensive operation since
a new list must be created and the objects copied over. Using extend to append ele‐
ments to an existing list, especially if you are building up a large list, is usually pref‐
erable. Thus,
56 | Chapter 3: Built-in Data Structures, Functions, and Files
everything = []
for chunk in list_of_lists:
everything.extend(chunk)
is faster than the concatenative alternative:
everything = []
for chunk in list_of_lists:
everything = everything + chunk
Sorting
You can sort a list in-place (without creating a new object) by calling its sort
function:
In [61]: a = [7, 2, 5, 1, 3]
In [62]: a.sort()
In [63]: a
Out[63]: [1, 2, 3, 5, 7]
sort has a few options that will occasionally come in handy. One is the ability to pass
a secondary sort key—that is, a function that produces a value to use to sort the
objects. For example, we could sort a collection of strings by their lengths:
In [64]: b = ['saw', 'small', 'He', 'foxes', 'six']
In [65]: b.sort(key=len)
In [66]: b
Out[66]: ['He', 'saw', 'six', 'small', 'foxes']
Soon, we’ll look at the sorted function, which can produce a sorted copy of a general
sequence.
Binary search and maintaining a sorted list
The built-in bisect module implements binary search and insertion into a sorted list.
bisect.bisect finds the location where an element should be inserted to keep it sor‐
ted, while bisect.insort actually inserts the element into that location:
In [67]: import bisect
In [68]: c = [1, 2, 2, 2, 3, 4, 7]
In [69]: bisect.bisect(c, 2)
Out[69]: 4
In [70]: bisect.bisect(c, 5)
Out[70]: 6
3.1 Data Structures and Sequences | 57
In [71]: bisect.insort(c, 6)
In [72]: c
Out[72]: [1, 2, 2, 2, 3, 4, 6, 7]
The bisect module functions do not check whether the list is sor‐
ted, as doing so would be computationally expensive. Thus, using
them with an unsorted list will succeed without error but may lead
to incorrect results.
Slicing
You can select sections of most sequence types by using slice notation, which in its
basic form consists of start:stop passed to the indexing operator []:
In [73]: seq = [7, 2, 3, 7, 5, 6, 0, 1]
In [74]: seq[1:5]
Out[74]: [2, 3, 7, 5]
Slices can also be assigned to with a sequence:
In [75]: seq[3:4] = [6, 3]
In [76]: seq
Out[76]: [7, 2, 3, 6, 3, 5, 6, 0, 1]
While the element at the start index is included, the stop index is not included, so
that the number of elements in the result is stop - start.
Either the start or stop can be omitted, in which case they default to the start of the
sequence and the end of the sequence, respectively:
In [77]: seq[:5]
Out[77]: [7, 2, 3, 6, 3]
In [78]: seq[3:]
Out[78]: [6, 3, 5, 6, 0, 1]
Negative indices slice the sequence relative to the end:
In [79]: seq[-4:]
Out[79]: [5, 6, 0, 1]
In [80]: seq[-6:-2]
Out[80]: [6, 3, 5, 6]
Slicing semantics takes a bit of getting used to, especially if you’re coming from R or
MATLAB. See Figure 3-1 for a helpful illustration of slicing with positive and nega‐
tive integers. In the figure, the indices are shown at the “bin edges” to help show
where the slice selections start and stop using positive or negative indices.
58 | Chapter 3: Built-in Data Structures, Functions, and Files
A step can also be used after a second colon to, say, take every other element:
In [81]: seq[::2]
Out[81]: [7, 3, 3, 6, 1]
A clever use of this is to pass -1, which has the useful effect of reversing a list or tuple:
In [82]: seq[::-1]
Out[82]: [1, 0, 6, 5, 3, 6, 3, 2, 7]
Figure 3-1. Illustration of Python slicing conventions
Built-in Sequence Functions
Python has a handful of useful sequence functions that you should familiarize your‐
self with and use at any opportunity.
enumerate
It’s common when iterating over a sequence to want to keep track of the index of the
current item. A do-it-yourself approach would look like:
i = 0
for value in collection:
# do something with value
i += 1
Since this is so common, Python has a built-in function, enumerate, which returns a
sequence of (i, value) tuples:
for i, value in enumerate(collection):
# do something with value
When you are indexing data, a helpful pattern that uses enumerate is computing a
dict mapping the values of a sequence (which are assumed to be unique) to their
locations in the sequence:
In [83]: some_list = ['foo', 'bar', 'baz']
In [84]: mapping = {}
3.1 Data Structures and Sequences | 59
In [85]: for i, v in enumerate(some_list):
....: mapping[v] = i
In [86]: mapping
Out[86]: {'bar': 1, 'baz': 2, 'foo': 0}
sorted
The sorted function returns a new sorted list from the elements of any sequence:
In [87]: sorted([7, 1, 2, 6, 0, 3, 2])
Out[87]: [0, 1, 2, 2, 3, 6, 7]
In [88]: sorted('horse race')
Out[88]: [' ', 'a', 'c', 'e', 'e', 'h', 'o', 'r', 'r', 's']
The sorted function accepts the same arguments as the sort method on lists.
zip
zip “pairs” up the elements of a number of lists, tuples, or other sequences to create a
list of tuples:
In [89]: seq1 = ['foo', 'bar', 'baz']
In [90]: seq2 = ['one', 'two', 'three']
In [91]: zipped = zip(seq1, seq2)
In [92]: list(zipped)
Out[92]: [('foo', 'one'), ('bar', 'two'), ('baz', 'three')]
zip can take an arbitrary number of sequences, and the number of elements it pro‐
duces is determined by the shortest sequence:
In [93]: seq3 = [False, True]
In [94]: list(zip(seq1, seq2, seq3))
Out[94]: [('foo', 'one', False), ('bar', 'two', True)]
A very common use of zip is simultaneously iterating over multiple sequences, possi‐
bly also combined with enumerate:
In [95]: for i, (a, b) in enumerate(zip(seq1, seq2)):
....: print('{0}: {1}, {2}'.format(i, a, b))
....:
0: foo, one
1: bar, two
2: baz, three
60 | Chapter 3: Built-in Data Structures, Functions, and Files
Given a “zipped” sequence, zip can be applied in a clever way to “unzip” the
sequence. Another way to think about this is converting a list of rows into a list of
columns. The syntax, which looks a bit magical, is:
In [96]: pitchers = [('Nolan', 'Ryan'), ('Roger', 'Clemens'),
....: ('Schilling', 'Curt')]
In [97]: first_names, last_names = zip(*pitchers)
In [98]: first_names
Out[98]: ('Nolan', 'Roger', 'Schilling')
In [99]: last_names
Out[99]: ('Ryan', 'Clemens', 'Curt')
reversed
reversed iterates over the elements of a sequence in reverse order:
In [100]: list(reversed(range(10)))
Out[100]: [9, 8, 7, 6, 5, 4, 3, 2, 1, 0]
Keep in mind that reversed is a generator (to be discussed in some more detail later),
so it does not create the reversed sequence until materialized (e.g., with list or a for
loop).
dict
dict is likely the most important built-in Python data structure. A more common
name for it is hash map or associative array. It is a flexibly sized collection of key-value
pairs, where key and value are Python objects. One approach for creating one is to use
curly braces {} and colons to separate keys and values:
In [101]: empty_dict = {}
In [102]: d1 = {'a' : 'some value', 'b' : [1, 2, 3, 4]}
In [103]: d1
Out[103]: {'a': 'some value', 'b': [1, 2, 3, 4]}
You can access, insert, or set elements using the same syntax as for accessing elements
of a list or tuple:
In [104]: d1[7] = 'an integer'
In [105]: d1
Out[105]: {'a': 'some value', 'b': [1, 2, 3, 4], 7: 'an integer'}
In [106]: d1['b']
Out[106]: [1, 2, 3, 4]
3.1 Data Structures and Sequences | 61
You can check if a dict contains a key using the same syntax used for checking
whether a list or tuple contains a value:
In [107]: 'b' in d1
Out[107]: True
You can delete values either using the del keyword or the pop method (which simul‐
taneously returns the value and deletes the key):
In [108]: d1[5] = 'some value'
In [109]: d1
Out[109]:
{'a': 'some value',
'b': [1, 2, 3, 4],
7: 'an integer',
5: 'some value'}
In [110]: d1['dummy'] = 'another value'
In [111]: d1
Out[111]:
{'a': 'some value',
'b': [1, 2, 3, 4],
7: 'an integer',
5: 'some value',
'dummy': 'another value'}
In [112]: del d1[5]
In [113]: d1
Out[113]:
{'a': 'some value',
'b': [1, 2, 3, 4],
7: 'an integer',
'dummy': 'another value'}
In [114]: ret = d1.pop('dummy')
In [115]: ret
Out[115]: 'another value'
In [116]: d1
Out[116]: {'a': 'some value', 'b': [1, 2, 3, 4], 7: 'an integer'}
The keys and values method give you iterators of the dict’s keys and values, respec‐
tively. While the key-value pairs are not in any particular order, these functions out‐
put the keys and values in the same order:
In [117]: list(d1.keys())
Out[117]: ['a', 'b', 7]
62 | Chapter 3: Built-in Data Structures, Functions, and Files
In [118]: list(d1.values())
Out[118]: ['some value', [1, 2, 3, 4], 'an integer']
You can merge one dict into another using the update method:
In [119]: d1.update({'b' : 'foo', 'c' : 12})
In [120]: d1
Out[120]: {'a': 'some value', 'b': 'foo', 7: 'an integer', 'c': 12}
The update method changes dicts in-place, so any existing keys in the data passed to
update will have their old values discarded.
Creating dicts from sequences
It’s common to occasionally end up with two sequences that you want to pair up
element-wise in a dict. As a first cut, you might write code like this:
mapping = {}
for key, value in zip(key_list, value_list):
mapping[key] = value
Since a dict is essentially a collection of 2-tuples, the dict function accepts a list of
2-tuples:
In [121]: mapping = dict(zip(range(5), reversed(range(5))))
In [122]: mapping
Out[122]: {0: 4, 1: 3, 2: 2, 3: 1, 4: 0}
Later we’ll talk about dict comprehensions, another elegant way to construct dicts.
Default values
It’s very common to have logic like:
if key in some_dict:
value = some_dict[key]
else:
value = default_value
Thus, the dict methods get and pop can take a default value to be returned, so that
the above if-else block can be written simply as:
value = some_dict.get(key, default_value)
get by default will return None if the key is not present, while pop will raise an excep‐
tion. With setting values, a common case is for the values in a dict to be other collec‐
tions, like lists. For example, you could imagine categorizing a list of words by their
first letters as a dict of lists:
In [123]: words = ['apple', 'bat', 'bar', 'atom', 'book']
In [124]: by_letter = {}
3.1 Data Structures and Sequences | 63
In [125]: for word in words:
.....: letter = word[0]
.....: if letter not in by_letter:
.....: by_letter[letter] = [word]
.....: else:
.....: by_letter[letter].append(word)
.....:
In [126]: by_letter
Out[126]: {'a': ['apple', 'atom'], 'b': ['bat', 'bar', 'book']}
The setdefault dict method is for precisely this purpose. The preceding for loop
can be rewritten as:
for word in words:
letter = word[0]
by_letter.setdefault(letter, []).append(word)
The built-in collections module has a useful class, defaultdict, which makes this
even easier. To create one, you pass a type or function for generating the default value
for each slot in the dict:
from collections import defaultdict
by_letter = defaultdict(list)
for word in words:
by_letter[word[0]].append(word)
Valid dict key types
While the values of a dict can be any Python object, the keys generally have to be
immutable objects like scalar types (int, float, string) or tuples (all the objects in the
tuple need to be immutable, too). The technical term here is hashability. You can
check whether an object is hashable (can be used as a key in a dict) with the hash
function:
In [127]: hash('string')
Out[127]: 5023931463650008331
In [128]: hash((1, 2, (2, 3)))
Out[128]: 1097636502276347782
In [129]: hash((1, 2, [2, 3])) # fails because lists are mutable
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-129-800cd14ba8be> in <module>()
----> 1 hash((1, 2, [2, 3])) # fails because lists are mutable
TypeError: unhashable type: 'list'
64 | Chapter 3: Built-in Data Structures, Functions, and Files
To use a list as a key, one option is to convert it to a tuple, which can be hashed as
long as its elements also can:
In [130]: d = {}
In [131]: d[tuple([1, 2, 3])] = 5
In [132]: d
Out[132]: {(1, 2, 3): 5}
set
A set is an unordered collection of unique elements. You can think of them like dicts,
but keys only, no values. A set can be created in two ways: via the set function or via
a set literal with curly braces:
In [133]: set([2, 2, 2, 1, 3, 3])
Out[133]: {1, 2, 3}
In [134]: {2, 2, 2, 1, 3, 3}
Out[134]: {1, 2, 3}
Sets support mathematical set operations like union, intersection, difference, and
symmetric difference. Consider these two example sets:
In [135]: a = {1, 2, 3, 4, 5}
In [136]: b = {3, 4, 5, 6, 7, 8}
The union of these two sets is the set of distinct elements occurring in either set. This
can be computed with either the union method or the | binary operator:
In [137]: a.union(b)
Out[137]: {1, 2, 3, 4, 5, 6, 7, 8}
In [138]: a | b
Out[138]: {1, 2, 3, 4, 5, 6, 7, 8}
The intersection contains the elements occurring in both sets. The & operator or the
intersection method can be used:
In [139]: a.intersection(b)
Out[139]: {3, 4, 5}
In [140]: a & b
Out[140]: {3, 4, 5}
See Table 3-1 for a list of commonly used set methods.
3.1 Data Structures and Sequences | 65
Table 3-1. Python set operations
Function Alternative
syntax
Description
a.add(x) N/A Add element x to the set a
a.clear() N/A Reset the set a to an empty state, discarding all of
its elements
a.remove(x) N/A Remove element x from the set a
a.pop() N/A Remove an arbitrary element from the set a, raising
KeyError if the set is empty
a.union(b) a | b All of the unique elements in a and b
a.update(b) a |= b Set the contents of a to be the union of the
elements in a and b
a.intersection(b) a & b All of the elements in both a and b
a.intersection_update(b) a &= b Set the contents of a to be the intersection of the
elements in a and b
a.difference(b) a - b The elements in a that are not in b
a.difference_update(b) a -= b Set a to the elements in a that are not in b
a.symmetric_difference(b) a ^ b All of the elements in either a or b but not both
a.symmetric_difference_update(b) a ^= b Set a to contain the elements in either a or b but
not both
a.issubset(b) N/A True if the elements of a are all contained in b
a.issuperset(b) N/A True if the elements of b are all contained in a
a.isdisjoint(b) N/A True if a and b have no elements in common
All of the logical set operations have in-place counterparts, which enable you to
replace the contents of the set on the left side of the operation with the result. For
very large sets, this may be more efficient:
In [141]: c = a.copy()
In [142]: c |= b
In [143]: c
Out[143]: {1, 2, 3, 4, 5, 6, 7, 8}
In [144]: d = a.copy()
In [145]: d &= b
In [146]: d
Out[146]: {3, 4, 5}
Like dicts, set elements generally must be immutable. To have list-like elements, you
must convert it to a tuple:
66 | Chapter 3: Built-in Data Structures, Functions, and Files
In [147]: my_data = [1, 2, 3, 4]
In [148]: my_set = {tuple(my_data)}
In [149]: my_set
Out[149]: {(1, 2, 3, 4)}
You can also check if a set is a subset of (is contained in) or a superset of (contains all
elements of) another set:
In [150]: a_set = {1, 2, 3, 4, 5}
In [151]: {1, 2, 3}.issubset(a_set)
Out[151]: True
In [152]: a_set.issuperset({1, 2, 3})
Out[152]: True
Sets are equal if and only if their contents are equal:
In [153]: {1, 2, 3} == {3, 2, 1}
Out[153]: True
List, Set, and Dict Comprehensions
List comprehensions are one of the most-loved Python language features. They allow
you to concisely form a new list by filtering the elements of a collection, transforming
the elements passing the filter in one concise expression. They take the basic form:
[expr for val in collection if condition]
This is equivalent to the following for loop:
result = []
for val in collection:
if condition:
result.append(expr)
The filter condition can be omitted, leaving only the expression. For example, given a
list of strings, we could filter out strings with length 2 or less and also convert them to
uppercase like this:
In [154]: strings = ['a', 'as', 'bat', 'car', 'dove', 'python']
In [155]: [x.upper() for x in strings if len(x) > 2]
Out[155]: ['BAT', 'CAR', 'DOVE', 'PYTHON']
Set and dict comprehensions are a natural extension, producing sets and dicts in an
idiomatically similar way instead of lists. A dict comprehension looks like this:
dict_comp = {key-expr : value-expr for value in collection
if condition}
3.1 Data Structures and Sequences | 67
A set comprehension looks like the equivalent list comprehension except with curly
braces instead of square brackets:
set_comp = {expr for value in collection if condition}
Like list comprehensions, set and dict comprehensions are mostly conveniences, but
they similarly can make code both easier to write and read. Consider the list of strings
from before. Suppose we wanted a set containing just the lengths of the strings con‐
tained in the collection; we could easily compute this using a set comprehension:
In [156]: unique_lengths = {len(x) for x in strings}
In [157]: unique_lengths
Out[157]: {1, 2, 3, 4, 6}
We could also express this more functionally using the map function, introduced
shortly:
In [158]: set(map(len, strings))
Out[158]: {1, 2, 3, 4, 6}
As a simple dict comprehension example, we could create a lookup map of these
strings to their locations in the list:
In [159]: loc_mapping = {val : index for index, val in enumerate(strings)}
In [160]: loc_mapping
Out[160]: {'a': 0, 'as': 1, 'bat': 2, 'car': 3, 'dove': 4, 'python': 5}
Nested list comprehensions
Suppose we have a list of lists containing some English and Spanish names:
In [161]: all_data = [['John', 'Emily', 'Michael', 'Mary', 'Steven'],
.....: ['Maria', 'Juan', 'Javier', 'Natalia', 'Pilar']]
You might have gotten these names from a couple of files and decided to organize
them by language. Now, suppose we wanted to get a single list containing all names
with two or more e’s in them. We could certainly do this with a simple for loop:
names_of_interest = []
for names in all_data:
enough_es = [name for name in names if name.count('e') >= 2]
names_of_interest.extend(enough_es)
You can actually wrap this whole operation up in a single nested list comprehension,
which will look like:
In [162]: result = [name for names in all_data for name in names
.....: if name.count('e') >= 2]
In [163]: result
Out[163]: ['Steven']
68 | Chapter 3: Built-in Data Structures, Functions, and Files
At first, nested list comprehensions are a bit hard to wrap your head around. The for
parts of the list comprehension are arranged according to the order of nesting, and
any filter condition is put at the end as before. Here is another example where we
“flatten” a list of tuples of integers into a simple list of integers:
In [164]: some_tuples = [(1, 2, 3), (4, 5, 6), (7, 8, 9)]
In [165]: flattened = [x for tup in some_tuples for x in tup]
In [166]: flattened
Out[166]: [1, 2, 3, 4, 5, 6, 7, 8, 9]
Keep in mind that the order of the for expressions would be the same if you wrote a
nested for loop instead of a list comprehension:
flattened = []
for tup in some_tuples:
for x in tup:
flattened.append(x)
You can have arbitrarily many levels of nesting, though if you have more than two or
three levels of nesting you should probably start to question whether this makes sense
from a code readability standpoint. It’s important to distinguish the syntax just shown
from a list comprehension inside a list comprehension, which is also perfectly valid:
In [167]: [[x for x in tup] for tup in some_tuples]
Out[167]: [[1, 2, 3], [4, 5, 6], [7, 8, 9]]
This produces a list of lists, rather than a flattened list of all of the inner elements.
3.2 Functions
Functions are the primary and most important method of code organization and
reuse in Python. As a rule of thumb, if you anticipate needing to repeat the same or
very similar code more than once, it may be worth writing a reusable function. Func‐
tions can also help make your code more readable by giving a name to a group of
Python statements.
Functions are declared with the def keyword and returned from with the return key‐
word:
def my_function(x, y, z=1.5):
if z > 1:
return z * (x + y)
else:
return z / (x + y)
3.2 Functions | 69
There is no issue with having multiple return statements. If Python reaches the end
of a function without encountering a return statement, None is returned automati‐
cally.
Each function can have positional arguments and keyword arguments. Keyword argu‐
ments are most commonly used to specify default values or optional arguments. In
the preceding function, x and y are positional arguments while z is a keyword argu‐
ment. This means that the function can be called in any of these ways:
my_function(5, 6, z=0.7)
my_function(3.14, 7, 3.5)
my_function(10, 20)
The main restriction on function arguments is that the keyword arguments must fol‐
low the positional arguments (if any). You can specify keyword arguments in any
order; this frees you from having to remember which order the function arguments
were specified in and only what their names are.
It is possible to use keywords for passing positional arguments as
well. In the preceding example, we could also have written:
my_function(x=5, y=6, z=7)
my_function(y=6, x=5, z=7)
In some cases this can help with readability.
Namespaces, Scope, and Local Functions
Functions can access variables in two different scopes: global and local. An alternative
and more descriptive name describing a variable scope in Python is a namespace. Any
variables that are assigned within a function by default are assigned to the local
namespace. The local namespace is created when the function is called and immedi‐
ately populated by the function’s arguments. After the function is finished, the local
namespace is destroyed (with some exceptions that are outside the purview of this
chapter). Consider the following function:
def func():
a = []
for i in range(5):
a.append(i)
When func() is called, the empty list a is created, five elements are appended, and
then a is destroyed when the function exits. Suppose instead we had declared a as
follows:
a = []
def func():
for i in range(5):
a.append(i)
70 | Chapter 3: Built-in Data Structures, Functions, and Files
Assigning variables outside of the function’s scope is possible, but those variables
must be declared as global via the global keyword:
In [168]: a = None
In [169]: def bind_a_variable():
.....: global a
.....: a = []
.....: bind_a_variable()
.....:
In [170]: print(a)
[]
I generally discourage use of the global keyword. Typically global
variables are used to store some kind of state in a system. If you
find yourself using a lot of them, it may indicate a need for object-
oriented programming (using classes).
Returning Multiple Values
When I first programmed in Python after having programmed in Java and C++, one
of my favorite features was the ability to return multiple values from a function with
simple syntax. Here’s an example:
def f():
a = 5
b = 6
c = 7
return a, b, c
a, b, c = f()
In data analysis and other scientific applications, you may find yourself doing this
often. What’s happening here is that the function is actually just returning one object,
namely a tuple, which is then being unpacked into the result variables. In the preced‐
ing example, we could have done this instead:
return_value = f()
In this case, return_value would be a 3-tuple with the three returned variables. A
potentially attractive alternative to returning multiple values like before might be to
return a dict instead:
def f():
a = 5
b = 6
c = 7
return {'a' : a, 'b' : b, 'c' : c}
3.2 Functions | 71
This alternative technique can be useful depending on what you are trying to do.
Functions Are Objects
Since Python functions are objects, many constructs can be easily expressed that are
difficult to do in other languages. Suppose we were doing some data cleaning and
needed to apply a bunch of transformations to the following list of strings:
In [171]: states = [' Alabama ', 'Georgia!', 'Georgia', 'georgia', 'FlOrIda',
.....: 'south carolina##', 'West virginia?']
Anyone who has ever worked with user-submitted survey data has seen messy results
like these. Lots of things need to happen to make this list of strings uniform and
ready for analysis: stripping whitespace, removing punctuation symbols, and stand‐
ardizing on proper capitalization. One way to do this is to use built-in string methods
along with the re standard library module for regular expressions:
import re
def clean_strings(strings):
result = []
for value in strings:
value = value.strip()
value = re.sub('[!#?]', '', value)
value = value.title()
result.append(value)
return result
The result looks like this:
In [173]: clean_strings(states)
Out[173]:
['Alabama',
'Georgia',
'Georgia',
'Georgia',
'Florida',
'South Carolina',
'West Virginia']
An alternative approach that you may find useful is to make a list of the operations
you want to apply to a particular set of strings:
def remove_punctuation(value):
return re.sub('[!#?]', '', value)
clean_ops = [str.strip, remove_punctuation, str.title]
def clean_strings(strings, ops):
result = []
for value in strings:
for function in ops:
72 | Chapter 3: Built-in Data Structures, Functions, and Files
value = function(value)
result.append(value)
return result
Then we have the following:
In [175]: clean_strings(states, clean_ops)
Out[175]:
['Alabama',
'Georgia',
'Georgia',
'Georgia',
'Florida',
'South Carolina',
'West Virginia']
A more functional pattern like this enables you to easily modify how the strings are
transformed at a very high level. The clean_strings function is also now more reus‐
able and generic.
You can use functions as arguments to other functions like the built-in map function,
which applies a function to a sequence of some kind:
In [176]: for x in map(remove_punctuation, states):
.....: print(x)
Alabama
Georgia
Georgia
georgia
FlOrIda
south carolina
West virginia
Anonymous (Lambda) Functions
Python has support for so-called anonymous or lambda functions, which are a way of
writing functions consisting of a single statement, the result of which is the return
value. They are defined with the lambda keyword, which has no meaning other than
“we are declaring an anonymous function”:
def short_function(x):
return x * 2
equiv_anon = lambda x: x * 2
I usually refer to these as lambda functions in the rest of the book. They are especially
convenient in data analysis because, as you’ll see, there are many cases where data
transformation functions will take functions as arguments. It’s often less typing (and
clearer) to pass a lambda function as opposed to writing a full-out function declara‐
tion or even assigning the lambda function to a local variable. For example, consider
this silly example:
3.2 Functions | 73
def apply_to_list(some_list, f):
return [f(x) for x in some_list]
ints = [4, 0, 1, 5, 6]
apply_to_list(ints, lambda x: x * 2)
You could also have written [x * 2 for x in ints], but here we were able to suc‐
cinctly pass a custom operator to the apply_to_list function.
As another example, suppose you wanted to sort a collection of strings by the number
of distinct letters in each string:
In [177]: strings = ['foo', 'card', 'bar', 'aaaa', 'abab']
Here we could pass a lambda function to the list’s sort method:
In [178]: strings.sort(key=lambda x: len(set(list(x))))
In [179]: strings
Out[179]: ['aaaa', 'foo', 'abab', 'bar', 'card']
One reason lambda functions are called anonymous functions is
that , unlike functions declared with the def keyword, the function
object itself is never given an explicit __name__ attribute.
Currying: Partial Argument Application
Currying is computer science jargon (named after the mathematician Haskell Curry)
that means deriving new functions from existing ones by partial argument applica‐
tion. For example, suppose we had a trivial function that adds two numbers together:
def add_numbers(x, y):
return x + y
Using this function, we could derive a new function of one variable, add_five, that
adds 5 to its argument:
add_five = lambda y: add_numbers(5, y)
The second argument to add_numbers is said to be curried. There’s nothing very fancy
here, as all we’ve really done is define a new function that calls an existing function.
The built-in functools module can simplify this process using the partial function:
from functools import partial
add_five = partial(add_numbers, 5)
74 | Chapter 3: Built-in Data Structures, Functions, and Files
Generators
Having a consistent way to iterate over sequences, like objects in a list or lines in a
file, is an important Python feature. This is accomplished by means of the iterator
protocol, a generic way to make objects iterable. For example, iterating over a dict
yields the dict keys:
In [180]: some_dict = {'a': 1, 'b': 2, 'c': 3}
In [181]: for key in some_dict:
.....: print(key)
a
b
c
When you write for key in some_dict, the Python interpreter first attempts to cre‐
ate an iterator out of some_dict:
In [182]: dict_iterator = iter(some_dict)
In [183]: dict_iterator
Out[183]: <dict_keyiterator at 0x7fbbd5a9f908>
An iterator is any object that will yield objects to the Python interpreter when used in
a context like a for loop. Most methods expecting a list or list-like object will also
accept any iterable object. This includes built-in methods such as min, max, and sum,
and type constructors like list and tuple:
In [184]: list(dict_iterator)
Out[184]: ['a', 'b', 'c']
A generator is a concise way to construct a new iterable object. Whereas normal func‐
tions execute and return a single result at a time, generators return a sequence of
multiple results lazily, pausing after each one until the next one is requested. To create
a generator, use the yield keyword instead of return in a function:
def squares(n=10):
print('Generating squares from 1 to {0}'.format(n ** 2))
for i in range(1, n + 1):
yield i ** 2
When you actually call the generator, no code is immediately executed:
In [186]: gen = squares()
In [187]: gen
Out[187]: <generator object squares at 0x7fbbd5ab4570>
It is not until you request elements from the generator that it begins executing its
code:
3.2 Functions | 75
In [188]: for x in gen:
.....: print(x, end=' ')
Generating squares from 1 to 100
1 4 9 16 25 36 49 64 81 100
Generator expresssions
Another even more concise way to make a generator is by using a generator expres‐
sion. This is a generator analogue to list, dict, and set comprehensions; to create one,
enclose what would otherwise be a list comprehension within parentheses instead of
brackets:
In [189]: gen = (x ** 2 for x in range(100))
In [190]: gen
Out[190]: <generator object <genexpr> at 0x7fbbd5ab29e8>
This is completely equivalent to the following more verbose generator:
def _make_gen():
for x in range(100):
yield x ** 2
gen = _make_gen()
Generator expressions can be used instead of list comprehensions as function argu‐
ments in many cases:
In [191]: sum(x ** 2 for x in range(100))
Out[191]: 328350
In [192]: dict((i, i **2) for i in range(5))
Out[192]: {0: 0, 1: 1, 2: 4, 3: 9, 4: 16}
itertools module
The standard library itertools module has a collection of generators for many com‐
mon data algorithms. For example, groupby takes any sequence and a function,
grouping consecutive elements in the sequence by return value of the function. Here’s
an example:
In [193]: import itertools
In [194]: first_letter = lambda x: x[0]
In [195]: names = ['Alan', 'Adam', 'Wes', 'Will', 'Albert', 'Steven']
In [196]: for letter, names in itertools.groupby(names, first_letter):
.....: print(letter, list(names)) # names is a generator
A ['Alan', 'Adam']
W ['Wes', 'Will']
A ['Albert']
S ['Steven']
76 | Chapter 3: Built-in Data Structures, Functions, and Files
See Table 3-2 for a list of a few other itertools functions I’ve frequently found help‐
ful. You may like to check out the official Python documentation for more on this
useful built-in utility module.
Table 3-2. Some useful itertools functions
Function Description
combinations(iterable, k) Generates a sequence of all possible k-tuples of elements in the iterable,
ignoring order and without replacement (see also the companion function
combinations_with_replacement)
permutations(iterable, k) Generates a sequence of all possible k-tuples of elements in the iterable,
respecting order
groupby(iterable[, keyfunc]) Generates (key, sub-iterator) for each unique key
product(*iterables, repeat=1) Generates the Cartesian product of the input iterables as tuples, similar to a
nested for loop
Errors and Exception Handling
Handling Python errors or exceptions gracefully is an important part of building
robust programs. In data analysis applications, many functions only work on certain
kinds of input. As an example, Python’s float function is capable of casting a string
to a floating-point number, but fails with ValueError on improper inputs:
In [197]: float('1.2345')
Out[197]: 1.2345
In [198]: float('something')
---------------------------------------------------------------------------
ValueError Traceback (most recent call last)
<ipython-input-198-439904410854> in <module>()
----> 1 float('something')
ValueError: could not convert string to float: 'something'
Suppose we wanted a version of float that fails gracefully, returning the input argu‐
ment. We can do this by writing a function that encloses the call to float in a try/
except block:
def attempt_float(x):
try:
return float(x)
except:
return x
The code in the except part of the block will only be executed if float(x) raises an
exception:
In [200]: attempt_float('1.2345')
Out[200]: 1.2345
3.2 Functions | 77
In [201]: attempt_float('something')
Out[201]: 'something'
You might notice that float can raise exceptions other than ValueError:
In [202]: float((1, 2))
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-202-842079ebb635> in <module>()
----> 1 float((1, 2))
TypeError: float() argument must be a string or a number, not 'tuple'
You might want to only suppress ValueError, since a TypeError (the input was not a
string or numeric value) might indicate a legitimate bug in your program. To do that,
write the exception type after except:
def attempt_float(x):
try:
return float(x)
except ValueError:
return x
We have then:
In [204]: attempt_float((1, 2))
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-204-9bdfd730cead> in <module>()
----> 1 attempt_float((1, 2))
<ipython-input-203-3e06b8379b6b> in attempt_float(x)
1 def attempt_float(x):
2 try:
----> 3 return float(x)
4 except ValueError:
5 return x
TypeError: float() argument must be a string or a number, not 'tuple'
You can catch multiple exception types by writing a tuple of exception types instead
(the parentheses are required):
def attempt_float(x):
try:
return float(x)
except (TypeError, ValueError):
return x
In some cases, you may not want to suppress an exception, but you want some code
to be executed regardless of whether the code in the try block succeeds or not. To do
this, use finally:
f = open(path, 'w')
try:
write_to_file(f)
78 | Chapter 3: Built-in Data Structures, Functions, and Files
finally:
f.close()
Here, the file handle f will always get closed. Similarly, you can have code that exe‐
cutes only if the try: block succeeds using else:
f = open(path, 'w')
try:
write_to_file(f)
except:
print('Failed')
else:
print('Succeeded')
finally:
f.close()
Exceptions in IPython
If an exception is raised while you are %run-ing a script or executing any statement,
IPython will by default print a full call stack trace (traceback) with a few lines of con‐
text around the position at each point in the stack:
In [10]: %run examples/ipython_bug.py
---------------------------------------------------------------------------
AssertionError Traceback (most recent call last)
/home/wesm/code/pydata-book/examples/ipython_bug.py in <module>()
13 throws_an_exception()
14
---> 15 calling_things()
/home/wesm/code/pydata-book/examples/ipython_bug.py in calling_things()
11 def calling_things():
12 works_fine()
---> 13 throws_an_exception()
14
15 calling_things()
/home/wesm/code/pydata-book/examples/ipython_bug.py in throws_an_exception()
7 a = 5
8 b = 6
----> 9 assert(a + b == 10)
10
11 def calling_things():
AssertionError:
Having additional context by itself is a big advantage over the standard Python inter‐
preter (which does not provide any additional context). You can control the amount
of context shown using the %xmode magic command, from Plain (same as the stan‐
dard Python interpreter) to Verbose (which inlines function argument values and
3.2 Functions | 79
more). As you will see later in the chapter, you can step into the stack (using the
%debug or %pdb magics) after an error has occurred for interactive post-mortem
debugging.
3.3 Files and the Operating System
Most of this book uses high-level tools like pandas.read_csv to read data files from
disk into Python data structures. However, it’s important to understand the basics of
how to work with files in Python. Fortunately, it’s very simple, which is one reason
why Python is so popular for text and file munging.
To open a file for reading or writing, use the built-in open function with either a rela‐
tive or absolute file path:
In [207]: path = 'examples/segismundo.txt'
In [208]: f = open(path)
By default, the file is opened in read-only mode 'r'. We can then treat the file handle
f like a list and iterate over the lines like so:
for line in f:
pass
The lines come out of the file with the end-of-line (EOL) markers intact, so you’ll
often see code to get an EOL-free list of lines in a file like:
In [209]: lines = [x.rstrip() for x in open(path)]
In [210]: lines
Out[210]:
['Sueña el rico en su riqueza,',
'que más cuidados le ofrece;',
'',
'sueña el pobre que padece',
'su miseria y su pobreza;',
'',
'sueña el que a medrar empieza,',
'sueña el que afana y pretende,',
'sueña el que agravia y ofende,',
'',
'y en el mundo, en conclusión,',
'todos sueñan lo que son,',
'aunque ninguno lo entiende.',
'']
When you use open to create file objects, it is important to explicitly close the file
when you are finished with it. Closing the file releases its resources back to the oper‐
ating system:
In [211]: f.close()
80 | Chapter 3: Built-in Data Structures, Functions, and Files
One of the ways to make it easier to clean up open files is to use the with statement:
In [212]: with open(path) as f:
.....: lines = [x.rstrip() for x in f]
This will automatically close the file f when exiting the with block.
If we had typed f = open(path, 'w'), a new file at examples/segismundo.txt would
have been created (be careful!), overwriting any one in its place. There is also the 'x'
file mode, which creates a writable file but fails if the file path already exists. See
Table 3-3 for a list of all valid file read/write modes.
For readable files, some of the most commonly used methods are read, seek, and
tell. read returns a certain number of characters from the file. What constitutes a
“character” is determined by the file’s encoding (e.g., UTF-8) or simply raw bytes if
the file is opened in binary mode:
In [213]: f = open(path)
In [214]: f.read(10)
Out[214]: 'Sueña el r'
In [215]: f2 = open(path, 'rb') # Binary mode
In [216]: f2.read(10)
Out[216]: b'Suexc3xb1a el '
The read method advances the file handle’s position by the number of bytes read.
tell gives you the current position:
In [217]: f.tell()
Out[217]: 11
In [218]: f2.tell()
Out[218]: 10
Even though we read 10 characters from the file, the position is 11 because it took
that many bytes to decode 10 characters using the default encoding. You can check
the default encoding in the sys module:
In [219]: import sys
In [220]: sys.getdefaultencoding()
Out[220]: 'utf-8'
seek changes the file position to the indicated byte in the file:
In [221]: f.seek(3)
Out[221]: 3
In [222]: f.read(1)
Out[222]: 'ñ'
3.3 Files and the Operating System | 81
Lastly, we remember to close the files:
In [223]: f.close()
In [224]: f2.close()
Table 3-3. Python file modes
Mode Description
r Read-only mode
w Write-only mode; creates a new file (erasing the data for any file with the same name)
x Write-only mode; creates a new file, but fails if the file path already exists
a Append to existing file (create the file if it does not already exist)
r+ Read and write
b Add to mode for binary files (i.e., 'rb' or 'wb')
t Text mode for files (automatically decoding bytes to Unicode). This is the default if not specified. Add t to other
modes to use this (i.e., 'rt' or 'xt')
To write text to a file, you can use the file’s write or writelines methods. For exam‐
ple, we could create a version of prof_mod.py with no blank lines like so:
In [225]: with open('tmp.txt', 'w') as handle:
.....: handle.writelines(x for x in open(path) if len(x) > 1)
In [226]: with open('tmp.txt') as f:
.....: lines = f.readlines()
In [227]: lines
Out[227]:
['Sueña el rico en su riqueza,n',
'que más cuidados le ofrece;n',
'sueña el pobre que padecen',
'su miseria y su pobreza;n',
'sueña el que a medrar empieza,n',
'sueña el que afana y pretende,n',
'sueña el que agravia y ofende,n',
'y en el mundo, en conclusión,n',
'todos sueñan lo que son,n',
'aunque ninguno lo entiende.n']
See Table 3-4 for many of the most commonly used file methods.
Table 3-4. Important Python file methods or attributes
Method Description
read([size]) Return data from file as a string, with optional size argument indicating the number of
bytes to read
readlines([size]) Return list of lines in the file, with optional size argument
write(str) Write passed string to file
82 | Chapter 3: Built-in Data Structures, Functions, and Files