Looking backward, looking
forward
Wes McKinney @wesmckinn
PyCon DE / PyData Karlsruhe 2018
Motivations
Guiding questions
How to make data
analysis “easier”?
Making individuals
more productive
More fruitful open
source collaborations
Better hardware
utilization
Examining the
status quo
Change is difficult
From one existential
crisis to another
April 2008 - Avant garde PyData
● Socializing Python inside AQR, a quantitative
hedge fund
● scipy.stats.models enabled some R ->
Python workload migration
Dec 2009 - pandas 0.1
● First open source release after ~18 months
of internal-only use
May 2011 - “PyData” core dev meetings
"Need a toolset that is robust, fast, and suitable
for a production environment..."
May 2011
"Need a toolset that is robust, fast, and suitable
for a production environment..."
"... but also good for interactive research... "
May 2011 - “PyData” core dev meetings
May 2011
"Need a toolset that is robust, fast, and suitable
for a production environment..."
"... but also good for interactive research... "
"... and easy / intuitive for non-software
engineers to use"
May 2011 - “PyData” core dev meetings
May 2011
* also, we need to fix packaging
May 2011 - “PyData” core dev meetings
July 2011- Concerns
"... the current state of affairs has me rather
anxious … these tools [e.g. pandas] have
largely not been integrated with any other tools
because of the community's collective
commitment anxiety"
http://wesmckinney.com/blog/a-roadmap-for-rich-scientific-data-structures-in-python/
July 2011- Concerns
"Fragmentation is killing us”
http://wesmckinney.com/blog/a-roadmap-for-rich-scientific-data-structures-in-python/
Reading CSV files
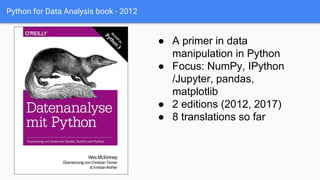
Python for Data Analysis book - 2012
● A primer in data
manipulation in Python
● Focus: NumPy, IPython
/Jupyter, pandas,
matplotlib
● 2 editions (2012, 2017)
● 8 translations so far
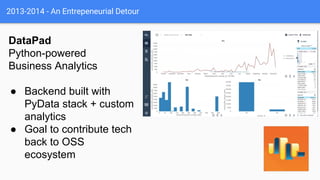
2013-2014 - An Entrepeneurial Detour
DataPad
Python-powered
Business Analytics
● Backend built with
PyData stack + custom
analytics
● Goal to contribute tech
back to OSS
ecosystem
DataPad learnings
● 200ms threshold for interactivity
● Multitenant query execution, resource management
● pandas performance / memory use problems
PyData NYC 2013: 10 Things I Hate About pandas
● November 2013
● Summary: “pandas is
not designed like, or
intended to be used
as, a database query
engine”
Vertical
Integration
The Good
● Control
● Development Speed
● Releases
Vertical
Integration
The Bad
● Large scope of code
ownership
● Lack of code reuse
● Bit rot
Fall 2014: Python in a Big Data World
Task: Helping Python
become a first-class
technology for Big Data
Some Problems
● File formats
● JVM interop
● Non-array-oriented
interfaces
Fragmentation of data
and code
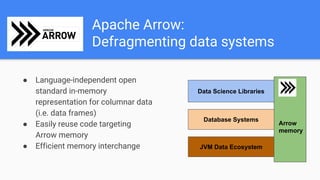
Apache Arrow:
Defragmenting data systems
● Language-independent open
standard in-memory
representation for columnar data
(i.e. data frames)
● Easily reuse code targeting
Arrow memory
● Efficient memory interchange
Arrow
memory
JVM Data Ecosystem
Database Systems
Data Science Libraries
Apache Arrow:
Defragmenting data systems
● https://github.com/apache/arrow
● Over 200 unique contributors
● Some level of support for 11 programming
languages
Funding ambitious
new open source
projects
Early Partners
● https://ursalabs.org
● Apache Arrow-powered
Data Science Tools
● Funded by corporate
partners
● Built in collaboration with
RStudio
Looking forward