MySQL Replication 101
PHPTek Atlanta 2017
https://joind.in/talk/d98bc
About today
MySQL replication is fairly easy to set up and run, but there are many facets you may not be using that could
make your life much easier. With containers, you will see how to setup basic replication, learn how to use
GTIDs, discover multi-source replication, and then see how to use active-active multi-master Group
Replication. You will understand what the various settings really do and what should be in your config files.
Bring a Linux box with Docker installed and follow along.
Rules: Ask questions!! Only bad question is the one never asked
Be interactive
Try to see ‘big picture’, do not get lost in the config files
3
About me
Dave Stokes
@stoker
david.stokes@oracle.com
elephantdolphin.blogger.com
slideshare.net/davidmstokes
MySQL Community Manager, former MySQL Certification Manager
Live in a small Texas town, have pickup truck & hound dog as required by law 4
Why are you here
What do you do?
What do you want to learn?
What are you long term data needs?
5
What is Replication
6
Replication
Replication enables data from one MySQL database server (the
master) to be copied to one or more MySQL database servers
(the slaves). Replication is asynchronous by default; slaves do
not need to be connected permanently to receive updates from
the master. Depending on the configuration, you can replicate all
databases, selected databases, or even selected tables within a
database.
7
Advantages of Replication
Scale-out solutions - spreading the load among multiple slaves to improve performance. In this
environment, all writes and updates must take place on the master server. Reads, however, may take
place on one or more slaves. This model can improve the performance of writes (since the master is
dedicated to updates), while dramatically increasing read speed across an increasing number of slaves.
Data security - because data is replicated to the slave, and the slave can pause the replication process,
it is possible to run backup services on the slave without corrupting the corresponding master data.
Analytics - live data can be created on the master, while the analysis of the information can take place
on the slave without affecting the performance of the master.
Long-distance data distribution - you can use replication to create a local copy of data for a remote
site to use, without permanent access to the master.
8
MySQL 5.7 supports different methods of replication. The traditional method is based on replicating events from the
master's binary log, and requires the log files and positions in them to be synchronized between master and slave. The
newer method based on global transaction identifiers (GTIDs) is transactional and therefore does not require working with
log files or positions within these files, which greatly simplifies many common replication tasks. Replication using GTIDs
guarantees consistency between master and slave as long as all transactions committed on the master have also been
applied on the slave
Replication in MySQL supports different types of synchronization. The original type of synchronization is one-way,
asynchronous replication, in which one server acts as the master, while one or more other servers act as slaves. This is in
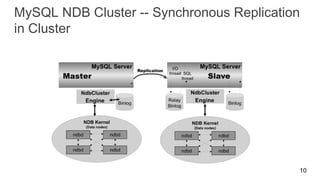
contrast to the synchronous replication which is a characteristic of NDB Cluster. In MySQL 5.7, semisynchronous
replication is supported in addition to the built-in asynchronous replication. With semisynchronous replication, a commit
performed on the master blocks before returning to the session that performed the transaction until at least one slave
acknowledges that it has received and logged the events for the transaction.
There are two core types of replication format, Statement Based Replication (SBR), which replicates entire SQL
statements, and Row Based Replication (RBR), which replicates only the changed rows. You can also use a third variety,
Mixed Based Replication (MBR).
9
MySQL NDB Cluster -- Synchronous Replication
in Cluster
10
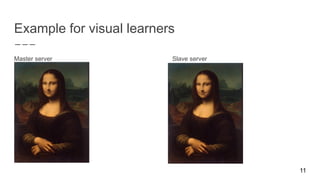
Example for visual learners
Master server Slave server
11
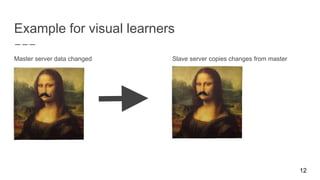
Example for visual learners
Master server data changed Slave server copies changes from master
12
Example for visual learners
Master server keeps changing Slave server keeps copying changes
13
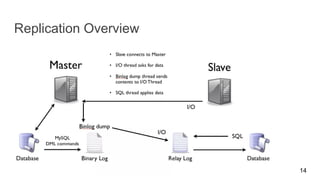
Replication Overview
14
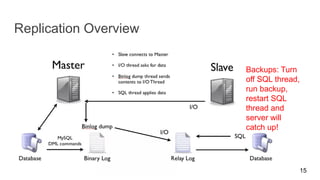
Replication Overview
15
Backups: Turn
off SQL thread,
run backup,
restart SQL
thread and
server will
catch up!
Software
16
https://github.com/datacharmer/mysql-
replication-samples.git
Big Thanks to Giuseppe Maxia
https://github.com/datacharmer/mysql-replication-samples.git
17
Basic Replication
Cd mysql-replication-samples-master/docker-replication/simple
18
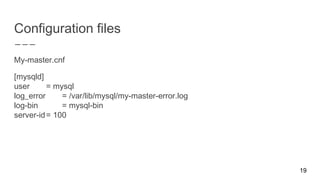
Configuration files
My-master.cnf
[mysqld]
user = mysql
log_error = /var/lib/mysql/my-master-error.log
log-bin = mysql-bin
server-id= 100
19
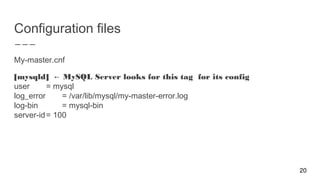
Configuration files
My-master.cnf
[mysqld] MySQL Server looks for this tag for its config←
user = mysql
log_error = /var/lib/mysql/my-master-error.log
log-bin = mysql-bin
server-id= 100
20
Configuration files
My-master.cnf
[mysqld]
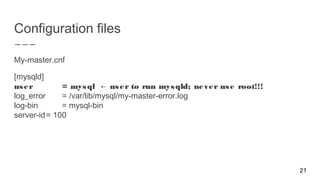
user = mysql user to run mysqld; never use root!!!←
log_error = /var/lib/mysql/my-master-error.log
log-bin = mysql-bin
server-id= 100
21
Configuration files
My-master.cnf
[mysqld]
user = mysql
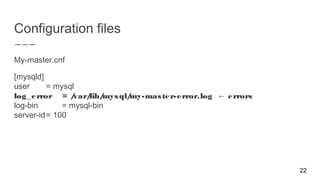
log_error = /var/lib/mysql/my-master-error.log errors←
log-bin = mysql-bin
server-id= 100
22
Configuration files
My-master.cnf
[mysqld]
user = mysql
log_error = /var/lib/mysql/my-master-error.log
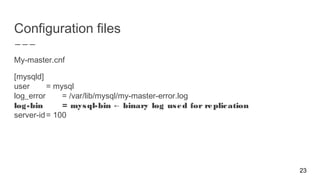
log-bin = mysql-bin binary log used for replication←
server-id= 100
23
Configuration files
My-master.cnf
[mysqld]
user = mysql
log_error = /var/lib/mysql/my-master-error.log
log-bin = mysql-bin
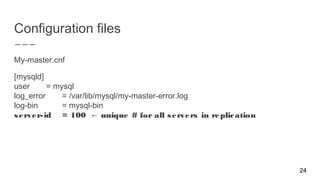
server-id = 100 unique # for all servers in replication←
24
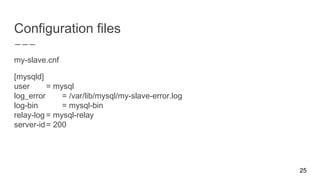
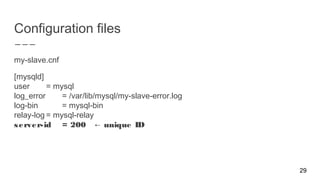
Configuration files
my-slave.cnf
[mysqld]
user = mysql
log_error = /var/lib/mysql/my-slave-error.log
log-bin = mysql-bin
relay-log = mysql-relay
server-id= 200
25
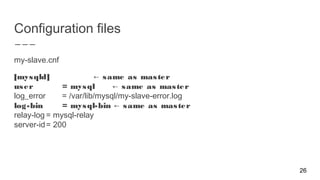
Configuration files
my-slave.cnf
[mysqld] same as master←
user = mysql same as master←
log_error = /var/lib/mysql/my-slave-error.log
log-bin = mysql-bin same as master←
relay-log = mysql-relay
server-id= 200
26
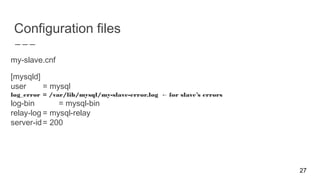
Configuration files
my-slave.cnf
[mysqld]
user = mysql
log_error = /var/lib/mysql/my-slave-error.log for slave’s errors←
log-bin = mysql-bin
relay-log = mysql-relay
server-id= 200
27
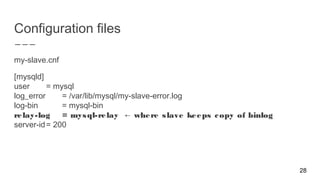
Configuration files
my-slave.cnf
[mysqld]
user = mysql
log_error = /var/lib/mysql/my-slave-error.log
log-bin = mysql-bin
relay-log = mysql-relay where slave keeps copy of binlog←
server-id= 200
28
Configuration files
my-slave.cnf
[mysqld]
user = mysql
log_error = /var/lib/mysql/my-slave-error.log
log-bin = mysql-bin
relay-log = mysql-relay
server-id = 200 unique ID←
29
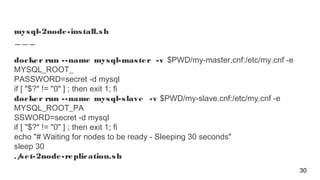
mysql-2node-install.sh
docker run --name mysql-master -v $PWD/my-master.cnf:/etc/my.cnf -e
MYSQL_ROOT_
PASSWORD=secret -d mysql
if [ "$?" != "0" ] ; then exit 1; fi
docker run --name mysql-slave -v $PWD/my-slave.cnf:/etc/my.cnf -e
MYSQL_ROOT_PA
SSWORD=secret -d mysql
if [ "$?" != "0" ] ; then exit 1; fi
echo "# Waiting for nodes to be ready - Sleeping 30 seconds"
sleep 30
./set-2node-replication.sh
30
Run ./mysql-2node-install.sh
Demo
31
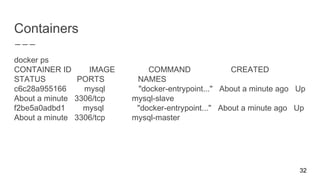
Containers
docker ps
CONTAINER ID IMAGE COMMAND CREATED
STATUS PORTS NAMES
c6c28a955166 mysql "docker-entrypoint..." About a minute ago Up
About a minute 3306/tcp mysql-slave
f2be5a0adbd1 mysql "docker-entrypoint..." About a minute ago Up
About a minute 3306/tcp mysql-master
32
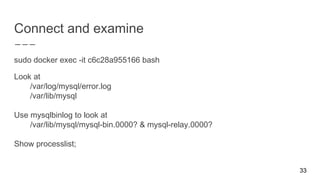
Connect and examine
sudo docker exec -it c6c28a955166 bash
Look at
/var/log/mysql/error.log
/var/lib/mysql
Use mysqlbinlog to look at
/var/lib/mysql/mysql-bin.0000? & mysql-relay.0000?
Show processlist;
33
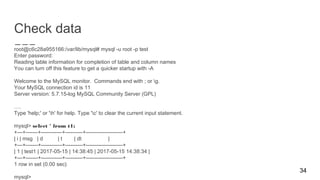
Check data
root@c6c28a955166:/var/lib/mysql# mysql -u root -p test
Enter password:
Reading table information for completion of table and column names
You can turn off this feature to get a quicker startup with -A
Welcome to the MySQL monitor. Commands end with ; or g.
Your MySQL connection id is 11
Server version: 5.7.15-log MySQL Community Server (GPL)
….
Type 'help;' or 'h' for help. Type 'c' to clear the current input statement.
mysql> select * from t1;
+---+-------+------------+----------+---------------------+
| i | msg | d | t | dt |
+---+-------+------------+----------+---------------------+
| 1 | test1 | 2017-05-15 | 14:38:45 | 2017-05-15 14:38:34 |
+---+-------+------------+----------+---------------------+
1 row in set (0.00 sec)
mysql>
34
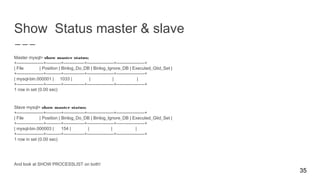
Show Status master & slave
Master mysql> show master status;
+------------------+----------+--------------+------------------+-------------------+
| File | Position | Binlog_Do_DB | Binlog_Ignore_DB | Executed_Gtid_Set |
+------------------+----------+--------------+------------------+-------------------+
| mysql-bin.000001 | 1033 | | | |
+------------------+----------+--------------+------------------+-------------------+
1 row in set (0.00 sec)
Slave mysql> show master status;
+------------------+----------+--------------+------------------+-------------------+
| File | Position | Binlog_Do_DB | Binlog_Ignore_DB | Executed_Gtid_Set |
+------------------+----------+--------------+------------------+-------------------+
| mysql-bin.000003 | 154 | | | |
+------------------+----------+--------------+------------------+-------------------+
1 row in set (0.00 sec)
And look at SHOW PROCESSLIST on both!
35
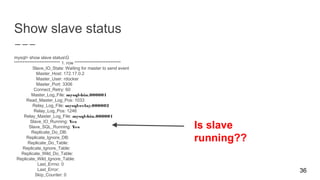
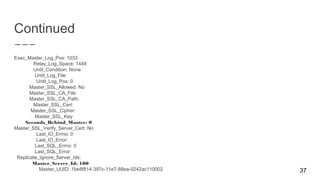
Show slave status
mysql> show slave statusG
*************************** 1. row ***************************
Slave_IO_State: Waiting for master to send event
Master_Host: 172.17.0.2
Master_User: rdocker
Master_Port: 3306
Connect_Retry: 60
Master_Log_File: mysql-bin.000001
Read_Master_Log_Pos: 1033
Relay_Log_File: mysql-relay.000002
Relay_Log_Pos: 1246
Relay_Master_Log_File: mysql-bin.000001
Slave_IO_Running: Yes
Slave_SQL_Running: Yes
Replicate_Do_DB:
Replicate_Ignore_DB:
Replicate_Do_Table:
Replicate_Ignore_Table:
Replicate_Wild_Do_Table:
Replicate_Wild_Ignore_Table:
Last_Errno: 0
Last_Error:
Skip_Counter: 0
36
Is slave
running??
Continued
Exec_Master_Log_Pos: 1033
Relay_Log_Space: 1449
Until_Condition: None
Until_Log_File:
Until_Log_Pos: 0
Master_SSL_Allowed: No
Master_SSL_CA_File:
Master_SSL_CA_Path:
Master_SSL_Cert:
Master_SSL_Cipher:
Master_SSL_Key:
Seconds_Behind_Master: 0
Master_SSL_Verify_Server_Cert: No
Last_IO_Errno: 0
Last_IO_Error:
Last_SQL_Errno: 0
Last_SQL_Error:
Replicate_Ignore_Server_Ids:
Master_Server_Id: 100
Master_UUID: 1be8f814-397c-11e7-88ea-0242ac110002 37
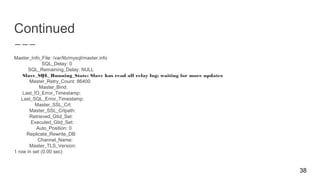
Continued
Master_Info_File: /var/lib/mysql/master.info
SQL_Delay: 0
SQL_Remaining_Delay: NULL
Slave_SQL_Running_State: Slave has read all relay log; waiting for more updates
Master_Retry_Count: 86400
Master_Bind:
Last_IO_Error_Timestamp:
Last_SQL_Error_Timestamp:
Master_SSL_Crl:
Master_SSL_Crlpath:
Retrieved_Gtid_Set:
Executed_Gtid_Set:
Auto_Position: 0
Replicate_Rewrite_DB:
Channel_Name:
Master_TLS_Version:
1 row in set (0.00 sec)
38
set-2node-replication.sh
Explore file
BTW: ./remove-2node.sh
39
Setup Work Or things replication really, really
needs!
40
Now that you know that you know
who it works it is time to expand the
knowledge you know.
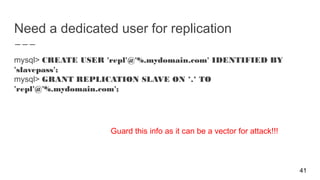
Need a dedicated user for replication
mysql> CREATE USER 'repl'@'%.mydomain.com' IDENTIFIED BY
'slavepass';
mysql> GRANT REPLICATION SLAVE ON *.* TO
'repl'@'%.mydomain.com';
41
Guard this info as it can be a vector for attack!!!
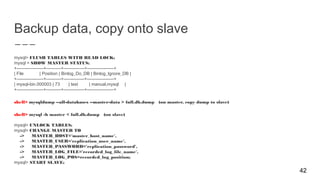
Backup data, copy onto slave
mysql> FLUSH TABLES WITH READ LOCK;
mysql > SHOW MASTER STATUS;
+------------------+----------+--------------+------------------+
| File | Position | Binlog_Do_DB | Binlog_Ignore_DB |
+------------------+----------+--------------+------------------+
| mysql-bin.000003 | 73 | test | manual,mysql |
+------------------+----------+--------------+------------------+
shell> mysqldump --all-databases --master-data > full.db.dump (on master, copy dump to slave)
shell> mysql -h master < full.db.dump (on slave)
mysql> UNLOCK TABLES;
mysql> CHANGE MASTER TO
-> MASTER_HOST='master_host_name',
-> MASTER_USER='replication_user_name',
-> MASTER_PASSWORD='replication_password',
-> MASTER_LOG_FILE='recorded_log_file_name',
-> MASTER_LOG_POS=recorded_log_position;
mysql> START SLAVE;
42
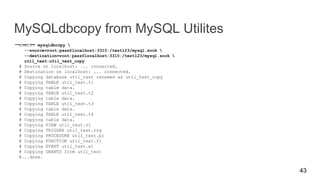
MySQLdbcopy from MySQL Utilites
shell> mysqldbcopy 
--source=root:pass@localhost:3310:/test123/mysql.sock 
--destination=root:pass@localhost:3310:/test123/mysql.sock 
util_test:util_test_copy
# Source on localhost: ... connected.
# Destination on localhost: ... connected.
# Copying database util_test renamed as util_test_copy
# Copying TABLE util_test.t1
# Copying table data.
# Copying TABLE util_test.t2
# Copying table data.
# Copying TABLE util_test.t3
# Copying table data.
# Copying TABLE util_test.t4
# Copying table data.
# Copying VIEW util_test.v1
# Copying TRIGGER util_test.trg
# Copying PROCEDURE util_test.p1
# Copying FUNCTION util_test.f1
# Copying EVENT util_test.e1
# Copying GRANTS from util_test
#...done.
43
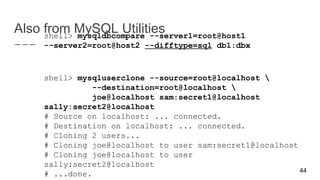
Also from MySQL Utilitiesshell> mysqldbcompare --server1=root@host1
--server2=root@host2 --difftype=sql db1:dbx
shell> mysqluserclone --source=root@localhost 
--destination=root@localhost 
joe@localhost sam:secret1@localhost
sally:secret2@localhost
# Source on localhost: ... connected.
# Destination on localhost: ... connected.
# Cloning 2 users...
# Cloning joe@localhost to user sam:secret1@localhost
# Cloning joe@localhost to user
sally:secret2@localhost
# ...done. 44
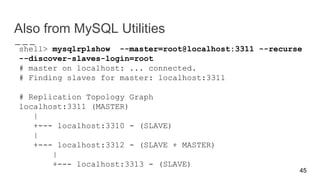
Also from MySQL Utilities
shell> mysqlrplshow --master=root@localhost:3311 --recurse
--discover-slaves-login=root
# master on localhost: ... connected.
# Finding slaves for master: localhost:3311
# Replication Topology Graph
localhost:3311 (MASTER)
|
+--- localhost:3310 - (SLAVE)
|
+--- localhost:3312 - (SLAVE + MASTER)
|
+--- localhost:3313 - (SLAVE)
45
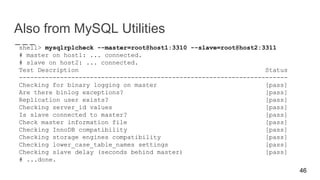
Also from MySQL Utilities
shell> mysqlrplcheck --master=root@host1:3310 --slave=root@host2:3311
# master on host1: ... connected.
# slave on host2: ... connected.
Test Description Status
------------------------------------------------------------------------
Checking for binary logging on master [pass]
Are there binlog exceptions? [pass]
Replication user exists? [pass]
Checking server_id values [pass]
Is slave connected to master? [pass]
Check master information file [pass]
Checking InnoDB compatibility [pass]
Checking storage engines compatibility [pass]
Checking lower_case_table_names settings [pass]
Checking slave delay (seconds behind master) [pass]
# ...done.
46
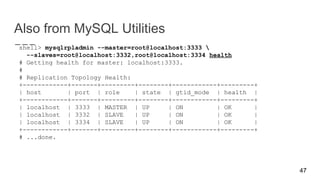
Also from MySQL Utilities
shell> mysqlrpladmin --master=root@localhost:3333 
--slaves=root@localhost:3332,root@localhost:3334 health
# Getting health for master: localhost:3333.
#
# Replication Topology Health:
+------------+-------+---------+--------+------------+---------+
| host | port | role | state | gtid_mode | health |
+------------+-------+---------+--------+------------+---------+
| localhost | 3333 | MASTER | UP | ON | OK |
| localhost | 3332 | SLAVE | UP | ON | OK |
| localhost | 3334 | SLAVE | UP | ON | OK |
+------------+-------+---------+--------+------------+---------+
# ...done.
47
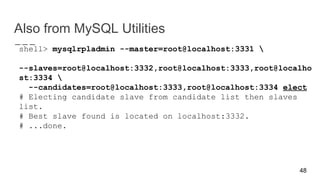
Also from MySQL Utilities
shell> mysqlrpladmin --master=root@localhost:3331 
--slaves=root@localhost:3332,root@localhost:3333,root@localho
st:3334 
--candidates=root@localhost:3333,root@localhost:3334 elect
# Electing candidate slave from candidate list then slaves
list.
# Best slave found is located on localhost:3332.
# ...done.
48
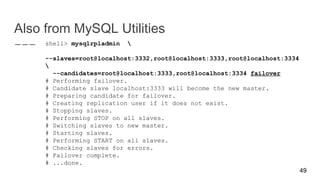
Also from MySQL Utilities
shell> mysqlrpladmin 
--slaves=root@localhost:3332,root@localhost:3333,root@localhost:3334

--candidates=root@localhost:3333,root@localhost:3334 failover
# Performing failover.
# Candidate slave localhost:3333 will become the new master.
# Preparing candidate for failover.
# Creating replication user if it does not exist.
# Stopping slaves.
# Performing STOP on all slaves.
# Switching slaves to new master.
# Starting slaves.
# Performing START on all slaves.
# Checking slaves for errors.
# Failover complete.
# ...done.
49
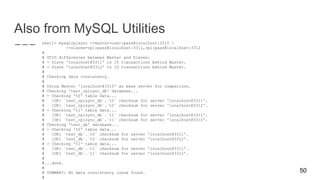
Also from MySQL Utilities
shell> mysqlrplsync --master=user:pass@localhost:3310 
--slaves=rpl:pass@localhost:3311,rpl:pass@localhost:3312
#
# GTID differences between Master and Slaves:
# - Slave 'localhost@3311' is 15 transactions behind Master.
# - Slave 'localhost@3312' is 12 transactions behind Master.
#
# Checking data consistency.
#
# Using Master 'localhost@3310' as base server for comparison.
# Checking 'test_rplsync_db' database...
# - Checking 't0' table data...
# [OK] `test_rplsync_db`.`t0` checksum for server 'localhost@3311'.
# [OK] `test_rplsync_db`.`t0` checksum for server 'localhost@3312'.
# - Checking 't1' table data...
# [OK] `test_rplsync_db`.`t1` checksum for server 'localhost@3311'.
# [OK] `test_rplsync_db`.`t1` checksum for server 'localhost@3312'.
# Checking 'test_db' database...
# - Checking 't0' table data...
# [OK] `test_db`.`t0` checksum for server 'localhost@3311'.
# [OK] `test_db`.`t0` checksum for server 'localhost@3312'.
# - Checking 't1' table data...
# [OK] `test_db`.`t1` checksum for server 'localhost@3311'.
# [OK] `test_db`.`t1` checksum for server 'localhost@3312'.
#
#...done.
#
# SUMMARY: No data consistency issue found.
#
50
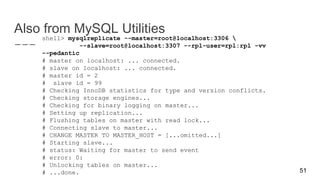
Also from MySQL Utilities
shell> mysqlreplicate --master=root@localhost:3306 
--slave=root@localhost:3307 --rpl-user=rpl:rpl -vv
--pedantic
# master on localhost: ... connected.
# slave on localhost: ... connected.
# master id = 2
# slave id = 99
# Checking InnoDB statistics for type and version conflicts.
# Checking storage engines...
# Checking for binary logging on master...
# Setting up replication...
# Flushing tables on master with read lock...
# Connecting slave to master...
# CHANGE MASTER TO MASTER_HOST = [...omitted...]
# Starting slave...
# status: Waiting for master to send event
# error: 0:
# Unlocking tables on master...
# ...done. 51
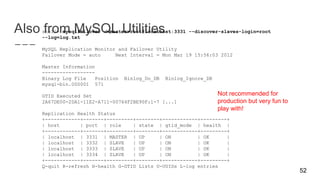
Also from MySQL Utilitiesshell> mysqlfailover --master=root@localhost:3331 --discover-slaves-login=root
--log=log.txt
MySQL Replication Monitor and Failover Utility
Failover Mode = auto Next Interval = Mon Mar 19 15:56:03 2012
Master Information
------------------
Binary Log File Position Binlog_Do_DB Binlog_Ignore_DB
mysql-bin.000001 571
GTID Executed Set
2A67DE00-2DA1-11E2-A711-00764F2BE90F:1-7 [...]
Replication Health Status
+------------+-------+---------+--------+------------+---------+
| host | port | role | state | gtid_mode | health |
+------------+-------+---------+--------+------------+---------+
| localhost | 3331 | MASTER | UP | ON | OK |
| localhost | 3332 | SLAVE | UP | ON | OK |
| localhost | 3333 | SLAVE | UP | ON | OK |
| localhost | 3334 | SLAVE | UP | ON | OK |
+------------+-------+---------+--------+------------+---------+
Q-quit R-refresh H-health G-GTID Lists U-UUIDs L-log entries
52
Not recommended for
production but very fun to
play with!
Also from MySQL Utilities
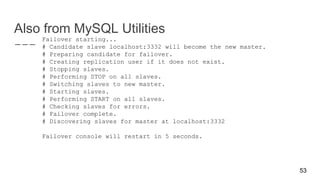
Failover starting...
# Candidate slave localhost:3332 will become the new master.
# Preparing candidate for failover.
# Creating replication user if it does not exist.
# Stopping slaves.
# Performing STOP on all slaves.
# Switching slaves to new master.
# Starting slaves.
# Performing START on all slaves.
# Checking slaves for errors.
# Failover complete.
# Discovering slaves for master at localhost:3332
Failover console will restart in 5 seconds.
53
A Peek At The Future
https://youtu.be/8coqFGEKOWw
54
Global Transaction Identifiers -- GTID
Easier to
use
No looking for
logfile offsets
Can Be
Automated
Faster to
setup
55
Global Transaction Identifiers
56
With GTIDs, each transaction can be identified and tracked as it is committed on the originating server
and applied by any slaves. This means that it is not necessary when using GTIDs to refer to log files or
positions within those files when starting a new slave or failing over to a new master, which greatly
simplifies these tasks. Because GTID-based replication is completely transaction-based, it is simple to
determine whether masters and slaves are consistent. As long as all transactions committed on a master
are also committed on a slave, consistency between the two is guaranteed. You can use either
statement-based or row-based replication with GTIDs; however, for best results, we recommend that you
use the row-based format.
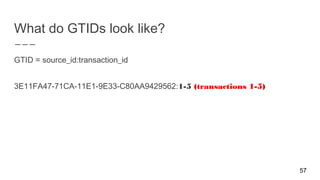
What do GTIDs look like?
GTID = source_id:transaction_id
3E11FA47-71CA-11E1-9E33-C80AA9429562:1-5 (transactions 1-5)
57
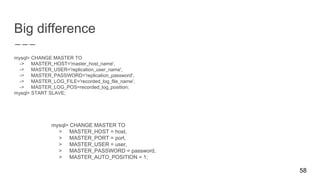
Big difference
mysql> CHANGE MASTER TO
-> MASTER_HOST='master_host_name',
-> MASTER_USER='replication_user_name',
-> MASTER_PASSWORD='replication_password',
-> MASTER_LOG_FILE='recorded_log_file_name',
-> MASTER_LOG_POS=recorded_log_position;
mysql> START SLAVE;
58
mysql> CHANGE MASTER TO
> MASTER_HOST = host,
> MASTER_PORT = port,
> MASTER_USER = user,
> MASTER_PASSWORD = password,
> MASTER_AUTO_POSITION = 1;
Optional Exercise
Change simple replication from log files to
GTIDs
59
Optional Options
60
Log files in tables not tables
61
InnoDB crash safe - set relay_log_info_repository and
master_info_repository to TABLE
Group Replication
62
63
Cd group-replication
./gr.sh
./gr_start.sh
./gr_test.sh
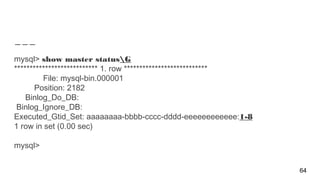
mysql> show master statusG
*************************** 1. row ***************************
File: mysql-bin.000001
Position: 2182
Binlog_Do_DB:
Binlog_Ignore_DB:
Executed_Gtid_Set: aaaaaaaa-bbbb-cccc-dddd-eeeeeeeeeeee:1-8
1 row in set (0.00 sec)
mysql>
64
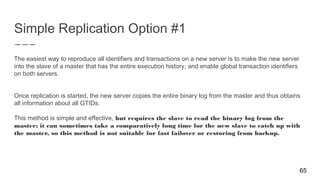
Simple Replication Option #1
The easiest way to reproduce all identifiers and transactions on a new server is to make the new server
into the slave of a master that has the entire execution history, and enable global transaction identifiers
on both servers.
Once replication is started, the new server copies the entire binary log from the master and thus obtains
all information about all GTIDs.
This method is simple and effective, but requires the slave to read the binary log from the
master; it can sometimes take a comparatively long time for the new slave to catch up with
the master, so this method is not suitable for fast failover or restoring from backup.
65
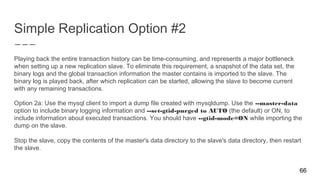
Simple Replication Option #2
Playing back the entire transaction history can be time-consuming, and represents a major bottleneck
when setting up a new replication slave. To eliminate this requirement, a snapshot of the data set, the
binary logs and the global transaction information the master contains is imported to the slave. The
binary log is played back, after which replication can be started, allowing the slave to become current
with any remaining transactions.
Option 2a: Use the mysql client to import a dump file created with mysqldump. Use the --master-data
option to include binary logging information and --set-gtid-purged to AUTO (the default) or ON, to
include information about executed transactions. You should have --gtid-mode=ON while importing the
dump on the slave.
Stop the slave, copy the contents of the master's data directory to the slave's data directory, then restart
the slave.
66
Simple Replication Option #2
Option 2b: If gtid_mode is not ON, restart the server with GTID mode enabled.
Import the binary log using mysqlbinlog, with the --read-from-remote-server and --read-from-
remote-master options.
Copy the master's binary log files to the slave. You can make copies from the slave using mysqlbinlog
--read-from-remote-server --raw. These can be read into the slave in either of the following ways:
Update the slave's binlog.index file to point to the copied log files. Then execute a CHANGE MASTER
TO statement in the mysql client to point to the first log file, and START SLAVE to read them.
Use mysqlbinlog > file (without the --raw option) to export the binary log files to SQL files that can be
processed by the mysql client.
67
GTID Restrictions
Need to know!
68
GTID Restrictions
Because GTID-based replication is dependent on transactions, some features
otherwise available in MySQL are not supported when using it. This section
provides information about restrictions on and limitations of replication with GTIDs.
No MyISAM, use InnoDB.
69
GTID Restrictions
CREATE TABLE ... SELECT statements. CREATE TABLE ... SELECT is not safe for statement-based
replication. When using row-based replication, this statement is actually logged as two separate events—
one for the creation of the table, and another for the insertion of rows from the source table into the new
table just created. When this statement is executed within a transaction, it is possible in some cases for
these two events to receive the same transaction identifier, which means that the transaction containing
the inserts is skipped by the slave. Therefore, CREATE TABLE ... SELECT is not supported when using
GTID-based replication.
Temporary tables. CREATE TEMPORARY TABLE and DROP TEMPORARY TABLE statements are not
supported inside transactions when using GTIDs (that is, when the server was started with the
--enforce-gtid-consistency option). It is possible to use these statements with GTIDs enabled, but only
outside of any transaction, and only withautocommit=1.
70
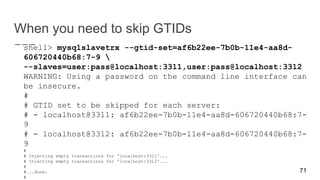
When you need to skip GTIDs
shell> mysqlslavetrx --gtid-set=af6b22ee-7b0b-11e4-aa8d-
606720440b68:7-9 
--slaves=user:pass@localhost:3311,user:pass@localhost:3312
WARNING: Using a password on the command line interface can
be insecure.
#
# GTID set to be skipped for each server:
# - localhost@3311: af6b22ee-7b0b-11e4-aa8d-606720440b68:7-
9
# - localhost@3312: af6b22ee-7b0b-11e4-aa8d-606720440b68:7-
9
#
# Injecting empty transactions for 'localhost:3311'...
# Injecting empty transactions for 'localhost:3312'...
#
#...done.
#
71
SBR, RBR, &
MBR
72
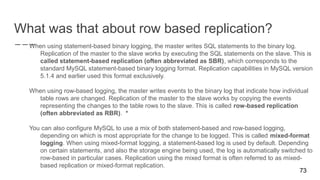
What was that about row based replication?
When using statement-based binary logging, the master writes SQL statements to the binary log.
Replication of the master to the slave works by executing the SQL statements on the slave. This is
called statement-based replication (often abbreviated as SBR), which corresponds to the
standard MySQL statement-based binary logging format. Replication capabilities in MySQL version
5.1.4 and earlier used this format exclusively.
When using row-based logging, the master writes events to the binary log that indicate how individual
table rows are changed. Replication of the master to the slave works by copying the events
representing the changes to the table rows to the slave. This is called row-based replication
(often abbreviated as RBR). *
You can also configure MySQL to use a mix of both statement-based and row-based logging,
depending on which is most appropriate for the change to be logged. This is called mixed-format
logging. When using mixed-format logging, a statement-based log is used by default. Depending
on certain statements, and also the storage engine being used, the log is automatically switched to
row-based in particular cases. Replication using the mixed format is often referred to as mixed-
based replication or mixed-format replication.
73
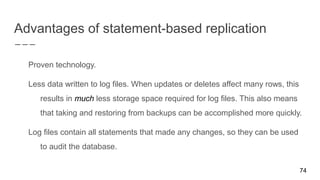
Advantages of statement-based replication
Proven technology.
Less data written to log files. When updates or deletes affect many rows, this
results in much less storage space required for log files. This also means
that taking and restoring from backups can be accomplished more quickly.
Log files contain all statements that made any changes, so they can be used
to audit the database.
74
Disadvantages of statement-based replication
Statements that are unsafe for SBR. Not all statements which modify data (such as INSERT
DELETE, UPDATE, and REPLACE statements) can be replicated using statement-based
replication. Any nondeterministic behavior is difficult to replicate when using statement-based
replication. Examples of such Data Modification Language (DML) statements include the following:
A statement that depends on a UDF or stored program that is nondeterministic, since the
value returned by such a UDF or stored program or depends on factors other than the
parameters supplied to it. (Row-based replication, however, simply replicates the value
returned by the UDF or stored program, so its effect on table rows and data is the same
on both the master and slave.)
DELETE and UPDATE statements that use a LIMIT clause without an ORDER BY are
nondeterministic. Deterministic UDFs must be applied on the slaves.
75
Disadvantages of statement-based replication
Statements using any of the following functions cannot be replicated properly
using statement-based replication:
 LOAD_FILE()
 UUID(), UUID_SHORT()
 USER()
 FOUND_ROWS()
 SYSDATE() (unless both the master and the slave are started with the --sysdate-is-now option)
 GET_LOCK()
 IS_FREE_LOCK()
 IS_USED_LOCK() 76
Disadvantages of statement-based replication
Statements that cannot be replicated correctly using statement-based replication are logged with a
warning like the one shown here:
[Warning] Statement is not safe to log in statement format.
A similar warning is also issued to the client in such cases. The client can display it using
SHOW WARNINGS.
INSERT ... SELECT requires a greater number of row-level locks than with row-based replication.
UPDATE statements that require a table scan (because no index is used in the WHERE clause)
must lock a greater number of rows than with row-based replication.
For InnoDB: An INSERT statement that uses AUTO_INCREMENT blocks other nonconflicting
INSERT statements.
For complex statements, the statement must be evaluated and executed on the slave before the
rows are updated or inserted. With row-based replication, the slave only has to modify the
affected rows, not execute the full statement.
77
Advantages of row-based replication
All changes can be replicated. This is the safest form of replication.
Note
Statements that update the information in the mysql database—such as GRANT, REVOKE and
the manipulation of triggers, stored routines (including stored procedures), and views—are all
replicated to slaves using statement-based replication.
For statements such as CREATE TABLE ... SELECT, a CREATE statement is generated from the
table definition and replicated using statement-based format, while the row insertions are
replicated using row-based format.
Fewer row locks are required on the master, which thus achieves higher concurrency, for the 78
Disadvantages of row-based replication
RBR can generate more data that must be logged. To replicate a DML statement (such as an UPDATE or DELETE
statement), statement-based replication writes only the statement to the binary log. By contrast, row-based
replication writes each changed row to the binary log. If the statement changes many rows, row-based replication
may write significantly more data to the binary log; this is true even for statements that are rolled back. This also
means that making and restoring a backup can require more time. In addition, the binary log is locked for a longer
time to write the data, which may cause concurrency problems. Use binlog_row_image=minimal to reduce the
disadvantage considerably.
Deterministic UDFs that generate large BLOB values take longer to replicate with row-based replication than with
statement-based replication. This is because the BLOBcolumn value is logged, rather than the statement
generating the data.
You cannot see on the slave what statements were received from the master and executed. However, you can see what
data was changed using mysqlbinlog with the options --base64-output=DECODE-ROWS and --verbose.
Alternatively, use the binlog_rows_query_log_events variable, which if enabled adds a Rows_query event with the
statement to mysqlbinlog output when the -vvoption is used.
79
Splits
80
Read / Write Splits
81
Optimal way to scale reads
Easy to setup
Works well, proven model
82
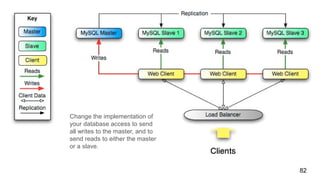
Change the implementation of
your database access to send
all writes to the master, and to
send reads to either the master
or a slave.
83
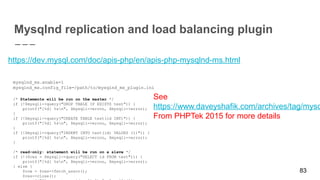
Mysqlnd replication and load balancing plugin
https://dev.mysql.com/doc/apis-php/en/apis-php-mysqlnd-ms.html
mysqlnd_ms.enable=1
mysqlnd_ms.config_file=/path/to/mysqlnd_ms_plugin.ini
/* Statements will be run on the master */
if (!$mysqli->query("DROP TABLE IF EXISTS test")) {
printf("[%d] %sn", $mysqli->errno, $mysqli->error);
}
if (!$mysqli->query("CREATE TABLE test(id INT)")) {
printf("[%d] %sn", $mysqli->errno, $mysqli->error);
}
if (!$mysqli->query("INSERT INTO test(id) VALUES (1)")) {
printf("[%d] %sn", $mysqli->errno, $mysqli->error);
}
/* read-only: statement will be run on a slave */
if (!($res = $mysqli->query("SELECT id FROM test"))) {
printf("[%d] %sn", $mysqli->errno, $mysqli->error);
} else {
$row = $res->fetch_assoc();
$res->close();
See
https://www.daveyshafik.com/archives/tag/mysq
From PHPTek 2015 for more details
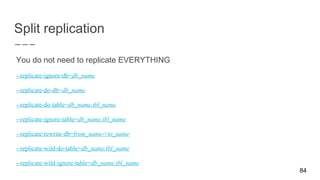
Split replication
You do not need to replicate EVERYTHING
--replicate-ignore-db=db_name
--replicate-do-db=db_name
--replicate-do-table=db_name.tbl_name
--replicate-ignore-table=db_name.tbl_name
--replicate-rewrite-db=from_name->to_name
--replicate-wild-do-table=db_name.tbl_name
--replicate-wild-ignore-table=db_name.tbl_name
84
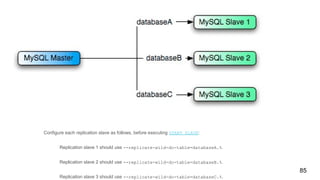
85
Configure each replication slave as follows, before executing START SLAVE:
Replication slave 1 should use --replicate-wild-do-table=databaseA.%.
Replication slave 2 should use --replicate-wild-do-table=databaseB.%.
Replication slave 3 should use --replicate-wild-do-table=databaseC.%.
86
Semi Sync
87
Semisynchronous replication
MySQL replication by default is asynchronous. The master writes events to its binary log but does not know whether or when a slave has retrieved
and processed them. With asynchronous replication, if the master crashes, transactions that it has committed might not have been transmitted to
any slave. Consequently, failover from master to slave in this case may result in failover to a server that is missing transactions relative to the
master.
Semisynchronous replication can be used as an alternative to asynchronous replication:
A slave indicates whether it is semisynchronous-capable when it connects to the master.
If semisynchronous replication is enabled on the master side and there is at least one semisynchronous slave, a thread that performs a
transaction commit on the master blocks and waits until at least one semisynchronous slave acknowledges that it has received all
events for the transaction, or until a timeout occurs.
The slave acknowledges receipt of a transaction's events only after the events have been written to its relay log and flushed to
disk.
If a timeout occurs without any slave having acknowledged the transaction, the master reverts to asynchronous replication. When at least
one semisynchronous slave catches up, the master returns to semisynchronous replication.
Semisynchronous replication must be enabled on both the master and slave sides. If semisynchronous replication is disabled on the
master, or enabled on the master but on no slaves, the master uses asynchronous replication.
As of MySQL 5.7.3, the number of slave acknowledgments the master must receive per transaction before proceeding is configurable
Semisynchronous configuration
Two plugins implement semisynchronous capability. There is one plugin for the master side and one for the slave side.
System variables control plugin behavior. Some examples:
rpl_semi_sync_master_enabled
Controls whether semisynchronous replication is enabled on the master. To enable or disable the plugin, set this variable
to 1 or 0, respectively. The default is 0 (off).
rpl_semi_sync_master_timeout
A value in milliseconds that controls how long the master waits on a commit for acknowledgment from a slave before
timing out and reverting to asynchronous replication. The default value is 10000 (10 seconds).
rpl_semi_sync_slave_enabled
Similar to rpl_semi_sync_master_enabled, but controls the slave plugin.
88
Semisynchronous configuration
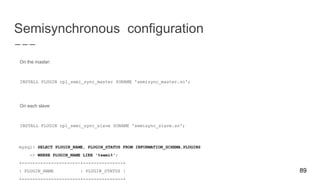
On the master:
INSTALL PLUGIN rpl_semi_sync_master SONAME 'semisync_master.so';
On each slave:
INSTALL PLUGIN rpl_semi_sync_slave SONAME 'semisync_slave.so';
mysql> SELECT PLUGIN_NAME, PLUGIN_STATUS FROM INFORMATION_SCHEMA.PLUGINS
-> WHERE PLUGIN_NAME LIKE '%semi%';
+----------------------+---------------+
| PLUGIN_NAME | PLUGIN_STATUS | 89
Troubleshooting
90
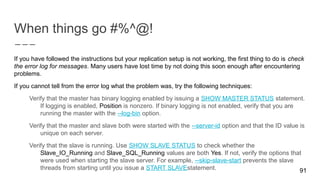
When things go #%^@!
91
If you have followed the instructions but your replication setup is not working, the first thing to do is check
the error log for messages. Many users have lost time by not doing this soon enough after encountering
problems.
If you cannot tell from the error log what the problem was, try the following techniques:
Verify that the master has binary logging enabled by issuing a SHOW MASTER STATUS statement.
If logging is enabled, Position is nonzero. If binary logging is not enabled, verify that you are
running the master with the --log-bin option.
Verify that the master and slave both were started with the --server-id option and that the ID value is
unique on each server.
Verify that the slave is running. Use SHOW SLAVE STATUS to check whether the
Slave_IO_Running and Slave_SQL_Running values are both Yes. If not, verify the options that
were used when starting the slave server. For example, --skip-slave-start prevents the slave
threads from starting until you issue a START SLAVEstatement.
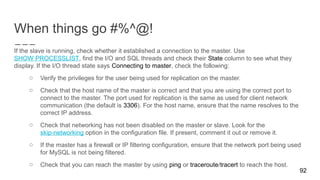
When things go #%^@!
92
If the slave is running, check whether it established a connection to the master. Use
SHOW PROCESSLIST, find the I/O and SQL threads and check their State column to see what they
display. If the I/O thread state says Connecting to master, check the following:
o Verify the privileges for the user being used for replication on the master.
o Check that the host name of the master is correct and that you are using the correct port to
connect to the master. The port used for replication is the same as used for client network
communication (the default is 3306). For the host name, ensure that the name resolves to the
correct IP address.
o Check that networking has not been disabled on the master or slave. Look for the
skip-networking option in the configuration file. If present, comment it out or remove it.
o If the master has a firewall or IP filtering configuration, ensure that the network port being used
for MySQL is not being filtered.
o Check that you can reach the master by using ping or traceroute/tracert to reach the host.
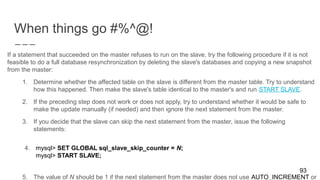
When things go #%^@!
93
If a statement that succeeded on the master refuses to run on the slave, try the following procedure if it is not
feasible to do a full database resynchronization by deleting the slave's databases and copying a new snapshot
from the master:
1. Determine whether the affected table on the slave is different from the master table. Try to understand
how this happened. Then make the slave's table identical to the master's and run START SLAVE.
2. If the preceding step does not work or does not apply, try to understand whether it would be safe to
make the update manually (if needed) and then ignore the next statement from the master.
3. If you decide that the slave can skip the next statement from the master, issue the following
statements:
4. mysql> SET GLOBAL sql_slave_skip_counter = N;
mysql> START SLAVE;
5. The value of N should be 1 if the next statement from the master does not use AUTO_INCREMENT or
Group Replication
Master Master
94
Group Replication
Group Replication enables you to create fault-tolerant systems with redundancy by replicating the system state throughout a set
of servers. Consequently, even if some of the servers fail, as long it is not all or a majority, the system is still available, and all it
could have degraded performance or scalability, it is still available. Server failures are isolated and independent. They are
tracked by a group membership service which relies on a distributed failure detector that is able to signal when any servers leave
the group, either voluntarily or due to an unexpected halt. There is a distributed recovery procedure to ensure that when servers
join the group they are brought up to date automatically. There is no need for server fail-over, and the multi-master update
everywhere nature ensures that not even updates are blocked in the event of a single server failure. Therefore MySQL Group
Replication guarantees that the database service is continuously available.
It is important to understand that although the database service is available, in the event of a server crash, those clients
connected to it must be redirected, or failed over, to a different server. This is not something Group Replication attempts to
resolve. A connector, load balancer, router, or some form of middleware are more suitable to deal with this issue.
To summarize, MySQL Group Replication provides a highly available, highly elastic, dependable MySQL service.
95
Examples of Use Case Scenarios
The following examples are typical use cases for Group Replication.
Elastic Replication - Environments that require a very fluid replication infrastructure, where the number
of servers has to grow or shrink dynamically and with as few side-effects as possible. For instance,
database services for the cloud.
Highly Available Shards - Sharding is a popular approach to achieve write scale-out. Use MySQL
Group Replication to implement highly available shards, where each shard maps to a replication
group.
Alternative to Master-Slave replication - In certain situations, using a single master server makes it a
single point of contention. Writing to an entire group may prove more scalable under certain
circumstances.
Autonomic Systems - Additionally, you can deploy MySQL Group Replication purely for the automation
that is built into the replication protocol (described already in this and previous chapters).
96
Failure Detection
There is a failure detection mechanism provided that is able to find and report which servers are silent and as such
assumed to be dead. At a high level, the failure detector is a distributed service that provides information about which
servers may be dead (suspicions). Later if the group agrees that the suspicions are probably true, then the group decides
that a given server has indeed failed. This means that the remaining members in the group take a coordinated decision to
exclude a given member.
Suspicions are triggered when servers go mute. When server A does not receive messages from server B during a given
period, a timeout occurs and a suspicion is raised.
If a server gets isolated from the rest of the group, then it suspects that all others have failed. Being unable to secure
agreement with the group (as it cannot secure a quorum), its suspicion does not have consequences. When a server is
isolated from the group in this way, it is unable to execute any local transactions.
97
Group Membership
MySQL Group Replication relies on a group membership service. This is built into the plugin. It defines which servers are online and
participating in the group. The list of online servers is often referred to as a view. Therefore, every server in the group has a consistent view of
which are the members participating actively in the group at a given moment in time.
Servers have to agree not only on transaction commits, but also which is the current view. Therefore, if servers agree that a new server
becomes part of the group, then the group itself is reconfigured to integrate that server in it, triggering a view change. The opposite also
happens, if a server leaves the group, voluntarily or not, then the group dynamically rearranges its configuration and a view change is
triggered.
Note though that when a member leaves voluntarily, it first initiates a dynamic group reconfiguration. This triggers a procedure, where all
members have to agree on the new view without the leaving server. However, if a member leaves involuntarily (for example it has stopped
unexpectedly or the network connection is down) then the failure detection mechanism realizes this fact and a reconfiguration of the group is
proposed, this one without the failed member. As mentioned this requires agreement from the majority of servers in the group. If the group is
not able to reach agreement (for example it partitioned in such a way that there is no majority of servers online), then the system is not be
able to dynamically change the configuration and as such, blocks to prevent a split-brain situation. Ultimately, this means that the
administrator needs to step in and fix this.
98
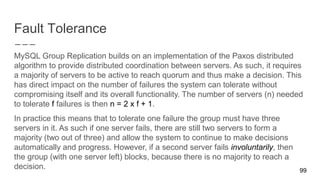
Fault Tolerance
MySQL Group Replication builds on an implementation of the Paxos distributed
algorithm to provide distributed coordination between servers. As such, it requires
a majority of servers to be active to reach quorum and thus make a decision. This
has direct impact on the number of failures the system can tolerate without
compromising itself and its overall functionality. The number of servers (n) needed
to tolerate f failures is then n = 2 x f + 1.
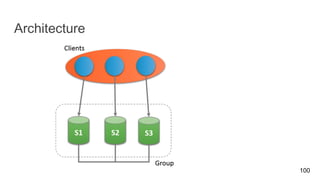
In practice this means that to tolerate one failure the group must have three
servers in it. As such if one server fails, there are still two servers to form a
majority (two out of three) and allow the system to continue to make decisions
automatically and progress. However, if a second server fails involuntarily, then
the group (with one server left) blocks, because there is no majority to reach a
decision. 99
Architecture
100