Explore CPU scheduling fundamentals, challenges, and how sched_ext enables customizable, efficient scheduling via BPF in Linux kernels, improving workload management and system performance.
System SWE @MTK
GitHub: EricccTaiwan
LinkedIn: Eric Chou
MS @ NCKUEE
GitHub: charliechiou
LinkedIn: Po-Ying Chiu
聲明:以下內容為個人研究分享,與工作無關,不代表任職公司立場。 2
3.
Outline
● What isCPU scheduling
● Why sched_ext
● How sched_ext
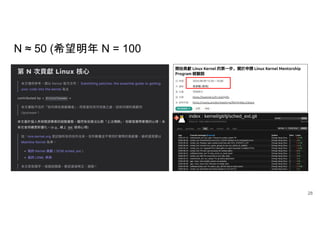
● 第 N 次貢獻 Linux 核心 : link
3
4.
Outline
● What isCPU scheduling
● Why sched_ext
● How sched_ext
● 第 N 次貢獻 Linux 核心 : link
4
5.
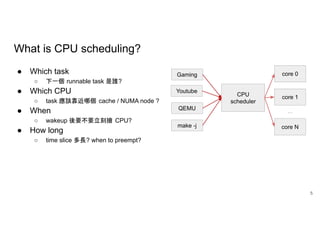
What is CPUscheduling?
● Which task
○ 下一個 runnable task 是誰?
● Which CPU
○ task 應該靠近哪個 cache / NUMA node ?
● When
○ wakeup 後要不要立刻搶 CPU?
● How long
○ time slice 多長? when to preempt?
5
6.
What is CPUscheduling?
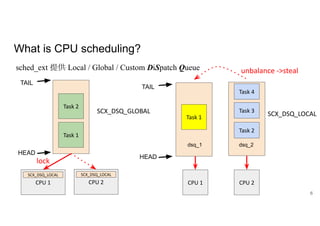
sched_ext 提供 Local / Global / Custom DiSpatch Queue
6
CPU 2 CPU 1 CPU 2
Task 2
Task 1
Task 1
Task 2
SCX_DSQ_GLOBAL SCX_DSQ_LOCAL
dsq_1 dsq_2
HEAD
TAIL
HEAD
TAIL
Task 3
Task 4
unbalance ->steal
lock
SCX_DSQ_LOCAL
CPU 1
SCX_DSQ_LOCAL
7.
Outline
● What isCPU scheduling
● Why sched_ext
● How sched_ext
● 第 N 次貢獻 Linux 核心 : link
7
8.
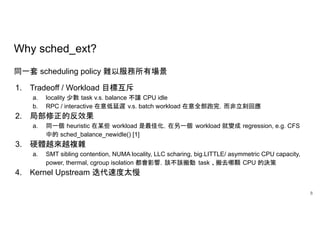
Why sched_ext?
同一套 schedulingpolicy 難以服務所有場景
1. Tradeoff / Workload 目標互斥
a. locality 少數 task v.s. balance 不讓 CPU idle
b. RPC / interactive 在意低延遲 v.s. batch workload 在意全部跑完,而非立刻回應
2. 局部修正的反效果
a. 同一個 heuristic 在某些 workload 是最佳化,在另一個 workload 就變成 regression, e.g. CFS
中的 sched_balance_newidle() [1]
3. 硬體越來越複雜
a. SMT sibling contention, NUMA locality, LLC scharing, big.LITTLE/ asymmetric CPU capacity,
power, thermal, cgroup isolation 都會影響,該不該搬動 task 、搬去哪顆 CPU 的決策
4. Kernel Upstream 迭代速度太慢
8
9.
9
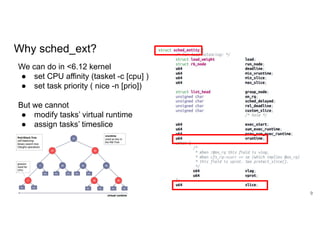
We can doin <6.12 kernel
● set CPU affinity (tasket -c [cpu] )
● set task priority ( nice -n [prio])
But we cannot
● modify tasks’ virtual runtime
● assign tasks’ timeslice
Why sched_ext?
10.
Outline
● What isCPU scheduling
● Why sched_ext
● How sched_ext
● 第 N 次貢獻 Linux 核心 : link
10
11.
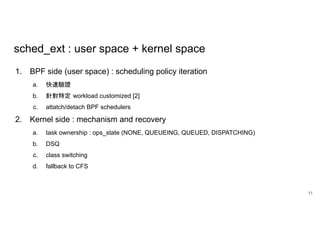
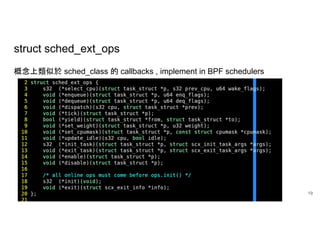
sched_ext : userspace + kernel space
1. BPF side (user space) : scheduling policy iteration
a. 快速驗證
b. 針對特定 workload customized [2]
c. attatch/detach BPF schedulers
2. Kernel side : mechanism and recovery
a. task ownership : ops_state (NONE, QUEUEING, QUEUED, DISPATCHING)
b. DSQ
c. class switching
d. fallback to CFS
11
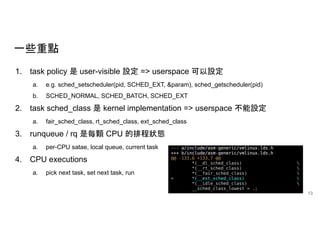
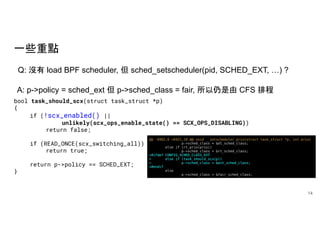
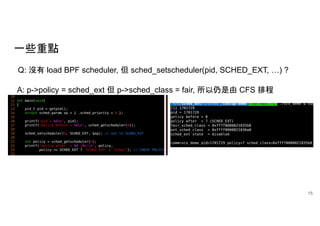
一些重點
1. task policy是 user-visible 設定 => userspace 可以設定
a. e.g. sched_setscheduler(pid, SCHED_EXT, ¶m), sched_getscheduler(pid)
b. SCHED_NORMAL, SCHED_BATCH, SCHED_EXT
2. task sched_class 是 kernel implementation => userspace 不能設定
a. fair_sched_class, rt_sched_class, ext_sched_class
3. runqueue / rq 是每顆 CPU 的排程狀態
a. per-CPU satae, local queue, current task
4. CPU executions
a. pick next task, set next task, run
13
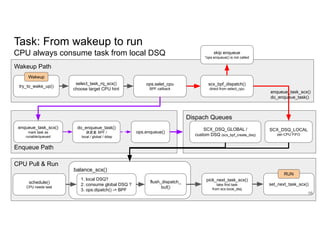
try_to_wake_up()
select_task_rq_scx()
choose target CPUhint
ops.selet_cpu
BPF callback
skip enqueue
*ops.enqueue() is not called
Wakeup Path
scx_bpf_dispatch()
direct from select_cpu
Enqueue Path
enqueue_task_scx()
mark task as
runable/queued
ops.enqueue()
Dispach Queues
SCX_DSQ_GLOBAL /
custom DSQ (scx_bpf_create_dsq)
SCX_DSQ_LOCAL
per-CPU FIFO
CPU Pull & Run
schedule()
CPU needs task
balance_scx()
1. local DSQ?
2. consume global DSQ ?
3. ops.dipatch() -> BPF
flush_dispatch_
buf()
pick_next_task_scx()
take first task
from scx.local_dsq
set_next_task_scx()
16
Wakeup
RUN
do_enqueue_task()
決定走 BPF /
local / global / ddsp
Task: From wakeup to run
CPU always consume task from local DSQ
enqueue_task_scx()
do_enqueue_task()
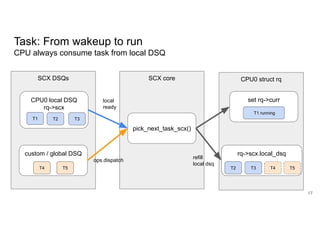
17.
Task: From wakeupto run
CPU always consume task from local DSQ
SCX DSQs
CPU0 local DSQ
rq->scx
custom / global DSQ
T1 T2 T3
T4 T5
SCX core
pick_next_task_scx()
local
ready
ops.dispatch
CPU0 struct rq
set rq->curr
T1 running
rq->scx.local_dsq
T2 T3 T4 T5
refill
local dsq
17
18.
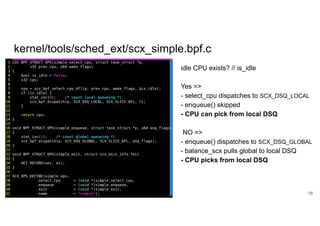
kernel/tools/sched_ext/scx_simple.bpf.c
18
idle CPU exists?// is_idle
Yes =>
- select_cpu dispatches to SCX_DSQ_LOCAL
- enqueue() skipped
- CPU can pick from local DSQ
NO =>
- enqueue() dispatches to SCX_DSQ_GLOBAL
- balance_scx pulls global to local DSQ
- CPU picks from local DSQ
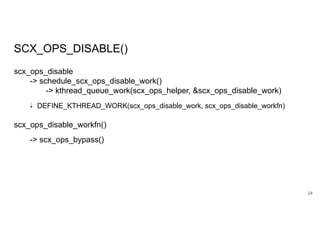
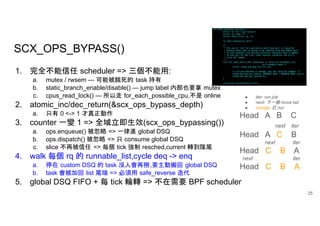
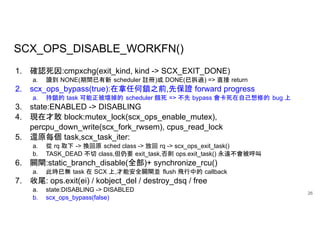
SCX_OPS_BYPASS()
25
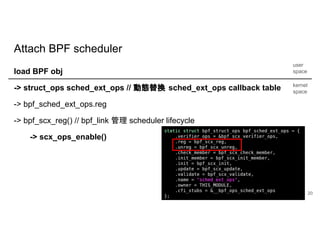
1. 完全不能信任 scheduler=> 三個不能用:
a. mutex / rwsem — 可能被餓死的 task 持有
b. static_branch_enable/disable() — jump label 內部也要拿 mutex
c. cpus_read_lock() — 所以走 for_each_possible_cpu,不是 online
2. atomic_inc/dec_return(&scx_ops_bypass_depth)
a. 只有 0 <-> 1 才真正動作
3. counter 一變 1 => 全域立即生效(scx_ops_bypassing())
a. ops.enqueue() 被忽略 => 一律進 global DSQ
b. ops.dispatch() 被忽略 => 只 consume global DSQ
c. slice 不再被信任 => 每個 tick 強制 resched,current 轉到隊尾
4. walk 每個 rq 的 runnable_list,cycle deq -> enq
a. 停在 custom DSQ 的 task 沒人會再撈,要主動搬回 global DSQ
b. task 會被加回 list 尾端 => 必須用 safe_reverse 迭代
5. global DSQ FIFO + 每 tick 輪轉 => 不在需要 BPF scheduler
● iter: run job
● next: 下一個 move tail
● orange: 已 run
Head A B C
next iter
Head A C B
next iter
Head C B A
next iter
Head C B A
 Most read
 Most read
 Most read