Integrating DuckDB for High-Performance Analytics Inside MySQL Systems
Explore embedding DuckDB in MySQL to enable integrated HTAP with efficient columnar analytics, batch processing, crash recovery, and compatibility, enhancing MySQL's OLTP with fast, compressed OLAP capabilities.
Integrating DuckDB for High-Performance Analytics Inside MySQL Systems
1.
MYSQL SUMMIT ·ENGINEERING STORY
When MySQL
Meets DuckDB
Embedding DuckDB in MySQL
Zongzhi Chen
MYSQL SUMMIT · AUGUST 2026
2.
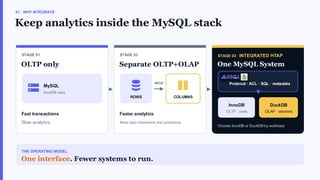
01 · WHYINTEGRATE
Keep analytics inside the MySQL stack
STAGE 01
OLTP only
MySQL
InnoDB rows
Fast transactions
Slow analytics
STAGE 02
Separate OLTP+OLAP
ROWS
MOVE
COLUMNS
Faster analytics
More data movement and operations
STAGE 03 · INTEGRATED HTAP
One MySQL System
InnoDB
OLTP · rows
DuckDB
OLAP · columns
THE OPERATING MODEL
One interface. Fewer systems to run.
Protocol · ACL · SQL · metadata
3.
02 · THEENGINE ADVANTAGE
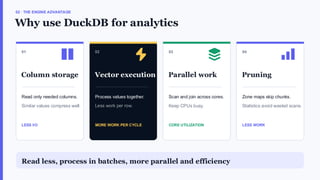
Why use DuckDB for analytics
01
Column storage
Read only needed columns.
Similar values compress well.
LESS I/O
Vector execution
Process values together.
MORE WORK PER CYCLE
03
Parallel work
Scan and join across cores.
Keep CPUs busy.
CORE UTILIZATION
04
Pruning
Zone maps skip chunks.
Statistics avoid wasted scans.
LESS WORK
Read less, process in batches, more parallel and efficiency
4.
03 · EVIDENCEFIRST
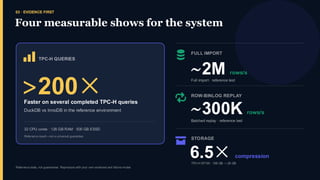
Four measurable shows for the system
>200×
Faster on several completed TPC-H queries
~2M rows/s
~300K rows/s
6.5× compression
5.
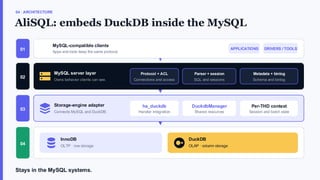
04 · ARCHITECTURE
AliSQL:embeds DuckDB inside the MySQL
01
MySQL-compatible clients
Apps and tools keep the same protocol.
APPLICATIONS DRIVERS / TOOLS
02
MySQL server layer Protocol + ACL Parser + session Metadata + binlog
03
Storage-engine adapter
Connects MySQL and DuckDB.
ha_duckdb
Handler integration
DuckdbManager
Shared resources
Per-THD context
Session and batch state
04
InnoDB
OLTP · row storage
DuckDB
OLAP · column storage
Stays in the MySQL systems.
6.
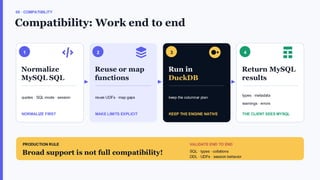
05 · COMPATIBILITY
Compatibility:Work end to end
1
Normalize
MySQL SQL
quotes · SQL mode · session
NORMALIZE FIRST
2
Reuse or map
functions
reuse UDFs · map gaps
MAKE LIMITS EXPLICIT
3
Run in
DuckDB
keep the columnar plan
KEEP THE ENGINE NATIVE
4
Return MySQL
results
types · metadata
warnings · errors
THE CLIENT SEES MYSQL
PRODUCTION RULE
Broad support is not full compatibility!
VALIDATE END TO END
SQL · types · collations
DDL · UDFs · session behavior
7.
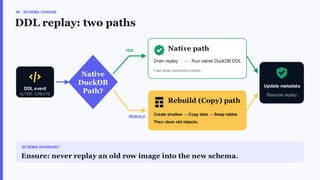
06 · SCHEMACHANGE
DDL replay: two paths
DDL event
Native
DuckDB
Path?
YES
REBUILD
Native path
Drain replay → Run native DuckDB DDL
Fast when semantics match.
Rebuild (Copy) path
Create shadow → Copy data → Swap tables
Then clean old objects.
Update metadata
SCHEMA INVARIANT
Ensure: never replay an old row image into the new schema.
8.
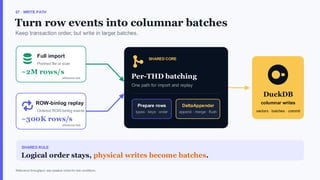
07 · WRITEPATH
Turn row events into columnar batches
Keep transaction order, but write in larger batches.
Full import
Planned file or scan
~2M rows/s
reference test
ROW-binlog replay
Ordered ROW-binlog events
~300K rows/s
reference test
SHARED CORE
Per-THD batching
Prepare rows DeltaAppender
DuckDB
columnar writes
vectors · batches · commit
SHARED RULE
Logical order stays, physical writes become batches.
Reference throughput; see speaker notes for test conditions.
9.
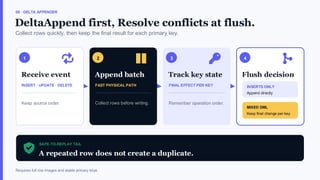
08 · DELTAAPPENDER
DeltaAppend first, Resolve conflicts at flush.
Collect rows quickly, then keep the final result for each primary key.
1
Receive event
INSERT · UPDATE · DELETE
Keep source order.
2
Append batch
FAST PHYSICAL PATH
3
Track key state
FINAL EFFECT PER KEY
Remember operation order.
4
Flush decision
INSERTS ONLY
Append directly
MIXED DML
Keep final change per key
SAFE-TO-REPLAY TAIL
A repeated row does not create a duplicate.
Requires full row images and stable primary keys.
10.
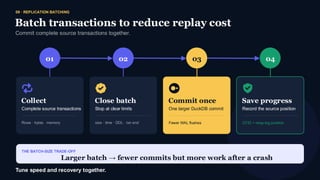
09 · REPLICATIONBATCHING
Batch transactions to reduce replay cost
01
Collect
Complete source transactions
02
Close batch
Stop at clear limits
03
Commit once
One larger DuckDB commit
Fewer WAL flushes
04
Save progress
Record the source position
GTID + relay-log position
THE BATCH-SIZE TRADE-OFF
Larger batch → fewer commits but more work after a crash
Tune speed and recovery together.
11.
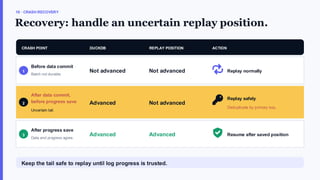
10 · CRASHRECOVERY
Recovery: handle an uncertain replay position.
CRASH POINT DUCKDB REPLAY POSITION ACTION
1
Before data commit
Batch not durable.
Not advanced Not advanced Replay normally
2
After data commit,
before progress save
Uncertain tail.
Advanced Not advanced
Replay safely
Deduplicate by primary key.
3
After progress save
Data and progress agree.
Advanced Advanced Resume after saved position
Keep the tail safe to replay until log progress is trusted.
12.
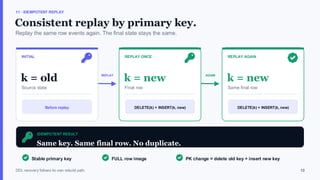
11 · IDEMPOTENTREPLAY
Consistent replay by primary key.
Replay the same row events again. The final state stays the same.
REPLAY AGAIN
INITIAL
k = old
Source state
Before replay
REPLAY ONCE
k = new
Final row
DELETE(k) + INSERT(k, new)
REPLAY AGAIN
k = new
Same final row
DELETE(k) + INSERT(k, new)
IDEMPOTENT RESULT
Same key. Same final row. No duplicate.
Stable primary key FULL row image PK change = delete old key + insert new key
DDL recovery follows its own rebuild path. 10
13.
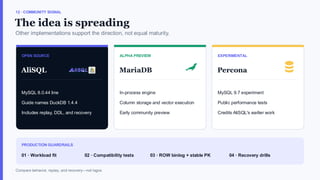
12 · COMMUNITYSIGNAL
The idea is spreading
Other implementations support the direction, not equal maturity.
OPEN SOURCE
AliSQL
MySQL 8.0.44 line
Guide names DuckDB 1.4.4
Includes replay, DDL, and recovery
ALPHA PREVIEW
MariaDB
In-process engine
Column storage and vector execution
Early community preview
EXPERIMENTAL
Percona
MySQL 9.7 experiment
Public performance tests
Credits AliSQL's earlier work
PRODUCTION GUARDRAILS
01 · Workload fit 02 · Compatibility tests 03 · ROW binlog + stable PK 04 · Recovery drills
Compare behavior, replay, and recovery—not logos.
14.
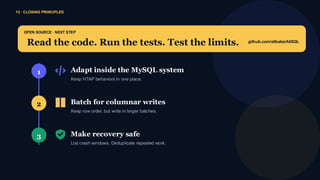
13 · CLOSINGPRINCIPLES
1 Adapt inside the MySQL system
2 Batch for columnar writes
3 Make recovery safe
OPEN SOURCE · NEXT STEP
Read the code. Run the tests. Test the limits. github.com/alibaba/AliSQL