etcd, Patroni, and HAProxy
Inside the 30-Second PostgreSQL Failover Window
How quorum, leader election, and traffic routing behave
in the 30 seconds that actually matter
Manosh Malai · CTO
MyWebinar 51, 2026
About Me
Manosh Malai
CTO, Mydbops
❏ 15+ years of Database experience
❏ Active practitioner of Open Source technologies
❏ Active practitioner of MongoDB,PostgreSQL,
DevOps & DevOpSec Practices
❏ Tech Speaker/Blogger
Why This Talk Matters
1 Primary crashes, but promotion never happens
2 Standby is healthy, but apps still can't write
3 HAProxy keeps sending traffic to the wrong node
4 etcd loses quorum, whole cluster goes read-only
5 "Automatic failover" turns out not to be automatic recovery
HA is not a feature of one tool. It is the emergent behavior of the full stack.
The Mental Model Is Usually Incomplete
What Teams Know
Patroni does failover.
etcd stores state.
HAProxy routes traffic.
What They Don't Know
● What Patroni does when etcd
quorum is lost
● How the leader lock actually expires
● How HAProxy detects role changes
● What happens in the 30-second
window
● Where the delay actually comes from
“If you can't describe the control flow, failover becomes something you observe
not something you engineer.”
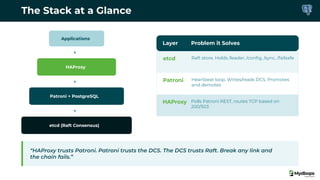
The Stack at a Glance
Applications
▼
HAProxy
▼
Patroni + PostgreSQL
▼
etcd (Raft Consensus)
Layer Problem it Solves
etcd Raft store. Holds /leader, /config, /sync, /failsafe
Patroni Heartbeat loop. Writes/reads DCS. Promotes
and demotes
HAProxy Polls Patroni REST, routes TCP based on
200/503
“HAProxy trusts Patroni. Patroni trusts the DCS. The DCS trusts Raft. Break any link and
the chain fails.”
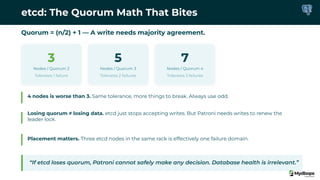
etcd: The Quorum Math That Bites
Quorum = (n/2) + 1 — A write needs majority agreement.
3
Nodes / Quorum 2
Tolerates 1 failure
5
Nodes / Quorum 3
Tolerates 2 failures
7
Nodes / Quorum 4
Tolerates 3 failures
4 nodes is worse than 3. Same tolerance, more things to break. Always use odd.
Losing quorum ≠ losing data. etcd just stops accepting writes. But Patroni needs writes to renew the
leader lock.
Placement matters. Three etcd nodes in the same rack is effectively one failure domain.
“If etcd loses quorum, Patroni cannot safely make any decision. Database health is irrelevant.”
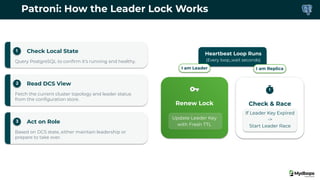
Patroni: How the Leader Lock Works
1 Check Local State
Query PostgreSQL to confirm it's running and healthy.
2 Read DCS View
Fetch the current cluster topology and leader status
from the configuration store.
3 Act on Role
Based on DCS state, either maintain leadership or
prepare to take over.
Heartbeat Loop Runs
(Every loop_wait seconds)
I am Leader
Renew Lock
Update Leader Key
with Fresh TTL
I am Replica
Check & Race
If Leader Key Expired
->
Start Leader Race
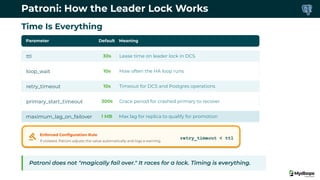
Patroni: How the Leader Lock Works
Parameter Default Meaning
ttl 30s Lease time on leader lock in DCS
loop_wait 10s How often the HA loop runs
retry_timeout 10s Timeout for DCS and Postgres operations
primary_start_timeout 300s Grace period for crashed primary to recover
maximum_lag_on_failover 1 MB Max lag for replica to qualify for promotion
Patroni does not "magically fail over." It races for a lock. Timing is everything.
Time Is Everything
Enforced Configuration Rule
If violated, Patroni adjusts the value automatically and logs a warning.
retry_timeout < ttl
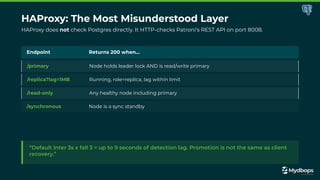
HAProxy: The Most Misunderstood Layer
HAProxy does not check Postgres directly. It HTTP-checks Patroni's REST API on port 8008.
Endpoint Returns 200 when...
/primary Node holds leader lock AND is read/write primary
/replica?lag=1MB Running, role=replica, lag within limit
/read-only Any healthy node including primary
/synchronous Node is a sync standby
“Default inter 3s x fall 3 = up to 9 seconds of detection lag. Promotion is not the same as client
recovery.”
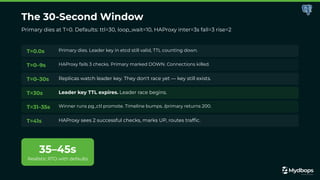
The 30-Second Window
Primary dies at T=0. Defaults: ttl=30, loop_wait=10, HAProxy inter=3s fall=3 rise=2
T=0.0s Primary dies. Leader key in etcd still valid, TTL counting down.
T=0–9s HAProxy fails 3 checks. Primary marked DOWN. Connections killed.
T=0–30s Replicas watch leader key. They don't race yet — key still exists.
T=30s Leader key TTL expires. Leader race begins.
T=31–35s Winner runs pg_ctl promote. Timeline bumps. /primary returns 200.
T=41s HAProxy sees 2 successful checks, marks UP, routes traffic.
35–45s
Realistic RTO with defaults
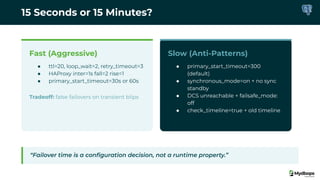
15 Seconds or 15 Minutes?
Fast (Aggressive)
● ttl=20, loop_wait=2, retry_timeout=3
● HAProxy inter=1s fall=2 rise=1
● primary_start_timeout=30s or 60s
Tradeoff: false failovers on transient blips
Slow (Anti-Patterns)
● primary_start_timeout=300
(default)
● synchronous_mode=on + no sync
standby
● DCS unreachable + failsafe_mode:
off
● check_timeline=true + old timeline
“Failover time is a configuration decision, not a runtime property.”
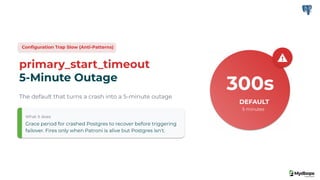
Configuration Trap Slow (Anti-Patterns)
primary_start_timeout
5-Minute Outage
The default that turns a crash into a 5-minute outage
What it does
Grace period for crashed Postgres to recover before triggering
failover. Fires only when Patroni is alive but Postgres isn't.
300s
DEFAULT
5 minutes
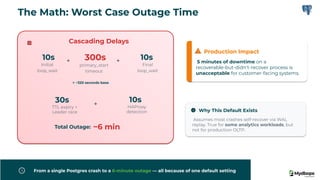
Cascading Delays
10s
Initial
loop_wait
+ 300s
primary_start
timeout
+ 10s
Final
loop_wait
= ~320 seconds base
30s
TTL expiry +
Leader race
+
10s
HAProxy
detection
Total Outage: ~6 min
Production Impact
5 minutes of downtime on a
recoverable-but-didn't-recover process is
unacceptable for customer-facing systems.
Why This Default Exists
Assumes most crashes self-recover via WAL
replay. True for some analytics workloads, but
not for production OLTP.
From a single Postgres crash to a 6-minute outage — all because of one default setting
The Math: Worst Case Outage Time
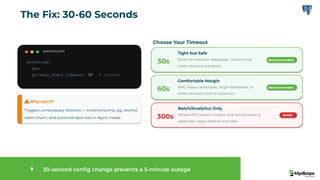
patroni.yml
bootstrap:
dcs:
primary_start_timeout: 30 # seconds
Why not 0?
Triggers unnecessary failovers — timeline bump, pg_rewind,
client churn, and potential data loss in async mode.
Choose Your Timeout
30s
Tight but Safe
Small-to-medium databases. Covers most
crash recovery scenarios.
Recommended
60s
Comfortable Margin
WAL-heavy workloads, larger databases, or
when recovery time is uncertain.
Recommended
300s
Batch/Analytics Only
Where RTO doesn't matter and self-recovery is
expected. Leave default only here.
Avoid
30-second config change prevents a 5-minute outage
The Fix: 30-60 Seconds
Slow (Anti-Patterns)
synchronous_mode: on
The Promotion Trap
The failover mechanism most teams don't see
coming—and why refusing to promote might be the safest
thing your database can do.
patronictl list
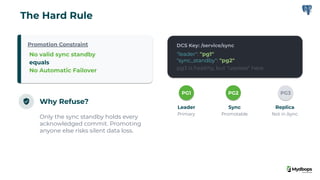
Promotion Constraint
No valid sync standby
equals
No Automatic Failover
Why Refuse?
Only the sync standby holds every
acknowledged commit. Promoting
anyone else risks silent data loss.
DCS Key: /service/sync
"leader": "pg1"
"sync_standby": "pg2"
pg3 is healthy, but "useless" here.
PG1
Leader
Primary
PG2
Sync
Promotable
PG3
Replica
Not in /sync
The Hard Rule
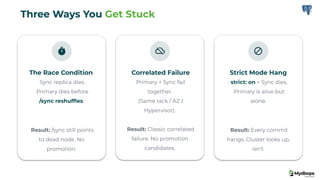
The Race Condition
Sync replica dies.
Primary dies before
/sync reshuffles.
Result: /sync still points
to dead node. No
promotion.
Correlated Failure
Primary + Sync fail
together.
(Same rack / AZ /
Hypervisor).
Result: Classic correlated
failure. No promotion
candidates.
Strict Mode Hang
strict: on + Sync dies.
Primary is alive but
alone.
Result: Every commit
hangs. Cluster looks up,
isn't.
Three Ways You Get Stuck
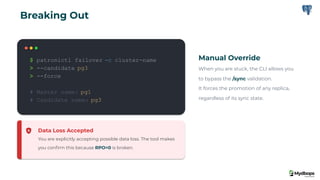
$ patronictl failover -c cluster-name
> --candidate pg3
> --force
# Master name: pg1
# Candidate name: pg3
Manual Override
When you are stuck, the CLI allows you
to bypass the /sync validation.
It forces the promotion of any replica,
regardless of its sync state.
Data Loss Accepted
You are explicitly accepting possible data loss. The tool makes
you confirm this because RPO=0 is broken.
Breaking Out
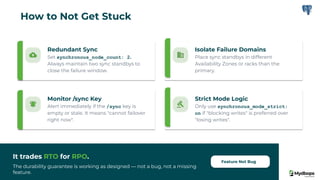
Redundant Sync
Set synchronous_node_count: 2.
Always maintain two sync standbys to
close the failure window.
Isolate Failure Domains
Place sync standbys in different
Availability Zones or racks than the
primary.
Monitor /sync Key
Alert immediately if the /sync key is
empty or stale. It means "cannot failover
right now".
Strict Mode Logic
Only use synchronous_mode_strict:
on if "blocking writes" is preferred over
"losing writes".
It trades RTO for RPO.
The durability guarantee is working as designed — not a bug, not a missing
feature.
Feature Not Bug
How to Not Get Stuck
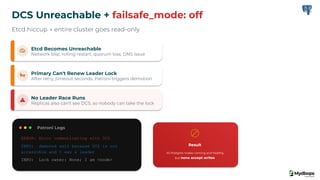
Etcd Becomes Unreachable
Network blip, rolling restart, quorum loss, DNS issue
Primary Can't Renew Leader Lock
After retry_timeout seconds, Patroni triggers demotion
No Leader Race Runs
Replicas also can't see DCS, so nobody can take the lock
Patroni Logs
ERROR: Error communicating with DCS
INFO: demoted self because DCS is not
accessible and I was a leader
INFO: Lock owner: None; I am <node>
Result
All Postgres nodes running and healthy,
but none accept writes
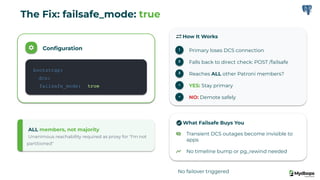
DCS Unreachable + failsafe_mode: off
Etcd hiccup → entire cluster goes read-only
Configuration
bootstrap:
dcs:
failsafe_mode: true
ALL members, not majority
Unanimous reachability required as proxy for "I'm not
partitioned"
How It Works
1 Primary loses DCS connection
2 Falls back to direct check: POST /failsafe
3 Reaches ALL other Patroni members?
→ YES: Stay primary
→ NO: Demote safely
What Failsafe Buys You
Transient DCS outages become invisible to
apps
No failover triggered
No timeline bump or pg_rewind needed
The Fix: failsafe_mode: true
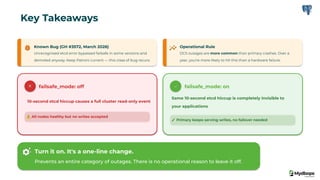
Known Bug (GH #3572, March 2026)
Unrecognised etcd error bypassed failsafe in some versions and
demoted anyway. Keep Patroni current — this class of bug recurs.
Operational Rule
DCS outages are more common than primary crashes. Over a
year, you're more likely to hit this than a hardware failure.
failsafe_mode: off
10-second etcd hiccup causes a full cluster read-only event
⚠ All nodes healthy but no writes accepted
failsafe_mode: on
Same 10-second etcd hiccup is completely invisible to
your applications
✓ Primary keeps serving writes, no failover needed
Turn it on. It's a one-line change.
Prevents an entire category of outages. There is no operational reason to leave it off.
Key Takeaways
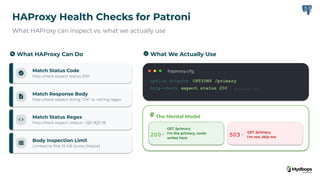
What HAProxy Can Do
Match Status Code
http-check expect status 200
Match Response Body
http-check expect string "OK" or rstring regex
Match Status Regex
http-check expect rstatus ^2[0-9][0-9]
Body Inspection Limit
Limited to first 16 KB (tune.chksize)
What We Actually Use
haproxy.cfg
option httpchk OPTIONS /primary
http-check expect status 200 # Status only
The Mental Model
200→
GET /primary
I'm the primary, route
writes here
503 →
GET /primary
I'm not, skip me
HAProxy Health Checks for Patroni
What HAProxy can inspect vs. what we actually use
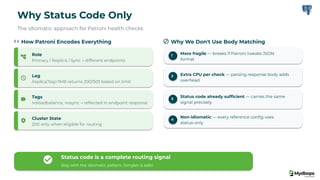
How Patroni Encodes Everything
Role
Primary / Replica / Sync → different endpoints
Lag
/replica?lag=1MB returns 200/503 based on limit
Tags
noloadbalance, nosync → reflected in endpoint response
Cluster State
200 only when eligible for routing
Why We Don't Use Body Matching
1 More fragile — breaks if Patroni tweaks JSON
format
2 Extra CPU per check — parsing response body adds
overhead
3
Status code already sufficient — carries the same
signal precisely
4
Non-idiomatic — every reference config uses
status-only
Status code is a complete routing signal
Stay with the idiomatic pattern. Simpler is safer.
Why Status Code Only
The idiomatic approach for Patroni health checks
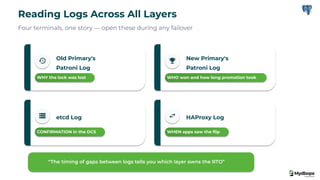
Old Primary's
Patroni Log
WHY the lock was lost
New Primary's
Patroni Log
WHO won and how long promotion took
etcd Log
CONFIRMATION in the DCS
HAProxy Log
WHEN apps saw the flip
“The timing of gaps between logs tells you which layer owns the RTO”
Reading Logs Across All Layers
Four terminals, one story — open these during any failover
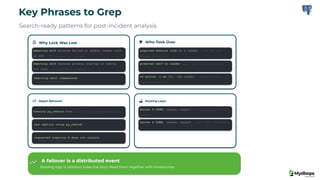
Key Phrases to Grep
Search-ready patterns for post-incident analysis
Why Lock Was Lost
Demoting self because failed to update leader lock
in DCS → DCS outage, no failsafe
Demoting self because primary startup is taking
too long → primary_start_timeout hit
Demoting self (immediate)
→ urgent, split-brain prevention
Who Took Over
acquired session lock as a leader → won the race
(before promotion)
promoted self to leader ... → pg_ctl promote done
no action. I am (X), the leader → steady state,
failover complete
Rejoin Behavior
running pg_rewind from ... → old primary reconciling
new replica using pg_rewind
→ clean rejoin
requested timeline X does not contain
→ divergence, reinit needed
Routing Layer
Server X DOWN, reason: Layer7 → role flip, 503 from
Patroni
Server X DOWN, reason: Layer4 → port 8008 unreachable
A failover is a distributed event
Reading logs in isolation hides the story. Read them together with timestamps.
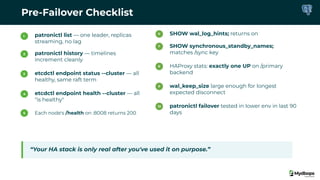
Pre-Failover Checklist
1 patronictl list — one leader, replicas
streaming, no lag
2 patronictl history — timelines
increment cleanly
3 etcdctl endpoint status --cluster — all
healthy, same raft term
4 etcdctl endpoint health --cluster — all
"is healthy"
5 Each node's /health on :8008 returns 200
6 SHOW wal_log_hints; returns on
7 SHOW synchronous_standby_names;
matches /sync key
8 HAProxy stats: exactly one UP on /primary
backend
9 wal_keep_size large enough for longest
expected disconnect
10 patronictl failover tested in lower env in last 90
days
“Your HA stack is only real after you've used it on purpose.”
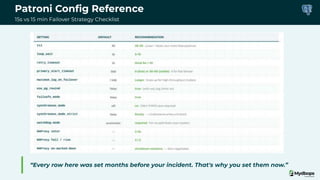
Patroni Config Reference
15s vs 15 min Failover Strategy Checklist
“Every row here was set months before your incident. That's why you set them now.”
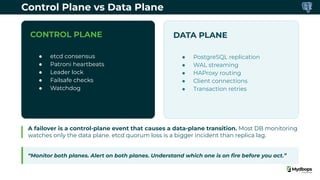
Control Plane vs Data Plane
CONTROL PLANE
● etcd consensus
● Patroni heartbeats
● Leader lock
● Failsafe checks
● Watchdog
DATA PLANE
● PostgreSQL replication
● WAL streaming
● HAProxy routing
● Client connections
● Transaction retries
A failover is a control-plane event that causes a data-plane transition. Most DB monitoring
watches only the data plane. etcd quorum loss is a bigger incident than replica lag.
“Monitor both planes. Alert on both planes. Understand which one is on fire before you act.”
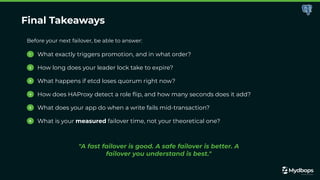
Final Takeaways
Before your next failover, be able to answer:
1 What exactly triggers promotion, and in what order?
2 How long does your leader lock take to expire?
3 What happens if etcd loses quorum right now?
4 How does HAProxy detect a role flip, and how many seconds does it add?
5 What does your app do when a write fails mid-transaction?
6 What is your measured failover time, not your theoretical one?
"A fast failover is good. A safe failover is better. A
failover you understand is best."
Questions?
Let's talk about real failover behavior, not architecture diagrams.