How to Compare
High Performance Databases
The Webinar will begin shortly…
How to Compare High
Performance Databases
Felipe Mendes, Technical Director
Guilherme Nogueira, Technical Director
Introductions
Felipe Mendes, Technical Director at ScyllaDB
+ Published Author on Linux and Databases
+ Helps teams solve their most challenging problems
+ Years of experience with Linux and distributed systems
Guilherme Nogueira, Technical Director at ScyllaDB
+ Previously Solutions Architect
+ Publishing
+ Streaming
+ Automotive
Poll
When testing performance, which
aspects do you prioritize most?
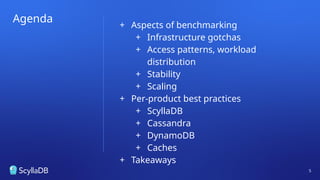
Agenda
+ Aspects of benchmarking
+ Infrastructure gotchas
+ Access patterns, workload
distribution
+ Stability
+ Scaling
+ Per-product best practices
+ ScyllaDB
+ Cassandra
+ DynamoDB
+ Caches
+ Takeaways
5
ScyllaDB Users
Powering India's top
social media platform
Video recommendation
management
Real-time fraud
detection
Seamless experiences
across content + devices
Network security
threat detection
Content personalization &
recommendation platform
Mobile Growth &
Monetization Platform
Inventory hub for
retail operations
Property listings
and updates
Cryptocurrency
exchange app
Real-time auctions
advertising platform
Predictable performance
for on sale surges
Online gaming
ad targeting
Media streaming
for 45M+ subscribers
Bridging AI to IT Service
Management
Real-time ML-driven
recommendations
Real-time endpoint threat
detection and security
Real-time personalized
recommendations
World leading beauty
platform behind Avon
Real-time AI decisioning
for digital advertisers
AI-centric customer
research platform
Powering Unreal Engine
real-time asset distribution
Real-time interactions
at massive scale
Always-on e-commerce
platform for millions of fans
ScyllaDB Users
6
Everybody knows how to
run benchmarks
7
Everybody knows how to
run benchmarks
8
RIG
Rightsizing Infrastructure
How big to go?
+ Too small
+ Easy to saturate computing resources
+ Hard to quantify performance and scalability gains
+ Too big
+ Expensive
+ Introduces additional layers of complexity
+ Definitely don't:
+ Use your laptop (The Cost of Containerization)
+ Deploy in K8s without an Operator
+ Recommendation:
+ Choose a meaningful representation of your workload
+ Storage x Throughput
9
Cloud Gotchas
Special attention to Networking.
+ Inter AZ traffic often has a cost (kudos Azure!)
+ Deploy under a single AZ
+ Place replicas under artificial distinct AZs
+ Bonus: Use Placement Groups for even lower latencies
+ Factor cross AZ RTT (often hundreds of ms) for accurate reporting
+ Base and burst network performance
+ This
+ Prefer loader VMs with guaranteed bandwidth
+ Feedback loop warning: Don't try to measure PPS limits
+ Often not a problem for the database node itself
■ You'll often saturate CPU or I/O first
10
Loader(s) Complications
Different solutions, implementations and traps (and bugs).
+ YCSB, NoSQLBench, cassandra-stress, latte, tlp-stress, redis-benchmark, mc-shredder, …
+ Concurrency x Thread tuning
+ You can't possibly achieve 1M ops/sec with a single thread
+ But too many threads add overhead to client-side latency!
+ Hard Recommendations:
+ At higher throughputs, seed different loader machines
+ Remember: Never overlap your population
+ Load generators often get confused with mixed workloads
■ Keep an eye on your database's monitoring
■ If at all possible, split reads from writes
11
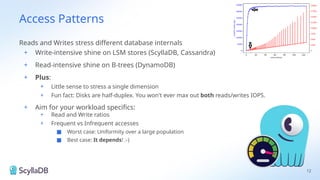
Access Patterns
Reads and Writes stress different database internals
+ Write-intensive shine on LSM stores (ScyllaDB, Cassandra)
+ Read-intensive shine on B-trees (DynamoDB)
+ Plus:
+ Little sense to stress a single dimension
+ Fun fact: Disks are half-duplex. You won't ever max out both reads/writes IOPS.
+ Aim for your workload specifics:
+ Read and Write ratios
+ Frequent vs Infrequent accesses
■ Worst case: Uniformity over a large population
■ Best case: It depends! :-)
12
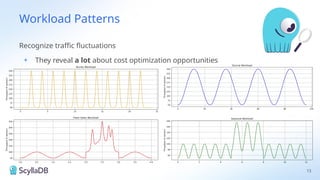
Workload Patterns
Recognize traffic fluctuations
+ They reveal a lot about cost optimization opportunities
13
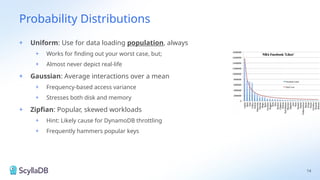
Probability Distributions
+ Uniform: Use for data loading population, always
+ Works for finding out your worst case, but;
+ Almost never depict real-life
+ Gaussian: Average interactions over a mean
+ Frequency-based access variance
+ Stresses both disk and memory
+ Zipfian: Popular, skewed workloads
+ Hint: Likely cause for DynamoDB throttling
+ Frequently hammers popular keys
14
Stability Under Load
Most databases have some burst capacity
+ DynamoDB caveats:
+ "DynamoDB currently retains up to five minutes (300 seconds) of unused read and write
capacity."
+ "DynamoDB can also consume burst capacity for background maintenance and other
tasks without prior notice."
+ Cassandra:
+ Compactions dominate
+ ScyllaDB:
+ Schedulers and Backlog Controllers!
+ To a point! :-)
15
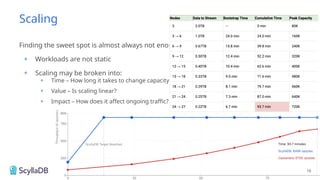
Scaling
Finding the sweet spot is almost always not enough.
+ Workloads are not static
+ Scaling may be broken into:
+ Time – How long it takes to change capacity?
+ Value – Is scaling linear?
+ Impact – How does it affect ongoing traffic?
16
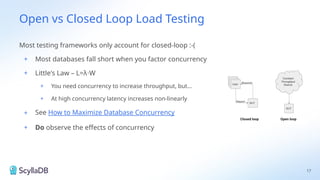
Open vs Closed Loop Load Testing
Most testing frameworks only account for closed-loop :-(
+ Most databases fall short when you factor concurrency
+ Little's Law – L=λ W
⋅
+ You need concurrency to increase throughput, but...
+ At high concurrency latency increases non-linearly
+ See How to Maximize Database Concurrency
+ Do observe the effects of concurrency
17
Wait! Is there
more to it?
18
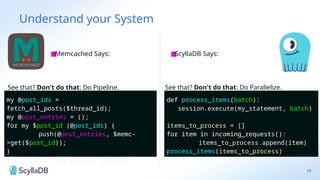
Understand your System
19
■
Memcached Says: ■
ScyllaDB Says:
my @post_ids =
fetch_all_posts($thread_id);
my @post_entries = ();
for my $post_id (@post_ids) {
push(@post_entries, $memc-
>get($post_id));
}
# Yay I have all my post entries!
See that? Don't do that: Do Pipeline.
def process_items(batch):
session.execute(my_statement, batch)
items_to_process = []
for item in incoming_requests():
items_to_process.append(item)
process_items(items_to_process)
See that? Don't do that: Do Parallelize.
my @post_ids =
fetch_all_posts($thread_id);
my @post_entries = ();
for my $post_id (@post_ids) {
push(@post_entries, $memc-
>get($post_id));
}
# Yay I have all my post entries!
def process_items(batch):
session.execute(my_statement, batch)
items_to_process = []
for item in incoming_requests():
items_to_process.append(item)
process_items(items_to_process)
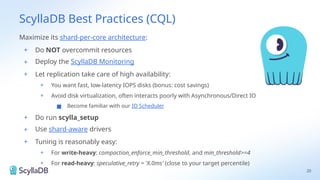
ScyllaDB Best Practices (CQL)
20
Maximize its shard-per-core architecture:
+ Do NOT overcommit resources
+ Deploy the ScyllaDB Monitoring
+ Let replication take care of high availability:
+ You want fast, low-latency IOPS disks (bonus: cost savings)
+ Avoid disk virtualization, often interacts poorly with Asynchronous/Direct IO
■ Become familiar with our IO Scheduler
+ Do run scylla_setup
+ Use shard-aware drivers
+ Tuning is reasonably easy:
+ For write-heavy: compaction_enforce_min_threshold, and min_threshold>=4
+ For read-heavy: speculative_retry = 'X.0ms' (close to your target percentile)
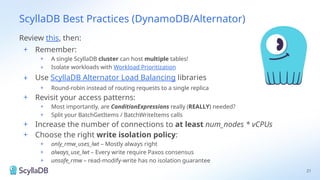
ScyllaDB Best Practices (DynamoDB/Alternator)
21
Review this, then:
+ Remember:
+ A single ScyllaDB cluster can host multiple tables!
+ Isolate workloads with Workload Prioritization
+ Use ScyllaDB Alternator Load Balancing libraries
+ Round-robin instead of routing requests to a single replica
+ Revisit your access patterns:
+ Most importantly, are ConditionExpressions really (REALLY) needed?
+ Split your BatchGetItems / BatchWriteItems calls
+ Increase the number of connections to at least num_nodes * vCPUs
+ Choose the right write isolation policy:
+ only_rmw_uses_lwt – Mostly always right
+ always_use_lwt – Every write require Paxos consensus
+ unsafe_rmw – read-modify-write has no isolation guarantee
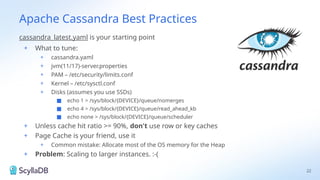
Apache Cassandra Best Practices
cassandra_latest.yaml is your starting point
+ What to tune:
+ cassandra.yaml
+ jvm(11/17)-server.properties
+ PAM – /etc/security/limits.conf
+ Kernel – /etc/sysctl.conf
+ Disks (assumes you use SSDs)
■ echo 1 > /sys/block/{DEVICE}/queue/nomerges
■ echo 4 > /sys/block/{DEVICE}/queue/read_ahead_kb
■ echo none > /sys/block/{DEVICE}/queue/scheduler
+ Unless cache hit ratio >= 90%, don't use row or key caches
+ Page Cache is your friend, use it
+ Common mistake: Allocate most of the OS memory for the Heap
+ Problem: Scaling to larger instances. :-(
22
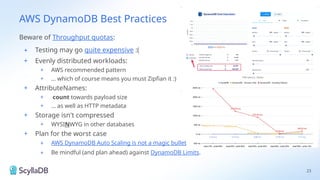
AWS DynamoDB Best Practices
Beware of Throughput quotas:
+ Testing may go quite expensive :(
+ Evenly distributed workloads:
+ AWS recommended pattern
+ … which of course means you must Zipfian it :)
+ AttributeNames:
+ count towards payload size
+ … as well as HTTP metadata
+ Storage isn't compressed
+ WYSINWYG in other databases
+ Plan for the worst case
+ AWS DynamoDB Auto Scaling is not a magic bullet
+ Be mindful (and plan ahead) against DynamoDB Limits.
23
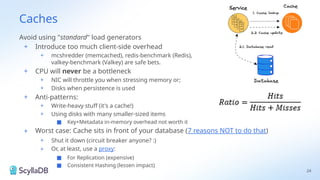
Caches
Avoid using "standard" load generators
+ Introduce too much client-side overhead
+ mcshredder (memcached), redis-benchmark (Redis),
valkey-benchmark (Valkey) are safe bets.
+ CPU will never be a bottleneck
+ NIC will throttle you when stressing memory or;
+ Disks when persistence is used
+ Anti-patterns:
+ Write-heavy stuff (it's a cache!)
+ Using disks with many smaller-sized items
■ Key+Metadata in-memory overhead not worth it
+ Worst case: Cache sits in front of your database (7 reasons NOT to do that)
+ Shut it down (circuit breaker anyone? :)
+ Or, at least, use a proxy:
■ For Replication (expensive)
■ Consistent Hashing (lessen impact)
24
Key Takeaways
25
+ Context is paramount when evaluating "performance"
+Scalability, Elasticity, Latencies, Throughput
+ Databases are different, so does how you interact with them
+ Real-world Workloads often deviate from the "standard norm"
+ Probability distributions, Open vs Closed Loop, Traffic Fluctuations, Available Infrastructure ...
26
Must-Read Books for High-
Performance System Design
Access 4 PDFs on building and optimizing data-intensive applications
lp.scylladb.com/book-library-
offer
Thank you
for joining us today.
@scylladb scylladb/
slack.scylladb.com
@scylladb company/
scylladb/
scylladb/