Skip to main content
Recommended
PPTX
PDF
PPTX
PDF
The Best Securely Communication Software
PPT
Hive - SerDe and LazySerde
PPTX
Ten tools for ten big data areas 04_Apache Hive
PPT
PDF
Data Engineering with Spring, Hadoop and Hive
PDF
PPTX
Hive analytic workloads hadoop summit san jose 2014
PPTX
Introduction to Big Data processing (FGRE2016)
PPT
PPTX
Big Data Warehousing: Pig vs. Hive Comparison
PPT
PPTX
Cassandra EU 2012 - Overview of Case Studies and State of the Market by 451 R...
PPTX
Cost-based query optimization in Apache Hive
PPTX
Learning Apache HIVE - Data Warehouse and Query Language for Hadoop
PPTX
PDF
PPT
Hive Training -- Motivations and Real World Use Cases
PPTX
PDF
PDF
PPT
HIVE: ��Data Warehousing & Analytics on Hadoop
PDF
Replacing Telco DB/DW to Hadoop and Hive
PDF
Hive Quick Start Tutorial
PPTX
Comprehensive Guide to Cyber Attacks on Networks and Prevention Techniques
PDF
Outsourcing Finance Function: The CFO Strategy for 2027
PPTX
When AI Agents Work Together: Exploring A2A, MCP, and Connected AI Frameworks...
PDF
HITCON 2026 Slide- Not Just Spies Anymore: DPRK's Espionage Actors Are Coming...
More Related Content
PPTX
PDF
PPTX
PDF
The Best Securely Communication Software
PPT
Hive - SerDe and LazySerde
PPTX
Ten tools for ten big data areas 04_Apache Hive
PPT
PDF
Data Engineering with Spring, Hadoop and Hive
Viewers also liked
PDF
PPTX
Hive analytic workloads hadoop summit san jose 2014
PPTX
Introduction to Big Data processing (FGRE2016)
PPT
PPTX
Big Data Warehousing: Pig vs. Hive Comparison
PPT
PPTX
Cassandra EU 2012 - Overview of Case Studies and State of the Market by 451 R...
PPTX
Cost-based query optimization in Apache Hive
PPTX
Learning Apache HIVE - Data Warehouse and Query Language for Hadoop
PPTX
PDF
PPT
Hive Training -- Motivations and Real World Use Cases
PPTX
PDF
PDF
PPT
HIVE: ��Data Warehousing & Analytics on Hadoop
PDF
Replacing Telco DB/DW to Hadoop and Hive
PDF
Hive Quick Start Tutorial
Recently uploaded
PPTX
Comprehensive Guide to Cyber Attacks on Networks and Prevention Techniques
PDF
Outsourcing Finance Function: The CFO Strategy for 2027
PPTX
When AI Agents Work Together: Exploring A2A, MCP, and Connected AI Frameworks...
PDF
HITCON 2026 Slide- Not Just Spies Anymore: DPRK's Espionage Actors Are Coming...
PPTX
Comprehensive MEAN Stack Developer Roadmap for 2026: From Fundamentals to Job...
PDF
Salesforce Headless 360: Revolutionizing Agentic Enterprise with AI and Multi...
PPTX
From APIs to Agents: Rethinking Testing for Dynamic Systems
PDF
Invisible Process Hazards: 4 Risks Your Workers Can’t See
PPTX
Comprehensive Azure Migration Readiness Guide: Inventory, Security, Networkin...
PPTX
How to Make AI-Assisted Writing More Authentic: A Practical Guide to Original...
PPTX
Centralized Application-Context Aware Firewall with AI/ML for Enhanced Cybers...
PPTX
Optimizing Write-Intensive Database Workloads Masterclass: Why Scaling Writes...
PDF
Computer Organization and Design MIPS Edition 6th Edition PDF
DOCX
5 Unique Sites to Buy Old Gmail Accounts 2fa Number.
PDF
How Much Does Data Annotation Cost? Pricing Models, Rates & Budget Benchmarks
PPTX
Comprehensive Introduction to Artificial Intelligence: Concepts, History, and...
PPTX
BotGentz AI Playbook: Seamless AI Agents Integrated into Your Workflow
PPTX
Optimizing Write-Intensive Database Workloads Masterclass: Strategies for Opt...
PDF
Agile Gurugram & Delhi National Capital Region 2026 | AISDLC - Why, What and ...
PDF
Closing the 20-Minute Security Gap with OhhPro Smart Gate Management
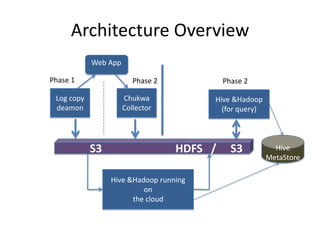
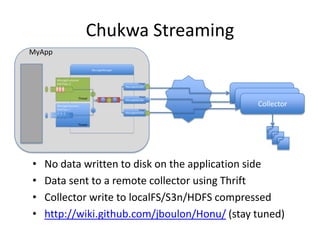
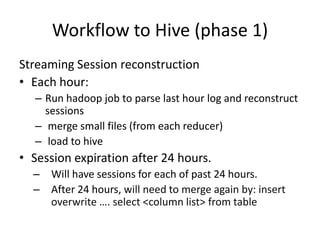
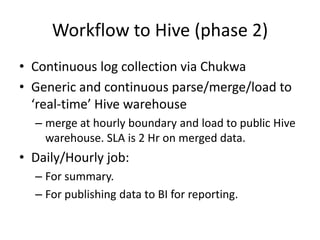
Hive user group presentation from Netflix (3/18/2010) 1. 2. What are we trying to achieve?Scalable log analysis to gain business insights:Logs for website streaming (phase 1)All logs from web (phase 2)Output required:Engineers access:Ad-hoc query and reportingBI access:Flat files to be loaded into BI system for cross-functional reporting. 3. 4. Architecture Overview Web AppPhase 1Phase 2Phase 2Chukwa CollectorLog copy deamonHive & Hadoop (for query)Hive MetaStore S3 HDFS / S3Hive & Hadoop running on the cloud 5. 6. 7. 8. http://wiki.github.com/jboulon/Honu/ (stay tuned)Workflow to Hive (phase 1)Streaming Session reconstructionEach hour: Run hadoop job to parse last hour log and reconstruct sessions merge small files (from each reducer) load to hiveSession expiration after 24 hours.Will have sessions for each of past 24 hours.After 24 hours, will need to merge again by: insert overwrite …. select <column list> from table 9. Workflow to Hive (phase 2)Continuous log collection via ChukwaGeneric and continuous parse/merge/load to ‘real-time’ Hive warehousemerge at hourly boundary and load to public Hive warehouse. SLA is 2 Hr on merged data.Daily/Hourly job: For summary.For publishing data to BI for reporting.