Hierarchical Object Detection with Deep
Reinforcement Learning
NIPS 2016 Workshop on Reinforcement Learning
[github] [arXiv]
Míriam Bellver, Xavier Giró i Nieto, Ferran Marqués, Jordi Torres
Outline
● Introduction
● Related Work
● Hierarchical Object Detection Model
● Experiments
● Conclusions
2
Introduction
3
Introduction
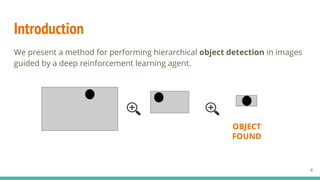
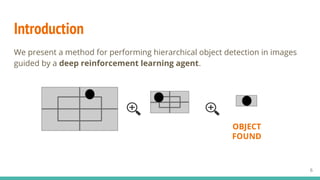
We present a method for performing hierarchical object detection in images
guided by a deep reinforcement learning agent.
4
OBJECT
FOUND
Introduction
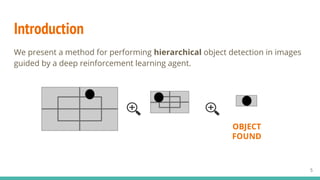
We present a method for performing hierarchical object detection in images
guided by a deep reinforcement learning agent.
5
OBJECT
FOUND
Introduction
We present a method for performing hierarchical object detection in images
guided by a deep reinforcement learning agent.
6
OBJECT
FOUND
Introduction
What is Reinforcement Learning ?
“a way of programming agents by reward and punishment without needing to
specify how the task is to be achieved”
[Kaelbling, Littman, & Moore, 96]
7
Introduction
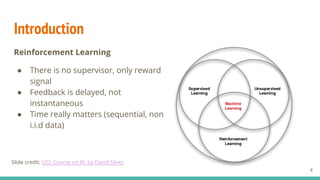
Reinforcement Learning
● There is no supervisor, only reward
signal
● Feedback is delayed, not
instantaneous
● Time really matters (sequential, non
i.i.d data)
8
Slide credit: UCL Course on RL by David Silver
Introduction
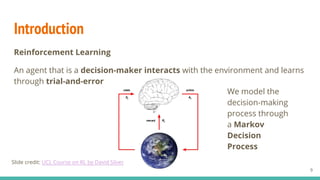
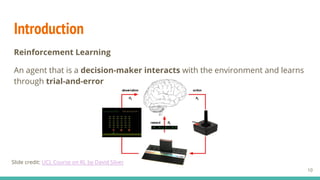
Reinforcement Learning
An agent that is a decision-maker interacts with the environment and learns
through trial-and-error
9
Slide credit: UCL Course on RL by David Silver
We model the
decision-making
process through
a Markov
Decision
Process
Introduction
Reinforcement Learning
An agent that is a decision-maker interacts with the environment and learns
through trial-and-error
10
Slide credit: UCL Course on RL by David Silver
Introduction
Contributions:
● Hierarchical object detection in images using deep reinforcement
learning agent
● We define two different hierarchies of regions
● We compare two different strategies to extract features for each
candidate proposal to define the state
● We achieve to find objects analyzing just a few regions
11
Related Work
12
Related Work
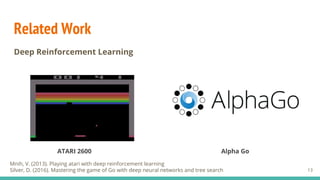
Deep Reinforcement Learning
13
ATARI 2600 Alpha Go
Mnih, V. (2013). Playing atari with deep reinforcement learning
Silver, D. (2016). Mastering the game of Go with deep neural networks and tree search
Related Work
14
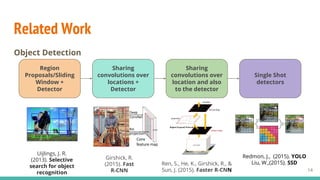
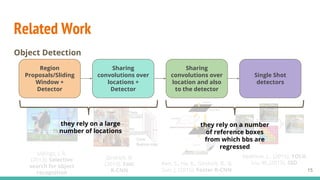
Region
Proposals/Sliding
Window +
Detector
Sharing
convolutions over
locations +
Detector
Sharing
convolutions over
location and also
to the detector
Single Shot
detectors
Uijlings, J. R.
(2013). Selective
search for object
recognition
Girshick, R.
(2015). Fast
R-CNN
Ren, S., He, K., Girshick, R., &
Sun, J. (2015). Faster R-CNN
Redmon, J., (2015). YOLO
Liu, W.,(2015). SSD
Object Detection
Related Work
15
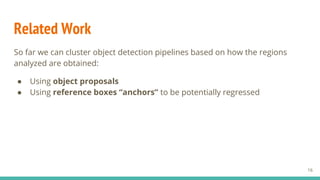
Region
Proposals/Sliding
Window +
Detector
Sharing
convolutions over
locations +
Detector
Sharing
convolutions over
location and also
to the detector
Single Shot
detectors
Object Detection
they rely on a large
number of locations
they rely on a number
of reference boxes
from which bbs are
regressed
Uijlings, J. R.
(2013). Selective
search for object
recognition
Girshick, R.
(2015). Fast
R-CNN
Ren, S., He, K., Girshick, R., &
Sun, J. (2015). Faster R-CNN
Redmon, J., (2015). YOLO
Liu, W.,(2015). SSD
Related Work
So far we can cluster object detection pipelines based on how the regions
analyzed are obtained:
● Using object proposals
● Using reference boxes “anchors” to be potentially regressed
16
Related Work
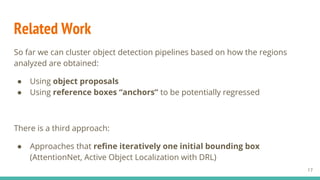
So far we can cluster object detection pipelines based on how the regions
analyzed are obtained:
● Using object proposals
● Using reference boxes “anchors” to be potentially regressed
There is a third approach:
● Approaches that refine iteratively one initial bounding box
(AttentionNet, Active Object Localization with DRL)
17
Related Work
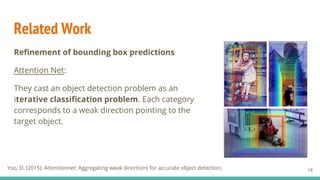
Refinement of bounding box predictions
Attention Net:
They cast an object detection problem as an
iterative classification problem. Each category
corresponds to a weak direction pointing to the
target object.
18Yoo, D. (2015). Attentionnet: Aggregating weak directions for accurate object detection.
Related Work
Refinement of bounding box predictions
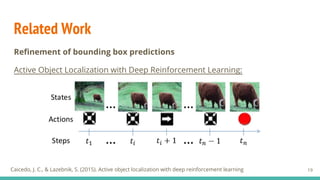
Active Object Localization with Deep Reinforcement Learning:
19Caicedo, J. C., & Lazebnik, S. (2015). Active object localization with deep reinforcement learning
Hierarchical Object Detection Model
Reinforcement Learning formulation
20
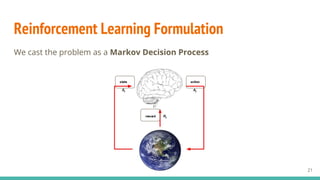
Reinforcement Learning Formulation
We cast the problem as a Markov Decision Process
21
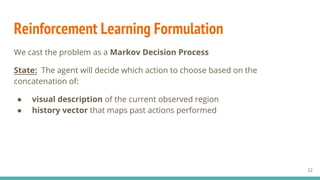
Reinforcement Learning Formulation
We cast the problem as a Markov Decision Process
State: The agent will decide which action to choose based on the
concatenation of:
● visual description of the current observed region
● history vector that maps past actions performed
22
Reinforcement Learning Formulation
We cast the problem as a Markov Decision Process
Actions: Two kind of actions:
● movement actions: to which of the 5 possible regions defined by the
hierarchy to move
● terminal action: the agent indicates that the object has been found
23
Reinforcement Learning Formulation
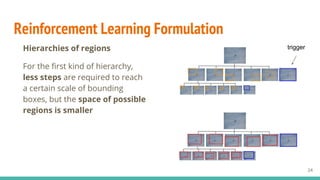
Hierarchies of regions
For the first kind of hierarchy,
less steps are required to reach
a certain scale of bounding
boxes, but the space of possible
regions is smaller
24
trigger
Reinforcement Learning Formulation
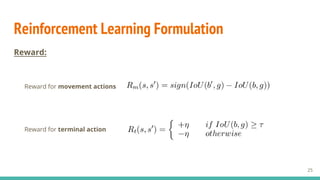
Reward:
25
Reward for movement actions
Reward for terminal action
Hierarchical Object Detection Model
Q-learning
26
Q-learning
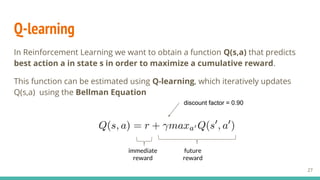
In Reinforcement Learning we want to obtain a function Q(s,a) that predicts
best action a in state s in order to maximize a cumulative reward.
This function can be estimated using Q-learning, which iteratively updates
Q(s,a) using the Bellman Equation
27
immediate
reward
future
reward
discount factor = 0.90
Q-learning
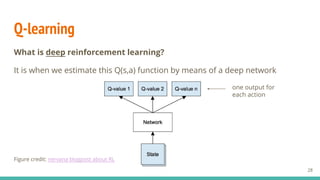
What is deep reinforcement learning?
It is when we estimate this Q(s,a) function by means of a deep network
28
Figure credit: nervana blogpost about RL
one output for
each action
Hierarchical Object Detection Model
Model
29
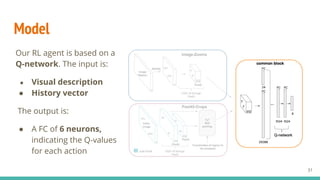
Model
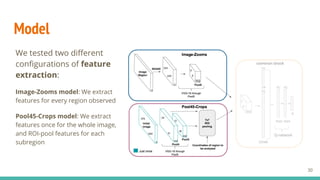
We tested two different
configurations of feature
extraction:
Image-Zooms model: We extract
features for every region observed
Pool45-Crops model: We extract
features once for the whole image,
and ROI-pool features for each
subregion
30
Model
Our RL agent is based on a
Q-network. The input is:
● Visual description
● History vector
The output is:
● A FC of 6 neurons,
indicating the Q-values
for each action
31
Hierarchical Object Detection Model
Training
32
Training
Exploration-Exploitation dilemma
ε-greedy policy
Exploration: With probability ε the agent performs a random action
Exploitation: With probability 1-ε performs action associated to highest Q(s,a)
33
Training
Experience Replay
Bellman equation learns from transitions formed by (s,a,r,s’) Consecutive
experiences are very correlated, leading to inefficient training.
Experience replay collects a buffer of experiences and the algorithm
randomly takes mini batches from this replay memory to train the network
34
Experiments
35
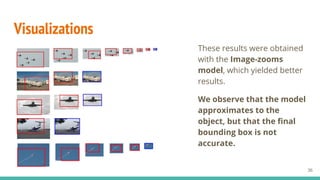
Visualizations
These results were obtained
with the Image-zooms
model, which yielded better
results.
We observe that the model
approximates to the
object, but that the final
bounding box is not
accurate.
36
Experiments
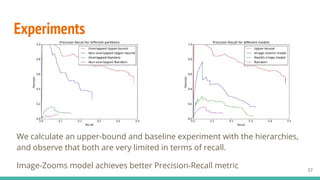
We calculate an upper-bound and baseline experiment with the hierarchies,
and observe that both are very limited in terms of recall.
Image-Zooms model achieves better Precision-Recall metric 37
Experiments
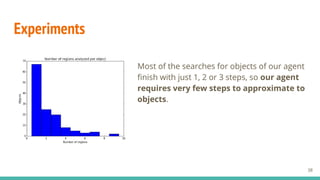
Most of the searches for objects of our agent
finish with just 1, 2 or 3 steps, so our agent
requires very few steps to approximate to
objects.
38
Conclusions
39
Conclusions
● Image-Zooms model yields better results. We argue that with the
ROI-pooling approach we do not have as much resolution as with the
Image-Zoom features. Although Image-Zooms is more computationally
intensive, we can afford it because with just a few steps we approximate
to the object.
● Our agent approximates to the object, but the final bounding box is not
accurate enough due that the hierarchy limits our space of solutions. A
solution could be training a regressor that adjusts the bounding box to
the target object.
40
Acknowledgements
Technical Support Financial Support
41
Albert Gil (UPC)
Josep Pujal (UPC)
Carlos Tripiana (BSC)
Thank you for your attention!
42