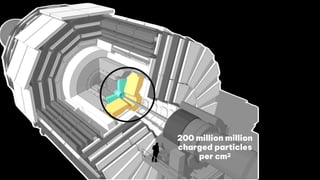
From Zettabytes to a Few Precious Events: Nanosecond AI at the Large Hadron Collider by Thea Aarrestad
The Large Hadron Collider generates tens of thousands of exabytes of raw data annually, making real-time AI and machine learning essential for filtering millions of collision events per second to find rare, meaningful signals. Dr. Thea Aarrestad offers an inside look at how physicists and engineers push the limits of data, speed, and precision to make discoveries like the Higgs boson possible.
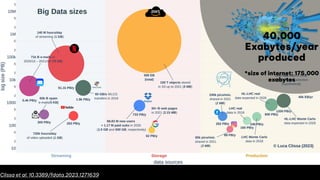
FIGURE 1
Big datasizes. Orders of magnitude involved in different data sources for several big data players. The area of each bubble represents the amount of
40,000
Exabytes/year
produced
*size of internet: 175,000
exabytes
Clissa et al. 10.3389/fdata.2023.1271639
4.
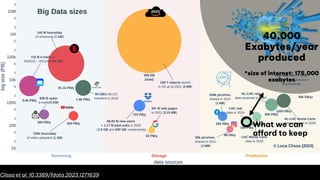
FIGURE 1
Big datasizes. Orders of magnitude involved in different data sources for several big data players. The area of each bubble represents the amount of
40,000
Exabytes/year
produced
*size of internet: 175,000
exabytes
What we can
a!ord to keep
Clissa et al. 10.3389/fdata.2023.1271639
9
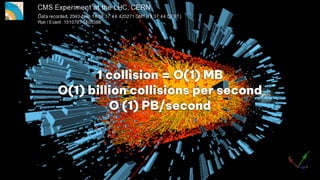
1 collision =O(1) MB
O(1) billion collisions per second
O (1) PB/second
11.
10
Blabla
• Dodge
• Dodge
Blabla
•Dodge
• Dodge
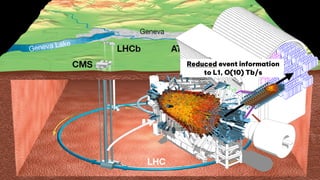
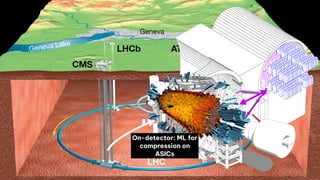
On-detector ML
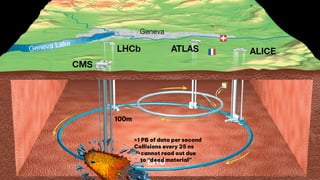
>1 PB of data per second
Collisions every 25 ns
→cannot read out due
to “dead material”
100m
12.
11
Blabla
• Dodge
• Dodge
Blabla
•Dodge
• Dodge
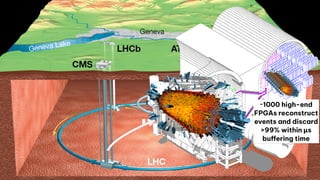
On-detector ML
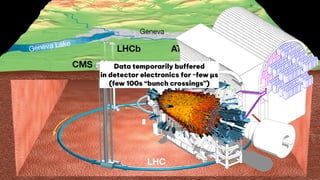
Data temporarily buffered
in detector electronics for ~few µs
(few 100s “bunch crossings”)
15
Blabla
• Dodge
• Dodge
Blabla
•Dodge
• Dodge
On-detector ML
Optical links for CMS
„ >60e3 optical links
„ ~20Tb/s raw data throughput
„ Extract raw data from the
detector, feed processing
electronics situated in shielded
and accessible area
„ Distribute clock and control data
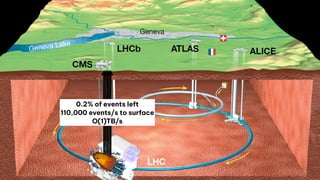
0.2% of events left
110,000 events/s to surface
O(1)TB/s
17.
16
Blabla
• Dodge
• Dodge
Blabla
•Dodge
• Dodge
On-detector ML
Optical links for CMS
„ >60e3 optical links
„ ~20Tb/s raw data throughput
„ Extract raw data from the
detector, feed processing
electronics situated in shielded
and accessible area
„ Distribute clock and control data
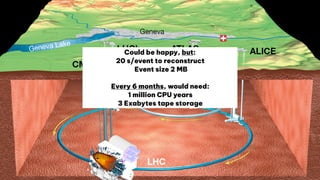
Could be happy, but:
20 s/event to reconstruct
Event size 2 MB
Every 6 months, would need:
1 million CPU years
3 Exabytes tape storage
18.
17
Blabla
• Dodge
• Dodge
Blabla
•Dodge
• Dodge
On-detector ML
Optical links for CMS
„ >60e3 optical links
„ ~20Tb/s raw data throughput
„ Extract raw data from the
detector, feed processing
electronics situated in shielded
and accessible area
„ Distribute clock and control data
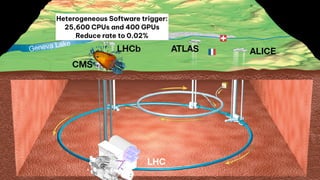
Heterogeneous Software trigger:
25,600 CPUs and 400 GPUs
Reduce rate to 0.02%
19.
18
Blabla
• Dodge
• Dodge
Blabla
•Dodge
• Dodge
On-detector ML
Optical links for CMS
„ >60e3 optical links
„ ~20Tb/s raw data throughput
„ Extract raw data from the
detector, feed processing
electronics situated in shielded
and accessible area
„ Distribute clock and control data
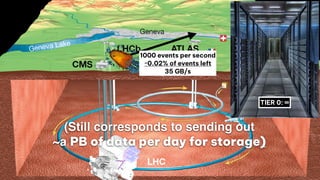
1000 events per second
~0.02% of events left
35 GB/s
(Still corresponds to sending out
~a PB of data per day for storage)
TIER 0: ∞
20.
19
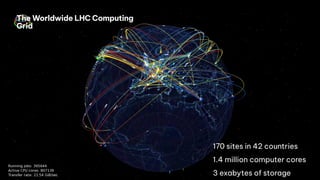
The Worldwide LHCComputing
Grid
170 sites in 42 countries
1.4 million computer cores
3 exabytes of storage
Blabla
• Dodge
• Dodge
Blabla
•Dodge
• Dodge
On-detector ML
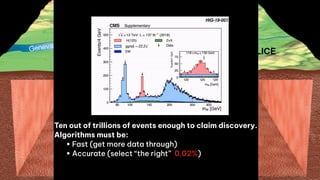
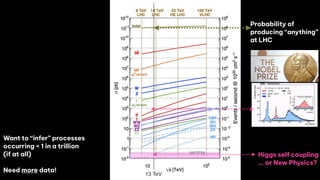
Ten out of trillions of events enough to claim discovery.
Algorithms must be:
• Fast (get more data through)
• Accurate (select “the right” 0.02%)
HIG-19-001
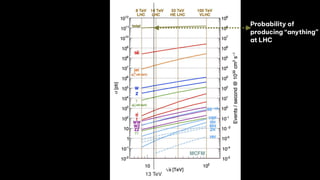
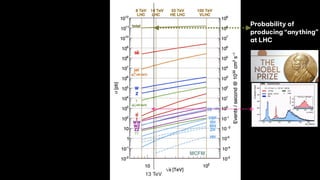
Want to “infer”processes
occurring < 1 in a trillion
(if at all)
Need more data!
13 TeV
Higgs self coupling
… or New Physics?
Probability of
producing “anything”
at LHC
26.
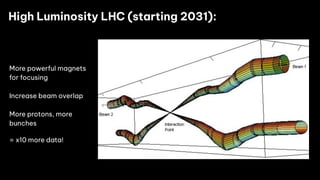
More powerful magnets
forfocusing
Increase beam overlap
More protons, more
bunches
= x10 more data!
High Luminosity LHC (starting 2031):
27.
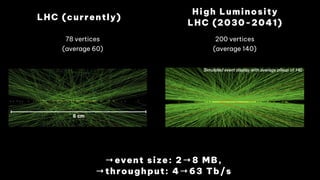
High Luminosity
LHC (2030-2041)
TheHL-LHC will come online around 2026.
e with monster pile-up
e à pile-up of ~ 60 events/x-ing
g)
CMS: event with 78 reconstructed vertices
CMS: event from 2017 with 78
reconstructed vertices
ATLAS: simulation for HL-LHC with
200 vertices
78 vertices
(average 60)
200 vertices
(average 140)
LHC (currently)
6 cm
Challenges
• Price to pay for high luminosity
— extreme pileup
‣ At HL-LHC, expect on average
200 overlapping pp collisions
• Particularly challenging for
trigger system
‣ Inclusion of tracking central to
mitigating effects of pileup
ATLAS & CMS: Trigger System
• Current trigger systems
• L1 trigger
• Hardware-based, implemented in custom-built electronics
• Muon & calorimeter information with reduced granularity, no tracking information
• High-Level Trigger (HLT)
• Software-based, executed on large computing farms
• Tracking information & full detector granularity
rney to HL-LHC
Simulated event display with average pileup of 140
500
1000
1500
2000
2500
3000
5ecRrded
/umLnRsLty
(pb
−1
/1.00)
<µ> 32
σpp
in =69.1 mb
500
1000
1500
2000
2500
3000
C0S Average 3ileuS, SS, 2018,
0
s = 13 TeV
500
1000
1500
2000
2500
3000
ecRrded
/umLnRsLty
(pb
−1
/1.00)
<µ> 32
σpp
in =69.1 mb
500
1000
1500
2000
2500
3000
C0S Average 3ileuS, SS, 2018,
0
s = 13 TeV
-1
10
0
10
1
10
2
10
3
10
4
10
5
5ecRrded
/umLnRsLty
(pb
−1
/1.00)
<µ> 32
σpp
in =69.1 mb
-1
10
0
10
1
10
2
10
3
10
4
10
5
C0S Average 3ileuS, SS, 2018,
0
s = 13 TeV
→event size: 2→8 MB,
→throughput: 4→63 Tb/s
28.
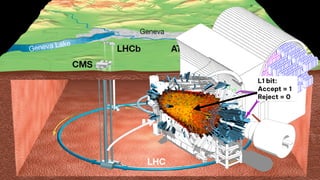
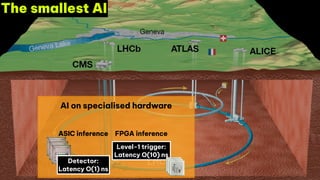
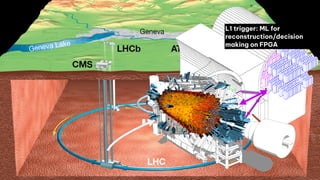
Level-1 trigger:
Latency O(10)ns
Detector:
Latency O(1) ns
AI on specialised hardware
FPGA inference
ASIC inference
The smallest AI
29.
266 Chapter 5.Conceptual design of the Phase-2 L1 Trigger
a global processing step which merges or sums the regional outputs. Given the rather simple
calorimeter-only object reconstruction algorithms and the available processing power to per-
form them, the performance achieved is not directly impacted by this choice. For example,
the GCT design remains completely convertible to a fully time-multiplexed approach where
all the data from barrel and endcap can be processed by the same board while offering a more
adaptive interface to the track finder, should future requirement changes result in preferring
it. In the case of the GMT, the choice to align the TMUX period with that of the track finder is
motivated by the main processing task of this system: correlate tracks and muon information.
The firmware resource estimations indicate that lighter hardware is required (See Section 5.3).
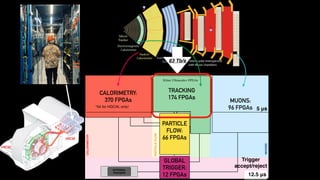
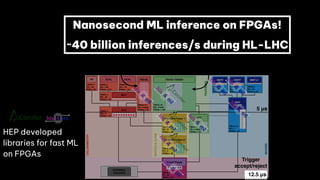
CALORIMETRY:
370 FPGAs MUONS:
96 FPGAs
TRACKING
174 FPGAs
12.5 μs
Trigger
accept/reject
5 μs
PARTICLE
FLOW:
66 FPGAs
GLOBAL
TRIGGER:
12 FPGAs
*54 for HGCAL only!
63 Tb/s
Xilinx Ultrascale+ FPGAs
30.
266 Chapter 5.Conceptual design of the Phase-2 L1 Trigger
a global processing step which merges or sums the regional outputs. Given the rather simple
calorimeter-only object reconstruction algorithms and the available processing power to per-
form them, the performance achieved is not directly impacted by this choice. For example,
the GCT design remains completely convertible to a fully time-multiplexed approach where
all the data from barrel and endcap can be processed by the same board while offering a more
adaptive interface to the track finder, should future requirement changes result in preferring
it. In the case of the GMT, the choice to align the TMUX period with that of the track finder is
motivated by the main processing task of this system: correlate tracks and muon information.
The firmware resource estimations indicate that lighter hardware is required (See Section 5.3).
12.5 μs
Trigger
accept/reject
5 μs
Challenges
• Price to pay for high luminosity
— extreme pileup
‣ At HL-LHC, expect on average
200 overlapping pp collisions
• Particularly challenging for
trigger system
‣ Inclusion of tracking central to
mitigating effects of pileup
ATLAS & CMS: Trigger System
• Current trigger systems
• L1 trigger
• Hardware-based, implemented in custom-built electronics
• Muon & calorimeter information with reduced granularity, no tracking information
• High-Level Trigger (HLT)
• Software-based, executed on large computing farms
• Tracking information & full detector granularity
• ATLAS use level-2 & event filter, CMS single-step HLT
Journey to HL-LHC
3 run:
7 x 1033, PU = 30, E = 7 TeV, 50 nsec bunch spacing
TLAS, CMS operating:
ccept ≤ 100 kHz,
ncy ≤ 2.5 (AT), 4 µsec (CM)
Accept ≤ 1 kHz
LAS & CMS will be:
Front end pipelines
Readout buffers
Processor farms
Switching network
Detectors
Lvl-1
HLT
Lvl-1
Lvl-2
Lvl-3
Front end pipelines
Readout buffers
Processor farms
Switching network
Detectors
Detectors
Front end
pipelines
Readout
buffers
Switching
network
Processor
farms
Detectors
Front end
pipelines
Readout
buffers
Switching
network
Processor
farms
40 MHz
L1 output: 75 kHz
~3 kHz
200 Hz
40 MHz
100 Hz
L1 trigger decision
in ~2.5 (4) µs for
ATLAS (CMS)
L1 output: 100 kHz
40 MHz
100 kHz
~1 kHz
750 kHz
7.5 kHz
LHC HL-LHC
40 MHz
L1 output:
HLT output:
Simulated event display with average pileup of 140
0 20 40 60 80
100
0ean number Rf LnteractLRns per crRssLng
0
500
1000
1500
2000
2500
3000
5ecRrded
/umLnRsLty
(pb
−1
/1.00)
<µ> 32
σpp
in =69.1 mb
0
500
1000
1500
2000
2500
3000
C0S Average 3ileuS, SS, 2018,
0
s = 13 TeV
0 20 40 60 80
100
0ean number Rf LnteractLRns per crRssLng
0
500
1000
1500
2000
2500
3000
5ecRrded
/umLnRsLty
(pb
−1
/1.00)
<µ> 32
σpp
in =69.1 mb
0
500
1000
1500
2000
2500
3000
C0S Average 3ileuS, SS, 2018,
0
s = 13 TeV
0 20 40 60 80
100
0ean number Rf LnteractLRns per crRssLng
10
-1
10
0
10
1
10
2
10
3
10
4
10
5
5ecRrded
/umLnRsLty
(pb
−1
/1.00)
<µ> 32
σpp
in =69.1 mb
10
-1
10
0
10
1
10
2
10
3
10
4
10
5
C0S Average 3ileuS, SS, 2018,
0
s = 13 TeV
• Trigger system reduces 40 MHz
collision rate to data rate that can be
read out & written to disk
• w/o tracking, L1 output for PU=200
is ~4000 kHz
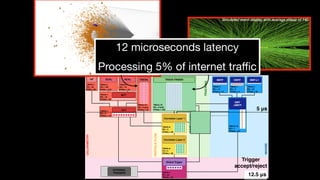
12 microseconds latency
Processing 5% of internet traffic
31.
•
•
•
•
Fast Machine Learningfor HEP
Our tasks not well-
represented by industry-driven
benchmarks
Must develop our own tools, datasets
and data challenges
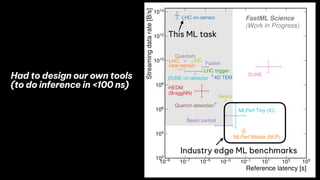
Industry edge ML benchmarks
This ML task
Had to design our own tools
(to do inference in <100 ns)
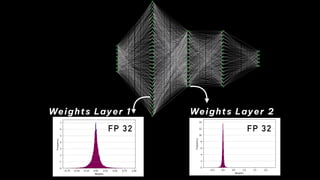
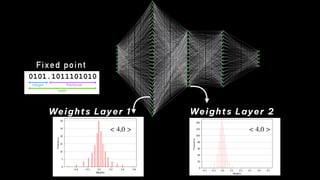
FP 32 FP32
< 4,0 > < 4,0 >
Fixed point
Efficient NN design: quantization
• In the FPGA we use fixed point representation
- Operations are integer ops, but we can represent
fractional values
• But we have to make sure we’ve used the correct data types!
0101.1011101010
width
fractional
integer
Full performance
at 6 integer bits
Scan integer bits
Fractional bits fixed to 8
Scan fractional bits
Integer bits fixed to 6
Full performance
at 8 fractional bits
PGA
AUC
/
Expected
AUC
GA
AUC
/
Expected
AUC
ap_fixed<width bits, integer bits>
Weights Layer 1 Weights Layer 2
40.
39
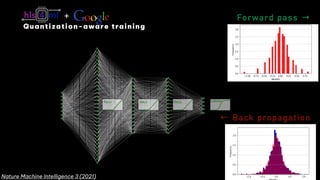
ReLU ReLU ReLUSoftmax
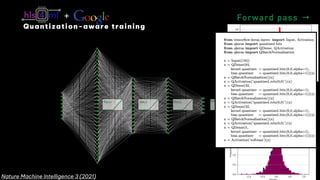
Forward pass →
← Back propagation
+
Quantization-aware training
Nature Machine Intelligence 3 (2021)
41.
40
ReLU ReLU ReLUSoftmax
Forward pass →
← Back propagation
+
Quantization-aware training
Nature Machine Intelligence 3 (2021)
42.
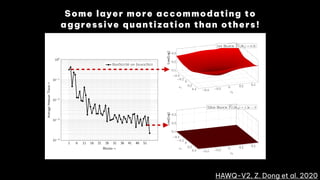
1 6 1116 21 26 31 36 41 46 51
10 4
10 3
10 2
10 1
100
Blocks!
Average
Hessian
Trace!
ResNet50 on ImageNet
0.4
0.2
0
0.2
0.4 0.4 0.2 0 0.2 0.4
0.1
0.2
0.3
✏1
✏2
Loss(Log)
1st Block Tr(H1) = 0.31
0.4
0.2
0
0.2
0.4 0.4 0.2 0 0.2 0.4
0.1
0.2
0.3
✏1
✏2
Loss(Log)
52nd Block Tr(H52) = 1.3e 3
ks in Inception-V3 and ResNet50 on ImageNet, along with the loss landscape
HAWQ-V2, Z. Dong et al. 2020
Some layer more accommodating to
aggressive quantization than others!
43.
42
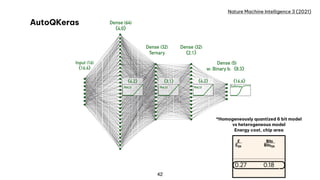
Dense (32)
Ternary
Input (16)
〈16,6〉
Dense(32)
〈2,1〉
ReLU ReLU ReLU Softmax
Dense (5)
w: Binary b:〈8,3〉
Dense (64)
〈4,0〉
〈16,6〉
〈16,6〉
〈4,2〉 〈3,1〉 〈4,2〉
*Homogeneously quantized 6 bit model
vs heterogeneous model
Energy cost, chip area
*
Nature Machine Intelligence 3 (2021)
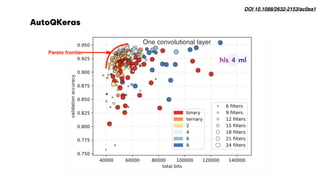
AutoQKeras
44
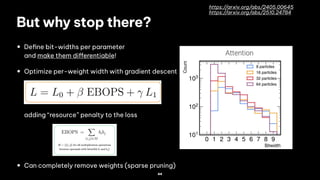
But why stopthere?
• De!ne bit-widths per parameter
and make them di"erentiable!
• Optimize per-weight width with gradient descent
adding “resource” penalty to the loss
• Can completely remove weights (sparse pruning)
https://arxiv.org/abs/2405.00645
https://arxiv.org/abs/2510.24784
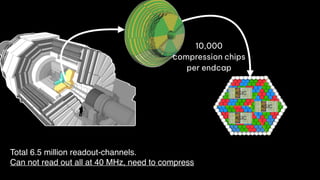
Total 6.5 millionreadout-channels.
Can not read out all at 40 MHz, need to compress
Tot
On-Detector Electronics
HGCROC
ECON-T
Sensor Cell
Super Trigger Cell (STC)
Sensor
module
PCB
System overview
3
10 Gb/s links
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
Front-end electronics are challenging 19
Thorben Quast | Edinburgh PPE Seminar, 11 June 2021
HGCAL FE electronics requirements:
• Low noise (<2500e) and high dynamic range
(0.2fC -10pC).
• Timing information to tens of picoseconds.
• Radiation tolerant.
• <20mW per channel (cooling limitation).
• Zero-suppression of data to transmit to DAQ.
• Computation of trigger sums for L1 trigger.
V3 HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Time-of-arrival (TOA) & time-over-threshold (TOT)
Signal
Sensor
module
PCB
System overview
3
10 Gb/s links
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
Front-end electronics are challenging 19
Thorben Quast | Edinburgh PPE Seminar, 11 June 2021
HGCAL FE electronics requirements:
• Low noise (<2500e) and high dynamic range
(0.2fC -10pC).
• Timing information to tens of picoseconds.
• Radiation tolerant.
• <20mW per channel (cooling limitation).
• Zero-suppression of data to transmit to DAQ.
• Computation of trigger sums for L1 trigger.
V3 HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Time-of-arrival (TOA) & time-over-threshold (TOT)
Signal
Sensor
module
PCB
System overview
3
10 Gb/s links
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
Front-end electronics are challenging 19
Thorben Quast | Edinburgh PPE Seminar, 11 June 2021
HGCAL FE electronics requirements:
• Low noise (<2500e) and high dynamic range
(0.2fC -10pC).
• Timing information to tens of picoseconds.
• Radiation tolerant.
• <20mW per channel (cooling limitation).
• Zero-suppression of data to transmit to DAQ.
• Computation of trigger sums for L1 trigger.
V3 HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Time-of-arrival (TOA) & time-over-threshold (TOT)
Signal
ASIC
ASIC
ASIC
10,000
compression chips
per endcap
51.
Sensor
module
PCB
System overview
3
10 Gb/slinks
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
Front-end electronics are challenging 19
Thorben Quast | Edinburgh PPE Seminar, 11 June 2021
HGCAL FE electronics requirements:
• Low noise (<2500e) and high dynamic range
(0.2fC -10pC).
• Timing information to tens of picoseconds.
• Radiation tolerant.
• <20mW per channel (cooling limitation).
• Zero-suppression of data to transmit to DAQ.
• Computation of trigger sums for L1 trigger.
V3 HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Time-of-arrival (TOA) & time-over-threshold (TOT)
Signal
Sensor
module
PCB
System overview
3
10 Gb/s links
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
nging 19
HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Sensor
module
PCB
System overview
3
10 Gb/s links
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
Front-end electronics are challenging 19
Thorben Quast | Edinburgh PPE Seminar, 11 June 2021
HGCAL FE electronics requirements:
• Low noise (<2500e) and high dynamic range
(0.2fC -10pC).
• Timing information to tens of picoseconds.
• Radiation tolerant.
• <20mW per channel (cooling limitation).
• Zero-suppression of data to transmit to DAQ.
• Computation of trigger sums for L1 trigger.
V3 HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Time-of-arrival (TOA) & time-over-threshold (TOT)
Signal
Sensor
module
PCB
System overview
3
10 Gb/s links
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
Front-end electronics are challenging 19
Thorben Quast | Edinburgh PPE Seminar, 11 June 2021
HGCAL FE electronics requirements:
• Low noise (<2500e) and high dynamic range
(0.2fC -10pC).
• Timing information to tens of picoseconds.
• Radiation tolerant.
• <20mW per channel (cooling limitation).
• Zero-suppression of data to transmit to DAQ.
• Computation of trigger sums for L1 trigger.
V3 HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Time-of-arrival (TOA) & time-over-threshold (TOT)
Signal
ASIC
ASIC
ASIC
ASIC
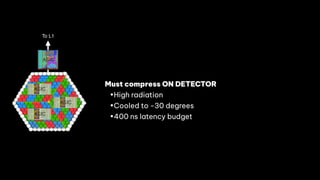
To L1
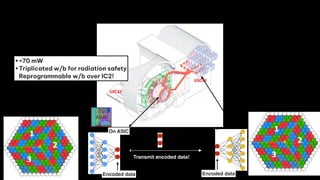
Must compress ON DETECTOR
•High radiation
•Cooled to -30 degrees
•400 ns latency budget
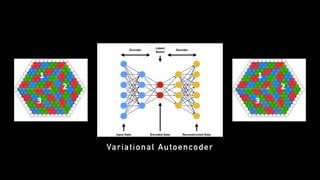
Transmit encoded data!
Encodeddata
Encoder architecture
Encoded data
Enco
Sensor
module
PCB
System overview
3
10 Gb/s links
10 Gb/s links
On
detector
Off
detector
Control
Data
Data
Front-end electronics are challenging 19
Thorben Quast | Edinburgh PPE Seminar, 11 June 2021
HGCAL FE electronics requirements:
• Low noise (<2500e) and high dynamic range
(0.2fC -10pC).
• Timing information to tens of picoseconds.
• Radiation tolerant.
• <20mW per channel (cooling limitation).
• Zero-suppression of data to transmit to DAQ.
• Computation of trigger sums for L1 trigger.
V3 HGCROC ASIC both for silicon and SiPMs ECON as concentrator ASIC
Time-of-arrival (TOA) & time-over-threshold (TOT)
Signal
ASIC
On ASIC
ECON-T, D. Noonan
•<70 mW
•Triplicated w/b for radiation safety
Reprogrammable w/b over IC2!
Clustering in theHGCAL L1 Trigger
On-Detector Electronics
HGCROC
ECON-T
Sensor Cell
Trigger Cell (TC)
Super Trigger Cell (STC)
Bac
Geom
Mask
Graph
ECON-T
Latent Space
Best Choice
(N highest energy TCs)
Super Trigger Cell
NN Encoder
Unc
acc
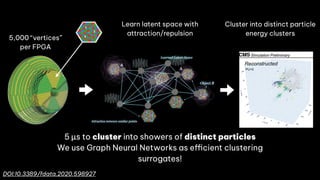
5 µs to cluster into showers of distinct particles
We use Graph Neural Networks as e$cient clustering
surrogates!
5,000 “vertices”
per FPGA
DOI:10.3389/fdata.2020.598927
Learn latent space with
attraction/repulsion
Cluster into distinct particle
energy clusters
4
57.
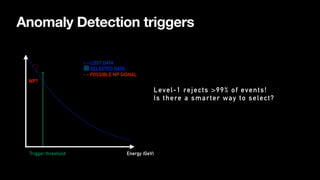
Anomaly Detection triggers
Energy(GeV)
Trigger threshold
NP?
- - LOST DATA
- - SELECTED DATA
- - POSSIBLE NP SIGNAL
Level-1 rejects >99% of events!
Is there a smarter way to select?
58.
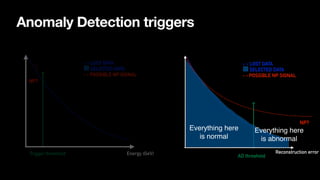
Anomaly Detection triggers
Energy(GeV)
Trigger threshold
NP?
- - LOST DATA
- - SELECTED DATA
- - POSSIBLE NP SIGNAL
Reconstruction error
AD threshold
NP?
- - LOST DATA
- - SELECTED DATA
- - POSSIBLE NP SIGNAL
Everything here
is normal
Everything here
is abnormal
59.
E, px, py,pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
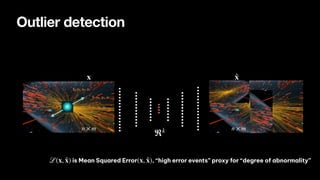
Outlier detection
E, px, py, pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
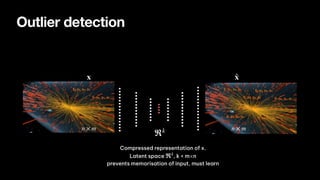
Compressed representation of x.
Latent space , k < m⨉n
prevents memorisation of input, must learn
ℜk
ℜk
x ̂
x
n × m n × m
60.
E, px, py,pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
Outlier detection
ℜk
x ̂
x
n × m n × m
is Mean Squared Error , “high error events” proxy for “degree of abnormality”
ℒ(x, ̂
x) (x, ̂
x)
61.
ℜk
256 A Lorentzinvariance based Deep Neu
When performing the following multiplication
xC
µ,i = xµ,iCi,j,
the resulting output matrix will have dimensions 4 ⇥ (1 + N + M
first column containing the sum of all constituent momenta, th
constituent, and M=14 di↵erent linear combinations of particle
corresponds to the neural network computing the four-vector o
in terms of its 20 highest-pT constituents. The second simply
four-momentum to the next layer. The final, and most interesti
alternative subjet four-vectors by letting it weigh constituents u
to reach optimal discrimination power. As an example, lets
simple case of only two input jet constituents and two trainab
0
B
B
B
B
B
@
E1
E2
p1
x p2
x
p1
y p1
y
p1
z p2
z
1
C
C
C
C
C
A
1 1 0 w1,4 w1,5
1 0 1 w2,4 w2,5
!
=
0
B
B
B
B
B
@
E1
+ E2
E1
E2
w
p1
x + p2
x p1
x p2
x w
p1
y + p1
y p1
y p1
y w
p1
z + p2
z p1
z p2
z w
In the two last columns, the neural network makes two “subj
relative contribution of each particle as it sees fit. This is simi
or PUPPI pileup subtraction (Section 5.3.2), and should a
constituents are part of the hard scatter and which are not. T
to the next layer, the Lorentz Layer.
256 A Lorentz invariance based Deep Neura
When performing the following multiplication
xC
µ,i = xµ,iCi,j,
the resulting output matrix will have dimensions 4 ⇥ (1 + N + M)
first column containing the sum of all constituent momenta, the fo
constituent, and M=14 di↵erent linear combinations of particles w
corresponds to the neural network computing the four-vector of th
in terms of its 20 highest-pT constituents. The second simply p
four-momentum to the next layer. The final, and most interesting
alternative subjet four-vectors by letting it weigh constituents up
to reach optimal discrimination power. As an example, lets loo
simple case of only two input jet constituents and two trainable
0
B
B
B
B
B
@
E1
E2
p1
x p2
x
p1
y p1
y
p1
z p2
z
1
C
C
C
C
C
A
1 1 0 w1,4 w1,5
1 0 1 w2,4 w2,5
!
=
0
B
B
B
B
B
@
E1
+ E2
E1
E2
w1,4E
p1
x + p2
x p1
x p2
x w1,4
p1
y + p1
y p1
y p1
y w1,4
p1
z + p2
z p1
z p2
z w1,4
In the two last columns, the neural network makes two “subjet”
relative contribution of each particle as it sees fit. This is similar
or PUPPI pileup subtraction (Section 5.3.2), and should allow
constituents are part of the hard scatter and which are not. The
to the next layer, the Lorentz Layer.
….
̂
x
n × m
๏ Idea applied to tagging jets,
in order to define a QCD-jet
veto
๏ Applied in a BSM search
(e.g., dijet resonance) could
highlight new physics signal
๏ Based on image and physics-
inspired representations of
jets
Example: Jet autoencoders
Figure 2: Distribution of reconstruction error computed with a CNN autoencoder on test
QCD background (gray) and two signals: tops (blue) and 400 GeV gluinos (orange).
We see that the autoencoder works as advertised: it learns to reconstruct
background that it has been trained on (to be precise, we train on 100k QCD
by recombination jet algorithms we can add linear combinations of these 4
trainable matrix Cij, defining a combination layer
kµ,i
CoLa
! e
kµ,j = kµ,i Cij with C =
0
B
B
@
1 1 0 · · · 0 C1,N+1 · · ·
.
.
. 0 1
.
.
. C2,N+1 · · ·
.
.
.
.
.
.
.
.
.
... 0
.
.
.
1 0 0 · · · 1 CN,N+1 · · ·
We allow for M = 10 trainable linear combinations. These combined 4-vectors
tion on the hadronically decaying massive particles. In the original LoLa ap
the momenta k̃j onto observable Lorentz scalars and related observables [13
mapping is not easily invertible we do not use it for the autoencoder. Instead
4-vectors by another component containing the invariant mass,
k̃j =
0
B
B
@
k̃0,j
k̃1,j
k̃2,j
k̃3,j
1
C
C
A
LoLa
!
0
B
B
B
B
B
B
@
k̃0,j
k̃1,j
k̃2,j
k̃3,j
q
k̃2
j
1
C
C
C
C
C
C
A
.
This defines a set of 51 extended 4-vectors, which form the input to our n
Again, we use Keras [35] combined with Tensorflow [36]. Its architectu
Fig. 3. The layer immediately after the LoLa contains 51 ⇥ (4 + 1) = 255
the second layer after LoLa and the last layer, the autoencoder network is s
final output consist of 40 4-vector-like objects, which can be compared with the
SciPost Physics Su
tagger [13]. It starts from a set of measured 4-vectors sorted by transverse mom
(kµ,i) =
0
B
B
@
k0,1 k0,2 · · · k0,N
k1,1 k1,2 · · · k1,N
k2,1 k2,2 · · · k2,N
k3,1 k3,2 · · · k3,N
1
C
C
A .
Following the left panel of Fig. 1 we use N = 40 constituents, after checking tha
to N = 120 does not make a measurable di↵erence. For jets with fewer co
naturally fill the entries remaining in the soft regime with zeros.
To remove all information from the jet-level kinematics we boost all 4-mom
rest frame of the fat jet. This also improves the performance of our netwo
by recombination jet algorithms we can add linear combinations of these 4-v
trainable matrix Cij, defining a combination layer
kµ,i
CoLa
! e
kµ,j = kµ,i Cij with C =
0
B
B
@
1 1 0 · · · 0 C1,N+1 · · · C
.
.
. 0 1
.
.
. C2,N+1 · · · C
.
.
.
.
.
.
.
.
.
... 0
.
.
.
1 0 0 · · · 1 CN,N+1 · · · CN
We allow for M = 10 trainable linear combinations. These combined 4-vectors c
tion on the hadronically decaying massive particles. In the original LoLa appr
the momenta k̃j onto observable Lorentz scalars and related observables [13].
mapping is not easily invertible we do not use it for the autoencoder. Instead, w
4-vectors by another component containing the invariant mass,
Large error for
abnormal data
MSE(x, ̂
x)
arXiv:1808.08992
E, px, py, pz
E, px, py, pz
E, px, py, pz
E, px, py, pz
n × m
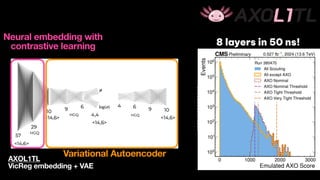
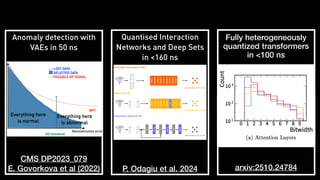
Anomaly detection with
VAEsin 50 ns
CMS DP2023_079
E. Govorkova et al (2022)
Quantised Interaction
Networks and Deep Sets
in <160 ns
P. Odagiu et al. 2024
Fully on-chip
transformers in 90 ns
(500k flops, 9k param)
IEEE ICFTP 2022
arxiv:409.05207
wide range of values and mapping them in memory or LUTs
to allow for lookup at run-time. Hence, the optimized design
requires one fewer lookup while also replacing multiplication
by a subtraction, which can be simpler to express in hardware.
x1
...
xN
exp
table
exp(x1)
exp(xN)
... + sum
inv
table
1 /
sum
σ(x1)
σ(xN)
...
log
table
log σ(x1)
log σ(xN)
...
X
X
Fig. 6. Direct hardware implementations of log softmax.
x1
...
xN
exp
table
exp(x1)
exp(xN)
... + sum
log
table
log
sum
log σ(x1)
log σ(xN)
...
-
-
Fig. 7. Optimized hardware implementations of log softmax.
Although further simplifications, including approximating
the summation by finding the maximum (see equation 5) or
simply omitting the logarithm portion of the expression, were
also evaluated, they noticeably lowered the final accuracy and
were thus abandoned.
(5)
log(ω(xi)) = exi
→ log(
N
!
j=1
exj
)
= exi
→
N
!
j=1
log(exj
)
= exi
→
N
!
j=1
xj
I:
Linear
II:
Concat
III:
Linear
IV:
Matmul
VI:
Matmul
V:
Softmax
VII:
Linear
IX:
Linear
X:
Linear
VIII:
Sum
XI:
Sum
XII:
Linear
XIII:
Log Softmax
XIV:
Sync
Linear
Linear Parameter
Input jet data
Prediction
Multi-Head
Self-attention
+
Log Softmax
Transformer
+
Concatenate
Linear
ReLU
Linear
ReLU
Linear
Q K V
Matmul
Scale
Matmul
Softmax
Linear Linear
Linear
x heads
I
II
XII
XIII
XIV
IX
X
XI
VIII
IV
V
III
VI
VII
14 stages pipeline (18 cycles)
Fig. 8. Proposed architecture with highlighted pipeline stages.
composed of 165,760 (80/20 split with training data set) 16-
dimensional HLF samples, which is a result worse by only 2.3
percent points compared to the Pytorch implementation. Due
to the intrinsic reduced precision of the fixed-point arithmetic,
that score matches the expectations.
The RTL synthesis report shows a remarkable improvement
in the inference time, from the Pytorch implementation values
pipelining the model, all the operations can be c
either one or two cycles. Certain operations lik
scaling share their stage with subsequent compo
their simplicity.
The design configuration affects several of
stages, and hence a significant portion of the
number of transformer layers have a direct impact
Anomaly detection with
VAEs in 50 ns
CMS DP2023_079
E. Govorkova et al (2022)
Quantised Interaction
Networks and Deep Sets
in <160 ns
P. Odagiu et al. 2024
Fully on-chip
transformers in 90 ns
(500k flops, 9k param)
IEEE ICFTP 2022
arxiv:409.05207
wide range of values and mapping them in memory or LUTs
to allow for lookup at run-time. Hence, the optimized design
requires one fewer lookup while also replacing multiplication
by a subtraction, which can be simpler to express in hardware.
x1
...
xN
exp
table
exp(x1)
exp(xN)
... + sum
inv
table
1 /
sum
σ(x1)
σ(xN)
...
log
table
log σ(x1)
log σ(xN)
...
X
X
Fig. 6. Direct hardware implementations of log softmax.
x1
...
xN
exp
table
exp(x1)
exp(xN)
... + sum
log
table
log
sum
log σ(x1)
log σ(xN)
...
-
-
Fig. 7. Optimized hardware implementations of log softmax.
Although further simplifications, including approximating
the summation by finding the maximum (see equation 5) or
simply omitting the logarithm portion of the expression, were
also evaluated, they noticeably lowered the final accuracy and
were thus abandoned.
(5)
log(ω(xi)) = exi
→ log(
N
!
j=1
exj
)
= exi
→
N
!
j=1
log(exj
)
= exi
→
N
!
j=1
xj
I:
Linear
II:
Concat
III:
Linear
IV:
Matmul
VI:
Matmul
V:
Softmax
VII:
Linear
IX:
Linear
X:
Linear
VIII:
Sum
XI:
Sum
XII:
Linear
XIII:
Log Softmax
XIV:
Sync
Linear
Linear Parameter
Input jet data
Prediction
Multi-Head
Self-attention
+
Log Softmax
Transformer
+
Concatenate
Linear
ReLU
Linear
ReLU
Linear
Q K V
Matmul
Scale
Matmul
Softmax
Linear Linear
Linear
x heads
I
II
XII
XIII
XIV
IX
X
XI
VIII
IV
V
III
VI
VII
14 stages pipeline (18 cycles)
Fig. 8. Proposed architecture with highlighted pipeline stages.
composed of 165,760 (80/20 split with training data set) 16-
dimensional HLF samples, which is a result worse by only 2.3
percent points compared to the Pytorch implementation. Due
to the intrinsic reduced precision of the fixed-point arithmetic,
that score matches the expectations.
The RTL synthesis report shows a remarkable improvement
in the inference time, from the Pytorch implementation values
pipelining the model, all the operations can be c
either one or two cycles. Certain operations lik
scaling share their stage with subsequent compo
their simplicity.
The design configuration affects several of
stages, and hence a significant portion of the
number of transformer layers have a direct impact
Fully heterogeneously
quantized transformers
in <100 ns
arxiv:2510.24784
64.
Semantic segmentation
for autonomousvehicles
N. Ghielmetti et al. 2022
Seizure Predicting Brain
Implant
W. Lemaire et al. 2022
Earth monitoring in
satellites
Edge SpAIce, S. Summers
…and outside
• MLPerf tinyML benchmarking
• For fusion science phase/mode monitoring
• Crystal structure detection
• Triggering in DUNE
• Accelerator control
• Magnet Quench Detection
• Food contamination detection
• Quantum control etc….
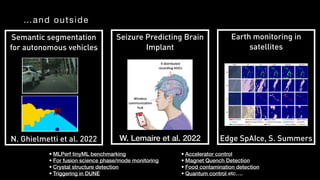
Semantic segmentation
for autonomous vehicles
N. Ghielmetti et al. 2022
Seizure Predicting Brain
Implant
W. Lemaire et al. 2022
Earth monitoring in
satellites
Edge SpAIce, S. Summers
…and outside
• MLPerf tinyML benchmarking
• For fusion science phase/mode monitoring
• Crystal structure detection
• Triggering in DUNE
• Accelerator control
• Magnet Quench Detection
• Food contamination detection
• Quantum control etc….