ENTERPRISE AI WHITEPAPER
Enterprise AI Cost Engineering
A Practical Framework for Token Economics in Hybrid GenAI and Agentic Architectures
A strategy for reducing token consumption while preserving accuracy, latency, scalability, governance, and
business value — across native AI platforms, custom GenAI solutions, and on-premises models.
Author
Avik Bhattacharjee
Enterprise AI Architecture & Cost Engineering
August 2026
ENTERPRISE AI COST ENGINEERING
Contents
01 Executive Summary
02 How Enterprise AI Became an Economics Problem
03 The Enterprise AI Landscape
04 Token Economics: The New Compute Currency
05 Where Enterprises Waste Tokens
06 The Enterprise AI Cost Engineering Framework (EACEF)
07 The Decision Framework: EA-CEDF
08 Hybrid AI Strategy — Native, Custom, and On-Prem
09 Measuring Business Impact
10 Governance and AI FinOps
11 The Enterprise Roadmap
12 Conclusion
About the Author
References
Page 2 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
01. Executive Summary
Generative AI has moved past the pilot stage. Enterprises now run copilots, agents, and custom assistants
in production, every day, at real scale. The early question was which model to use. That question has been
answered well enough for most workloads.
A new question has taken its place. How much does each AI-powered outcome actually cost, and is that
cost sustainable as usage grows? Gartner's research on agentic AI shows that upgrading from a simple
chatbot to an autonomous agent can increase token consumption per query by five to thirty times, because
the agent reasons, calls tools, and revisits context along the way.
Cost is no longer a footnote in enterprise AI planning. It is now a design input, alongside accuracy, latency,
and governance.
This paper introduces two connected frameworks. The Enterprise AI Cost Engineering Framework (EACEF)
treats every AI request as a system to be engineered, not just prompted. The Enterprise AI Cost Engineering
Decision Framework (EA-CEDF) gives architects a repeatable decision tree and scorecard to decide, before
any tokens are spent, whether a request needs a rule, a search, a native tool, a small model, or a large
language model.
The goal is not the smallest possible token bill. The goal is the best business outcome for every token spent,
delivered through a hybrid architecture that blends native AI platforms, custom agentic systems, and on-
premises models with intent.
02. How Enterprise AI Became an Economics Problem
In 2023, enterprises rushed to adopt generative AI. Early pilots showed real productivity gains.
Most organizations focused on one question: which model is the best?
By 2025, a different problem had emerged. AI worked. But operating costs grew faster than most teams
expected.
Every prompt consumed tokens. Every retry consumed more tokens. Every reasoning step added by an
agent consumed still more. Every document pulled in by retrieval increased the size of the context window.
Every long conversation carried its full history into the next turn.
Recent industry reporting has made the pattern visible. One widely cited case describes an employee at a
fintech company spending more than eighty thousand dollars in AI tokens in a single week while
experimenting with a side project. A large technology division reportedly exhausted its annual AI coding
budget months ahead of schedule after adoption outpaced expectation. These are extreme examples, but
they point to a structural issue: token consumption scales with usage in ways that traditional software
licensing never did.
The FinOps Foundation's sixth annual State of FinOps survey, covering 1,192 organizations and published in
February 2026, found that ninety-eight percent of FinOps practitioners now actively manage AI spend, up
from sixty-three percent in 2025 and just thirty-one percent two years earlier. The same research found AI
Page 3 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
has become the fastest-growing new spend category many of these teams track, with a majority reporting
that AI costs exceeded original budget projections.
Scaling enterprise AI is no longer only a model-selection problem. It has become an economics problem.
The enterprise question is no longer ‘Which model should we use?’ It is ‘How do we
deliver the same business outcome with fewer tokens, without losing quality,
governance, or user experience?’
This paper proposes an engineering answer to that question, one that treats cost, accuracy, latency, and
governance as a single design problem rather than four separate conversations.
03. The Enterprise AI Landscape
Most large enterprises now run AI on more than one track at the same time. Native assistants such as
Microsoft Copilot, Amazon Q, and Claude are embedded directly into everyday tools. Custom agentic
systems are built for workflows that native tools do not cover. On-premises and open-weight models
handle sensitive or highly regulated data.
No single model or platform can serve every workload well. A customer-facing chatbot has different latency
and accuracy needs than a back-office document classifier. A coding assistant has different context needs
than a compliance review agent. Enterprises that try to route everything through one model, one context
window, and one cost structure end up paying frontier prices for commodity work.
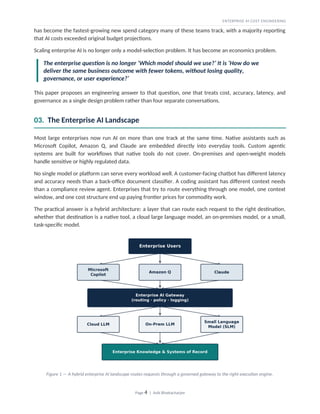
The practical answer is a hybrid architecture: a layer that can route each request to the right destination,
whether that destination is a native tool, a cloud large language model, an on-premises model, or a small,
task-specific model.
Figure 1 — A hybrid enterprise AI landscape routes requests through a governed gateway to the right execution engine.
Page 4 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
04. Token Economics: The New Compute Currency
A token is the basic unit an AI model reads and writes. Every word of a prompt, every retrieved document,
every line of conversation history, and every word of the model's answer is converted into tokens and billed
accordingly.
Tokens behave like a currency. They are consumed on the way in, through prompts and context, and on the
way out, through generated responses. Reasoning-heavy and agentic workloads consume tokens on every
intermediate step as well, not only on the final answer. Gartner's analysis found that per-token prices have
fallen sharply since 2022, yet total enterprise AI spend keeps rising, because agentic workflows use several
times more tokens per task than a simple chatbot query, and adoption is growing faster than unit prices are
falling.
The right way to think about a token is not as a technical detail. It is the smallest unit of AI operating cost,
and it should be traced all the way through to the business outcome it produces.
Figure 2 — Every business request becomes tokens before it becomes value. Cost should be measured end to end.
This is the shift from Cloud FinOps to AI FinOps. Cloud FinOps governs infrastructure spend that is relatively
predictable and centralized. AI spend is different: it grows through many decentralized channels at once,
including employees using copilots, business units deploying their own assistants, and product teams
embedding model calls directly into applications. AI FinOps extends financial governance to cover model
selection, workload routing, token governance, caching, prompt efficiency, and retrieval design, not
infrastructure alone.
05. Where Enterprises Waste Tokens
Most token waste is invisible until someone measures it. It hides inside habits that feel harmless: a slightly
larger prompt template, a chat history that is never trimmed, a retrieval step that returns whole documents
instead of relevant passages.
Common sources of waste include:
• Oversized system prompts that repeat instructions the model does not need for a given task.
• Full chat history carried into every turn of a long conversation, long after earlier turns stopped being
relevant.
• Retrieval-augmented generation (RAG) pipelines that return entire documents instead of the specific
passages that answer the question.
• Repeated retries after a malformed or incomplete response, each one re-sending the full context.
Page 5 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
• Agents that re-plan or re-read context at every step instead of carrying forward a compact working
memory.
• Verbose, unstructured model output where a short, structured answer would have served the
business need.
Anthropic's documentation on prompt caching offers a useful, vendor-verified reference point: caching a
stable prompt prefix, such as system instructions or a large reused document, can cut cost by up to ninety
percent and latency by up to eighty-five percent for long prompts on repeat requests. That single technique
illustrates the broader point. Waste is rarely one dramatic mistake. It is many small, repeated inefficiencies
that compound at scale.
The discipline this paper proposes is simple to state and hard to practice consistently: treat context as a
cost, not a convenience, and reduce it before you retrieve it, not after.
06. The Enterprise AI Cost Engineering Framework (EACEF)
Token optimization techniques matter, but techniques alone do not scale across an enterprise. What scales
is a repeatable framework that every team applies the same way, on every request.
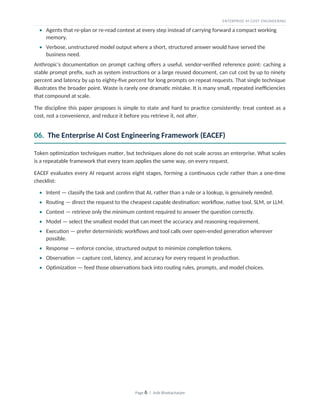
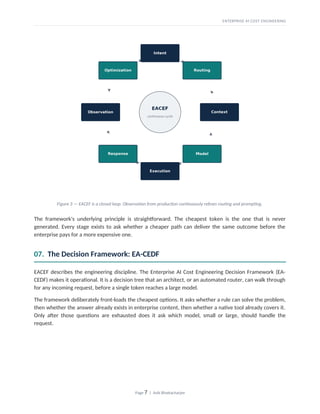
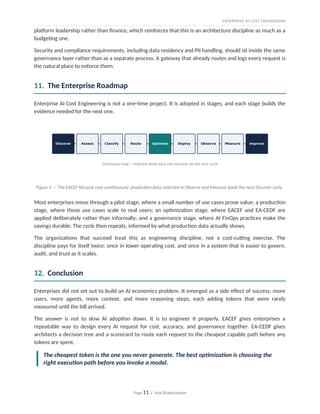
EACEF evaluates every AI request across eight stages, forming a continuous cycle rather than a one-time
checklist:
• Intent — classify the task and confirm that AI, rather than a rule or a lookup, is genuinely needed.
• Routing — direct the request to the cheapest capable destination: workflow, native tool, SLM, or LLM.
• Context — retrieve only the minimum content required to answer the question correctly.
• Model — select the smallest model that can meet the accuracy and reasoning requirement.
• Execution — prefer deterministic workflows and tool calls over open-ended generation wherever
possible.
• Response — enforce concise, structured output to minimize completion tokens.
• Observation — capture cost, latency, and accuracy for every request in production.
• Optimization — feed those observations back into routing rules, prompts, and model choices.
Page 6 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
Figure 3 — EACEF is a closed loop. Observation from production continuously refines routing and prompting.
The framework's underlying principle is straightforward. The cheapest token is the one that is never
generated. Every stage exists to ask whether a cheaper path can deliver the same outcome before the
enterprise pays for a more expensive one.
07. The Decision Framework: EA-CEDF
EACEF describes the engineering discipline. The Enterprise AI Cost Engineering Decision Framework (EA-
CEDF) makes it operational. It is a decision tree that an architect, or an automated router, can walk through
for any incoming request, before a single token reaches a large model.
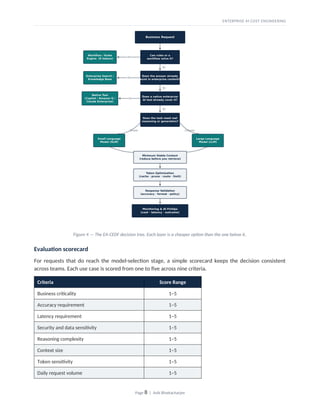
The framework deliberately front-loads the cheapest options. It asks whether a rule can solve the problem,
then whether the answer already exists in enterprise content, then whether a native tool already covers it.
Only after those questions are exhausted does it ask which model, small or large, should handle the
request.
Page 7 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
Figure 4 — The EA-CEDF decision tree. Each layer is a cheaper option than the one below it.
Evaluation scorecard
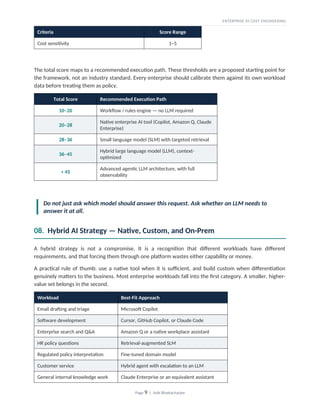
For requests that do reach the model-selection stage, a simple scorecard keeps the decision consistent
across teams. Each use case is scored from one to five across nine criteria.
Criteria Score Range
Business criticality 1–5
Accuracy requirement 1–5
Latency requirement 1–5
Security and data sensitivity 1–5
Reasoning complexity 1–5
Context size 1–5
Token sensitivity 1–5
Daily request volume 1–5
Page 8 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
Criteria Score Range
Cost sensitivity 1–5
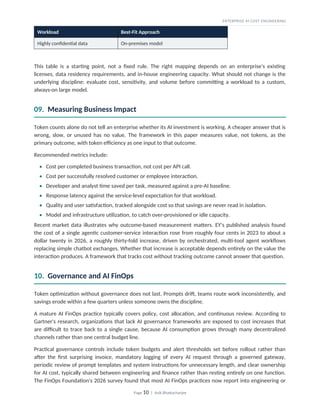
The total score maps to a recommended execution path. These thresholds are a proposed starting point for
the framework, not an industry standard. Every enterprise should calibrate them against its own workload
data before treating them as policy.
Total Score Recommended Execution Path
10–20 Workflow / rules engine — no LLM required
20–28
Native enterprise AI tool (Copilot, Amazon Q, Claude
Enterprise)
28–36 Small language model (SLM) with targeted retrieval
36–45
Hybrid large language model (LLM), context-
optimized
> 45
Advanced agentic LLM architecture, with full
observability
Do not just ask which model should answer this request. Ask whether an LLM needs to
answer it at all.
08. Hybrid AI Strategy — Native, Custom, and On-Prem
A hybrid strategy is not a compromise. It is a recognition that different workloads have different
requirements, and that forcing them through one platform wastes either capability or money.
A practical rule of thumb: use a native tool when it is sufficient, and build custom when differentiation
genuinely matters to the business. Most enterprise workloads fall into the first category. A smaller, higher-
value set belongs in the second.
Workload Best-Fit Approach
Email drafting and triage Microsoft Copilot
Software development Cursor, GitHub Copilot, or Claude Code
Enterprise search and Q&A Amazon Q or a native workplace assistant
HR policy questions Retrieval-augmented SLM
Regulated policy interpretation Fine-tuned domain model
Customer service Hybrid agent with escalation to an LLM
General internal knowledge work Claude Enterprise or an equivalent assistant
Page 9 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
Workload Best-Fit Approach
Highly confidential data On-premises model
This table is a starting point, not a fixed rule. The right mapping depends on an enterprise's existing
licenses, data residency requirements, and in-house engineering capacity. What should not change is the
underlying discipline: evaluate cost, sensitivity, and volume before committing a workload to a custom,
always-on large model.
09. Measuring Business Impact
Token counts alone do not tell an enterprise whether its AI investment is working. A cheaper answer that is
wrong, slow, or unused has no value. The framework in this paper measures value, not tokens, as the
primary outcome, with token efficiency as one input to that outcome.
Recommended metrics include:
• Cost per completed business transaction, not cost per API call.
• Cost per successfully resolved customer or employee interaction.
• Developer and analyst time saved per task, measured against a pre-AI baseline.
• Response latency against the service-level expectation for that workload.
• Quality and user satisfaction, tracked alongside cost so that savings are never read in isolation.
• Model and infrastructure utilization, to catch over-provisioned or idle capacity.
Recent market data illustrates why outcome-based measurement matters. EY's published analysis found
the cost of a single agentic customer-service interaction rose from roughly four cents in 2023 to about a
dollar twenty in 2026, a roughly thirty-fold increase, driven by orchestrated, multi-tool agent workflows
replacing simple chatbot exchanges. Whether that increase is acceptable depends entirely on the value the
interaction produces. A framework that tracks cost without tracking outcome cannot answer that question.
10. Governance and AI FinOps
Token optimization without governance does not last. Prompts drift, teams route work inconsistently, and
savings erode within a few quarters unless someone owns the discipline.
A mature AI FinOps practice typically covers policy, cost allocation, and continuous review. According to
Gartner's research, organizations that lack AI governance frameworks are exposed to cost increases that
are difficult to trace back to a single cause, because AI consumption grows through many decentralized
channels rather than one central budget line.
Practical governance controls include token budgets and alert thresholds set before rollout rather than
after the first surprising invoice, mandatory logging of every AI request through a governed gateway,
periodic review of prompt templates and system instructions for unnecessary length, and clear ownership
for AI cost, typically shared between engineering and finance rather than resting entirely on one function.
The FinOps Foundation's 2026 survey found that most AI FinOps practices now report into engineering or
Page 10 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
platform leadership rather than finance, which reinforces that this is an architecture discipline as much as a
budgeting one.
Security and compliance requirements, including data residency and PII handling, should sit inside the same
governance layer rather than as a separate process. A gateway that already routes and logs every request is
the natural place to enforce them.
11. The Enterprise Roadmap
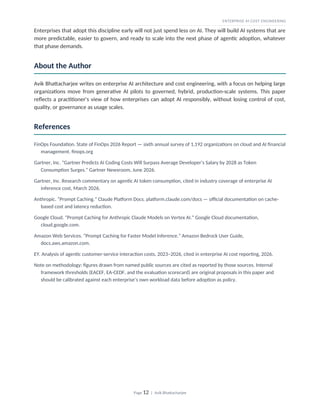
Enterprise AI Cost Engineering is not a one-time project. It is adopted in stages, and each stage builds the
evidence needed for the next one.
Figure 5 — The EACEF lifecycle runs continuously: production data collected in Observe and Measure feeds the next Discover cycle.
Most enterprises move through a pilot stage, where a small number of use cases prove value; a production
stage, where those use cases scale to real users; an optimization stage, where EACEF and EA-CEDF are
applied deliberately rather than informally; and a governance stage, where AI FinOps practices make the
savings durable. The cycle then repeats, informed by what production data actually shows.
The organizations that succeed treat this as engineering discipline, not a cost-cutting exercise. The
discipline pays for itself twice: once in lower operating cost, and once in a system that is easier to govern,
audit, and trust as it scales.
12. Conclusion
Enterprises did not set out to build an AI economics problem. It emerged as a side effect of success: more
users, more agents, more context, and more reasoning steps, each adding tokens that were rarely
measured until the bill arrived.
The answer is not to slow AI adoption down. It is to engineer it properly. EACEF gives enterprises a
repeatable way to design every AI request for cost, accuracy, and governance together. EA-CEDF gives
architects a decision tree and a scorecard to route each request to the cheapest capable path before any
tokens are spent.
The cheapest token is the one you never generate. The best optimization is choosing the
right execution path before you invoke a model.
Page 11 | Avik Bhattacharjee
ENTERPRISE AI COST ENGINEERING
Enterprises that adopt this discipline early will not just spend less on AI. They will build AI systems that are
more predictable, easier to govern, and ready to scale into the next phase of agentic adoption, whatever
that phase demands.
About the Author
Avik Bhattacharjee writes on enterprise AI architecture and cost engineering, with a focus on helping large
organizations move from generative AI pilots to governed, hybrid, production-scale systems. This paper
reflects a practitioner's view of how enterprises can adopt AI responsibly, without losing control of cost,
quality, or governance as usage scales.
References
FinOps Foundation. State of FinOps 2026 Report — sixth annual survey of 1,192 organizations on cloud and AI financial
management. finops.org
Gartner, Inc. “Gartner Predicts AI Coding Costs Will Surpass Average Developer’s Salary by 2028 as Token
Consumption Surges.” Gartner Newsroom, June 2026.
Gartner, Inc. Research commentary on agentic AI token consumption, cited in industry coverage of enterprise AI
inference cost, March 2026.
Anthropic. “Prompt Caching.” Claude Platform Docs. platform.claude.com/docs — official documentation on cache-
based cost and latency reduction.
Google Cloud. “Prompt Caching for Anthropic Claude Models on Vertex AI.” Google Cloud documentation,
cloud.google.com.
Amazon Web Services. “Prompt Caching for Faster Model Inference.” Amazon Bedrock User Guide,
docs.aws.amazon.com.
EY. Analysis of agentic customer-service interaction costs, 2023–2026, cited in enterprise AI cost reporting, 2026.
Note on methodology: figures drawn from named public sources are cited as reported by those sources. Internal
framework thresholds (EACEF, EA-CEDF, and the evaluation scorecard) are original proposals in this paper and
should be calibrated against each enterprise’s own workload data before adoption as policy.
Page 12 | Avik Bhattacharjee