Download as PDF, PPTX
- 1 / 75

- 2 / 75
- 3 / 75
- 4 / 75
- 5 / 75
- 6 / 75
- 7 / 75
- 8 / 75
- 9 / 75
- 10 / 75
- 11 / 75
- 12 / 75
- 13 / 75
- 14 / 75
- 15 / 75
- 16 / 75
- 17 / 75
- 18 / 75
- 19 / 75
- 20 / 75
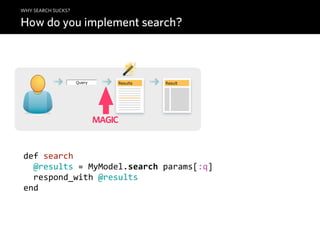
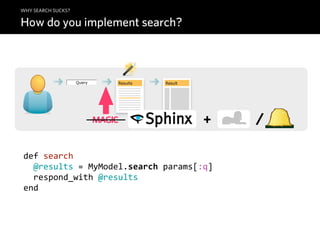
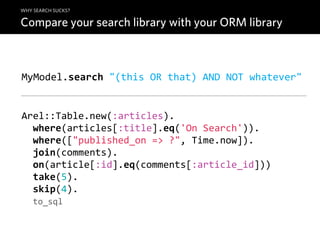
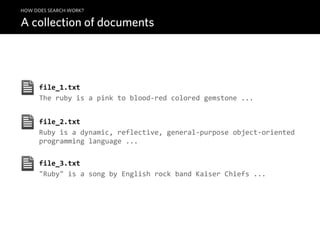
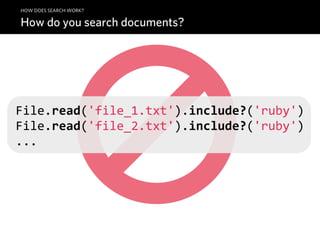
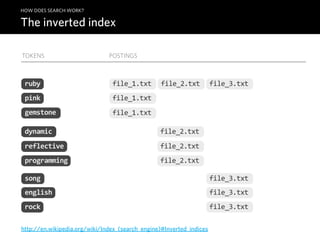
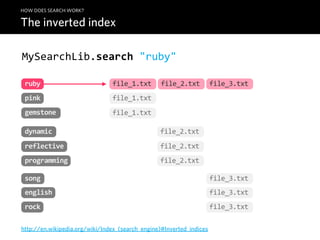
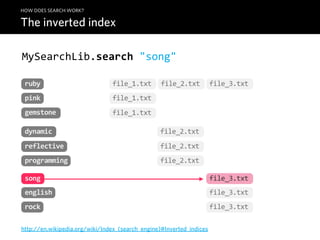
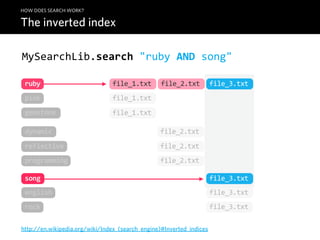
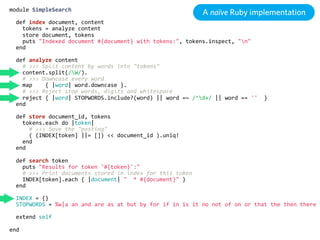
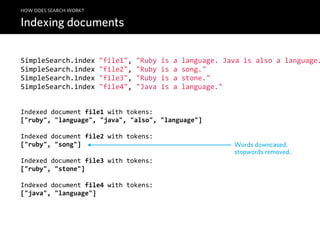
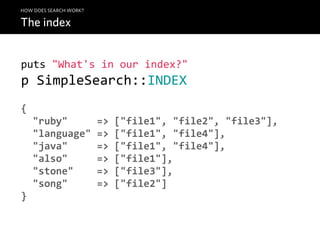
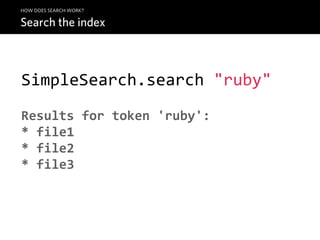
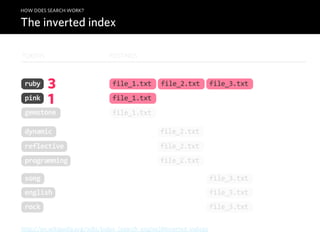
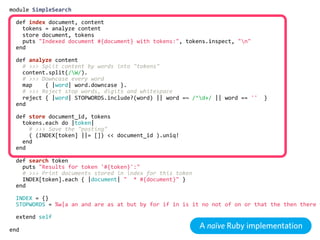
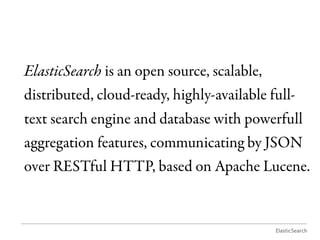
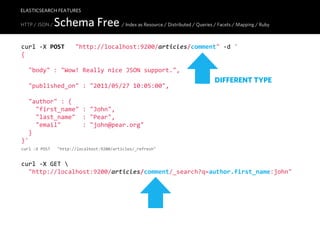
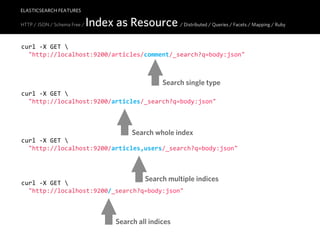
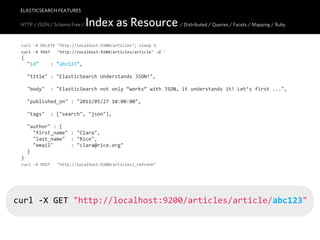
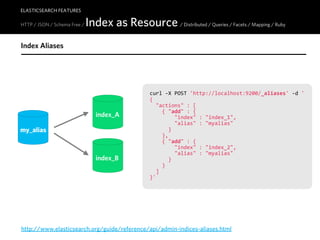
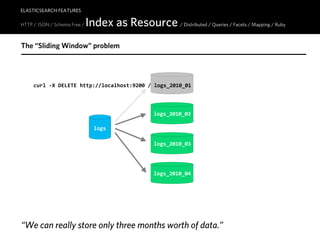
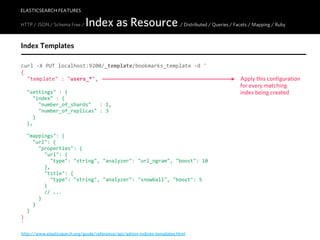
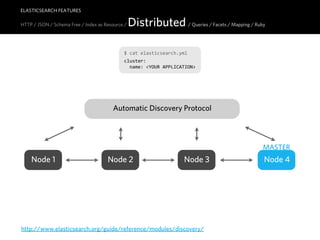
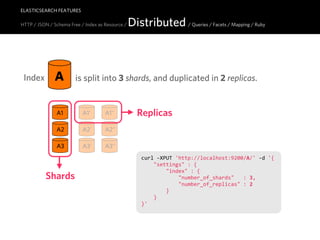
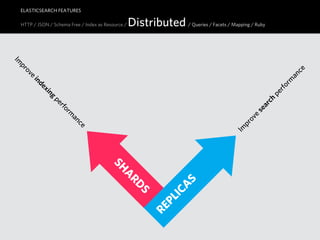
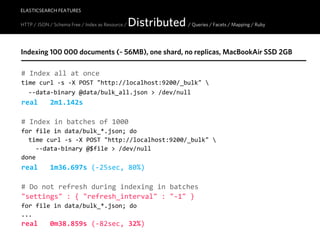
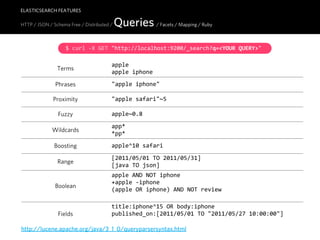
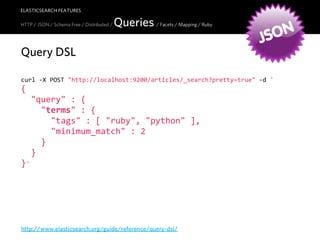
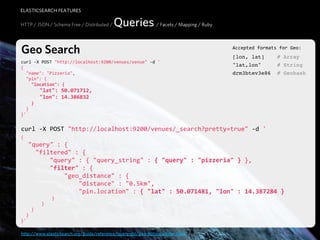
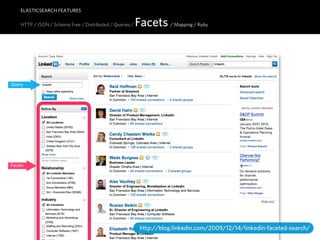
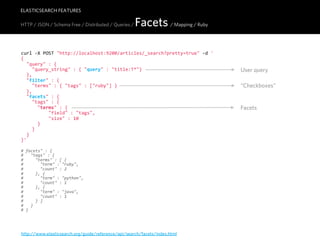
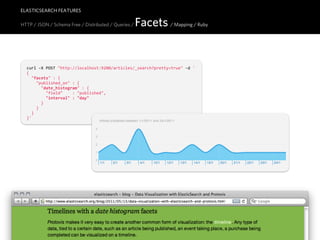
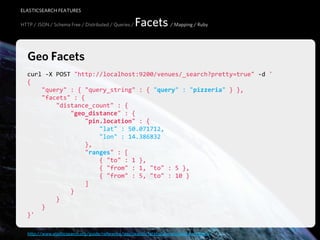
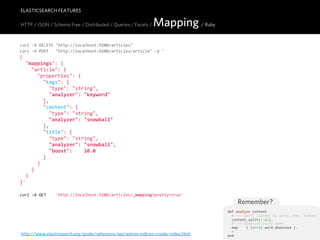
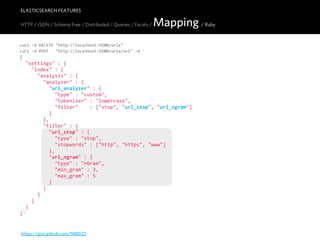
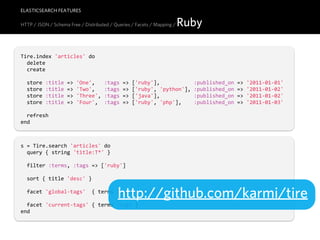
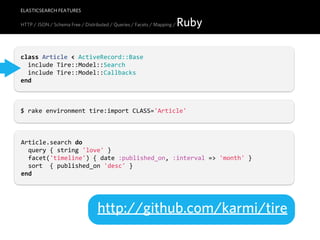
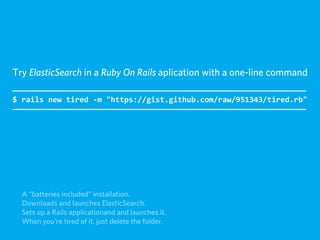

The document discusses search and how it works under the hood. It begins with an overview of common search problems and limitations. It then demonstrates how search works by indexing documents into an inverted index of tokens and associated document references. Key steps include analyzing text by splitting, downcasing, and removing stopwords, and then storing the token postings in the index. Search queries can then be executed by looking up token postings in the index. A Ruby example class demonstrates indexing sample documents and searching the generated index.


