Download to read offline
- 1 / 30
- 2 / 30
- 3 / 30
- 4 / 30
- 5 / 30
- 6 / 30
- 7 / 30
- 8 / 30
- 9 / 30
- 10 / 30
- 11 / 30
- 12 / 30
- 13 / 30
- 14 / 30
- 15 / 30
- 16 / 30
- 17 / 30
- 18 / 30
- 19 / 30
- 20 / 30
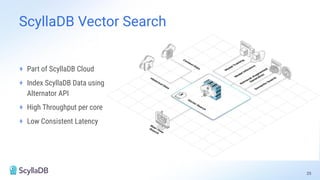
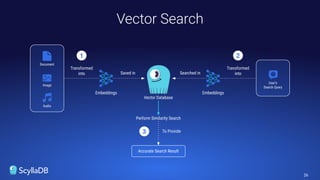

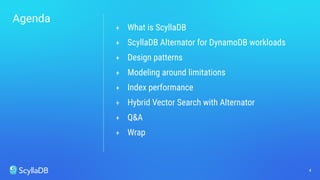
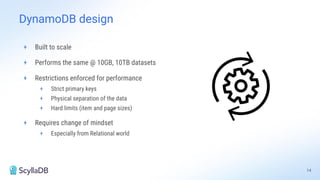
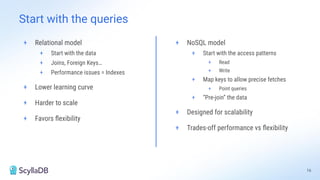
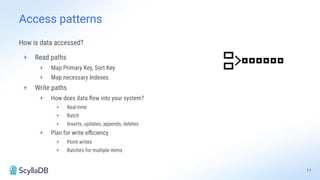
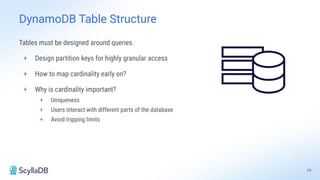
The modeling decisions you make early in a DynamoDB project — how you structure partition keys, design access patterns, and use indexes — can come back to bite you at scale. Join DynamoDB consultant Uriel Bitton and ScyllaDB engineers for a hands-on look at how to optimize your data modeling. We’ll start by focusing on data modeling within DynamoDB itself, then discuss additional options that are available for those who have moved DynamoDB workloads to ScyllaDB (via its DynamoDB-compatible API, Alternator). We'll cover: - Access-pattern-driven design and why it changes how you structure your tables - Partition key strategies that avoid hot spots and uneven throughput - How to model your way around DynamoDB's per-partition throughput limits or avoid it with ScyllaDB Alternator - Index design and where it hurts performance - Working around DynamoDB limits with ScyllaDB Alternator - Tips for hybrid vector search data modeling with ScyllaDB Alternator


