Copyright (C) PresentSquare Co., Ltd. All Rights Reserved.
4. 実験:Ablations
24
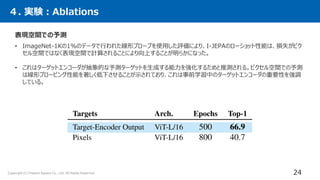
表現空間での予測
• ImageNet-1Kの1%のデータで行われた線形プローブを使用した評価により、I-JEPAのローショット性能は、損失がピク
セル空間ではなく表現空間で計算されることにより向上することが明らかになった。
• これはターゲットエンコーダが抽象的な予測ターゲットを生成する能力を強化するためと推測される。ピクセル空間での予測
は線形プロービング性能を著しく低下させることが示されており、これは事前学習中のターゲットエンコーダの重要性を強調
している。
25.
Copyright (C) PresentSquare Co., Ltd. All Rights Reserved.
5. まとめ
25
① I-JEPAは、手動によるデータ拡張を必要とせずに、高性能な表現を学習する。具体的には、ImageNet-1Kの線形プ
ローブ、半教師ありの1% ImageNet-1K、及び意味転移タスクにおいて、ピクセル再構成手法(例:MAE)を上回る
結果を示す。
② I-JEPAは、意味的なタスクにおいてビュー不変の事前学習アプローチと同等、さらには低レベルの視覚タスク(例:オ
ブジェクトのカウントや深度の予測)においても優れたパフォーマンスを達成する。この結果は、より単純で、誘導バイア
スの少ないモデルを用いることで、より幅広いタスクに対応可能であることを示している。
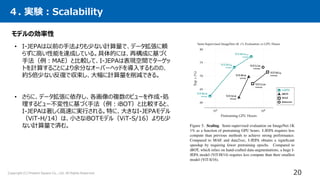
③ I-JEPAはスケーラブルで効率的である。具体的には、ViT-H/14をImageNetで事前学習するのに必要な時間は、
iBOTで事前学習したViT-S/16より2.5倍以上速く、MAEで事前学習したViT-H/14よりも10倍以上効率的である。
予測を表現空間で行うことで、自己教師あり事前学習に必要な総計算量を大幅に削減することができる。
実証内容
26.
Copyright (C) PresentSquare Co., Ltd. All Rights Reserved.
Appendix
参考文献
[4] Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael
Rabbat, and Nicolas Ballas. Masked siamese networks for label-efficient learning. European Conference on Computer Vision,
2022.
[7] Alexei Baevski, Arun Babu, Wei-Ning Hsu, and Michael Auli. Efficient self-supervised learning with contextualized target
representations for vision, speech and language. arXiv preprint arXiv:2212.07525, 2022.
[8] Alexei Baevski,Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, and Michael Auli. Data2vec: A general framework for
self-supervised learning in speech, vision and language. arXiv preprint arXiv:2202.03555, 2022
[17] Mathilde Caron, Ishan Misra, Julien Mairal, Priya Goyal, Piotr Bojanowski, and Armand Joulin. Unsupervised learning of
visual features by contrasting cluster assignments. arXiv preprint arXiv:2006.09882, 2020.
[36] Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Doll´ar, and Ross Girshick. Masked autoencoders are scalable
vision learners. IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2022.
[49] Yann LeCun, Sumit Chopra, Raia Hadsell, M Ranzato, and Fujie Huang. A tutorial on energy-based learning. Predicting
structured data, 1(0), 2006.
[79] Jinghao Zhou, Chen Wei, Huiyu Wang, Wei Shen, Cihang Xie, Alan Yuille, and Tao Kong. Ibot: Image bert pretraining
with online tokenizer. International Conference on Learning Representations, 2022.
26