IBM Systems
Michael Gildein
IBM z/OS Analytics Test Architect
megildei@us.ibm.com
#NittanyWatson
Data Cleansing
Nittany Watson
Challenge
IBM Systems
Agenda
• Objective
• ETL Process
• Extract
• Transform
• Load
• Examples
• Anonymizing Data
• Joining Data
| 224 January 2017
IBM Systems
What is it?
| 324 January 2017 IBM Confidential
IBM Systems
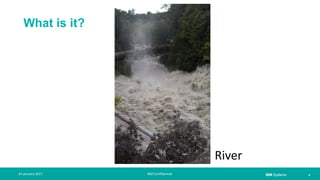
What is it?
| 424 January 2017 IBM Confidential
River
IBM Systems
What does it mean?
“Before SVT can begin we must DCUT a new APAR then we can roll it out
to the POC next week.”
“I tried IPLing the second lpar of the plex but we hit a slip causing a
waitstate.”
| 524 January 2017 IBM Confidential
IBM Systems
Objective
Cleanse data sources to produce high data quality in order to accurately
identify and extract trends and insights.
| 624 January 2017
Why?
Garbage In == Garbage Out!!
Imagine, having a blurry or out of
focus picture. How hard is it to
figure out what the picture is of?
Raw Data Data & Context Information
IBM Systems
Data Constraints
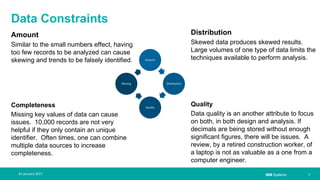
Amount
Similar to the small numbers effect, having
too few records to be analyzed can cause
skewing and trends to be falsely identified.
Completeness
Missing key values of data can cause
issues. 10,000 records are not very
helpful if they only contain an unique
identifier. Often times, one can combine
multiple data sources to increase
completeness.
| 724 January 2017
Distribution
Skewed data produces skewed results.
Large volumes of one type of data limits the
techniques available to perform analysis.
Quality
Data quality is an another attribute to focus
on both, in both design and analysis. If
decimals are being stored without enough
significant figures, there will be issues. A
review, by a retired construction worker, of
a laptop is not as valuable as a one from a
computer engineer.
Amount
Distribution
Quality
Missing
IBM Systems | 824 January 2017
ETL Process
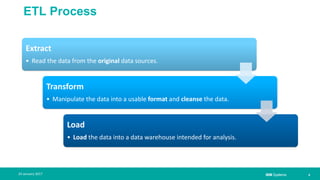
Extract
• Read the data from the original data sources.
Transform
• Manipulate the data into a usable format and cleanse the data.
Load
• Load the data into a data warehouse intended for analysis.
IBM Systems
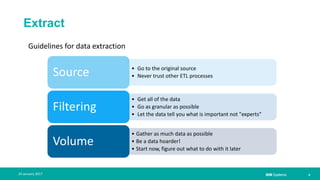
Extract
| 924 January 2017
• Go to the original source
• Never trust other ETL processesSource
• Get all of the data
• Go as granular as possible
• Let the data tell you what is important not "experts"
Filtering
• Gather as much data as possible
• Be a data hoarder!
• Start now, figure out what to do with it later
Volume
Guidelines for data extraction
IBM Systems
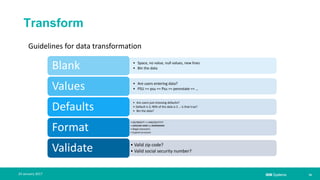
Transform
| 1024 January 2017
• Space, no value, null values, new lines
• Bin the dataBlank
• Are users entering data?
• PSU == psu == Psu == pennstate == …Values
• Are users just choosing defaults?
• Default is 2; 90% of the data is 2 … is that true?
• Bin the data?Defaults
• DD/MM/YY => MM/DD/YYYY
• (###)###-#### or ##########
• Illegal characters
• Expand acronyms
Format
• Valid zip code?
• Valid social security number?Validate
Guidelines for data transformation
IBM Systems
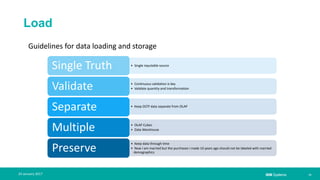
Load
| 1124 January 2017
• Single reputable source
Single Truth
• Continuous validation is key
• Validate quantity and transformationValidate
• Keep OLTP data separate from OLAP
Separate
• OLAP Cubes
• Data WarehouseMultiple
• Keep data through time
• Now I am married but the purchases I made 10 years ago should not be labeled with married
demographics
Preserve
Guidelines for data loading and storage
IBM Systems
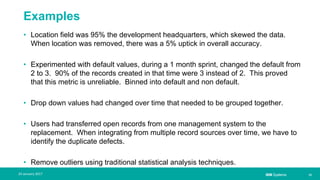
Examples
• Location field was 95% the development headquarters, which skewed the data.
When location was removed, there was a 5% uptick in overall accuracy.
• Experimented with default values, during a 1 month sprint, changed the default from
2 to 3. 90% of the records created in that time were 3 instead of 2. This proved
that this metric is unreliable. Binned into default and non default.
• Drop down values had changed over time that needed to be grouped together.
• Users had transferred open records from one management system to the
replacement. When integrating from multiple record sources over time, we have to
identify the duplicate defects.
• Remove outliers using traditional statistical analysis techniques.
| 1224 January 2017
IBM Systems
Anonymizing Data
Why?
• To protect privacy for legal and/or ethical reasons.
What?
• Remove identifying features such as
• Record ID, Names, DOB, Phone numbers
• Keep things syntactically correct
• Street Addresses (111 Main St. => 849 Alpaca Ln.)
• Keep Zipcodes and country codes
• Randomize record order
• Translation key to back reference may be helpful or unwanted (hash vs encryption)
| 1324 January 2017
IBM Systems
Unstructured Data
Data has no or less formatting than traditional data systems
Examples:
• Twitter
• Reviews
• Audio/video media
Considerations:
• Abbreviations
• Slang
• Domain specific terms
| 1424 January 2017
IBM Systems
Academia Model
Student Records
Student ID, Name, Gender, DOB, Credits Earned, Credits in Progress,
Transfer Credits, Previous School(s) ID
Courses
Course ID, Course Name, Course Description
Offerings
Course ID, Semester ID, Professor, Section #
Grades
Student ID, Course Offering, Grade
Semesters
Semester ID, Start Date, End Date
| 1524 January 2017 IBM Confidential
IBM Systems
Joining Data
Records and data are often stored in disparate systems.
It would be is easy if…
• All records of data have unique keys that can be joined to create a single
record
• Student ID: 0001 Name: Michael Gildein in all campuses
Practical:
• Join on complex unique identifiers (name & zip & DOB)
• Possible issue Mike vs Michael and Jr. vs Sr.
| 1624 January 2017 IBM Confidential
IBM Systems
Summary
• Data cleansing is a non-trivial task.
• Data must continuously be cleansed and validated.
• Data quality greatly effects the outcome of analysis.
• Get as much data as possible.
• Let the data tell you.
| 1724 January 2017
IBM SystemsIBM Systems
Questions?
| 1824 January 2017
IBM SystemsIBM Systems
Backup
| 1924 January 2017