MEASURES OF
CENTRAL
TENDENCY
BY:
Mrs.Keerthi Samuel
Asst.Professor,
INTRODUCTION AND DEFINITION
• Measures of central tendency is a typical value of the entire data.
• It describes the characteristics of the entire data.
• It is the value around which other values are distributed.
• It gives us the mental picture of the central value which is generally called average or
central tendency.
• This value always lies between maximum and minimum values and generally , it is
located in the center or middle of the distribution.
• Mean, median and mode are commonly used averages.
CHARACTERISTICS
• It should be easy to understand
• It should be rigidly defined
• It should be easy to calculate and simple to follow
• It should be based on all the observations of the series.
• It should not be affected by fluctuations of sampling
CLASSIFICATION
AVERAGES
MATHEMATICAL
AVERAGE
ARTHEMATIC
MEAN
POSITIONAL
AVERAGE
MEDIAN
MODE
MERITS
• Easy to understand
• Easy to calculate
• It takes into account each and every observation
• Sampling fluctuations do not affect the value of mean
• It is easy for further calculation
DEMERITS
• It is influenced by very big or very small numbers.
• example: the mean of 10,80,90,1,4 is 37 . This mean 37 neither represents big
number like 80,90 nor represent small numbers like 10,1,4 properly.
• Sometimes it looks ridiculous when we calculate average number of children born to the
women. We may get a mean value of 2.5 children. This id evidently absurd.
• It is not a positional average like median and mode.
• Sometimes it may give false conclusions.
ARTHEMATIC MEAN
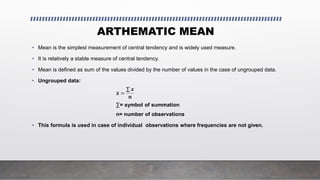
• Mean is the simplest measurement of central tendency and is widely used measure.
• It is relatively a stable measure of central tendency.
• Mean is defined as sum of the values divided by the number of values in the case of ungrouped data.
• Ungrouped data:
𝒙 =
𝒙
𝒏
∑= symbol of summation
n= number of observations
• This formula is used in case of individual observations where frequencies are not given.
ARTHEMATIC MEAN
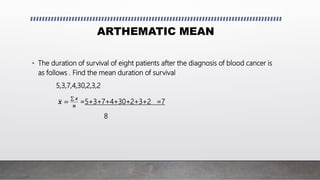
• The duration of survival of eight patients after the diagnosis of blood cancer is
as follows . Find the mean duration of survival
5,3,7,4,30,2,3,2
𝒙 =
𝒙
𝒏
=5+3+7+4+30+2+3+2 =7
8
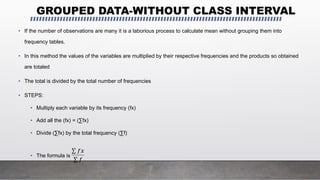
GROUPED DATA-WITHOUT CLASS INTERVAL
• If the number of observations are many it is a laborious process to calculate mean without grouping them into
frequency tables.
• In this method the values of the variables are multiplied by their respective frequencies and the products so obtained
are totaled
• The total is divided by the total number of frequencies
• STEPS:
• Multiply each variable by its frequency (fx)
• Add all the (fx) = (∑fx)
• Divide (∑fx) by the total frequency (∑f)
• The formula is
𝑓𝑥
𝑓
GROUPED DATA-WITHOUT CLASS INTERVAL
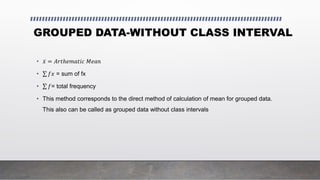
• 𝑥 = 𝐴𝑟𝑡ℎ𝑒𝑚𝑎𝑡𝑖𝑐 𝑀𝑒𝑎𝑛
• 𝑓𝑥 = sum of fx
• 𝑓= total frequency
• This method corresponds to the direct method of calculation of mean for grouped data.
This also can be called as grouped data without class intervals
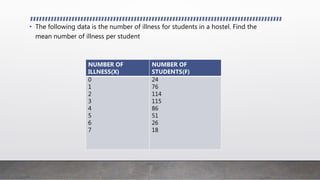
• The following data is the number of illness for students in a hostel. Find the
mean number of illness per student
NUMBER OF
ILLNESS(X)
NUMBER OF
STUDENTS(F)
0
1
2
3
4
5
6
7
24
76
114
115
86
51
26
18
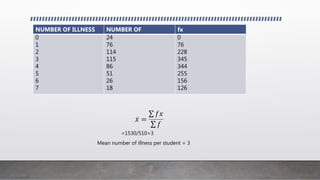
𝑥 =
𝑓𝑥
𝑓
=1530/510=3
Mean number of illness per student = 3
NUMBER OF ILLNESS NUMBER OF fx
0
1
2
3
4
5
6
7
24
76
114
115
86
51
26
18
0
76
228
345
344
255
156
126
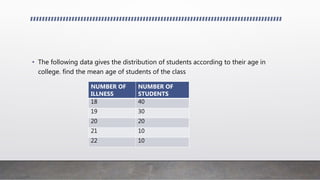
• The following data gives the distribution of students according to their age in
college. find the mean age of students of the class
NUMBER OF
ILLNESS
NUMBER OF
STUDENTS
18 40
19 30
20 20
21 10
22 10
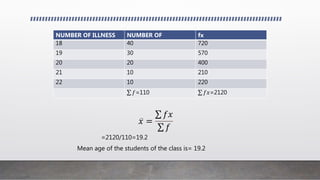
𝑥 =
𝑓𝑥
𝑓
=2120/110=19.2
Mean age of the students of the class is= 19.2
NUMBER OF ILLNESS NUMBER OF fx
18 40 720
19 30 570
20 20 400
21 10 210
22 10 220
𝑓=110 𝑓𝑥=2120
GROUPED DATA WITH CLASS INTERVAL
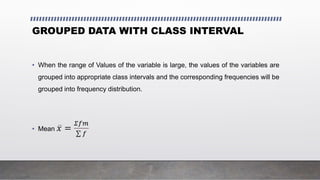
• When the range of Values of the variable is large, the values of the variables are
grouped into appropriate class intervals and the corresponding frequencies will be
grouped into frequency distribution.
• Mean 𝑥 =
𝛴𝑓𝑚
𝑓
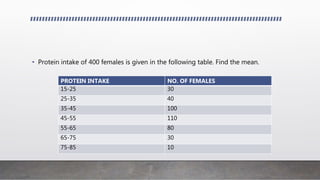
• Protein intake of 400 females is given in the following table. Find the mean.
PROTEIN INTAKE NO. OF FEMALES
15-25 30
25-35 40
35-45 100
45-55 110
55-65 80
65-75 30
75-85 10
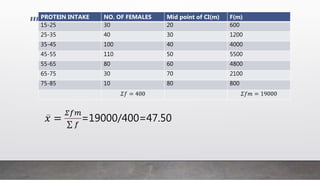
𝑥 =
𝛴𝑓𝑚
𝑓
=19000/400=47.50
PROTEIN INTAKE NO. OF FEMALES Mid point of CI(m) F(m)
15-25 30 20 600
25-35 40 30 1200
35-45 100 40 4000
45-55 110 50 5500
55-65 80 60 4800
65-75 30 70 2100
75-85 10 80 800
𝛴𝑓 = 400 𝛴𝑓𝑚 = 19000
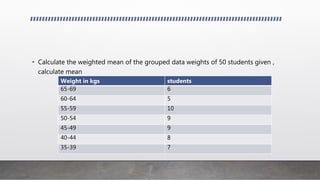
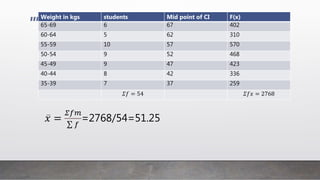
• Calculate the weighted mean of the grouped data weights of 50 students given ,
calculate mean
Weight in kgs students
65-69 6
60-64 5
55-59 10
50-54 9
45-49 9
40-44 8
35-39 7
𝑥 =
𝛴𝑓𝑚
𝑓
=2768/54=51.25
Weight in kgs students Mid point of CI F(x)
65-69 6 67 402
60-64 5 62 310
55-59 10 57 570
50-54 9 52 468
45-49 9 47 423
40-44 8 42 336
35-39 7 37 259
𝛴𝑓 = 54 𝛴𝑓𝑥 = 2768
MEDIAN
MEDIAN
• A value that divides a distribution into two equal halves or central or middle value
of a series of observations, when the observed values are arranged in ascending
or descending order of magnitude.
• Median is just the 50th perceive value. Median is denoted by’Md’
• Like mean, median can also be calculated.
• Ungrouped data
• Discrete series
• Continous series
MEDIAN-UNGROUPED DATA
• STEP-I:
• Arrange the data in ascending or descending order of magnitude
• STEP-2:
• If the number of items are odd, n+1/2 th item gives the serial number of the median.
• If the number of items are even, the average of n/2th and n/2+1 th item gives the
serial number of the median.
MEDIAN-PROBLEM
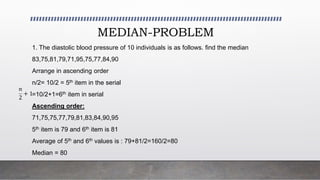
1. The diastolic blood pressure of 10 individuals is as follows. find the median
83,75,81,79,71,95,75,77,84,90
Arrange in ascending order
n/2= 10/2 = 5th item in the serial
=10/2+1=6th item in serial
Ascending order:
71,75,75,77,79,81,83,84,90,95
5th item is 79 and 6th item is 81
Average of 5th and 6th values is : 79+81/2=160/2=80
Median = 80
𝑛
2
+ 1
MEDIAN-PROBLEM
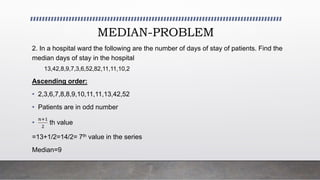
2. In a hospital ward the following are the number of days of stay of patients. Find the
median days of stay in the hospital
13,42,8,9,7,3,6,52,82,11,11,10,2
Ascending order:
• 2,3,6,7,8,8,9,10,11,11,13,42,52
• Patients are in odd number
•
𝑛+1
2
th value
=13+1/2=14/2= 7th value in the series
Median=9
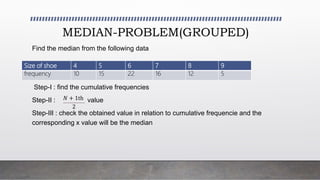
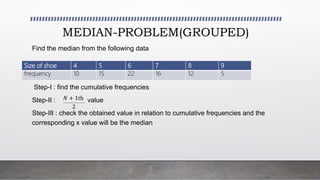
MEDIAN-PROBLEM(GROUPED)
Find the median from the following data
Step-I : find the cumulative frequencies
Step-II : value
Step-III : check the obtained value in relation to cumulative frequencie and the
corresponding x value will be the median
Size of shoe 4 5 6 7 8 9
frequency 10 15 22 16 12 5
𝑁 + 1th
2
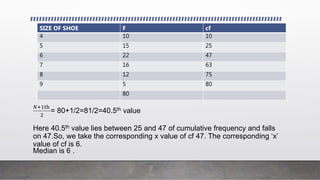
𝑁+1th
2
= 80+1/2=81/2=40.5th value
Here 40.5th value lies between 25 and 47 of cumulative frequency and falls
on 47.So, we take the corresponding x value of cf 47. The corresponding ‘x’
value of cf is 6.
Median is 6 .
SIZE OF SHOE F cf
4 10 10
5 15 25
6 22 47
7 16 63
8 12 75
9 5 80
80
MEDIAN-PROBLEM(GROUPED)
Find the median from the following data
Step-I : find the cumulative frequencies
Step-II : value
Step-III : check the obtained value in relation to cumulative frequencies and the
corresponding x value will be the median
Size of shoe 4 5 6 7 8 9
frequency 10 15 22 16 12 5
𝑁 + 1th
2
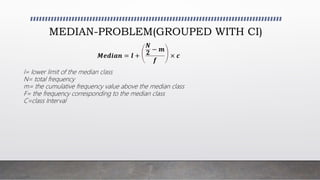
MEDIAN-PROBLEM(GROUPED WITH CI)
𝑴𝒆𝒅𝒊𝒂𝒏 = 𝒍 +
𝑵
𝟐
− 𝒎
𝒇
× 𝒄
l= lower limit of the median class
N= total frequency
m= the cumulative frequency value above the median class
F= the frequency corresponding to the median class
C=class Interval
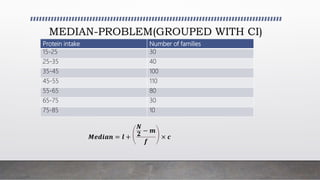
MEDIAN-PROBLEM(GROUPED WITH CI)
𝑴𝒆𝒅𝒊𝒂𝒏 = 𝒍 +
𝑵
𝟐
− 𝒎
𝒇
× 𝒄
Protein intake Number of families
15-25 30
25-35 40
35-45 100
45-55 110
55-65 80
65-75 30
75-85 10
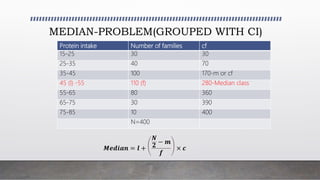
MEDIAN-PROBLEM(GROUPED WITH CI)
𝑴𝒆𝒅𝒊𝒂𝒏 = 𝒍 +
𝑵
𝟐
− 𝒎
𝒇
× 𝒄
Protein intake Number of families cf
15-25 30 30
25-35 40 70
35-45 100 170-m or cf
45 (l) -55 110 (f) 280-Median class
55-65 80 360
65-75 30 390
75-85 10 400
N=400
MEDIAN-PROBLEM(GROUPED WITH CI)
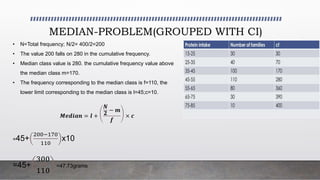
• N=Total frequency; N/2= 400/2=200
• The value 200 falls on 280 in the cumulative frequency.
• Median class value is 280. the cumulative frequency value above
the median class m=170.
• The frequency corresponding to the median class is f=110, the
lower limit corresponding to the median class is l=45;c=10.
𝑴𝒆𝒅𝒊𝒂𝒏 = 𝒍 +
𝑵
𝟐
− 𝒎
𝒇
× 𝒄
=45+
200−170
110
x10
=45+
300
110
=47.73grams
MEDIAN
ADVANTAGES:
• It is simple to calculate and easy to understand
• It can be located by inspection
• The value of median is unaffected by extreme values
• Its value generally lies in distribution.
DISADVANTAGES:
• Median is not familiar average like mean.
• If the data is large , it is tedious to arrange the data in ascending order.
• Since, it is a positional average, the value is not influenced by each and every observation.
• The median value is affected by sampling fluctuations.
MODE
• Mode is the most frequently occurring value in a series of observations.
• Mode is also a positional average. This is the another measure of central tendency which is least
influenced by the size of the individual observations.
• Mode is more useful in certain type od observations , where it is required to know the value of
observation, which has high influence in the series.
• Ex: when studying the age of attack , or onset of a disease it is advisable to know the maximum
number of persons are affected rather than the mean age of onset or median age of onset.
• Mode also can be calculated from the following relationship, if median and mean are known.
Mode=3(median)-2(mean)
MODE-TYPES
• The most frequently occurring value in the series of observations.
• Ex: 4,5,8,6,7,5,9,5
• Mode is 5
• BIMODEL:
• If two sets of observations are same or distribution with two modes is bimodal
• Ex: 4,8,9,10,4,6,12,10
• Bimodel:4 and 10
• MULTIMODEL:
• If more than two sets of observations are same or distribution with more than two modes is
multimodel.
• Ex: 5,8,9,10,5,9,16,8
• Multimodel:5,8,9
MODE-UNGROUPED DATA
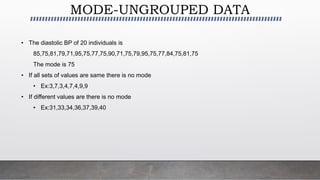
• The diastolic BP of 20 individuals is
85,75,81,79,71,95,75,77,75,90,71,75,79,95,75,77,84,75,81,75
The mode is 75
• If all sets of values are same there is no mode
• Ex:3,7,3,4,7,4,9,9
• If different values are there is no mode
• Ex:31,33,34,36,37,39,40
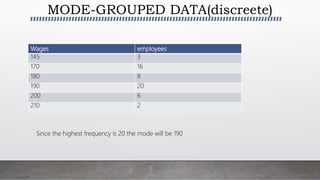
MODE-GROUPED DATA(discreete)
Wages employees
145 3
170 16
180 8
190 20
200 6
210 2
Since the highest frequency is 20 the mode will be 190
MODE-GROUPED DATA(Continous)
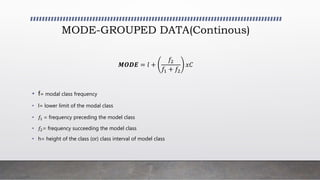
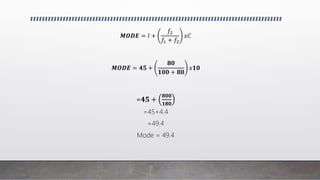
𝑴𝑶𝑫𝑬 = 𝑙 +
𝑓2
𝑓1 + 𝑓2
𝑥𝐶
• f= modal class frequency
• l= lower limit of the modal class
• 𝑓1 = frequency preceding the model class
• 𝑓2= frequency succeeding the model class
• h= height of the class (or) class interval of model class
MODE-GROUPED DATA(Continous)
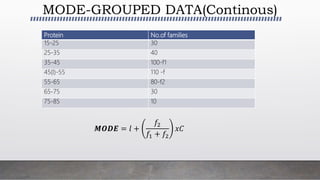
Protein No.of families
15-25 30
25-35 40
35-45 100-f1
45(l)-55 110 -f
55-65 80-f2
65-75 30
75-85 10
𝑴𝑶𝑫𝑬 = 𝑙 +
𝑓2
𝑓1 + 𝑓2
𝑥𝐶
𝑴𝑶𝑫𝑬 = 𝑙 +
𝑓2
𝑓1 + 𝑓2
𝑥𝐶
𝑴𝑶𝑫𝑬 = 𝟒𝟓 +
𝟖𝟎
𝟏𝟎𝟎 + 𝟖𝟎
𝑥𝟏𝟎
= 𝟒𝟓 +
𝟖𝟎𝟎
𝟏𝟖𝟎
=45+4.4
=49.4
Mode = 49.4
MERITS
• It is easy to understand and not affected by the extreme values
• It is a positional average and can be located easily by inspection
DEMERITS
• It is an average, which is ill defined and indeterminate
• In the case of bimodal class, the calculation is difficult as it involves grouping and
analysis
• It is not based on all observations
• The exact location is uncertain
• Mode is not used in biological and medical sciences