Building the First Agentic
Model for Edge Devices
Maxime Labonne
Cohere Labs Summer School 2026
29 July, 2026
Why edge models?
Cost
Tokens are free
Cost
Tokens are free
Connectivity
Offline applications
Latency
Small and local > big and remote
Why edge models?
Privacy
Data stays on device
Cost
Tokens are free
Connectivity
Offline applications
Latency
Small and local > big and remote
Why edge models?
Privacy
Data stays on device
Cost
Tokens are free
Connectivity
Offline applications
Latency
Small and local > big and remote
Why edge models?
Privacy
Data stays on device
Cost
Tokens are free
Connectivity
Offline applications
Latency
Small and local > big and remote
Why edge models?
Privacy
Data stays on device
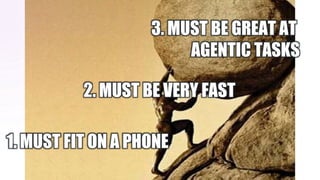
1. MUST FIT ON A PHONE
2. MUST BE VERY FAST
1. MUST FIT ON A PHONE
2. MUST BE VERY FAST
3. MUST BE GREAT AT
AGENTIC TASKS
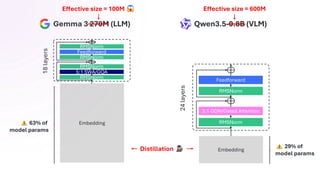
Architecture
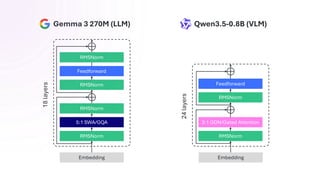
RMSNorm
3:1 GDN/Gated Attention
RMSNorm
Feedforward
Gemma 3 270M (LLM) Qwen3.5-0.8B (VLM)
24
layers
18
layers
RMSNorm
5:1 SWA/GQA
RMSNorm
Feedforward
RMSNorm
RMSNorm
Embedding Embedding
RMSNorm
3:1 GDN/Gated Attention
RMSNorm
Feedforward
24
layers
Embedding
Embedding
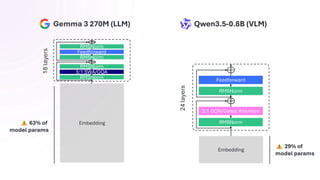
63% of
model params
29% of
model params
Gemma 3 270M (LLM) Qwen3.5-0.8B (VLM)
18
layers
RMSNorm
5:1 SWA/GQA
RMSNorm
Feedforward
RMSNorm
RMSNorm
RMSNorm
3:1 GDN/Gated Attention
RMSNorm
Feedforward
24
layers
Embedding
Embedding
63% of
model params
29% of
model params
Gemma 3 270M (LLM) Qwen3.5-0.8B (VLM)
18
layers
RMSNorm
5:1 SWA/GQA
RMSNorm
Feedforward
RMSNorm
RMSNorm
Effective size = 100M Effective size = 600M
Distillation
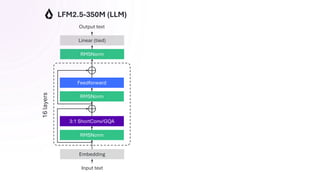
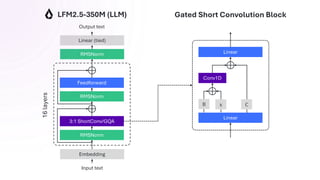
RMSNorm
3:1 ShortConv/GQA
RMSNorm
Feedforward
LFM2.5-350M (LLM)
16
layers
Embedding
Input text
RMSNorm
Linear (tied)
Output text
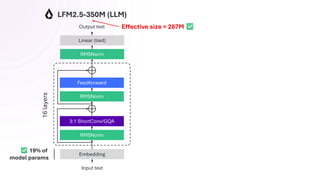
RMSNorm
3:1 ShortConv/GQA
RMSNorm
Feedforward
LFM2.5-350M (LLM)
Embedding
Input text
RMSNorm
Linear (tied)
Output text
16
layers
19% of
model params
Effective size = 287M
RMSNorm
3:1 ShortConv/GQA
RMSNorm
Feedforward
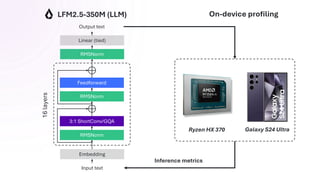
LFM2.5-350M (LLM)
16
layers
Embedding
Input text
RMSNorm
Linear (tied)
Output text
Inference metrics
Galaxy S24 Ultra
On-device profiling
Ryzen HX 370
RMSNorm
3:1 ShortConv/GQA
RMSNorm
Feedforward
LFM2.5-350M (LLM)
Embedding
Input text
RMSNorm
Linear (tied)
Output text
Linear
Linear
Conv1D
B x
Gated Short Convolution Block
C
16
layers
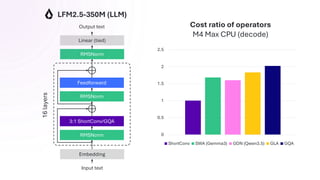
0
0.5
1
1.5
2
2.5
ShortConv SWA (Gemma3) GDN (Qwen3.5) GLA GQA
RMSNorm
3:1 ShortConv/GQA
RMSNorm
Feedforward
LFM2.5-350M (LLM)
Embedding
Input text
RMSNorm
Linear (tied)
Output text Cost ratio of operators
M4 Max CPU (decode)
16
layers
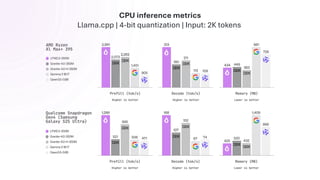
CPU inference metrics
Llama.cpp | 4-bit quantization | Input: 2K tokens
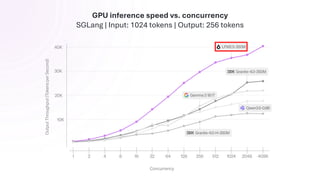
GPU inference speed vs. concurrency
SGLang | Input: 1024 tokens | Output: 256 tokens
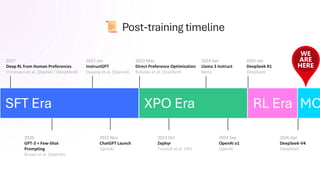
Post-training
SFT Era XPO Era RL Era
2017
Deep RL from Human Preferences
Christiano et al. (OpenAI / DeepMind)
2020
GPT-3 + Few-Shot
Prompting
Brown et al. (OpenAI)
2022 Jan
InstructGPT
Ouyang et al. (OpenAI)
2022 Nov
ChatGPT Launch
OpenAI
2023 Oct
Zephyr
Tunstall et al. (HF)
2024 Apr
Llama 3 Instruct
Meta
2023 May
Direct Preference Optimization
Rafailov et al. (Stanford)
2024 Sep
OpenAI o1
OpenAI
2025 Jan
DeepSeek R1
DeepSeek
Post-training timeline
MO
2026 Apr
DeepSeek-V4
DeepSeek
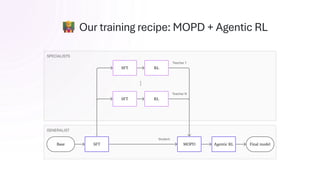
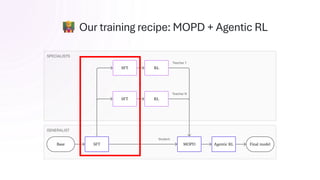
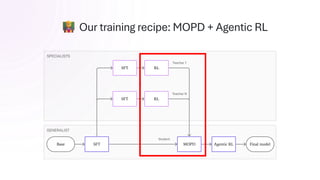
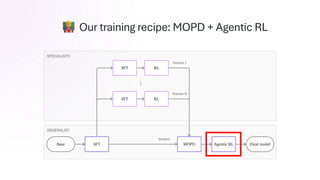
Our training recipe: MOPD + Agentic RL
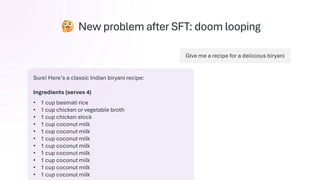
New problem after SFT: doom looping
Give me a recipe for a delicious biryani
Sure! Here’s a classic Indian biryani recipe:
Ingredients (serves 4)
• 1 cup basmati rice
• 1 cup chicken or vegetable broth
• 1 cup chicken stock
• 1 cup coconut milk
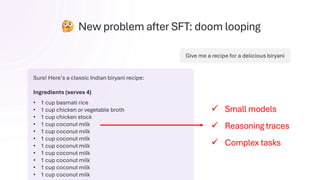
New problem after SFT: doom looping
Give me a recipe for a delicious biryani
Sure! Here’s a classic Indian biryani recipe:
Ingredients (serves 4)
• 1 cup basmati rice
• 1 cup chicken or vegetable broth
• 1 cup chicken stock
• 1 cup coconut milk
✓ Small models
✓ Reasoning traces
✓ Complex tasks
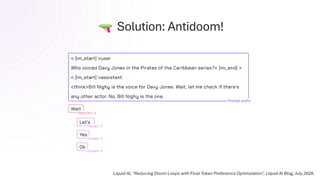
Solution: Antidoom!
Liquid AI, "Reducing Doom Loops with Final Token Preference Optimization", Liquid AI Blog, July 2026.
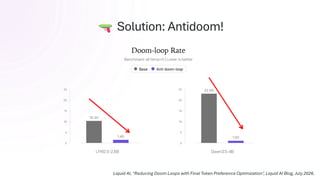
Solution: Antidoom!
Liquid AI, "Reducing Doom Loops with Final Token Preference Optimization", Liquid AI Blog, July 2026.
Our training recipe: MOPD + Agentic RL
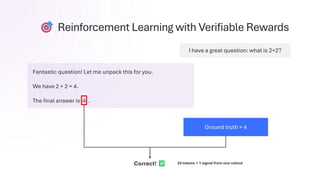
I have a great question: what is 2+2?
Fantastic question! Let me unpack this for you.
We have 2 + 2 = 4.
The final answer is 4 .
Ground truth = 4
Correct!
Reinforcement Learning with Verifiable Rewards
24 tokens → 1 signal from one rollout
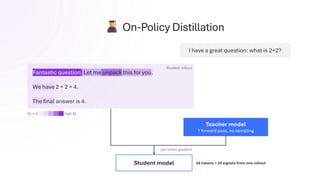
I have a great question: what is 2+2?
Student rollout
Fantastic question! Let me unpack this for you.
We have 2 + 2 = 4.
The final answer is 4.
per-token gradient
Student model 24 tokens → 24 signals from one rollout
KL ≈ 0 high KL
On-Policy Distillation
Teacher model
1 forward pass, no sampling
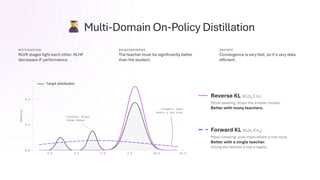
Multi-Domain On-Policy Distillation
MOTIVATION
RLVR stages fight each other: RLHF
decreases IF performance.
REQUIREMENT
The teacher must be significantly better
than the student.
PAYOFF
Convergence is very fast, so it’s very data
efficient.
Reverse KL KL(πθ ‖ πT)
Mode-seeking: drops the smaller modes.
Better with many teachers.
Forward KL KL(πT ‖ πθ)
Mass-covering: puts mass where p has none.
Better with a single teacher.
(Using the teacher’s top-k logits)
Our training recipe: MOPD + Agentic RL
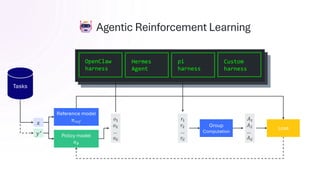
Policy model
𝜋𝜃
Reference model
𝜋𝑟𝑒𝑓
𝑥
𝑦∗
𝑜1
𝑜2
…
𝑜𝐺
𝑟1
𝑟2
…
𝑟𝐺
Group
Computation
𝐴1
𝐴2
…
𝐴𝐺
Loss
OpenClaw
harness
Hermes
Agent
pi
harness
Custom
harness
Agentic Reinforcement Learning
Tasks
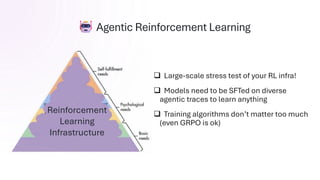
Agentic Reinforcement Learning
Reinforcement
Learning
Infrastructure
❑ Large-scale stress test of your RL infra!
❑ Models need to be SFTed on diverse
agentic traces to learn anything
❑ Training algorithms don’t matter too much
(even GRPO is ok)
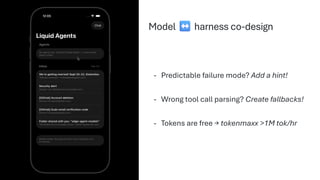
Agentic harness
- Predictable failure mode? Add a hint!
- Wrong tool call parsing? Create fallbacks!
- Tokens are free → tokenmaxx >1M tok/hr
Model harness co-design
❑ Edge models = unique challenges
❑ Model + harness co-design =
❑ Edge agents = new paradigm
Takeaways
"Circe Offering the Cup to Ulysses" by John William Waterhouse (1891)
Thank you!
@maximelabonne maxime - labonne