Building Real-Time Voice Agents with LiveKit & Gemini Live API
Explore creating conversational voice agents using LiveKit's real-time audio transport and Gemini Live API's speech-native capabilities, focusing on latency, memory, and production deployment.
Building Real-Time Voice Agents with LiveKit & Gemini Live API
1.
Voice Agents inProduction:
Building with LiveKit &
the Gemini Live API
Sri Lanka
Suresh Peiris
Co-Founder at Articom Inc.
Community Lead at GDG Sri Lanka
2.
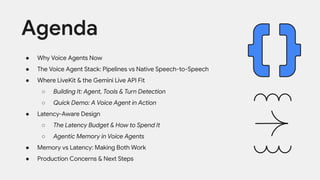
● Why VoiceAgents Now
● The Voice Agent Stack: Pipelines vs Native Speech-to-Speech
● Where LiveKit & the Gemini Live API Fit
○ Building It: Agent, Tools & Turn Detection
○ Quick Demo: A Voice Agent in Action
● Latency-Aware Design
○ The Latency Budget & How to Spend It
○ Agentic Memory in Voice Agents
● Memory vs Latency: Making Both Work
● Production Concerns & Next Steps
Agenda
3.
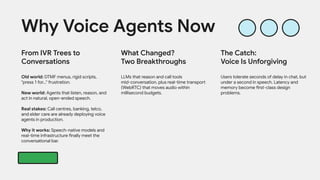
From IVR Treesto
Conversations
Old world: DTMF menus, rigid scripts,
"press 1 for..." frustration.
New world: Agents that listen, reason, and
act in natural, open-ended speech.
Real stakes: Call centres, banking, telco,
and elder care are already deploying voice
agents in production.
Why it works: Speech-native models and
real-time infrastructure finally meet the
conversational bar.
Why Voice Agents Now
What Changed?
Two Breakthroughs
LLMs that reason and call tools
mid-conversation, plus real-time transport
(WebRTC) that moves audio within
millisecond budgets.
The Catch:
Voice Is Unforgiving
Users tolerate seconds of delay in chat, but
under a second in speech. Latency and
memory become first-class design
problems.
4.
The Agent:
A conversationalvoice agent that
answers a call, speaks naturally, and
calls tools mid-conversation.
The Transport:
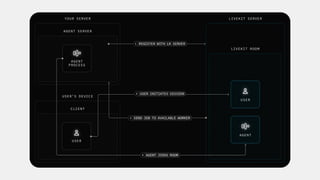
LiveKit handles the real-time audio:
rooms, tracks, SIP, and the agents
framework that hosts our worker.
What We Are
Building Today
The Brain:
The Gemini Live API streams audio in and
out natively, with reasoning and function
calling built in.
The Hard Parts:
Keeping responses under the conversational
latency bar, and giving the agent memory
across turns and sessions.
5.
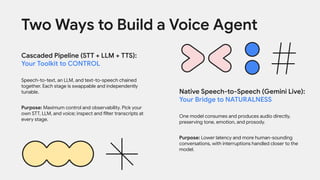
Cascaded Pipeline (STT+ LLM + TTS):
Your Toolkit to CONTROL
Speech-to-text, an LLM, and text-to-speech chained
together. Each stage is swappable and independently
tunable.
Purpose: Maximum control and observability. Pick your
own STT, LLM, and voice; inspect and filter transcripts at
every stage.
Two Ways to Build a Voice Agent
Native Speech-to-Speech (Gemini Live):
Your Bridge to NATURALNESS
One model consumes and produces audio directly,
preserving tone, emotion, and prosody.
Purpose: Lower latency and more human-sounding
conversations, with interruptions handled closer to the
model.
6.
Real-Time Transport:
● WebRTCmoves audio between caller and agent with low
latency, even on lossy networks.
● Rooms, Tracks, Participants: the agent joins the call like any
other participant.
● AgentSession: manages the conversation loop, turn-taking, and
plugin wiring for you.
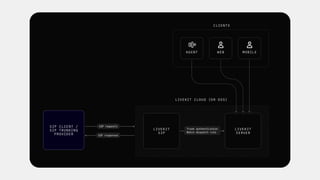
Telephony via SIP:
● Bridge PSTN phone calls into LiveKit rooms with SIP trunks,
inbound and outbound.
● The same agent code serves web, mobile, and phone callers.
● Dispatch rules route incoming calls to the right agent
automatically.
Plugin Ecosystem:
● Swap STT, LLM, and TTS providers behind one interface,
including the Gemini Live realtime plugin.
Where LiveKit Fits
Turn Detection & VAD:
● Built-in voice activity detection and
end-of-utterance models decide when the
user is done speaking.
Observability:
● Session logs, transcripts, and metrics to trace
what the agent heard, decided, and said.
Deployment Pathways:
● Run workers anywhere: LiveKit Cloud or
self-hosted on Kubernetes (AKS, GKE) close to
your callers.
8.
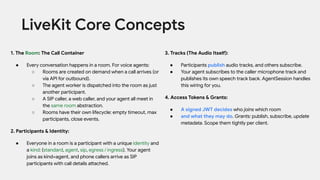
1. The Room:The Call Container
● Every conversation happens in a room. For voice agents:
○ Rooms are created on demand when a call arrives (or
via API for outbound).
○ The agent worker is dispatched into the room as just
another participant.
○ A SIP caller, a web caller, and your agent all meet in
the same room abstraction.
○ Rooms have their own lifecycle: empty timeout, max
participants, close events.
2. Participants & Identity:
● Everyone in a room is a participant with a unique identity and
a kind: (standard, agent, sip, egress / ingress). Your agent
joins as kind=agent, and phone callers arrive as SIP
participants with call details attached.
LiveKit Core Concepts
3. Tracks (The Audio Itself):
● Participants publish audio tracks, and others subscribe.
● Your agent subscribes to the caller microphone track and
publishes its own speech track back. AgentSession handles
this wiring for you.
4. Access Tokens & Grants:
● A signed JWT decides who joins which room
● and what they may do. Grants: publish, subscribe, update
metadata. Scope them tightly per client.
9.
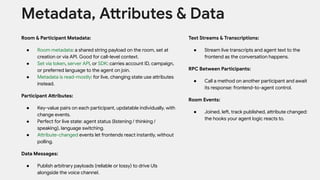
Room & ParticipantMetadata:
● Room metadata: a shared string payload on the room, set at
creation or via API. Good for call-level context.
● Set via token, server API, or SDK: carries account ID, campaign,
or preferred language to the agent on join.
● Metadata is read-mostly: for live, changing state use attributes
instead.
Participant Attributes:
● Key-value pairs on each participant, updatable individually, with
change events.
● Perfect for live state: agent status (listening / thinking /
speaking), language switching.
● Attribute-changed events let frontends react instantly, without
polling.
Data Messages:
● Publish arbitrary payloads (reliable or lossy) to drive UIs
alongside the voice channel.
Metadata, Attributes & Data
Text Streams & Transcriptions:
● Stream live transcripts and agent text to the
frontend as the conversation happens.
RPC Between Participants:
● Call a method on another participant and await
its response: frontend-to-agent control.
Room Events:
● Joined, left, track published, attribute changed:
the hooks your agent logic reacts to.
10.
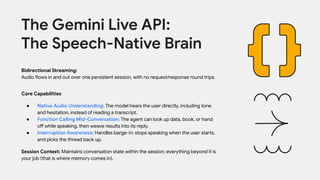
Bidirectional Streaming:
Audio flowsin and out over one persistent session, with no request/response round trips.
Core Capabilities
● Native Audio Understanding: The model hears the user directly, including tone
and hesitation, instead of reading a transcript.
● Function Calling Mid-Conversation: The agent can look up data, book, or hand
off while speaking, then weave results into its reply.
● Interruption Awareness: Handles barge-in: stops speaking when the user starts,
and picks the thread back up.
Session Context: Maintains conversation state within the session; everything beyond it is
your job (that is where memory comes in).
The Gemini Live API:
The Speech-Native Brain
11.
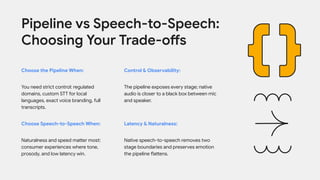
Choose the PipelineWhen:
You need strict control: regulated
domains, custom STT for local
languages, exact voice branding, full
transcripts.
Choose Speech-to-Speech When:
Naturalness and speed matter most:
consumer experiences where tone,
prosody, and low latency win.
Pipeline vs Speech-to-Speech:
Choosing Your Trade-offs
Control & Observability:
The pipeline exposes every stage; native
audio is closer to a black box between mic
and speaker.
Latency & Naturalness:
Native speech-to-speech removes two
stage boundaries and preserves emotion
the pipeline flattens.
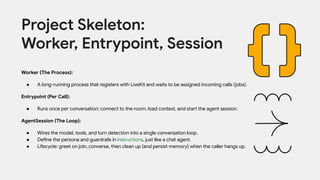
Worker (The Process):
●A long-running process that registers with LiveKit and waits to be assigned incoming calls (jobs).
Entrypoint (Per Call):
● Runs once per conversation: connect to the room, load context, and start the agent session.
AgentSession (The Loop):
● Wires the model, tools, and turn detection into a single conversation loop.
● Define the persona and guardrails in instructions, just like a chat agent.
● Lifecycle: greet on join, converse, then clean up (and persist memory) when the caller hangs up.
Project Skeleton:
Worker, Entrypoint, Session
15.
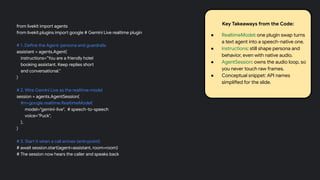
from livekit importagents
from livekit.plugins import google # Gemini Live realtime plugin
# 1. Define the Agent: persona and guardrails
assistant = agents.Agent(
instructions="You are a friendly hotel
booking assistant. Keep replies short
and conversational."
)
# 2. Wire Gemini Live as the realtime model
session = agents.AgentSession(
llm=google.realtime.RealtimeModel(
model="gemini-live", # speech-to-speech
voice="Puck",
),
)
# 3. Start it when a call arrives (entrypoint)
# await session.start(agent=assistant, room=room)
# The session now hears the caller and speaks back
Key Takeaways from the Code:
● RealtimeModel: one plugin swap turns
a text agent into a speech-native one.
● instructions: still shape persona and
behavior, even with native audio.
● AgentSession: owns the audio loop, so
you never touch raw frames.
● Conceptual snippet: API names
simplified for the slide.
16.
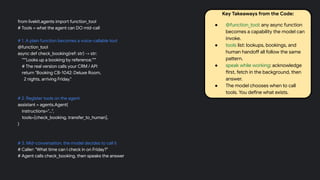
from livekit.agents importfunction_tool
# Tools = what the agent can DO mid-call
# 1. A plain function becomes a voice-callable tool
@function_tool
async def check_booking(ref: str) -> str:
"""Looks up a booking by reference."""
# The real version calls your CRM / API
return "Booking CB-1042: Deluxe Room,
2 nights, arriving Friday."
# 2. Register tools on the agent
assistant = agents.Agent(
instructions="...",
tools=[check_booking, transfer_to_human],
)
# 3. Mid-conversation, the model decides to call it
# Caller: "What time can I check in on Friday?"
# Agent calls check_booking, then speaks the answer
Key Takeaways from the Code:
● @function_tool: any async function
becomes a capability the model can
invoke.
● tools list: lookups, bookings, and
human handoff all follow the same
pattern.
● speak while working: acknowledge
first, fetch in the background, then
answer.
● The model chooses when to call
tools. You define what exists.
17.
Knowing When theUser Is Done:
● VAD detects speech vs silence, but pauses are ambiguous since people think
mid-sentence. Semantic end-of-utterance models judge whether the sentence is
complete.
● Handling Barge-In (Interruptions):
○ Users will interrupt, and a good agent treats this as signal, not error:
Stop output instantly and truncate the unspoken text from context, so the
model knows what the caller actually heard.
○ Resume gracefully: treat the interruption as the new user turn and
respond to it, not to the old thread.
Turn Detection & Interruptions
18.
"Here is ourvoice agent live. I will call in over the web client, and you will hear it
greet me using its instructions persona."
"Watch what happens when I ask about my booking: the agent keeps the
conversation going while check_booking runs in the background."
(Interrupt the agent mid-sentence to show barge-in handling.)
"Notice the response gap. That is our latency budget in action, which is exactly
what the next section is about."
Quick Demo/Walkthrough
What Users ActuallyPerceive:
● Human conversation has a rhythm: replies land in roughly 200-500 ms, and
anything beyond about one second feels like the agent froze. Your entire stack
(network, models, audio) must fit inside that budget, so every stage has to justify
the milliseconds it spends.
The Latency Budget
21.
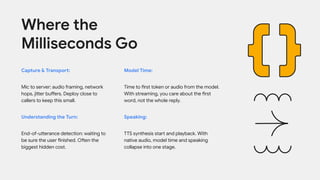
Capture & Transport:
Micto server: audio framing, network
hops, jitter buffers. Deploy close to
callers to keep this small.
Understanding the Turn:
End-of-utterance detection: waiting to
be sure the user finished. Often the
biggest hidden cost.
Where the
Milliseconds Go
Model Time:
Time to first token or audio from the model.
With streaming, you care about the first
word, not the whole reply.
Speaking:
TTS synthesis start and playback. With
native audio, model time and speaking
collapse into one stage.
22.
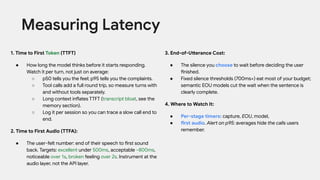
1. Time toFirst Token (TTFT)
● How long the model thinks before it starts responding.
Watch it per turn, not just on average:
○ p50 tells you the feel; p95 tells you the complaints.
○ Tool calls add a full round trip, so measure turns with
and without tools separately.
○ Long context inflates TTFT (transcript bloat, see the
memory section).
○ Log it per session so you can trace a slow call end to
end.
2. Time to First Audio (TTFA):
● The user-felt number: end of their speech to first sound
back. Targets: excellent under 500ms, acceptable ~800ms,
noticeable over 1s, broken feeling over 2s. Instrument at the
audio layer, not the API layer.
Measuring Latency
3. End-of-Utterance Cost:
● The silence you choose to wait before deciding the user
finished.
● Fixed silence thresholds (700ms+) eat most of your budget;
semantic EOU models cut the wait when the sentence is
clearly complete.
4. Where to Watch It:
● Per-stage timers: capture, EOU, model,
● first audio. Alert on p95: averages hide the calls users
remember.
23.
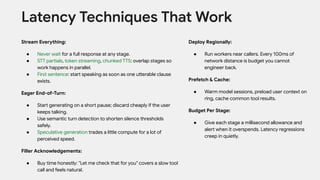
Stream Everything:
● Neverwait for a full response at any stage.
● STT partials, token streaming, chunked TTS: overlap stages so
work happens in parallel.
● First sentence: start speaking as soon as one utterable clause
exists.
Eager End-of-Turn:
● Start generating on a short pause; discard cheaply if the user
keeps talking.
● Use semantic turn detection to shorten silence thresholds
safely.
● Speculative generation trades a little compute for a lot of
perceived speed.
Filler Acknowledgements:
● Buy time honestly: "Let me check that for you" covers a slow tool
call and feels natural.
Latency Techniques That Work
Deploy Regionally:
● Run workers near callers. Every 100ms of
network distance is budget you cannot
engineer back.
Prefetch & Cache:
● Warm model sessions, preload user context on
ring, cache common tool results.
Budget Per Stage:
● Give each stage a millisecond allowance and
alert when it overspends. Latency regressions
creep in quietly.
24.
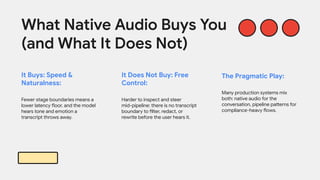
It Buys: Speed&
Naturalness:
Fewer stage boundaries means a
lower latency floor, and the model
hears tone and emotion a
transcript throws away.
What Native Audio Buys You
(and What It Does Not)
It Does Not Buy: Free
Control:
Harder to inspect and steer
mid-pipeline: there is no transcript
boundary to filter, redact, or
rewrite before the user hears it.
The Pragmatic Play:
Many production systems mix
both: native audio for the
conversation, pipeline patterns for
compliance-heavy flows.
25.
Chat Habits DoNot
Transfer
No scrollback: Callers cannot re-read
anything; the agent must recall for them.
Ephemeral sessions: Each call starts a
fresh Live API session, and nothing persists
unless you persist it.
Transcript bloat: An hour of speech is a
huge context; stuffing raw transcripts in
slows every turn.
Expectation gap: Repeat callers expect to
be remembered: "I called yesterday
about..." must just work.
Agentic Memory:
Why Voice Is Harder
In-Session Memory:
Managing the Live
Context
Summarize and prune the running
conversation so model time stays flat as
the call gets long.
Cross-Session Memory:
The Real Product
Persist facts, preferences, and open issues
per caller, and load them the next time
they ring.
26.
Layer 1: WorkingContext (This Turn):
● The live session state Gemini holds: recent turns, tool results, and the current thread.
Layer 2: Session Memory (This Call):
● Rolling summaries replace old turns: keep the decisions and facts, drop the verbatim chit-chat.
Layer 3: Long-Term Memory (This Caller):
● A structured store keyed by caller identity (profile, preferences, open issues, past outcomes).
● Write path: extract facts during or after the call. Read path: retrieve on the next call (entity
memory), so the agent greets a repeat caller with real context.
Memory Layers
for Voice Agents
27.
On Hang-Up (Write):
Runa cheap background job: summarize the call, extract structured facts, upsert to the
memory store.
The Memory Loop
● Structured Store (Keep): A key-value or vector store per caller: facts,
preferences, unresolved issues, last-call summary.
● On Ring (Read): Look up the caller (number or account) and fetch their memory
bundle before the first hello.
● Inject (Use): Drop the bundle into the session instructions and context, so the
greeting already knows the caller.
Result: Continuity across calls without dragging full transcripts into every session.
The Pattern:
Summarize, Store, Retrieve
28.
The Problem: Retrieval
CostsTime:
Fetching memory before the first
response adds to
time-to-first-audio, exactly where
the budget is tightest.
Memory vs Latency: The
Tension
The Fix: Prefetch on
Ring:
The seconds between ring and
answer are free. Fetch memory
then, or greet generically while
retrieval completes.
29.
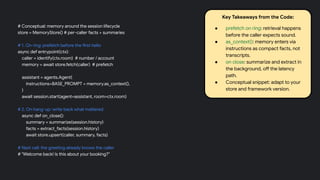
# Conceptual: memoryaround the session lifecycle
store = MemoryStore() # per-caller facts + summaries
# 1. On ring: prefetch before the first hello
async def entrypoint(ctx):
caller = identify(ctx.room) # number / account
memory = await store.fetch(caller) # prefetch
assistant = agents.Agent(
instructions=BASE_PROMPT + memory.as_context(),
)
await session.start(agent=assistant, room=ctx.room)
# 2. On hang-up: write back what mattered
async def on_close():
summary = summarize(session.history)
facts = extract_facts(session.history)
await store.upsert(caller, summary, facts)
# Next call: the greeting already knows the caller
# "Welcome back! Is this about your booking?"
Key Takeaways from the Code:
● prefetch on ring: retrieval happens
before the caller expects sound.
● as_context(): memory enters via
instructions as compact facts, not
transcripts.
● on close: summarize and extract in
the background, off the latency
path.
● Conceptual snippet: adapt to your
store and framework version.
30.
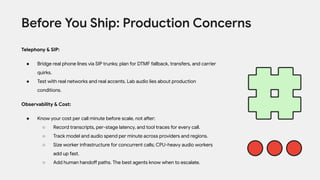
Telephony & SIP:
●Bridge real phone lines via SIP trunks; plan for DTMF fallback, transfers, and carrier
quirks.
● Test with real networks and real accents. Lab audio lies about production
conditions.
Observability & Cost:
● Know your cost per call minute before scale, not after:
○ Record transcripts, per-stage latency, and tool traces for every call.
○ Track model and audio spend per minute across providers and regions.
○ Size worker infrastructure for concurrent calls; CPU-heavy audio workers
add up fast.
○ Add human handoff paths. The best agents know when to escalate.
Before You Ship: Production Concerns
32.
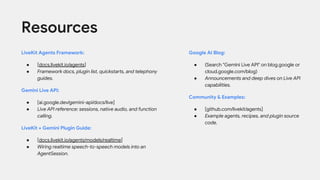
LiveKit Agents Framework:
●[docs.livekit.io/agents]
● Framework docs, plugin list, quickstarts, and telephony
guides.
Gemini Live API:
● [ai.google.dev/gemini-api/docs/live]
● Live API reference: sessions, native audio, and function
calling.
LiveKit + Gemini Plugin Guide:
● [docs.livekit.io/agents/models/realtime]
● Wiring realtime speech-to-speech models into an
AgentSession.
Resources
Google AI Blog:
● (Search "Gemini Live API" on blog.google or
cloud.google.com/blog)
● Announcements and deep dives on Live API
capabilities.
Community & Examples:
● [github.com/livekit/agents]
● Example agents, recipes, and plugin source
code.
 Most read
 Most read