Biostatistics: Measures,
Distributions &Inference
A comprehensive guide to the statistical tools used in health sciences — from
measures of central tendency and dispersion to hypothesis testing, correlation,
and regression. Understanding these principles is essential for every medical and
dental professional who consumes or conducts research.
HEALTH SCIENCES STATISTICS EPIDEMIOLOGY & RESEARCH METHODS
2.
Median & Mode:Completing the Picture of Central
Tendency
Median
The median is the middle value when observations are arranged in
ascending or descending order. If n is odd, the middle observation
is the median. If n is even, the average of the two middle
observations gives the median.
Example (DMFT of five children):
Raw data: 4, 2, 4, 3, 1
Arranged: 1, 2, 3, 4, 4
Median = 3
Mode
The mode is the value that occurs most frequently in a distribution.
It is the most representative and easiest to find among the measures
of central tendency.
Example (pulse rate per min):
71, 72, 73, 68, 71, 71
Mode = 71/min
Mode is not unique — it may yield two or more values
(bimodal/multimodal distributions). It is also not frequently
used in formal statistical analysis.
3.
Measures of Dispersion:Why Averages Alone Are Not Enough
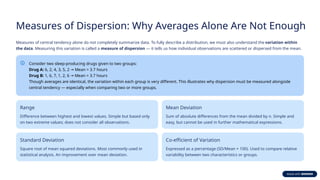
Measures of central tendency alone do not completely summarize data. To fully describe a distribution, we must also understand the variation within
the data. Measuring this variation is called a measure of dispersion — it tells us how individual observations are scattered or dispersed from the mean.
Consider two sleep-producing drugs given to two groups:
Drug A: 6, 2, 4, 3, 5, 2 Mean = 3.7 hours
→
Drug B: 1, 6, 7, 1, 2, 6 Mean = 3.7 hours
→
Though averages are identical, the variation within each group is very different. This illustrates why dispersion must be measured alongside
central tendency — especially when comparing two or more groups.
Range
Difference between highest and lowest values. Simple but based only
on two extreme values; does not consider all observations.
Mean Deviation
Sum of absolute differences from the mean divided by n. Simple and
easy, but cannot be used in further mathematical expressions.
Standard Deviation
Square root of mean squared deviations. Most commonly used in
statistical analysis. An improvement over mean deviation.
Co-efficient of Variation
Expressed as a percentage (SD/Mean × 100). Used to compare relative
variability between two characteristics or groups.
4.
Standard Deviation &Co-efficient of Variation
Standard Deviation (SD)
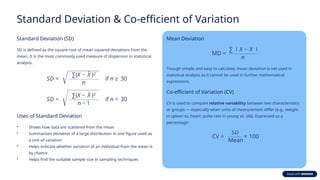
SD is defined as the square root of mean squared deviations from the
mean. It is the most commonly used measure of dispersion in statistical
analysis.
Uses of Standard Deviation
• Shows how data are scattered from the mean
• Summarises deviation of a large distribution in one figure used as
a unit of variation
• Helps indicate whether variation of an individual from the mean is
by chance
• Helps find the suitable sample size in sampling techniques
Mean Deviation
Though simple and easy to calculate, mean deviation is not used in
statistical analysis as it cannot be used in further mathematical
expressions.
Co-efficient of Variation (CV)
CV is used to compare relative variability between two characteristics
or groups — especially when units of measurement differ (e.g., weight
in spleen vs. heart; pulse rate in young vs. old). Expressed as a
percentage:
5.
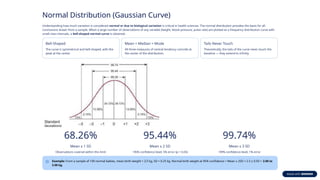
Normal Distribution (GaussianCurve)
Understanding how much variation is considered normal or due to biological variation is critical in health sciences. The normal distribution provides the basis for all
conclusions drawn from a sample. When a large number of observations of any variable (height, blood pressure, pulse rate) are plotted as a frequency distribution curve with
small class intervals, a bell-shaped normal curve is obtained.
Bell-Shaped
The curve is symmetrical and bell-shaped, with the
peak at the center.
Mean = Median = Mode
All three measures of central tendency coincide at
the center of the distribution.
Tails Never Touch
Theoretically, the tails of the curve never touch the
baseline — they extend to infinity.
68.26%
Mean ± 1 SD
Observations covered within this limit
95.44%
Mean ± 2 SD
~95% confidence level; 5% error (p = 0.05)
99.74%
Mean ± 3 SD
~99% confidence level; 1% error
Example: From a sample of 100 normal babies, mean birth weight = 2.5 kg, SD = 0.25 kg. Normal birth weight at 95% confidence = Mean ± 2SD = 2.5 ± 0.50 = 2.00 to
3.00 kg.
6.
Standard Normal Curve& Probability Estimation
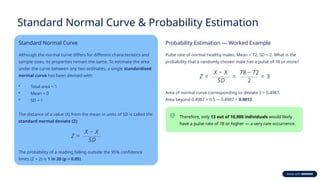
Standard Normal Curve
Although the normal curve differs for different characteristics and
sample sizes, its properties remain the same. To estimate the area
under the curve between any two ordinates, a single standardised
normal curve has been devised with:
• Total area = 1
• Mean = 0
• SD = 1
The distance of a value (X) from the mean in units of SD is called the
standard normal deviate (Z):
The probability of a reading falling outside the 95% confidence
limits (Z > 2) is 1 in 20 (p = 0.05).
Probability Estimation — Worked Example
Pulse rate of normal healthy males: Mean = 72, SD = 2. What is the
probability that a randomly chosen male has a pulse of 78 or more?
Area of normal curve corresponding to deviate 3 = 0.4987.
Area beyond 0.4987 = 0.5 0.4987 =
− 0.0013
Therefore, only 13 out of 10,000 individuals would likely
have a pulse rate of 78 or higher — a very rare occurrence.
7.
Statistical Inference: Estimationof Population Values
Statistical inference is the procedure of drawing conclusions from sample values. It consists of two aspects: (i) estimation of a population value and (ii) testing of
hypothesis. When many samples are drawn from a population, each gives a slightly different result — this is called sampling variation. The measure of this variation is the
Standard Error (SE).
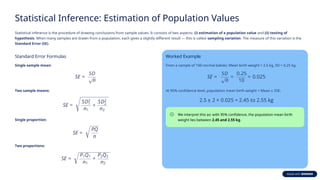
Standard Error Formulas
Single sample mean:
Two sample means:
Single proportion:
Two proportions:
Worked Example
From a sample of 100 normal babies: Mean birth weight = 2.5 kg, SD = 0.25 kg.
At 95% confidence level, population mean birth weight = Mean ± 2SE:
We interpret this as: with 95% confidence, the population mean birth
weight lies between 2.45 and 2.55 kg.
8.
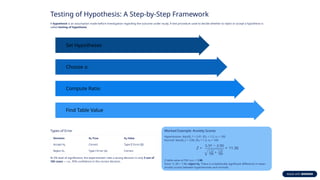
Testing of Hypothesis:A Step-by-Step Framework
A hypothesis is an assumption made before investigation regarding the outcome under study. A test procedure used to decide whether to reject or accept a hypothesis is
called testing of hypothesis.
Find Table Value
Compute Ratio
Choose α
Set Hypotheses
Types of Error
Decision H₀ True H₀ False
Accept H₀ Correct Type II Error (β)
Reject H₀ Type I Error (α) Correct
At 5% level of significance, the experimenter risks a wrong decision in only 5 out of
100 cases — i.e., 95% confidence in the correct decision.
Worked Example: Anxiety Scores
Hypertensive: bar{X}_1 = 5.91, SD₁ = 1.2, n₁ = 100
Normal: bar{X}_2 = 3.90, SD₂ = 1.3, n₂ = 100
Z table value at 5% l.o.s. = 1.96
Since 11.36 > 1.96, reject H₀. There is a statistically significant difference in mean
anxiety scores between hypertensives and normals.
9.
Tests of Significance& Correlation
Parametric vs. Non-Parametric Tests
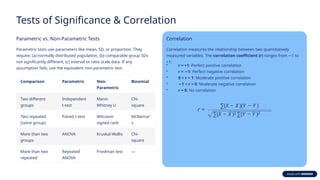
Parametric tests use parameters like mean, SD, or proportion. They
require: (a) normally distributed population, (b) comparable group SDs
not significantly different, (c) interval or ratio scale data. If any
assumption fails, use the equivalent non-parametric test.
Comparison Parametric Non-
Parametric
Binomial
Two different
groups
Independent
t-test
Mann-
Whitney U
Chi-
square
Two repeated
(same group)
Paired t-test Wilcoxon
signed rank
McNemar'
s
More than two
groups
ANOVA Kruskal-Wallis Chi-
square
More than two
repeated
Repeated
ANOVA
Friedman test —
Correlation
Correlation measures the relationship between two quantitatively
measured variables. The correlation coefficient (r) ranges from 1 to
−
+1:
• r = +1: Perfect positive correlation
• r = 1
− : Perfect negative correlation
• 0 < r < 1: Moderate positive correlation
• −1 < r < 0: Moderate negative correlation
• r = 0: No correlation
10.
Regression Analysis &Conclusion
Regression
Regression analysis enables prediction of the value of one variable from the
knowledge of another, provided they are linearly correlated. It helps identify risk
factors associated with an outcome variable. The regression coefficient (β)
quantifies how much the dependent variable changes per unit change in the
independent variable:
The regression equation to estimate the dependent variable (Y) from the independent
variable (X) is:
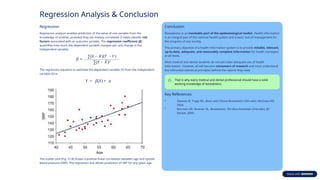
The scatter plot (Fig. 51.8) shows a positive linear correlation between age and systolic
blood pressure (SBP). The regression line allows prediction of SBP for any given age.
Conclusion
Biostatistics is an inevitable part of the epidemiological toolkit. Health information
is an integral part of the national health system and a basic tool of management for
the progress of any society.
The primary objective of a health information system is to provide reliable, relevant,
up-to-date, adequate, and reasonably complete information for health managers
at all levels.
Most medical and dental students do not yet make adequate use of health
information. However, all will become consumers of research and must understand
the inferential statistical principles behind the reports they read.
That is why every medical and dental professional should have a solid
working knowledge of biostatistics.
Key References
• Dawson B, Trapp RG. Basic and Clinical Biostatistics (4th edn). McGraw-Hill,
2004.
• Norman GR, Streiner DL. Biostatistics: The Bare Essentials (2nd edn). BC
Decker, 2000.