Leveling up the Analytics Stack
Wes McKinney
@wesmckinn
Apache
ibis
The Need for Speed
21 Years Ago...
A semi-revisionist
history of Big Data
Cloudera’s Jeff Hammerbacher
“Data first, ask questions later”
Enable everyone to
“party on the data”
(paraphrasing!)
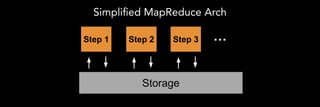
Decoupling Storage from Processing
Simplified MapReduce Arch
Storage
Step 1 Step 2 Step 3 ...
“Scalability! But at what COST?”
McSherry, Isard, Murray 2015
https://www.usenix.org/system/files/conference/hotos15/hotos15-paper-mcsherry.pdf
Configuration that
Outperforms a
Single
Thread
Brute Force Scalability
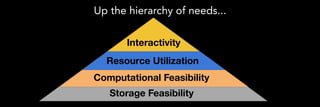
Storage Feasibility
Computational Feasibility
Resource Utilization
Interactivity
Up the hierarchy of needs...
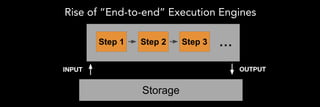
Rise of “End-to-end” Execution Engines
Storage
Step 1 Step 2 Step 3 ...
INPUT OUTPUT
End-to-end engines: drawbacks
• Example: SQL on Hadoop systems, Apache Spark,
others
• Serve some use cases well, others less well
• Fall short in ML/AI domain
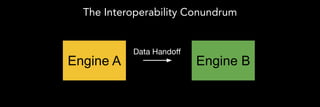
The Interoperability Conundrum
Engine A Engine B
Data Handoff
Some Hardware Trends
• Manycore processor architectures
• Much faster disk
• Much faster networking
• Beyond CPUs
“Why Modern CPUs Are Starving
and What Can Be Done about It”
Francesc Alted, IEEE 2010
Recognizing Serialization as
an Enemy
Serialization
Translation of data into a form that can
be stored or transmitted, and
reconstructed later
How to Eliminate Serialization
“Serialized” and In-Memory Format
must be the same (or nearly so)
A Collective Realization in 2015
Many open source developers had noted the
absence of an in-memory standard for
structured data analytics
● Language-agnostic in-memory format for
analytical query processing on modern
hardware
● Low-overhead data sharing and transport
● A cross-language development platform to
build Arrow-powered applications
Mission
Why Column-oriented?
• Reduce unnecessary IO
• Increase memory throughput
• Better parallelism
• Leverage SIMD instructions
Apache Arrow “meta” goals
• Forge collaborations between database
systems and data science / ML / AI
communities
• Eliminate barriers to code sharing between
application ecosystems and programming
languages
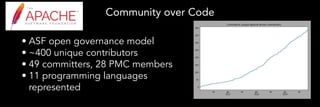
Community over Code
• ASF open governance model
• ~400 unique contributors
• 49 committers, 28 PMC members
• 11 programming languages
represented
Arrow Development in Practice
• “Core” format and protocol implementations
• “Batteries-included” standard libraries
• Common build / test / package infrastructure and
compatibility testing
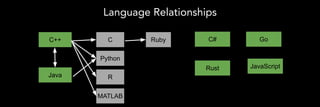
Language Relationships
C++
Java
Go
Rust
C#
JavaScript
C Ruby
Python
R
MATLAB
Some Arrow Success Stories
Apache
• gRPC-based framework for custom data
services
• High-speed network dataset transfer
• Now available for C++, Java, Python
Arrow Flight: Fast Data Services
Development Partners
Flight key ideas
• Zero-serialization
• Bidirectional streaming transfers
• Parallel transfers + horizontal scalability
designed into the protocol
• Reap benefits of Google’s work on gRPC
Flight use cases
• Replacing slow database protocols like
JDBC / ODBC
• General network data movement
• Retrofit legacy systems with fast Arrow IO
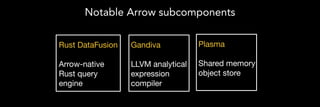
Notable Arrow subcomponents
Rust DataFusion
Arrow-native
Rust query
engine
Gandiva
LLVM analytical
expression
compiler
Plasma
Shared memory
object store
Funding Arrow Development
• Apache projects are technically communities of
volunteers
• Much development contributed by direct users of Arrow
• Ursa Labs: not-for-profit group I founded in 2018 with
initial support of RStudio and Two Sigma
Ursa Labs Sponsors
Thank you!
https://arrow.apache.org
https://ursalabs.org