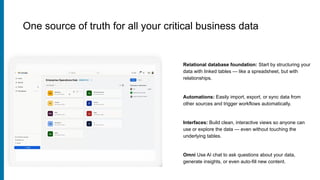
Relational database foundation:Start by structuring your
data with linked tables — like a spreadsheet, but with
relationships.
Automations: Easily import, export, or sync data from
other sources and trigger workflows automatically.
Interfaces: Build clean, interactive views so anyone can
use or explore the data — even without touching the
underlying tables.
Omni Use AI chat to ask questions about your data,
generate insights, or even auto-fill new content.
One source of truth for all your critical business data
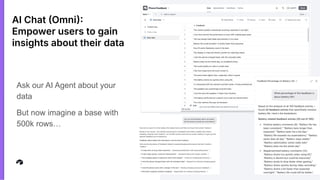
AI Chat Omni
Empowerusers to gain
insights about their data
Ask our AI Agent about your
data
But now imagine a base with
500k rows…
6.
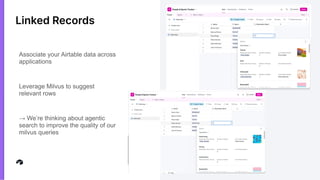
Linked Records
Associate yourAirtable data across
applications
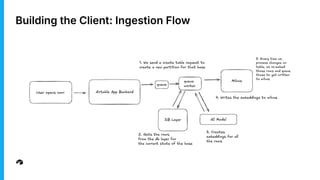
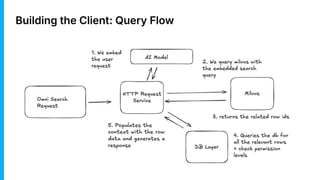
Leverage Milvus to suggest
relevant rows
→ We’re thinking about agentic
search to improve the quality of our
milvus queries
7.
How did wedecide on Milvus?
Priorities
Fast query performance
Scale to large bases
Scale to millions of bases, especially with a high ingestion throughput
We currently have 650k bases in Milvus and we just launched in April
Self-host
Observability and Monitoring
●The milvus team documents all the exposed metrics here
https://milvus.io/docs/metrics_dashboard.md#Milvus-Metrics-
Dashboard
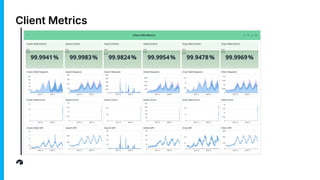
● We run a datadog agent that gets the data from the exposed
endpoint and pipelines into our system and lets us setup
alerting
System Metrics
Are allthe pods
running and how
healthy are they
looking
We want to be
paged if anything
is running hot
14.
Internal Metrics
We wantto know if
compaction and indexing
keeping up with our ingestion
rate
And how much data we have
overall
15.
Node Rotation
● Forsecurity and compliance reasons, we need to rotate every
kubernetes node in our system every week.
● We use pod disruption budgets to ensure we rotate one node at a
time.
● For our query nodes, we ensure that the coordinator has had time
to rebalance the data before rotating the next one
16.
Rollout & Upgradeprocess
We routinely perform upgrades, config changes, feature launches etc. on our production clusters. Our
product teams come up with new use cases, and we want to confidently say we can support them!
We have a load test format where we automatically spin up a production sized cluster with our changes
and read/write to it for 1-2 days. We evaluate performance against benchmarks to prevent regressions
We stress test to gain confidence for node rotation, fault tolerance, and disaster recovery
We rely on our CICD pipeline to rollout stage by stage from alpha to production with some bake time
between
17.
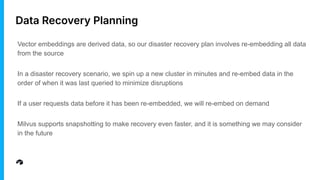
Data Recovery Planning
Vectorembeddings are derived data, so our disaster recovery plan involves re-embedding all data
from the source
In a disaster recovery scenario, we spin up a new cluster in minutes and re-embed data in the
order of when it was last queried to minimize disruptions
If a user requests data before it has been re-embedded, we will re-embed on demand
Milvus supports snapshotting to make recovery even faster, and it is something we may consider
in the future
18.
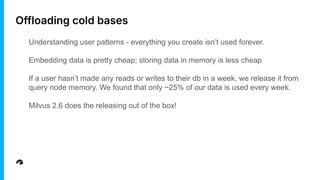
Offloading cold bases
Understandinguser patterns - everything you create isn’t used forever.
Embedding data is pretty cheap; storing data in memory is less cheap
If a user hasn’t made any reads or writes to their db in a week, we release it from
query node memory. We found that only ~25% of our data is used every week.
Milvus 2.6 does the releasing out of the box!