Downloaded 15 times
- 1 / 46
- 2 / 46
- 3 / 46
- 4 / 46
- 5 / 46
- 6 / 46
 Most read
- 7 / 46
- 8 / 46
- 9 / 46
 Most read
- 10 / 46
- 11 / 46
- 12 / 46
- 13 / 46
- 14 / 46

- 15 / 46
- 16 / 46
- 17 / 46
- 18 / 46
- 19 / 46
- 20 / 46
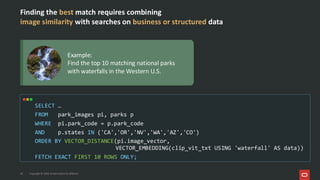
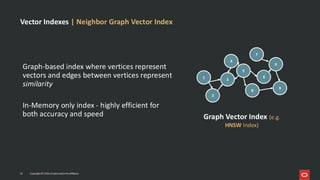
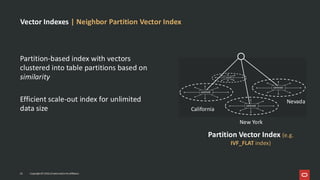
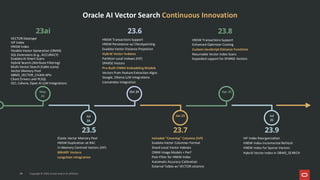
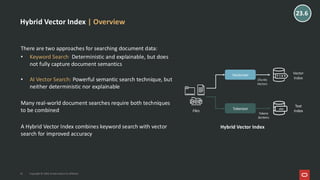
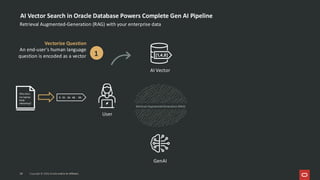
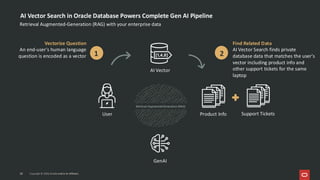
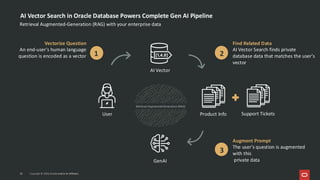
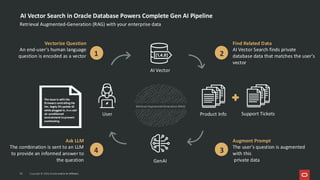
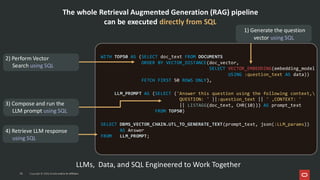
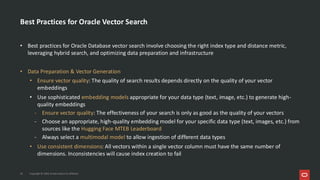
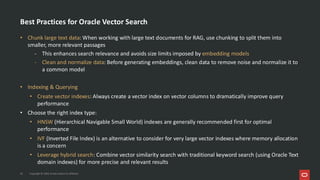
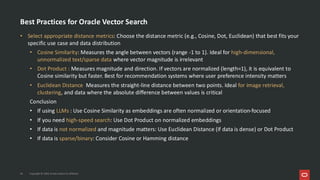
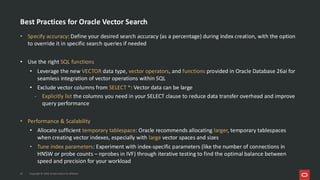
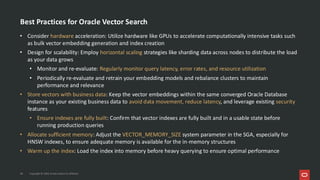
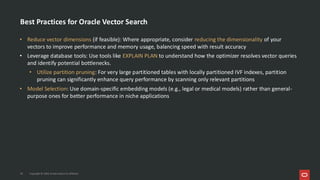

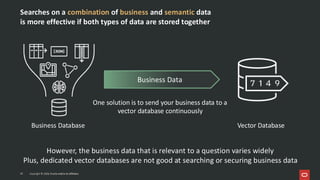
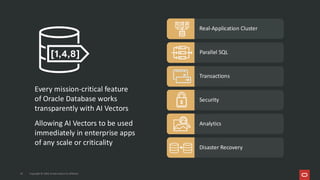
Retrieval-Augmented Generation (RAG) has emerged as a critical pattern for grounding large language models in enterprise data, but many implementations struggle with relevance, performance, and governance at scale. This session presents proven best practices for designing and operating RAG pipelines using Oracle Vector Search in enterprise environments. We will break down the end-to-end RAG lifecycle, including data preparation, embedding strategies, vector indexing, query optimization, and response generation. Attendees will learn how to choose the right chunking and embedding approaches, tune similarity search for accuracy and latency, and integrate Oracle Vector Search with private LLMs and enterprise applications. The session also covers operational best practices such as versioning embeddings, handling data updates, monitoring retrieval quality, and enforcing security controls. Through real-world examples, participants will gain practical guidance for building RAG pipelines that are accurate, scalable, secure, and production-ready on Oracle.


