©2013 DataStax Confidential. Do not distribute without consent.
@PatrickMcFadin
Patrick McFadin

Chief Evangelist for Apache Cassandra
Advanced Data Modeling
with Apache Cassandra
1
Advanced?
• Two thoughts here
Formal Practical
Formal Data Modeling Methods
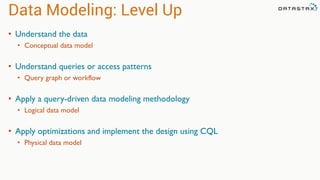
Data Modeling: Level Up
• Understand the data
• Conceptual data model
• Understand queries or access patterns
• Query graph or workflow
• Apply a query-driven data modeling methodology
• Logical data model
• Apply optimizations and implement the design using CQL
• Physical data model
Conceptual Data Model
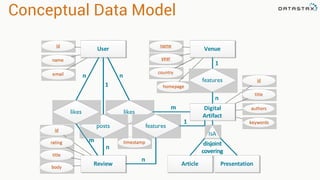
• Shows understanding of data entities and relationships
• Find errors
• Technology independent
• Graphical
Conceptual Data Model
User
Digital
Artifact
Venue
Article PresentationReview
User
Digital
Artifact
Venue
likes
n
m
features
1
n
IsA
Article Presentation
disjoint,
covering
posts
1
n
Review
likes
features
n
m
n
1
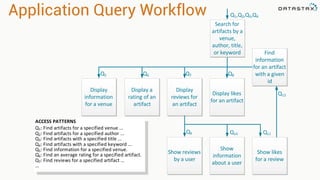
Application Query Workflow
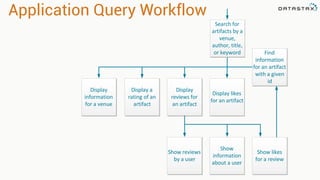
• Cassandra is an application database
• Show the how the application accesses data
• Find queries
Application Query Workflow
Search'for'
artifacts'by'a'
venue,'
author,'title,'
or'keyword
Display'
information'
for'a'venue
Display'a'
rating'of'an'
artifact
Display'
reviews'for'
an'artifact
Display'likes'
for'an'artifact
Find'
information'
for'an'artifact'
with'a'given'
id
Show'
information'
about'a'user
Show'likes'
for'a'review
Show'reviews'
by'a'user
Application Query Workflow
Q5
Q1,Q2,Q3,Q4
Q8Q6 Q7
Search1for1
artifacts1by1a1
venue,1
author,1title,1
or1keyword
Display1
information1
for1a1venue
Display1a1
rating1of1an1
artifact
Display1
reviews1for1
an1artifact
Display1likes1
for1an1artifact
Find1
information1
for1an1artifact1
with1a1given1
id
Show1
information1
about1a1user
Show1likes1
for1a1review
Show1reviews1
by1a1user
Q9 Q10
Q12
Q11
ACCESS%PATTERNS
Q1:$Find$artifacts$for$a$specified$venue$...
Q2:$Find$artifacts$for$a$specified$author$...
Q3:$Find$artifacts$with$a$specified$title$...
Q4:$Find$artifacts$with$a$specified$keyword$...
Q5:$Find$information$for$a$specified$venue.
Q6:$Find$an$average$rating$for$a$specified$artifact.
Q7:$Find$reviews$for$a$specified$artifact$...
...
Logical Data Model
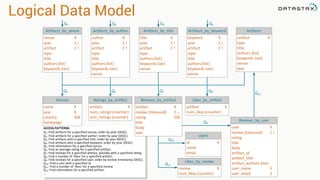
• Combines Conceptual and Query Workflow
• Defines Mapping rules
• Helps define schema
• Chebotko Diagrams
Logical Data Model
ACCESS%PATTERNS
Q1:$Find$artifacts$for$a$specified$venue;$order$by$year$(DESC).
Q2:$Find$artifacts$for$a$specified$author;$order$by$year$(DESC).
Q3:$Find$artifacts$with$a$specified$title;$order$by$year$(DESC).
Q4:$Find$artifacts$with$a$specified$keyword;$order$by$year$(DESC).
Q5:$Find$information$for$a$specified$venue.
Q6:$Find$an$average$rating$for$a$specified$artifact.
Q7:$Find$reviews$for$a$specified$artifact,$possibly$with$a$specified$rating.
Q8:$Find$a$number$of$‘likes’$for$a$specified$artifact.
Q9:$Find$reviews$for$a$specified$user;$order$by$review$timestamp$(DESC).
Q10:$Find$a$user$with$a$specified$id.
Q11:$Find$a$number$of$‘likes’$for$a$specified$review.
Q12:$Find$information$for$a$specified$artifact.
...
Venues
name K
year K
country IDX
homepage
Q5
Artifacts_by_venue
venue K
year C
artifact C
type
title
authors$(list)
keywords$(set)
Artifacts_by_author
author K
year C
artifact C
type
title
authors$(list)
keywords$(set)
venue
Artifacts_by_title
title K
year C
artifact C
type
authors$(list)
keywords$(set)
venue
Artifacts_by_keyword
keyword K
year C
artifact C
type
title
authors$(list)
keywords$(set)
venue
Users
id K
name
email
Ratings_by_artifact
artifact K
num_ratings$(counter)
sum_ratings$(counter)
Reviews_by_user
user K
review$(timeuuid) C
rating
title
body
artifact_id
artifact_title
artifact_authors$(list)
user_name S
user_email S
Reviews_by_artifact
artifact K
review$(timeuuid) C
rating IDX
title
body
user
Likes_by_artifact
artifact K
num_likes$(counter)
Likes_by_review
review K
num_likes$(counter)
Q1 Q2 Q3 Q4
Artifacts
artifact K
type
title
authors$(list)
keywords$(set)
venue
year
Q8Q6 Q7
Q11
Q10
Q9
Q12
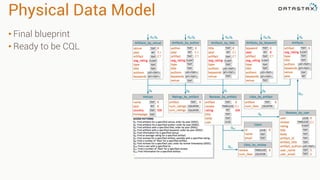
Physical Data Model
• Final blueprint
• Ready to be CQL
Practical Modeling Methods
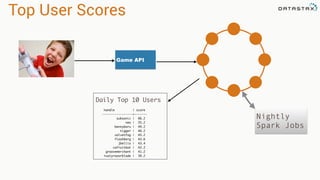
Top User Scores
Game API
Nightly
Spark Jobs
Daily Top 10 Users
handle | score
-----------------+-------
subsonic | 66.2
neo | 55.2
bennybaru | 49.2
tigger | 46.2
velvetfog | 45.2
flashberg | 43.6
jbellis | 43.4
cafruitbat | 43.2
groovemerchant | 41.2
rustyrazorblade | 39.2
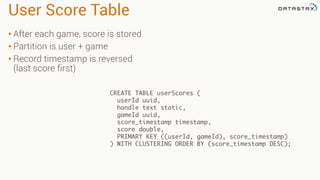
User Score Table
• After each game, score is stored
• Partition is user + game
• Record timestamp is reversed
(last score first)
CREATE TABLE userScores (
userId uuid,
handle text static,
gameId uuid,
score_timestamp timestamp,
score double,
PRIMARY KEY ((userId, gameId), score_timestamp)
) WITH CLUSTERING ORDER BY (score_timestamp DESC);
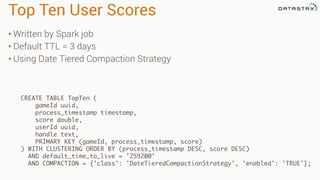
Top Ten User Scores
• Written by Spark job
• Default TTL = 3 days
• Using Date Tiered Compaction Strategy
CREATE TABLE TopTen (
gameId uuid,
process_timestamp timestamp,
score double,
userId uuid,
handle text,
PRIMARY KEY (gameId, process_timestamp, score)
) WITH CLUSTERING ORDER BY (process_timestamp DESC, score DESC)
AND default_time_to_live = '259200'
AND COMPACTION = {'class': 'DateTieredCompactionStrategy', 'enabled': 'TRUE'};
DTCS
• Built for time series
• SSTable windows of time ranges
• Compaction grouped by time
• Best for same TTLed data(default TTL)
• Entire SSTables can be dropped
Queries, Yo
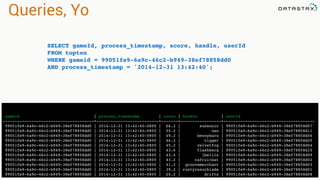
gameid | process_timestamp | score | handle | userid
--------------------------------------+--------------------------+-------+-----------------+--------------------------------------
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 66.2 | subsonic | 99051fe9-6a9c-46c2-b949-38ef78858d07
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 55.2 | neo | 99051fe9-6a9c-46c2-b949-38ef78858d11
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 49.2 | bennybaru | 99051fe9-6a9c-46c2-b949-38ef78858d06
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 46.2 | tigger | 99051fe9-6a9c-46c2-b949-38ef78858d05
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 45.2 | velvetfog | 99051fe9-6a9c-46c2-b949-38ef78858d04
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 43.6 | flashberg | 99051fe9-6a9c-46c2-b949-38ef78858d10
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 43.4 | jbellis | 99051fe9-6a9c-46c2-b949-38ef78858d09
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 43.2 | cafruitbat | 99051fe9-6a9c-46c2-b949-38ef78858d02
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 41.2 | groovemerchant | 99051fe9-6a9c-46c2-b949-38ef78858d03
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 39.2 | rustyrazorblade | 99051fe9-6a9c-46c2-b949-38ef78858d01
99051fe9-6a9c-46c2-b949-38ef78858dd0 | 2014-12-31 13:42:40-0800 | 20.2 | driftx | 99051fe9-6a9c-46c2-b949-38ef78858d08
SELECT gameId, process_timestamp, score, handle, userId
FROM topten
WHERE gameid = 99051fe9-6a9c-46c2-b949-38ef78858dd0
AND process_timestamp = '2014-12-31 13:42:40';
File Storage Use Case
Upload API
It’s all about the model
• Start with our queries
• All data for a image
• All images over time
• Specific images over a range
• Access times of each image
• Use case
• User creates an account
• User uploads image
• Image is distributed worldwide
• User can check access patterns
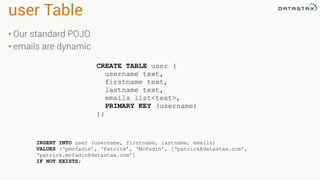
user Table
• Our standard POJO
• emails are dynamic
CREATE TABLE user (
username text,
firstname text,
lastname text,
emails list<text>,
PRIMARY KEY (username)
);
INSERT INTO user (username, firstname, lastname, emails)
VALUES (‘pmcfadin’, ‘Patrick’, ‘McFadin’, [‘patrick@datastax.com’,
‘patrick.mcfadin@datastax.com’]
IF NOT EXISTS;
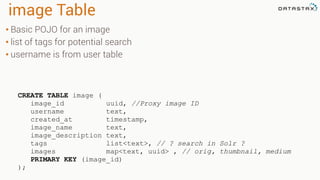
image Table
• Basic POJO for an image
• list of tags for potential search
• username is from user table
CREATE TABLE image (
image_id uuid, //Proxy image ID
username text,
created_at timestamp,
image_name text,
image_description text,
tags list<text>, // ? search in Solr ?
images map<text, uuid> , // orig, thumbnail, medium
PRIMARY KEY (image_id)
);
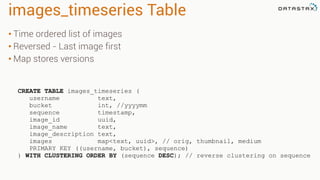
images_timeseries Table
• Time ordered list of images
• Reversed - Last image first
• Map stores versions
CREATE TABLE images_timeseries (
username text,
bucket int, //yyyymm
sequence timestamp,
image_id uuid,
image_name text,
image_description text,
images map<text, uuid>, // orig, thumbnail, medium
PRIMARY KEY ((username, bucket), sequence)
) WITH CLUSTERING ORDER BY (sequence DESC); // reverse clustering on sequence
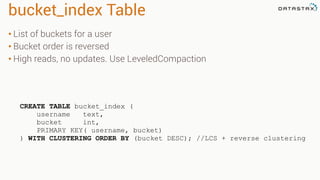
bucket_index Table
• List of buckets for a user
• Bucket order is reversed
• High reads, no updates. Use LeveledCompaction
CREATE TABLE bucket_index (
username text,
bucket int,
PRIMARY KEY( username, bucket)
) WITH CLUSTERING ORDER BY (bucket DESC); //LCS + reverse clustering
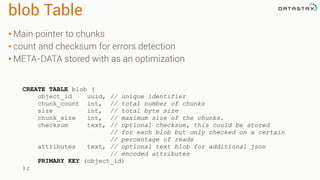
blob Table
• Main pointer to chunks
• count and checksum for errors detection
• META-DATA stored with as an optimization
CREATE TABLE blob (
object_id uuid, // unique identifier
chunk_count int, // total number of chunks
size int, // total byte size
chunk_size int, // maximum size of the chunks.
checksum text, // optional checksum, this could be stored
// for each blob but only checked on a certain
// percentage of reads
attributes text, // optional text blob for additional json
// encoded attributes
PRIMARY KEY (object_id)
);
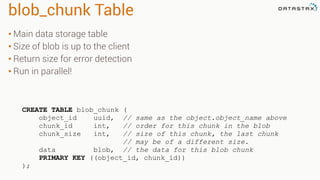
blob_chunk Table
• Main data storage table
• Size of blob is up to the client
• Return size for error detection
• Run in parallel!
CREATE TABLE blob_chunk (
object_id uuid, // same as the object.object_name above
chunk_id int, // order for this chunk in the blob
chunk_size int, // size of this chunk, the last chunk
// may be of a different size.
data blob, // the data for this blob chunk
PRIMARY KEY ((object_id, chunk_id))
);
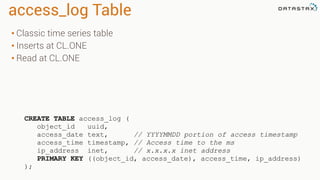
access_log Table
• Classic time series table
• Inserts at CL.ONE
• Read at CL.ONE
CREATE TABLE access_log (
object_id uuid,
access_date text, // YYYYMMDD portion of access timestamp
access_time timestamp, // Access time to the ms
ip_address inet, // x.x.x.x inet address
PRIMARY KEY ((object_id, access_date), access_time, ip_address)
);
Light Weight Transactions
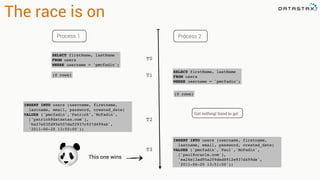
The race is on
Process 1 Process 2
SELECT firstName, lastName
FROM users
WHERE username = 'pmcfadin';
SELECT firstName, lastName
FROM users
WHERE username = 'pmcfadin';
(0 rows)
(0 rows)
INSERT INTO users (username, firstname,
lastname, email, password, created_date)
VALUES ('pmcfadin','Patrick','McFadin',
['patrick@datastax.com'],
'ba27e03fd95e507daf2937c937d499ab',
'2011-06-20 13:50:00');
INSERT INTO users (username, firstname,
lastname, email, password, created_date)
VALUES ('pmcfadin','Paul','McFadin',
['paul@oracle.com'],
'ea24e13ad95a209ded8912e937d499de',
'2011-06-20 13:51:00');
T0
T1
T2
T3
Got nothing! Good to go!
This one wins
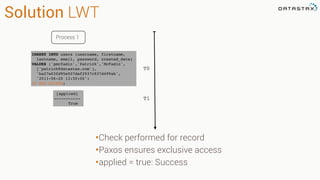
Solution LWT
Process 1
INSERT INTO users (username, firstname,
lastname, email, password, created_date)
VALUES ('pmcfadin','Patrick','McFadin',
['patrick@datastax.com'],
'ba27e03fd95e507daf2937c937d499ab',
'2011-06-20 13:50:00')
IF NOT EXISTS;
T0
T1
[applied]
-----------
True
•Check performed for record
•Paxos ensures exclusive access
•applied = true: Success
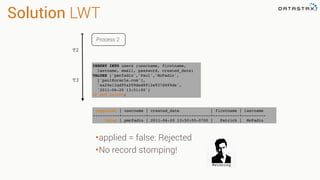
Solution LWT
Process 2
T2
T3
[applied] | username | created_date | firstname | lastname
-----------+----------+--------------------------+-----------+----------
False | pmcfadin | 2011-06-20 13:50:00-0700 | Patrick | McFadin
INSERT INTO users (username, firstname,
lastname, email, password, created_date)
VALUES ('pmcfadin','Paul','McFadin',
['paul@oracle.com'],
'ea24e13ad95a209ded8912e937d499de',
'2011-06-20 13:51:00')
IF NOT EXISTS;
•applied = false: Rejected
•No record stomping!
LWT Fine Print
•Light Weight Transactions solve edge conditions
•They have latency cost.
•Be aware
•Load test
•Consider in your data model
•Now go shut down that ZooKeeper mess you have!
Use case: Form Versioning
Form Versioning Pt 1
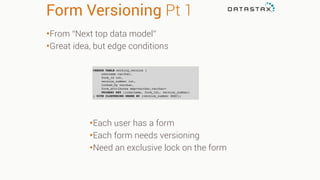
•From “Next top data model”
•Great idea, but edge conditions
CREATE TABLE working_version (
username varchar,
form_id int,
version_number int,
locked_by varchar,
form_attributes map<varchar,varchar>
PRIMARY KEY ((username, form_id), version_number)
) WITH CLUSTERING ORDER BY (version_number DESC);
•Each user has a form
•Each form needs versioning
•Need an exclusive lock on the form
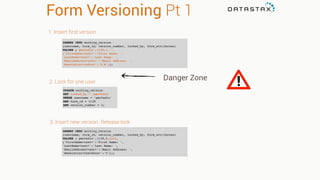
Form Versioning Pt 1
INSERT INTO working_version
(username, form_id, version_number, locked_by, form_attributes)
VALUES ('pmcfadin',1138,1,'',
{'FirstName<text>':'First Name: ',
'LastName<text>':'Last Name: ',
'EmailAddress<text>':'Email Address: ',
'Newsletter<radio>':'Y,N'});
UPDATE working_version
SET locked_by = 'pmcfadin'
WHERE username = 'pmcfadin'
AND form_id = 1138
AND version_number = 1;
INSERT INTO working_version
(username, form_id, version_number, locked_by, form_attributes)
VALUES ('pmcfadin',1138,2,null,
{'FirstName<text>':'First Name: ',
'LastName<text>':'Last Name: ',
'EmailAddress<text>':'Email Address: ',
'Newsletter<checkbox>':'Y'});
1. Insert first version
2. Lock for one user
3. Insert new version. Release lock
Danger Zone
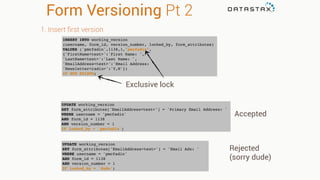
Form Versioning Pt 2
INSERT INTO working_version
(username, form_id, version_number, locked_by, form_attributes)
VALUES ('pmcfadin',1138,1,'pmcfadin',
{'FirstName<text>':'First Name: ',
'LastName<text>':'Last Name: ',
'EmailAddress<text>':'Email Address: ',
'Newsletter<radio>':'Y,N'})
IF NOT EXISTS;
UPDATE working_version
SET form_attributes['EmailAddress<text>'] = 'Primary Email Address: '
WHERE username = 'pmcfadin'
AND form_id = 1138
AND version_number = 1
IF locked_by = 'pmcfadin';
UPDATE working_version
SET form_attributes['EmailAddress<text>'] = 'Email Adx: '
WHERE username = 'pmcfadin'
AND form_id = 1138
AND version_number = 1
IF locked_by = 'dude';
1. Insert first version
Exclusive lock
Accepted
Rejected
(sorry dude)
Form Versioning Pt 2
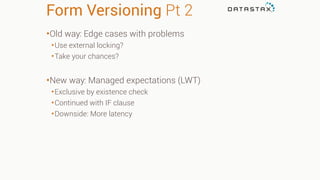
•Old way: Edge cases with problems
•Use external locking?
•Take your chances?
•New way: Managed expectations (LWT)
•Exclusive by existence check
•Continued with IF clause
•Downside: More latency
Cassandra 2.1 Data Model Enhancements
User Defined Types
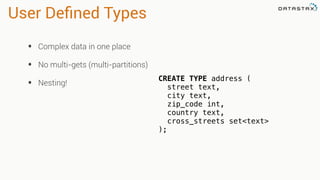
• Complex data in one place
• No multi-gets (multi-partitions)
• Nesting!
CREATE TYPE address (
street text,
city text,
zip_code int,
country text,
cross_streets set<text>
);
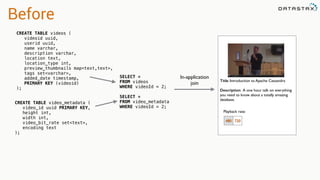
Before
CREATE TABLE videos (
videoid uuid,
userid uuid,
name varchar,
description varchar,
location text,
location_type int,
preview_thumbnails map<text,text>,
tags set<varchar>,
added_date timestamp,
PRIMARY KEY (videoid)
);
CREATE TABLE video_metadata (
video_id uuid PRIMARY KEY,
height int,
width int,
video_bit_rate set<text>,
encoding text
);
SELECT *
FROM videos
WHERE videoId = 2;
SELECT *
FROM video_metadata
WHERE videoId = 2;
Title: Introduction to Apache Cassandra
Description: A one hour talk on everything
you need to know about a totally amazing
database.
480 720
Playback rate:
In-application
join
After
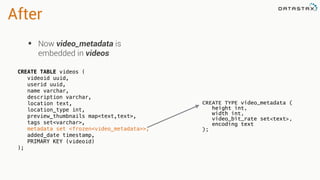
• Now video_metadata is
embedded in videos
CREATE TYPE video_metadata (
height int,
width int,
video_bit_rate set<text>,
encoding text
);
CREATE TABLE videos (
videoid uuid,
userid uuid,
name varchar,
description varchar,
location text,
location_type int,
preview_thumbnails map<text,text>,
tags set<varchar>,
metadata set <frozen<video_metadata>>,
added_date timestamp,
PRIMARY KEY (videoid)
);
Wait! Frozen??
• Staying out of technical
debt
• 3.0 UDTs will not have to
be frozen
• Applicable to User Defined
Types and Tuples
Do you want to build a schema?
Do you want to store some JSON?
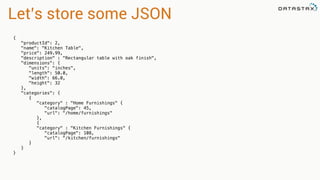
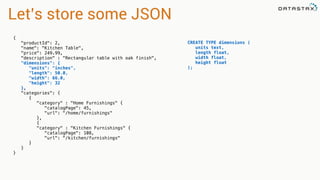
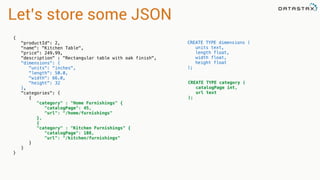
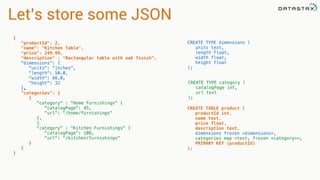
Let’s store some JSON
{
"productId": 2,
"name": "Kitchen Table",
"price": 249.99,
"description" : "Rectangular table with oak finish",
"dimensions": {
"units": "inches",
"length": 50.0,
"width": 66.0,
"height": 32
},
"categories": {
{
"category" : "Home Furnishings" {
"catalogPage": 45,
"url": "/home/furnishings"
},
{
"category" : "Kitchen Furnishings" {
"catalogPage": 108,
"url": "/kitchen/furnishings"
}
}
}
CREATE TYPE dimensions (
units text,
length float,
width float,
height float
);
CREATE TYPE category (
catalogPage int,
url text
);
CREATE TABLE product (
productId int,
name text,
price float,
description text,
dimensions frozen <dimensions>,
categories map <text, frozen <category>>,
PRIMARY KEY (productId)
);
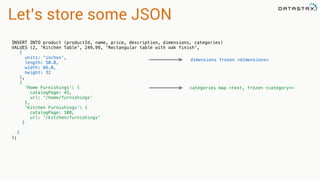
Let’s store some JSON
INSERT INTO product (productId, name, price, description, dimensions, categories)
VALUES (2, 'Kitchen Table', 249.99, 'Rectangular table with oak finish',
{
units: 'inches',
length: 50.0,
width: 66.0,
height: 32
},
{
'Home Furnishings': {
catalogPage: 45,
url: '/home/furnishings'
},
'Kitchen Furnishings': {
catalogPage: 108,
url: '/kitchen/furnishings'
}
}
);
dimensions frozen <dimensions>
categories map <text, frozen <category>>
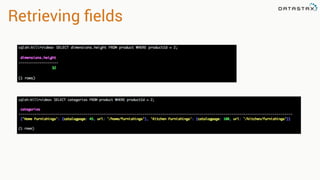
Retrieving fields
Thank you!
Bring the questions
Follow me on twitter
@PatrickMcFadin