0
50
100
150
200
250
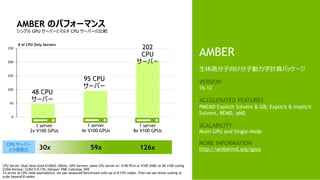
AMBER のパフォーマンス
シングル GPUサーバーとマルチ CPU サーバーの比較
CPU Server: Dual Xeon Gold 6140@2.30GHz, GPU Servers: same CPU server w/ V100 PCIe or V100 SXM2 on 8X v100 config
CUDA Version: CUDA 9.0.176; Dataset: PME-Cellulose_NVE
To arrive at CPU node equivalence, we use measured benchmark with up to 8 CPU nodes. Then we use linear scaling to
scale beyond 8 nodes.
AMBER
生体高分子向け分子動力学計算パッケージ
VERSION
16.12
ACCELERATED FEATURES
PMEMD Explicit Solvent & GB; Explicit & Implicit
Solvent, REMD, aMD
SCALABILITY
Multi-GPU and Single-Node
MORE INFORMATION
http://ambermd.org/gpus
# of CPU Only Servers
1 server
4x V100 GPUs
95 CPU
サーバー
59x
CPU サーバー
との速度比
SKL/V100
#’s may
change
30x 126x
202
CPU
サーバー
48 CPU
サーバー
1 server
8x V100 GPUs
1 server
2x V100 GPUs
9.
9
0
2
4
6
8
10
12
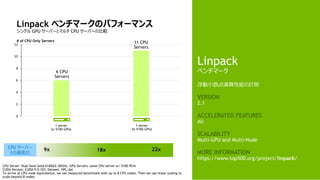
Linpack ベンチマークのパフォーマンス
シングル GPUサーバーとマルチ CPU サーバーの比較
CPU Server: Dual Xeon Gold 6140@2.30GHz, GPU Servers: same CPU server w/ V100 PCIe
CUDA Version: CUDA 9.0.103; Dataset: HPL.dat
To arrive at CPU node equivalence, we use measured benchmark with up to 8 CPU nodes. Then we use linear scaling to
scale beyond 8 nodes.
Linpack
ベンチマーク
浮動小数点演算性能の計測
VERSION
2.1
ACCELERATED FEATURES
All
SCALABILITY
Multi-GPU and Multi-Node
MORE INFORMATION
https://www.top500.org/project/linpack/
6 CPU
Servers
# of CPU Only Servers 11 CPU
Servers
9x 18x 22xCPU サーバー
との速度比
1 server
2x V100 GPUs
1 server
4x V100 GPUs
10.
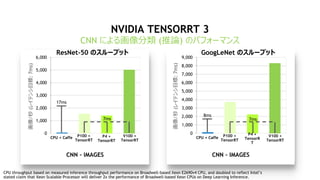
NVIDIA TENSORRT 3
CNNによる画像分類 (推論) のパフォーマンス
CNN - IMAGES
0
1,000
2,000
3,000
4,000
5,000
6,000
画像/秒(レイテンシ目標:7ms)
ResNet-50 のスループット
17ms
CPU + Caffe P100 +
TensorRT
P4 +
TensorRT
CPU throughput based on measured inference throughput performance on Broadwell-based Xeon E2690v4 CPU, and doubled to reflect Intel’s
stated claim that Xeon Scalable Processor will deliver 2x the performance of Broadwell-based Xeon CPUs on Deep Learning Inference.
V100 +
TensorRT
0
1,000
2,000
3,000
4,000
5,000
6,000
7,000
8,000
9,000
GoogLeNet のスループット
8ms
CPU + Caffe P100 +
TensorRT
P4 +
TensorR
T
V100 +
TensorRT
7ms 7ms
CNN - IMAGES
画像/秒(レイテンシ目標:7ms)
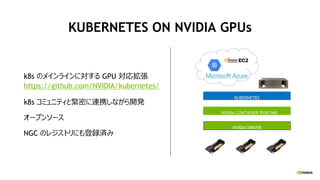
KUBERNETES ON NVIDIAGPUs
k8s のメインラインに対する GPU 対応拡張
https://github.com/NVIDIA/kubernetes/
k8s コミュニティと緊密に連携しながら開発
オープンソース
NGC のレジストリにも登録済み
NVIDIA CONTAINER RUNTIME
KUBERNETES
NVIDIA DRIVER
43.
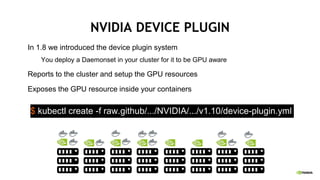
NVIDIA DEVICE PLUGIN
In1.8 we introduced the device plugin system
You deploy a Daemonset in your cluster for it to be GPU aware
Reports to the cluster and setup the GPU resources
Exposes the GPU resource inside your containers
$ kubectl create -f raw.github/.../NVIDIA/.../v1.10/device-plugin.yml
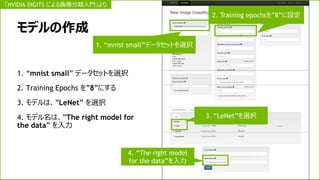
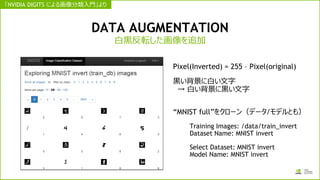
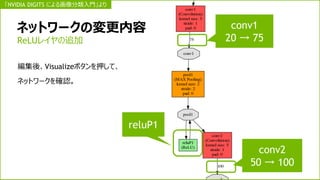
モデルの作成
1. “mnist small”データセットを選択
2. Training Epochs を”8”にする
3. モデルは、”LeNet” を選択
4. モデル名は、”The right model for
the data” を入力
1. “mnist small”データセットを選択
2. Training epochsを”8”に設定
3. “LeNet”を選択
4. “The right model
for the data”を入力
「NVIDIA DIGITS による画像分類入門」より