A look inside pandas
design and development
          Wes McKinney
        Lambda Foundry, Inc.

            @wesmckinn

    NYC Python Meetup, 1/10/2012


                                   1
a.k.a. “Pragmatic Python
 for high performance
       data analysis”


                           2
a.k.a. “Rise of the pandas”


                              3
Me


     4
More like...


SPEED!!!

                          5
Or maybe... (j/k)


                    6
Me
• Mathematician at heart
• 3 years in the quant finance industry
• Last 2: statistics + freelance + open source
• My new company: Lambda Foundry
 • Building analytics and tools for finance
    and other domains


                                                 7
Me
• Blog: http://blog.wesmckinney.com
• GitHub: http://github.com/wesm
• Twitter: @wesmckinn
• Working on “Python for Data Analysis” for
  O’Reilly Media
• Giving PyCon tutorial on pandas (!)

                                              8
pandas?
• http://pandas.sf.net
• Swiss-army knife of (in-memory) data
  manipulation in Python

  • Like R’s data.frame on steroids
  • Excellent performance
  • Easy-to-use, highly consistent API
• A foundation for data analysis in Python
                                             9
pandas

• In heavy production use in the financial
  industry
• Generally much better performance than
  other open source alternatives (e.g. R)
• Hope: basis for the “next generation” data
  analytical environment in Python


                                               10
Simplifying data wrangling

• Data munging / preparation / cleaning /
  integration is slow, error prone, and time
  consuming
• Everyone already <3’s Python for data
  wrangling: pandas takes it to the next level


                                                 11
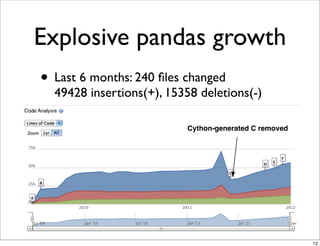
Explosive pandas growth
• Last 6 months: 240 files changed
  49428 insertions(+), 15358 deletions(-)

                          Cython-generated C removed


                                                       12
Rigorous unit testing
• Need to be able to trust your $1e3/e6/e9s
  to pandas
• > 98% line coverage as measured by
  coverage.py
• v0.3.0 (2/19/2011): 533 test functions
• v0.7.0 (1/09/2012): 1272 test functions

                                              13
Some development asides
• I get a lot of questions about my dev env
• Emacs + IPython FTW
• Indispensible development tools
 • pdb (and IPython-enhanced pdb)
 • pylint / pyflakes (integrated with Emacs)
 • nose
 • coverage.py
• grin, for searching code. >> ack/grep IMHO
                                               14
IPython
• Matthew Goodman: “If you are not using
  this tool, you are doing it wrong!”

• Tab completion, introspection, interactive
  debugger, command history

• Designed to enhance your productivity in
  every way. I can’t live without it

• IPython HTML notebook is a game changer
                                               15
Profiling and optimization
• %time, %timeit in IPython
• %prun, to profile a statement with cProfile
• %run -p to profile whole programs
• line_profiler module, for line-by-line timing
• Optimization: find right algorithm first.
  Cython-ize the bottlenecks (if need be)


                                                 16
Other things that matter
• Follow PEP8 religiously
 • Naming conventions, other code style
 • 80 character per line hard limit
• Test more than you think you need to, aim
  for 100% line coverage

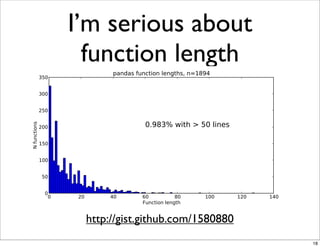
• Avoid long functions (> 50 lines), refactor
  aggressively

                                                17
I’m serious about
  function length


 http://gist.github.com/1580880
                                  18
Don’t make a mess


        Uncle Bob

YouTube: “What killed Smalltalk could kill s/Ruby/Python, too”
                                                                 19
Other stuff
• Good keyboard


                       20
Other stuff
• Big monitors


                         21
Other stuff
• Ergonomic chair (good hacking posture)


                                           22
pandas DataFrame
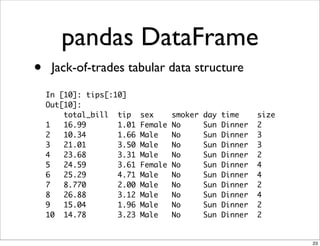
•    Jack-of-trades tabular data structure
    In [10]: tips[:10]
    Out[10]:
        total_bill tip     sex      smoker   day   time     size
    1   16.99       1.01   Female   No       Sun   Dinner   2
    2   10.34       1.66   Male     No       Sun   Dinner   3
    3   21.01       3.50   Male     No       Sun   Dinner   3
    4   23.68       3.31   Male     No       Sun   Dinner   2
    5   24.59       3.61   Female   No       Sun   Dinner   4
    6   25.29       4.71   Male     No       Sun   Dinner   4
    7   8.770       2.00   Male     No       Sun   Dinner   2
    8   26.88       3.12   Male     No       Sun   Dinner   4
    9   15.04       1.96   Male     No       Sun   Dinner   2
    10 14.78        3.23   Male     No       Sun   Dinner   2


                                                                   23
DataFrame

• Heterogeneous columns
• Data alignment and axis indexing
• No-copy data selection (!)
• Agile reshaping
• Fast joining, merging, concatenation

                                         24
DataFrame
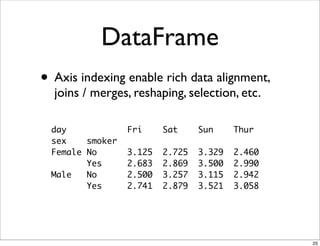
• Axis indexing enable rich data alignment,
  joins / merges, reshaping, selection, etc.

  day             Fri     Sat     Sun     Thur
  sex    smoker
  Female No       3.125   2.725   3.329   2.460
         Yes      2.683   2.869   3.500   2.990
  Male   No       2.500   3.257   3.115   2.942
         Yes      2.741   2.879   3.521   3.058


                                                  25
Let’s have a little fun

 To the IPython Notebook, Batman

http://ashleyw.co.uk/project/food-nutrient-database


                                                      26
Axis indexing, the special
 pandas-flavored sauce
• Enables “alignment-free” programming
• Prevents major source of data munging
  frustration and errors
• Fast (O(1) or O(log n)) selecting data
• Powerful way of describing reshape / join /
  merge / pivot-table operations


                                                27
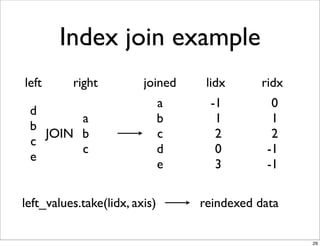
Data alignment, join ops

• The brains live in the axis index
• Indexes know how to do set logic
• Join/align ops: produce “indexers”
 • Mapping between source/output
• Indexer passed to fast “take” function

                                           28
Index join example
left      right          joined     lidx     ridx
                               a    -1         0
 d
        a                      b     1         1
 b
   JOIN b                      c     2         2
 c
        c                      d     0        -1
 e
                               e     3        -1

left_values.take(lidx, axis)       reindexed data

                                                    29
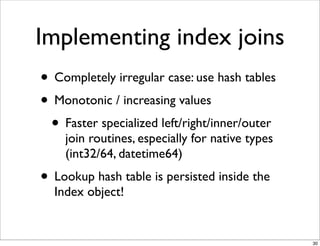
Implementing index joins
• Completely irregular case: use hash tables
• Monotonic / increasing values
 • Faster specialized left/right/inner/outer
    join routines, especially for native types
    (int32/64, datetime64)
• Lookup hash table is persisted inside the
  Index object!


                                                 30
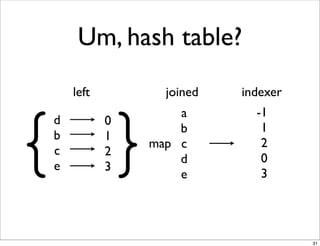
Um, hash table?
    left         joined   indexer


{ }
                   a        -1
d          0
                   b         1
b          1
               map c         2
c          2
                   d         0
e          3
                   e         3


                                    31
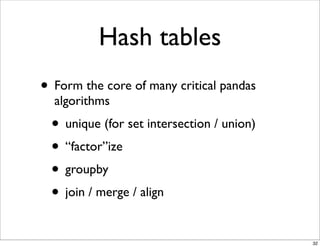
Hash tables
• Form the core of many critical pandas
  algorithms
 • unique (for set intersection / union)
 • “factor”ize
 • groupby
 • join / merge / align

                                           32
GroupBy, a brief
 algorithmic exploration
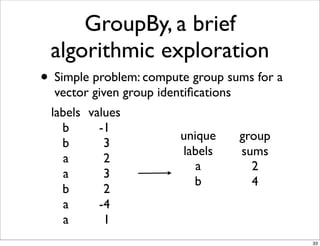
• Simple problem: compute group sums for a
  vector given group identifications
 labels values
   b      -1
                         unique       group
   b       3
                         labels       sums
    a      2
                            a           2
    a      3
                           b            4
   b       2
    a     -4
    a      1
                                              33
GroupBy: Algo #1

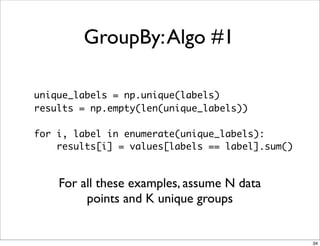
unique_labels = np.unique(labels)
results = np.empty(len(unique_labels))

for i, label in enumerate(unique_labels):
    results[i] = values[labels == label].sum()


    For all these examples, assume N data
         points and K unique groups


                                                 34
GroupBy: Algo #1, don’t do this

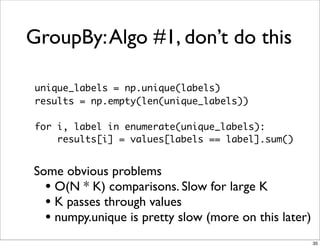
 unique_labels = np.unique(labels)
 results = np.empty(len(unique_labels))

 for i, label in enumerate(unique_labels):
     results[i] = values[labels == label].sum()


Some obvious problems
  • O(N * K) comparisons. Slow for large K
  • K passes through values
  • numpy.unique is pretty slow (more on this later)
                                                       35
GroupBy: Algo #2
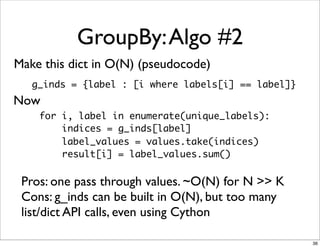
Make this dict in O(N) (pseudocode)
   g_inds = {label : [i where labels[i] == label]}
Now
    for i, label in enumerate(unique_labels):
        indices = g_inds[label]
        label_values = values.take(indices)
        result[i] = label_values.sum()


 Pros: one pass through values. ~O(N) for N >> K
 Cons: g_inds can be built in O(N), but too many
 list/dict API calls, even using Cython

                                                     36
GroupBy: Algo #3, much faster
 • “Factorize” labels
  • Produce vectorto the unique observedK-1
     corresponding
                      of integers from 0, ...,
      values (use a hash table)
   result = np.zeros(k)
   for i, j in enumerate(factorized_labels):
       result[j] += values[i]

Pros: avoid expensive dict-of-lists creation. Avoid
numpy.unique and have option to not to sort the
unique labels, skipping O(K lg K) work
                                                      37
Speed comparisons
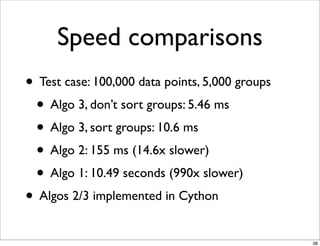
• Test case: 100,000 data points, 5,000 groups
 • Algo 3, don’t sort groups: 5.46 ms
 • Algo 3, sort groups: 10.6 ms
 • Algo 2: 155 ms (14.6x slower)
 • Algo 1: 10.49 seconds (990x slower)
• Algos 2/3 implemented in Cython
                                                 38
GroupBy


• Situation is significantly more complicated
  in the multi-key case.
• More on this later


                                               39
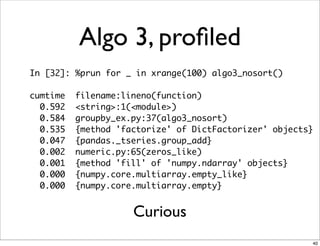
Algo 3, profiled
In [32]: %prun for _ in xrange(100) algo3_nosort()

cumtime   filename:lineno(function)
  0.592   <string>:1(<module>)
  0.584   groupby_ex.py:37(algo3_nosort)
  0.535   {method 'factorize' of DictFactorizer' objects}
  0.047   {pandas._tseries.group_add}
  0.002   numeric.py:65(zeros_like)
  0.001   {method 'fill' of 'numpy.ndarray' objects}
  0.000   {numpy.core.multiarray.empty_like}
  0.000   {numpy.core.multiarray.empty}


                     Curious
                                                        40
Slaves to algorithms

• Turns out that numpy.unique works by
  sorting, not a hash table. Thus O(N log N)
  versus O(N)
• Takes > 70% of the runtime of Algo #2
• Factorize is the new bottleneck, possible to
  go faster?!


                                                 41
Unique-ing faster
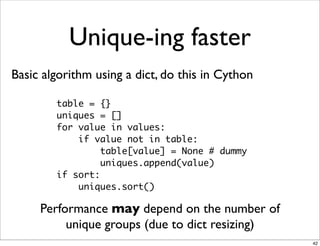
Basic algorithm using a dict, do this in Cython

        table = {}
        uniques = []
        for value in values:
            if value not in table:
                 table[value] = None # dummy
                 uniques.append(value)
        if sort:
            uniques.sort()

     Performance may depend on the number of
          unique groups (due to dict resizing)
                                                  42
Unique-ing faster


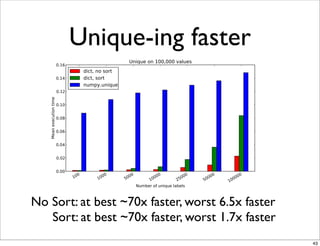
No Sort: at best ~70x faster, worst 6.5x faster
   Sort: at best ~70x faster, worst 1.7x faster
                                                  43
Remember


           44
Can we go faster?
• Python dictimplementations one of the best
  hash table
              is renowned as
                             anywhere
• But:
 • No abilityresizings
    arbitrary
              to preallocate, subject to

  • We don’t care about reference counting,
    throw away table once done
• Hm, what to do, what to do?
                                               45
Enter klib
• http://github.com/attractivechaos/klib
• Small, portable C data structures and
  algorithms
• khash: fast, memory-efficient hash table
• Hack a Cython interface (pxd file) and
  we’re in business


                                            46
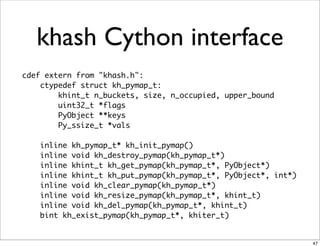
khash Cython interface
cdef extern from "khash.h":
    ctypedef struct kh_pymap_t:
        khint_t n_buckets, size, n_occupied, upper_bound
        uint32_t *flags
        PyObject **keys
        Py_ssize_t *vals

    inline kh_pymap_t* kh_init_pymap()
    inline void kh_destroy_pymap(kh_pymap_t*)
    inline khint_t kh_get_pymap(kh_pymap_t*, PyObject*)
    inline khint_t kh_put_pymap(kh_pymap_t*, PyObject*, int*)
    inline void kh_clear_pymap(kh_pymap_t*)
    inline void kh_resize_pymap(kh_pymap_t*, khint_t)
    inline void kh_del_pymap(kh_pymap_t*, khint_t)
    bint kh_exist_pymap(kh_pymap_t*, khiter_t)


                                                                47
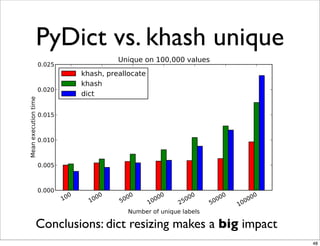
PyDict vs. khash unique


Conclusions: dict resizing makes a big impact
                                                48
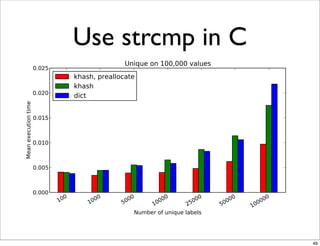
Use strcmp in C


                  49
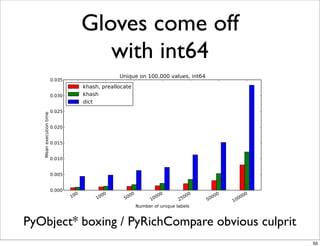
Gloves come off
             with int64


PyObject* boxing / PyRichCompare obvious culprit
                                                   50
Some NumPy-fu
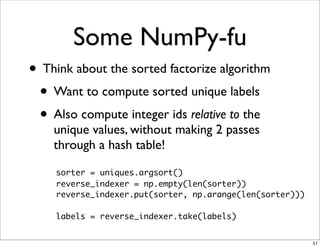
• Think about the sorted factorize algorithm
 • Want to compute sorted unique labels
 • Also compute integer ids relative to the
    unique values, without making 2 passes
    through a hash table!

    sorter = uniques.argsort()
    reverse_indexer = np.empty(len(sorter))
    reverse_indexer.put(sorter, np.arange(len(sorter)))

    labels = reverse_indexer.take(labels)


                                                          51
Aside, for the R community
• R’s factor function is suboptimal
• Makes two hash table passes
 • unique          uniquify and sort
 • match           ids relative to unique labels
• This is highly fixable
• R’s integer unique is about 40% slower than
  my khash_int64 unique

                                                   52
Multi-key GroupBy
• Significantly more complicated because the
  number of possible key combinations may
  be very large
• Example, group by two sets of labels
 • 1000 unique values in each
 • “Key space”: 1,000,000, even though
    observed key pairs may be small


                                              53
Multi-key GroupBy
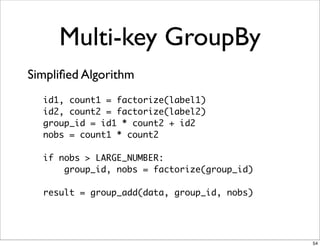
Simplified Algorithm
  id1, count1 = factorize(label1)
  id2, count2 = factorize(label2)
  group_id = id1 * count2 + id2
  nobs = count1 * count2

  if nobs > LARGE_NUMBER:
      group_id, nobs = factorize(group_id)

  result = group_add(data, group_id, nobs)


                                             54
Multi-GroupBy
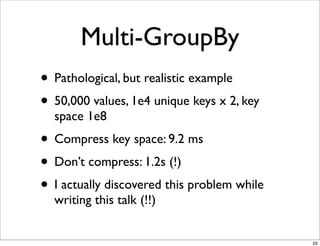
• Pathological, but realistic example
• 50,000 values, 1e4 unique keys x 2, key
  space 1e8
• Compress key space: 9.2 ms
• Don’t compress: 1.2s (!)
• I actually discovered this problem while
  writing this talk (!!)


                                             55
Speaking of performance
• Testing the correctness of code is easy:
  write unit tests
• How to systematically test performance?
• Need to catch performance regressions
• Being mildly performance obsessed, I got
  very tired of playing performance whack-a-
  mole with pandas


                                               56
vbench project
• http://github.com/wesm/vbench
• Run benchmarks for each version of your
  codebase
• vbench checks out each revision of your
  codebase, builds it, and runs all the
  benchmarks you define
• Results stored in a SQLite database
• Only works with git right now
                                            57
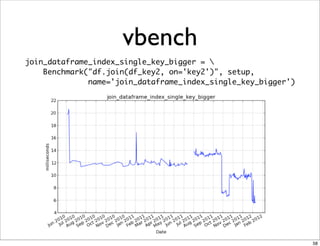
vbench
join_dataframe_index_single_key_bigger = 
    Benchmark("df.join(df_key2, on='key2')", setup,
              name='join_dataframe_index_single_key_bigger')


                                                               58
vbench
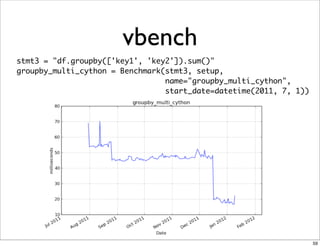
stmt3 = "df.groupby(['key1', 'key2']).sum()"
groupby_multi_cython = Benchmark(stmt3, setup,
                                 name="groupby_multi_cython",
                                 start_date=datetime(2011, 7, 1))


                                                                    59
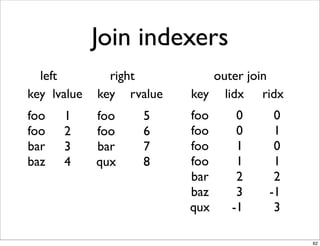
Fast database joins
• Problem: SQL-compatible left, right, inner,
  outer joins
• Row duplication
• Join on index and / or join on columns
• Sorting vs. not sorting
• Algorithmically closely related to groupby
  etc.


                                                60
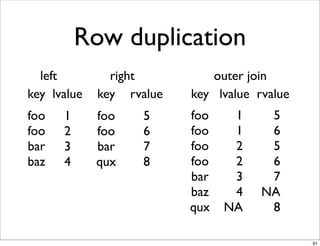
Row duplication
  left         right         outer join
key lvalue   key rvalue   key lvalue rvalue
foo   1      foo    5     foo    1     5
foo   2      foo    6     foo    1     6
bar   3      bar    7     foo    2     5
baz   4      qux    8     foo    2     6
                          bar    3     7
                          baz    4    NA
                          qux   NA     8

                                              61
Join indexers
  left         right         outer join
key lvalue   key rvalue   key lidx ridx
foo   1      foo    5     foo    0    0
foo   2      foo    6     foo    0    1
bar   3      bar    7     foo    1    0
baz   4      qux    8     foo    1    1
                          bar    2    2
                          baz    3   -1
                          qux   -1    3

                                          62
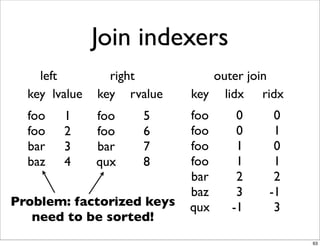
Join indexers
    left         right         outer join
  key lvalue   key rvalue   key lidx ridx
  foo   1      foo    5     foo    0    0
  foo   2      foo    6     foo    0    1
  bar   3      bar    7     foo    1    0
  baz   4      qux    8     foo    1    1
                            bar    2    2
                            baz    3   -1
Problem: factorized keys    qux   -1    3
   need to be sorted!
                                            63
An algorithmic observation

• If N values are known to be from the range
  0 through K - 1, can be sorted in O(N)
• Variant of counting sort
• For our purposes, only compute the
  sorting indexer (argsort)


                                               64
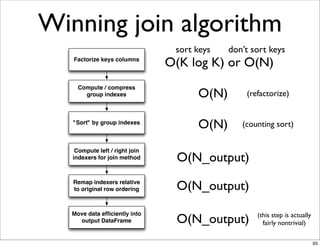
Winning join algorithm
                                 sort keys   don’t sort keys
   Factorize keys columns
                                O(K log K) or O(N)
     Compute / compress
       group indexes                  O(N)       (refactorize)


   "Sort" by group indexes
                                      O(N)      (counting sort)


    Compute left / right join
   indexers for join method      O(N_output)
   Remap indexers relative
   to original row ordering      O(N_output)

                                 O(N_output)        (this step is actually
   Move data efficiently into
     output DataFrame                                 fairly nontrivial)

                                                                             65
“You’re like CLR, I’m like CLRS”
                    - “Kill Dash Nine”, by Monzy


                                                   66
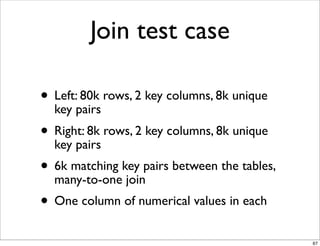
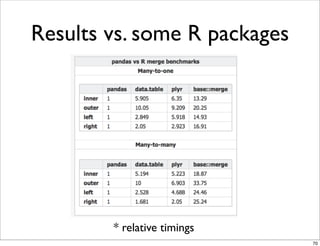
Join test case

• Left:pairs rows, 2 key columns, 8k unique
  key
        80k

• Right: 8k rows, 2 key columns, 8k unique
  key pairs
• 6k matching key pairs between the tables,
  many-to-one join
• One column of numerical values in each
                                              67
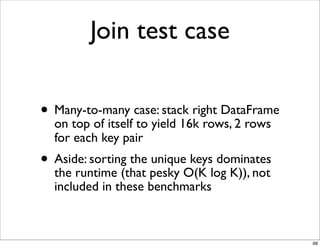
Join test case

• Many-to-many case: stack right DataFrame
  on top of itself to yield 16k rows, 2 rows
  for each key pair
• Aside: sorting the pesky O(K log K)), not
  the runtime (that
                     unique keys dominates

  included in these benchmarks


                                               68
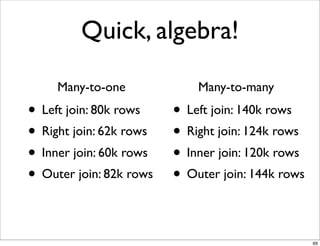
Quick, algebra!

     Many-to-one             Many-to-many
• Left join: 80k rows    • Left join: 140k rows
• Right join: 62k rows   • Right join: 124k rows
• Inner join: 60k rows   • Inner join: 120k rows
• Outer join: 82k rows   • Outer join: 144k rows

                                                   69
Results vs. some R packages


        * relative timings
                              70
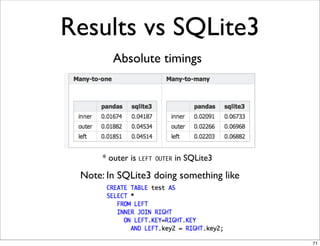
Results vs SQLite3
         Absolute timings


      * outer is LEFT   OUTER   in SQLite3

 Note: In SQLite3 doing something like


                                             71
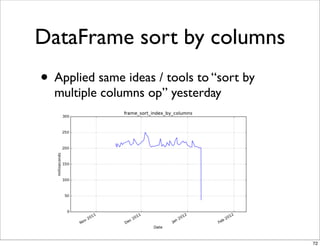
DataFrame sort by columns
• Applied same ideas / tools to “sort by
  multiple columns op” yesterday


                                           72
The bottom line
• Just a flavor: pretty much all of pandas has
  seen the same level of design effort and
  performance scrutiny
• Make sure whoever implemented your data
  structures and algorithms care about
  performance. A lot.
• Python has amazingly powerful and
  productive tools for implementation work


                                                73
Thanks!

• Follow me on Twitter: @wesmckinn
• Blog: http://blog.wesmckinney.com
• Exciting Python things ahead in 2012


                                         74