Grid Operations


Hadoop Performance at LinkedIn
Allen Wittenauer
Grid Computing Architect


©2012 LinkedIn Corporation. All Rights Reserved.
“I have never seen a Hadoop cluster that was
             legitimately CPU bound.”
                -- Milind Bhandarkar
                -- Milind Bhandarkar
                -- Milind Bhandarkar


©2012 LinkedIn Corporation. All Rights Reserved.
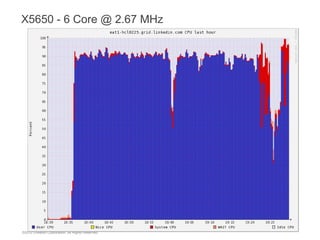
X5650 - 6 Core @ 2.67 MHz


©2012 LinkedIn Corporation. All Rights Reserved.
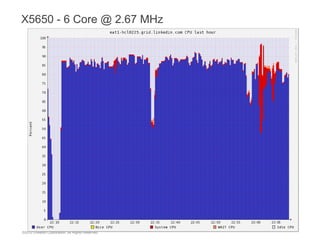
X5650 - 6 Core @ 2.67 MHz


©2012 LinkedIn Corporation. All Rights Reserved.
“I have only seen one Hadoop cluster that was
            legitimately CPU bound.”
               -- Milind Bhandarkar
               -- Milind Bhandarkar
               -- Milind Bhandarkar


©2012 LinkedIn Corporation. All Rights Reserved.
Why do we have such high CPU usage?


©2012 LinkedIn Corporation. All Rights Reserved.
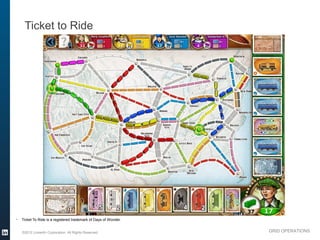
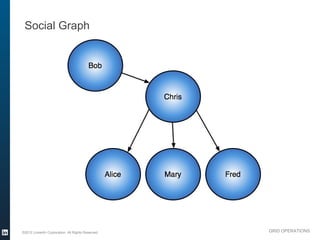
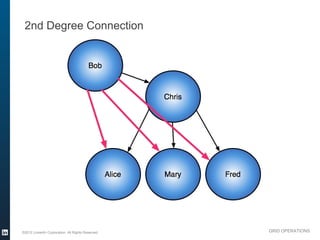
We do a lot of Graph Theory.


©2012 LinkedIn Corporation. All Rights Reserved.
Ticket to Ride


   Ticket To Ride is a registered trademark of Days of Wonder


    ©2012 LinkedIn Corporation. All Rights Reserved.             GRID OPERATIONS
Social Graph


©2012 LinkedIn Corporation. All Rights Reserved.   GRID OPERATIONS
2nd Degree Connection


©2012 LinkedIn Corporation. All Rights Reserved.   GRID OPERATIONS
We under-commit our memory.


©2012 LinkedIn Corporation. All Rights Reserved.
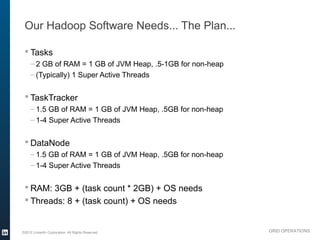
Our Hadoop Software Needs... The Plan...

  Tasks
     – 2 GB of RAM = 1 GB of JVM Heap, .5-1GB for non-heap
     – (Typically) 1 Super Active Threads


  TaskTracker
     – 1.5 GB of RAM = 1 GB of JVM Heap, .5GB for non-heap
     – 1-4 Super Active Threads


  DataNode
     – 1.5 GB of RAM = 1 GB of JVM Heap, .5GB for non-heap
     – 1-4 Super Active Threads


  RAM: 3GB + (task count * 2GB) + OS needs
  Threads: 8 + (task count) + OS needs


©2012 LinkedIn Corporation. All Rights Reserved.             GRID OPERATIONS
Our Hadoop Software Needs... The Reality

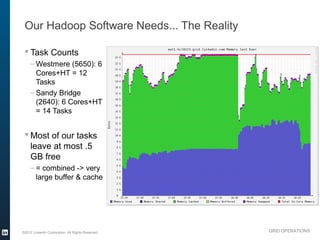
  Task Counts
     – Westmere (5650): 6
       Cores+HT = 12
       Tasks
     – Sandy Bridge
       (2640): 6 Cores+HT
       = 14 Tasks


  Most of our tasks
   leave at most .5
   GB free
     – = combined -> very
       large buffer & cache


©2012 LinkedIn Corporation. All Rights Reserved.   GRID OPERATIONS
We don’t have as many disks per node.


©2012 LinkedIn Corporation. All Rights Reserved.
Typical Hadoop Node Out in the Wild

  Most user’s don’t know their actual
   needs
     – Vendor advice... play it safe!


  Significantly more memory
     – “For the future!”
     – Badly written code
  Significantly more disk
     – “Hadoop is IO intensive!”
     – “Greater task locality!”


  Greater performance...but is it worth
   the cost...


©2012 LinkedIn Corporation. All Rights Reserved.   GRID OPERATIONS
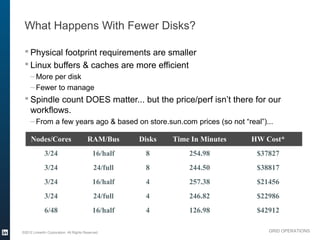
What Happens With Fewer Disks?

  Physical footprint requirements are smaller
  Linux buffers & caches are more efficient
     – More per disk
     – Fewer to manage
  Spindle count DOES matter... but the price/perf isn’t there for our
   workflows.
     – From a few years ago & based on store.sun.com prices (so not “real”)...

     Nodes/Cores                         RAM/Bus      Disks   Time In Minutes   HW Cost*
             3/24                           16/half    8          254.98         $37827
             3/24                           24/full    8          244.50         $38817
             3/24                           16/half    4          257.38         $21456
             3/24                           24/full    4          246.82         $22986
             6/48                           16/half    4          126.98         $42912

©2012 LinkedIn Corporation. All Rights Reserved.                                    GRID OPERATIONS
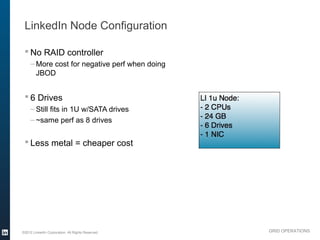
LinkedIn Node Configuration

  No RAID controller
     – More cost for negative perf when doing
       JBOD


  6 Drives
     – Still fits in 1U w/SATA drives
     – ~same perf as 8 drives


  Less metal = cheaper cost


©2012 LinkedIn Corporation. All Rights Reserved.   GRID OPERATIONS
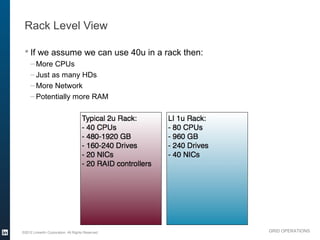
Rack Level View

  If we assume we can use 40u in a rack then:
     – More CPUs
     – Just as many HDs
     – More Network
     – Potentially more RAM


©2012 LinkedIn Corporation. All Rights Reserved.   GRID OPERATIONS
We care about file system tuning.


©2012 LinkedIn Corporation. All Rights Reserved.
LinkedIn Hadoop Disk/File Systems

  noatime Enabled

  writeback Enabled

  Each Disk (except root) Partitions:
     – Swap
     – MapReduce Spill Space
     – HDFS


  Delayed Commits
     – Why write once when you can do ganged writes more efficiently?


©2012 LinkedIn Corporation. All Rights Reserved.                        GRID OPERATIONS
We care about job tuning.


©2012 LinkedIn Corporation. All Rights Reserved.
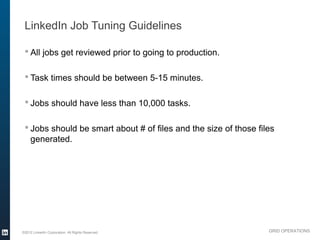
LinkedIn Job Tuning Guidelines

  All jobs get reviewed prior to going to production.

  Task times should be between 5-15 minutes.

  Jobs should have less than 10,000 tasks.

  Jobs should be smart about # of files and the size of those files
   generated.


©2012 LinkedIn Corporation. All Rights Reserved.                  GRID OPERATIONS
... and the result?


©2012 LinkedIn Corporation. All Rights Reserved.
Why is LinkedIn Running so Hot?

  We do a lot of non-MapReduce work.

  RAM buffers and caches allow us to offset a lot of disk IO.

  We audit our jobs.

  As a result, our CPUs are actually busy.


©2012 LinkedIn Corporation. All Rights Reserved.                 GRID OPERATIONS
©2012 LinkedIn Corporation. All Rights Reserved.   BUSINESS OPERATIONS